Every experiment the autonomous loop has run, across all 6 evaluation eras — kept and discarded. Each row was pre-registered before training (hypothesis, method, expected outcome, architecture figure), then trained on a single GPU and scored. Every score on this page is measured by one frozen ruler: the worst mission score on held-out viewpoints of a photograph the model never trained on — (1 − usable-fix rate) + false-fix rate, the product requirement rather than an error statistic. A model must also fit the aircraft: the champion’s file is 31.7 MB against a hard limit of 32 MiB (≈ 8 MiB once quantised to int8 for the chip). The earlier eras were judged by different rulers at the time, and where those two disagree the row says so. One agent designs, one implements; failures stay on the record. New here? Start with the overview.
Where we are right now
Status: best mission score is 0.078 in its hardest cell. That number is (1 − usable-fix rate) + false-fix rate: a frame counts as a usable fix only when the model is confident and within 100 m; abstaining is safe; being confident and wrong is a false fix, which for a UAV is worse than saying nothing at all. 1.0 means it abstains on everything, 2.0 means it is confidently wrong on everything, 0 is the goal.
28 experiments in this era, 12 kept — and 81 before it, across 5 earlier evaluation eras. The chart below shows all 109. Cost of the whole search: $487.87 — $465.74 of agent tokens (equivalent API cost; the work ran on a Max subscription) plus $22.13 of rented GPU, recorded for 88 of 109 experiments.
New bestNot a new bestRunning bestEra's own bestGoal (score 0)×Gated failHoldout checkPivot-directedNot on this rulerEvaluation eraupdated 2026-11-04 12:37 UTC
Mission score per experiment, all 109 of them — (1 − usable-fix rate) + false-fix rate, lower is better
#
Experiment
Category
Mission score
Time
Cost
Status
▸
6.28
Bigger magnifying glass: the 128 px frame is enlarged in-graph to 288 px instead of 224 px before the EfficientNet-B0 trunks, so Berlin's small structures (cars, roof edges, kerbs, tree crowns) reach the borrowed filters at a scale closer to the one their ImageNet invariance was learned on 2e90e35d
worse than champion: 0.100 vs 0.078
architecturepivot
0.100
172 m 23 s
$2.85
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The UAV's camera picture is small, and the pre-trained 'eyes' we borrow were taught on everyday photos where things are big. Last time we blew the picture up to the size those eyes are used to, it was one of the biggest improvements so far. This time we blow it up a bit more, so cars, roof edges and street corners look less like specks and more like the shapes the eyes already know how to recognise in any lighting or season — without adding any memory to the UAV.
What it cost
design agent
$1.26
figure agent
$0.97
implementation agent
$0.63
total
$2.85
by model — claude-opus-5-5 $2.85
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.100 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Builds on experiment 15, the one input-scale change of this era and one of its largest single steps: resizing the 128 px frame in-graph to 224 px (the trunk's ImageNet resolution) took held-out truedop_2024 from 65.5% to 74.25% usable (mission 0.395 -> 0.293) with zero new parameters. Its reading was FixRes-style: the pretrained filters carry invariance at the object scales they were trained on, and a 1 m/px aerial frame shows structures far smaller than ImageNet objects (a car is ~4 px at 128, ~7 px at 224). That lever was pulled once and never revisited; every experiment since has kept 224. Meanwhile the remaining gap on the champion (exp 20: 93.0% usable, 0.75% false, 6.25% abstain on truedop_2024; 100%/0% on the three training photographs at the same viewpoints) is the survey gap, and the survey-invariance lever that has paid on this ruler is what the PRETRAINED TRUNK brings (MNV3-S -> MNV2 -> B0), not training-procedure invariance tricks (JS consistency exp 23, continuous vantages exp 22, patchwork exp 27, LP-FT exp 26, Noisy-Student weights exp 25 all failed to beat 0.0777). A bigger trunk is closed by the size gate (31.7 MB of 33.6 MB), but how much of the trunk's existing invariance reaches Berlin's fine structure is not: at 288 px the stride-16 read level becomes 18x18 (from 14x14) and stride-32 becomes 9x9 (from 7x7), so the 3x3 / 5x5 kernels of the early stages span ~1.3x less ground each and see small, survey-stable structure (street layout, building footprints, kerb lines) with more pixels, while survey-specific texture (shadow grain, canopy speckle, colour noise) is no sharper because upsampling adds no new information. Hypothesis: the limiting factor on the foreign photograph is that the trunk's scale-tuned invariance only partly engages on structures this small, and a further 1.29x enlargement engages more of it, lowering abstention without raising false fixes.
Method
ONE change: INPUT_PX in model/model.py goes 224 -> 288 (2.25x enlargement of the 128 px frame, bilinear, in-graph, unchanged op). Everything that derives from it follows automatically: read levels become 112x18x18 (after features[5]) and 320x9x9 (after features[7]); GAP keeps the place feature at 112-d, so the parameter count, ONNX size and prototypes are identical. Trunk, MixStyle insertion points (after features[2]/[3]/[4], now 24x72x72 / 40x36x36 / 80x18x18), committee, cosine head, margin, offsets, decode, confidence gate, augmentation, 8 epochs, SWA from epoch 5 with BN recalibration: all unchanged.
Expected outcome
mission_score 0.0777 -> ~0.055-0.065 on truedop_2024: usable 93.0% -> ~94.5-95% (abstentions 25 -> ~17-20 frames), false fix held at <=1.0% (<=4 frames). Training-capture diagnostics stay ~100% usable / 0% false. Exported ONNX size unchanged (~31.7 MB); host latency rises ~1.6x (48.8 ms -> ~80 ms), well inside 250 ms; training wall-clock rises ~1.6x (~1.8 h -> ~3 h on the g6). If usable falls or stays flat while abstention moves only by noise (+/-2 frames = +/-0.005), the enlargement lever saturated at 224 and the scale reading of exp 15 is refuted beyond that point.
Result
mission score = 0.100173 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json. Retried 2026-11-03 with the experiment's exact code after the first run was cut off at epoch 6/8 by the AWS 150-minute safety shutdown (issue #22): usable 90.75%, false 0.75%, abstain 8.50%, median 35.7 m on truedop_2024; host latency 82.5 ms (champion 48.8 ms).
Conclusion
REVERTED — mission score did not improve (0.100173 vs best 0.077671); change discarded. Hypothesis not supported: the 288 px enlargement raised abstention (6.25% -> 8.5%) with the same false-fix rate and no gain in accuracy, and made inference ~1.7x slower. (First recorded as 1e9: the original run never finished; see issue #22.)
Where the model was tested — and how far off it was
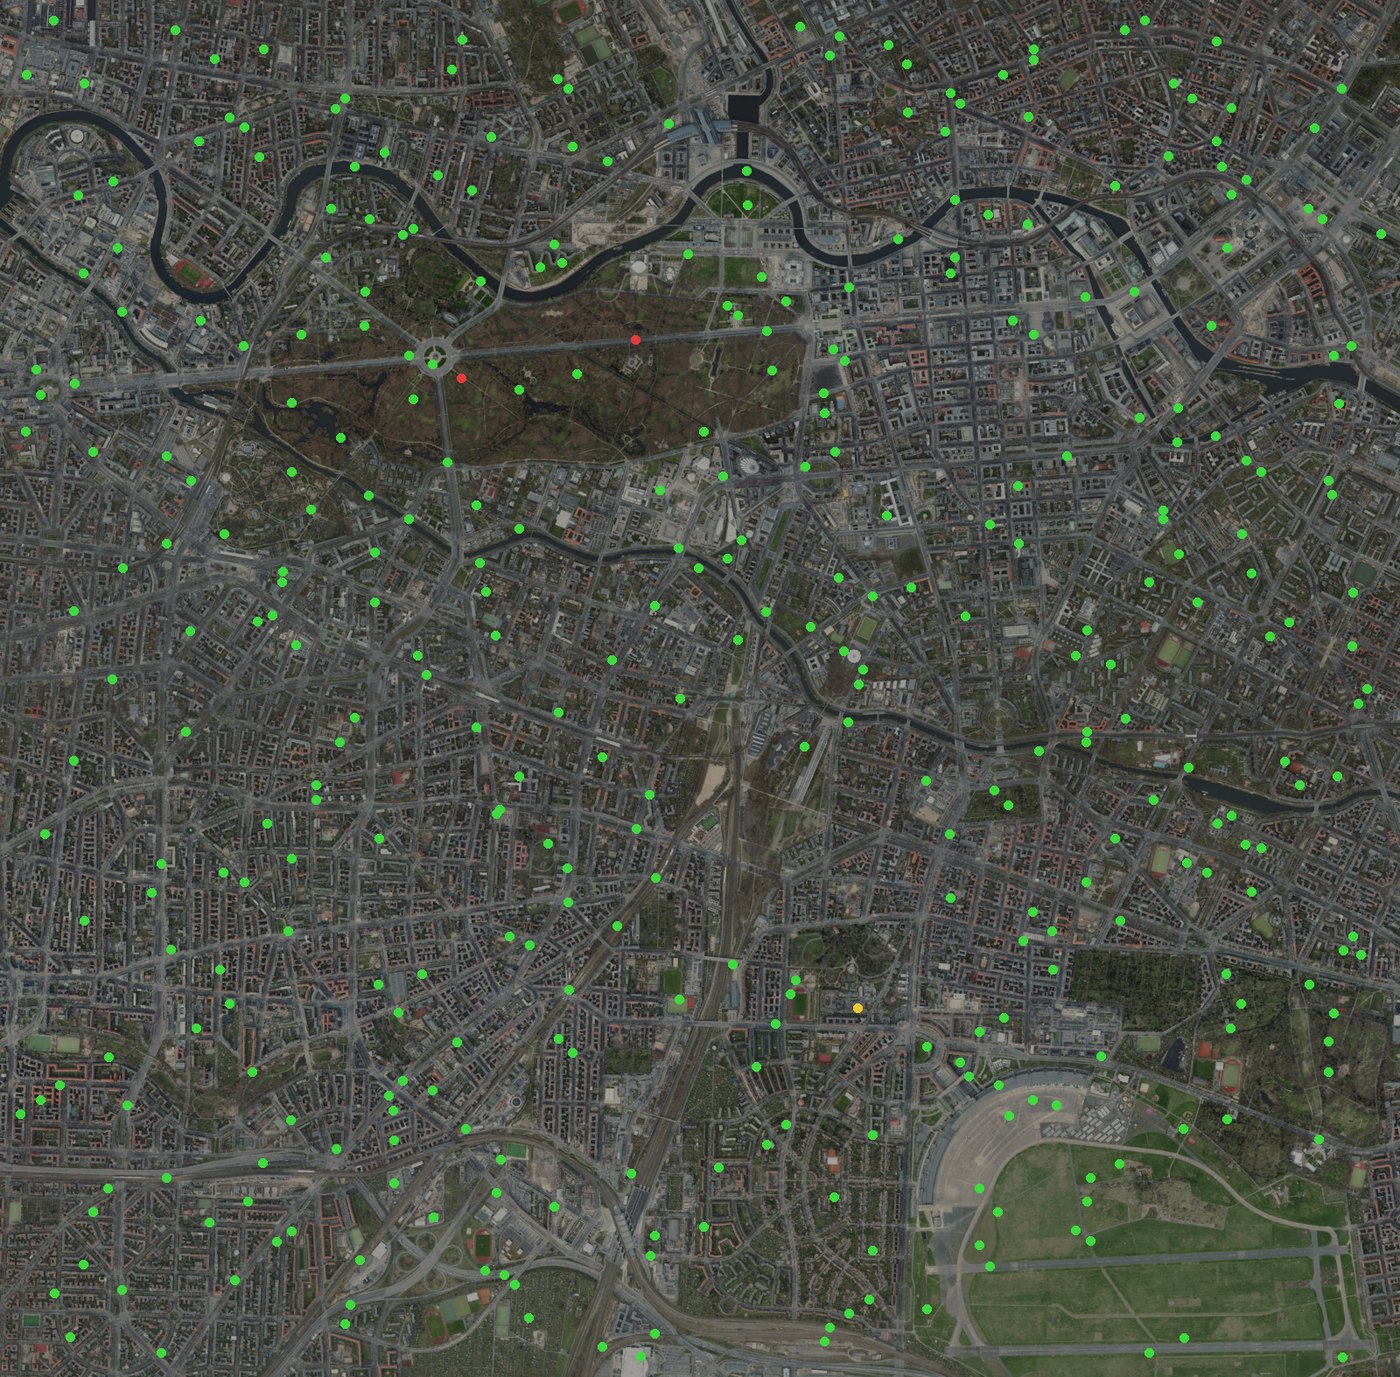
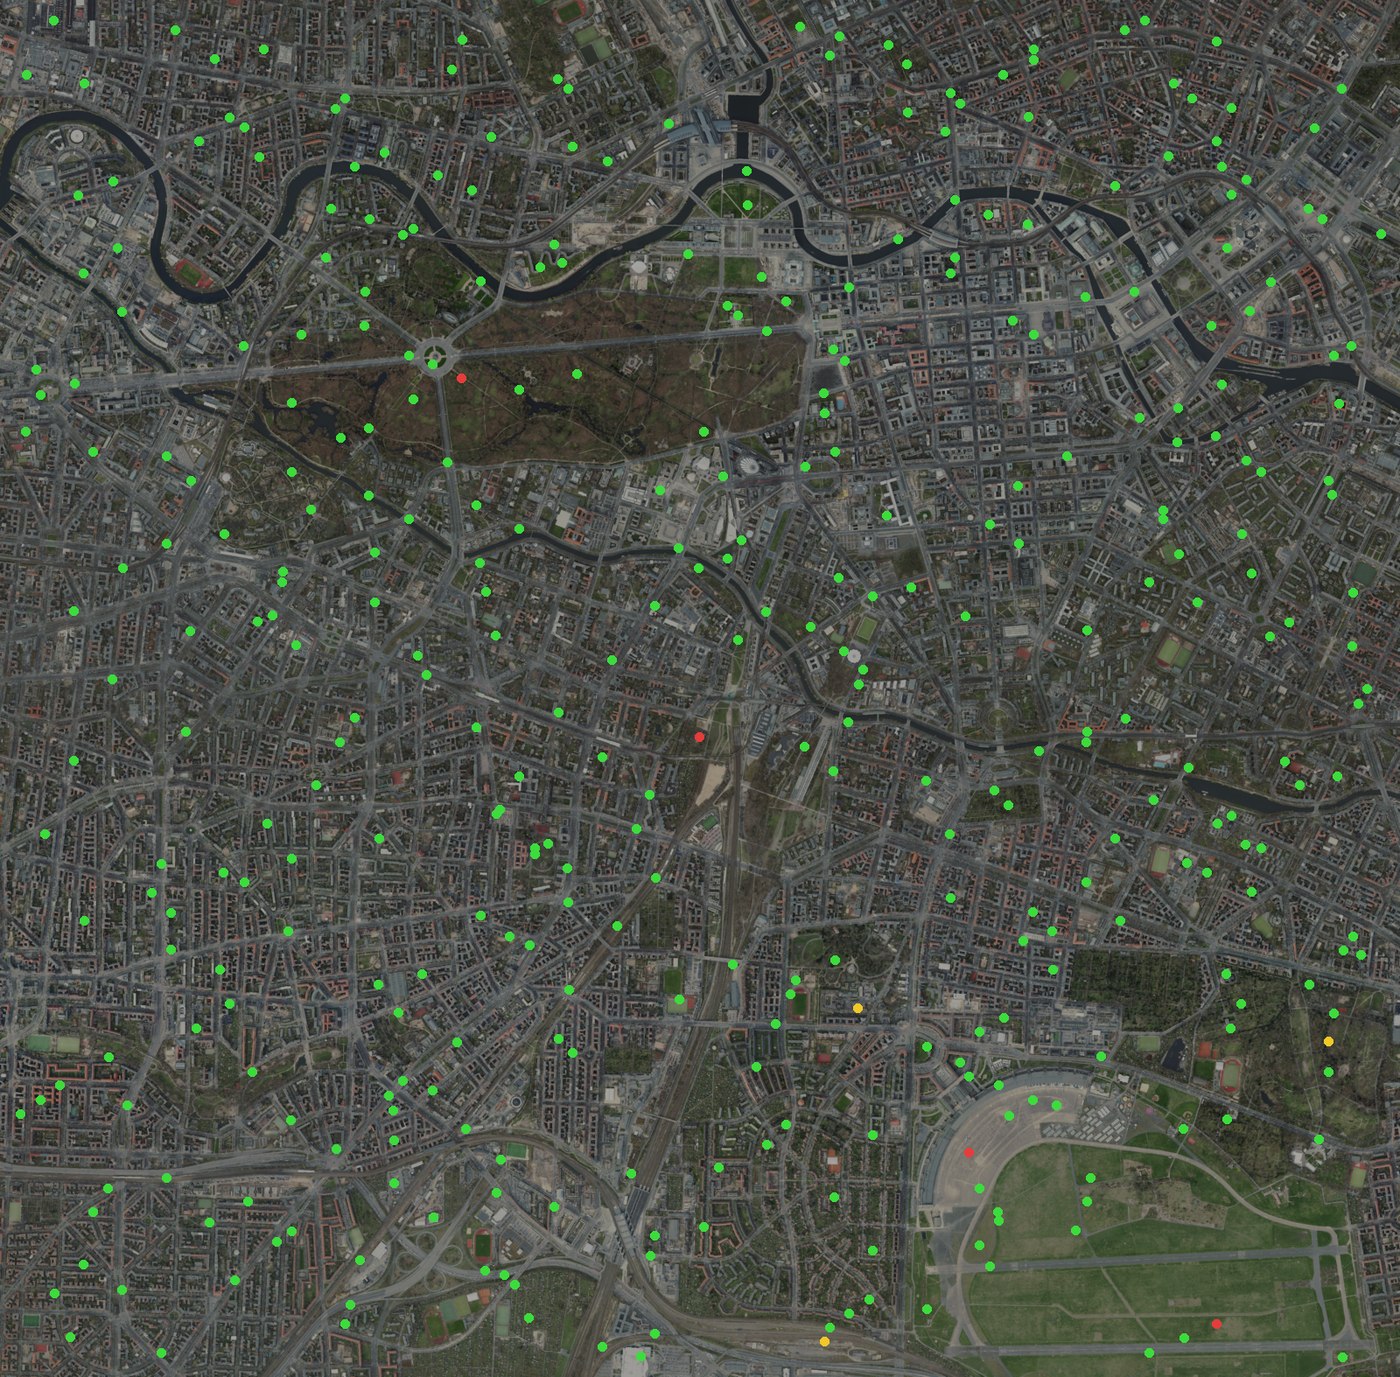
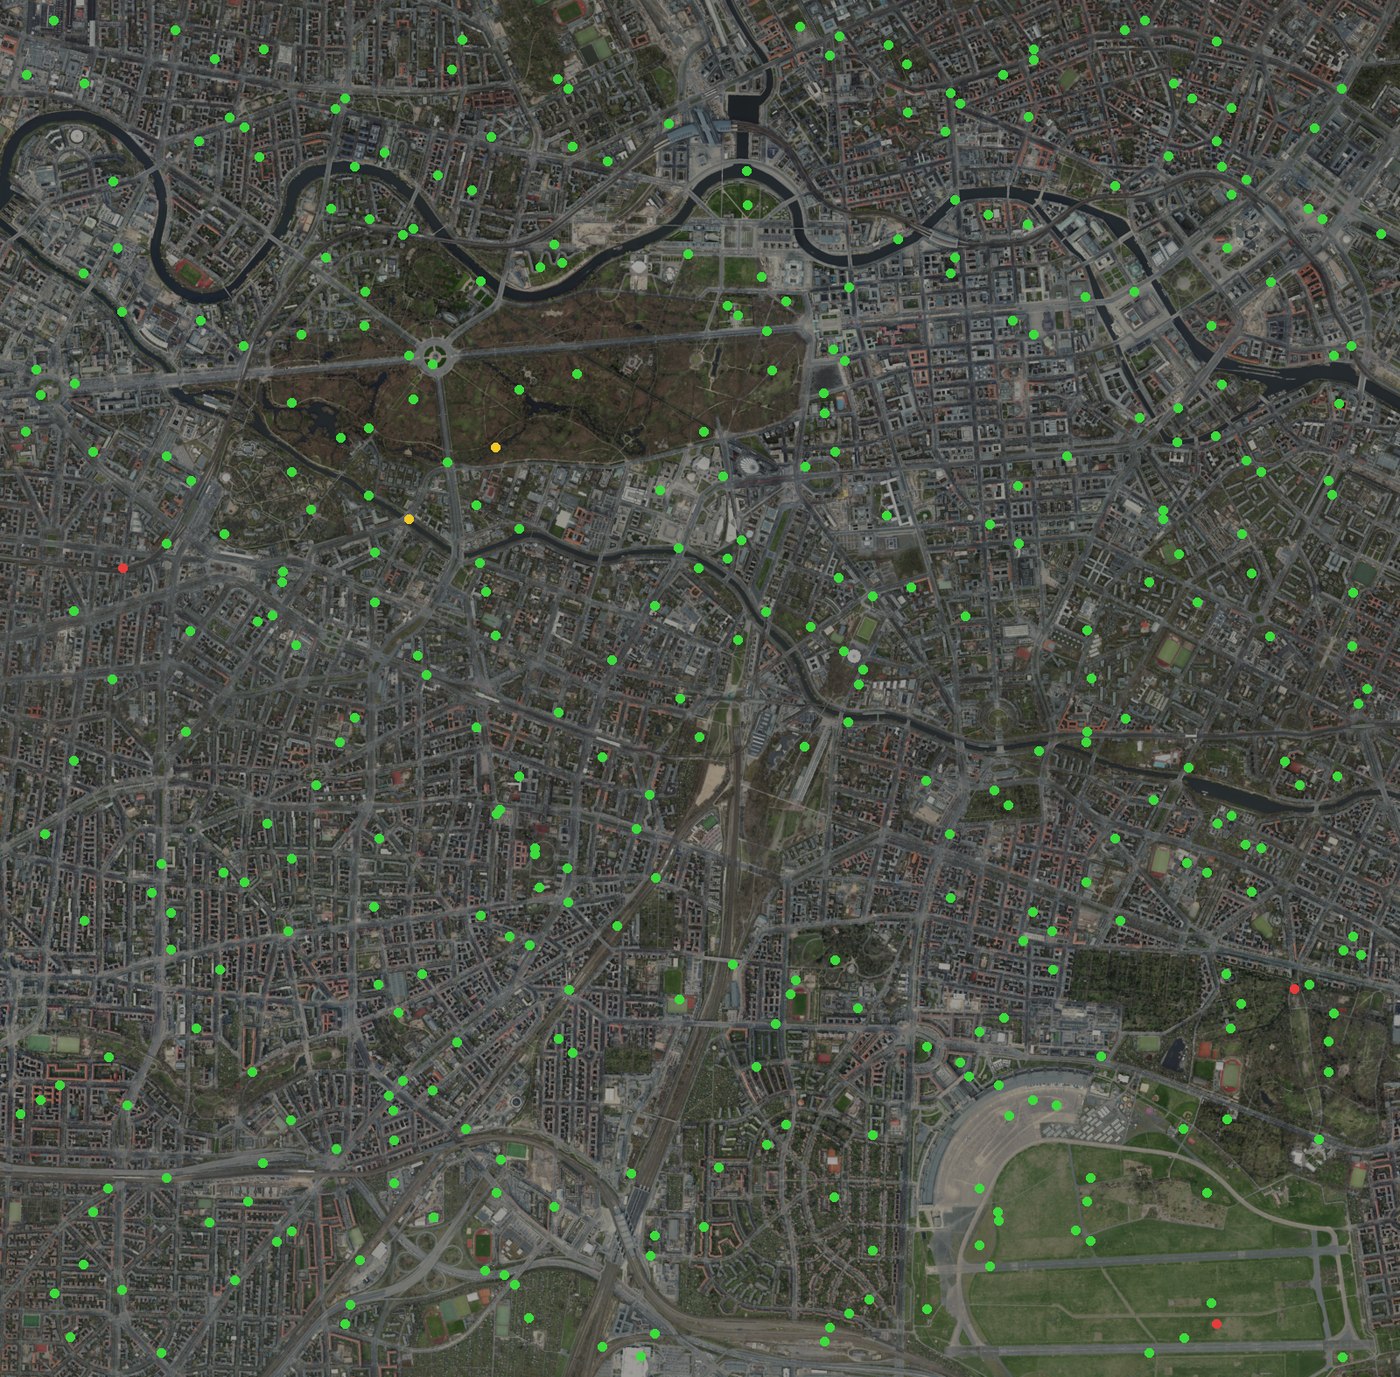
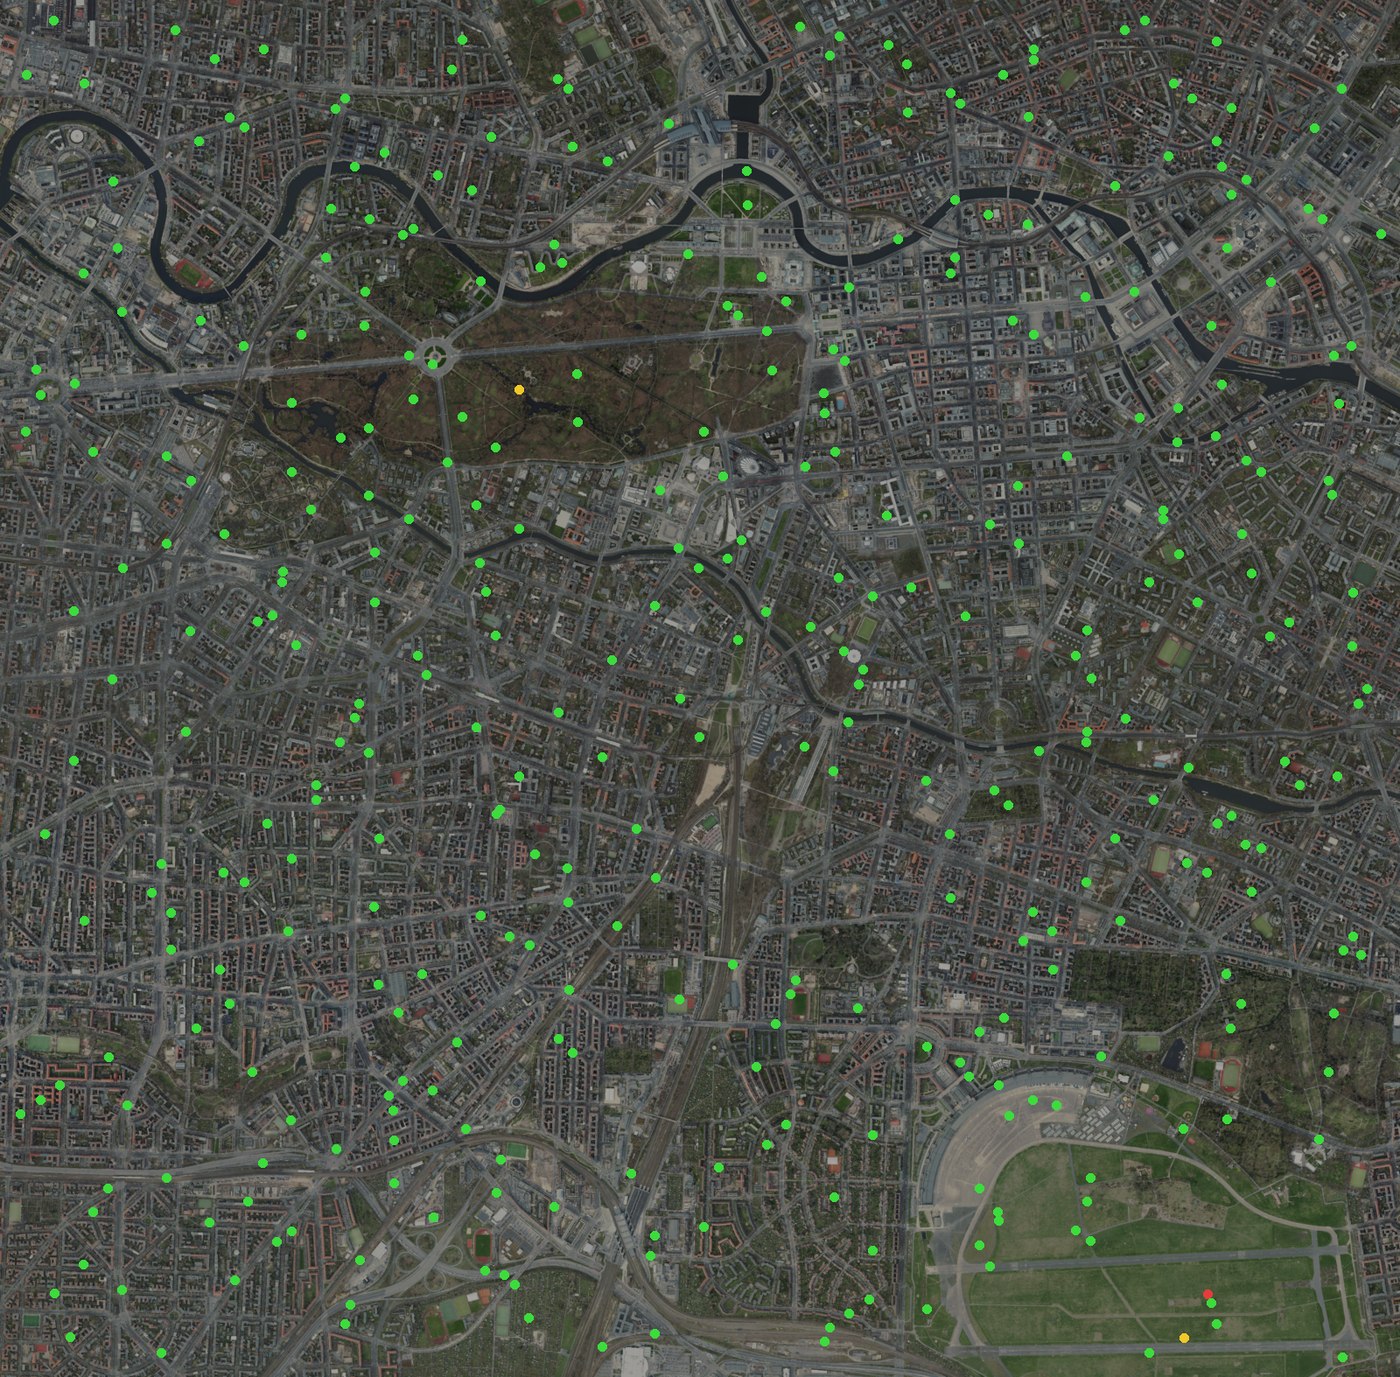
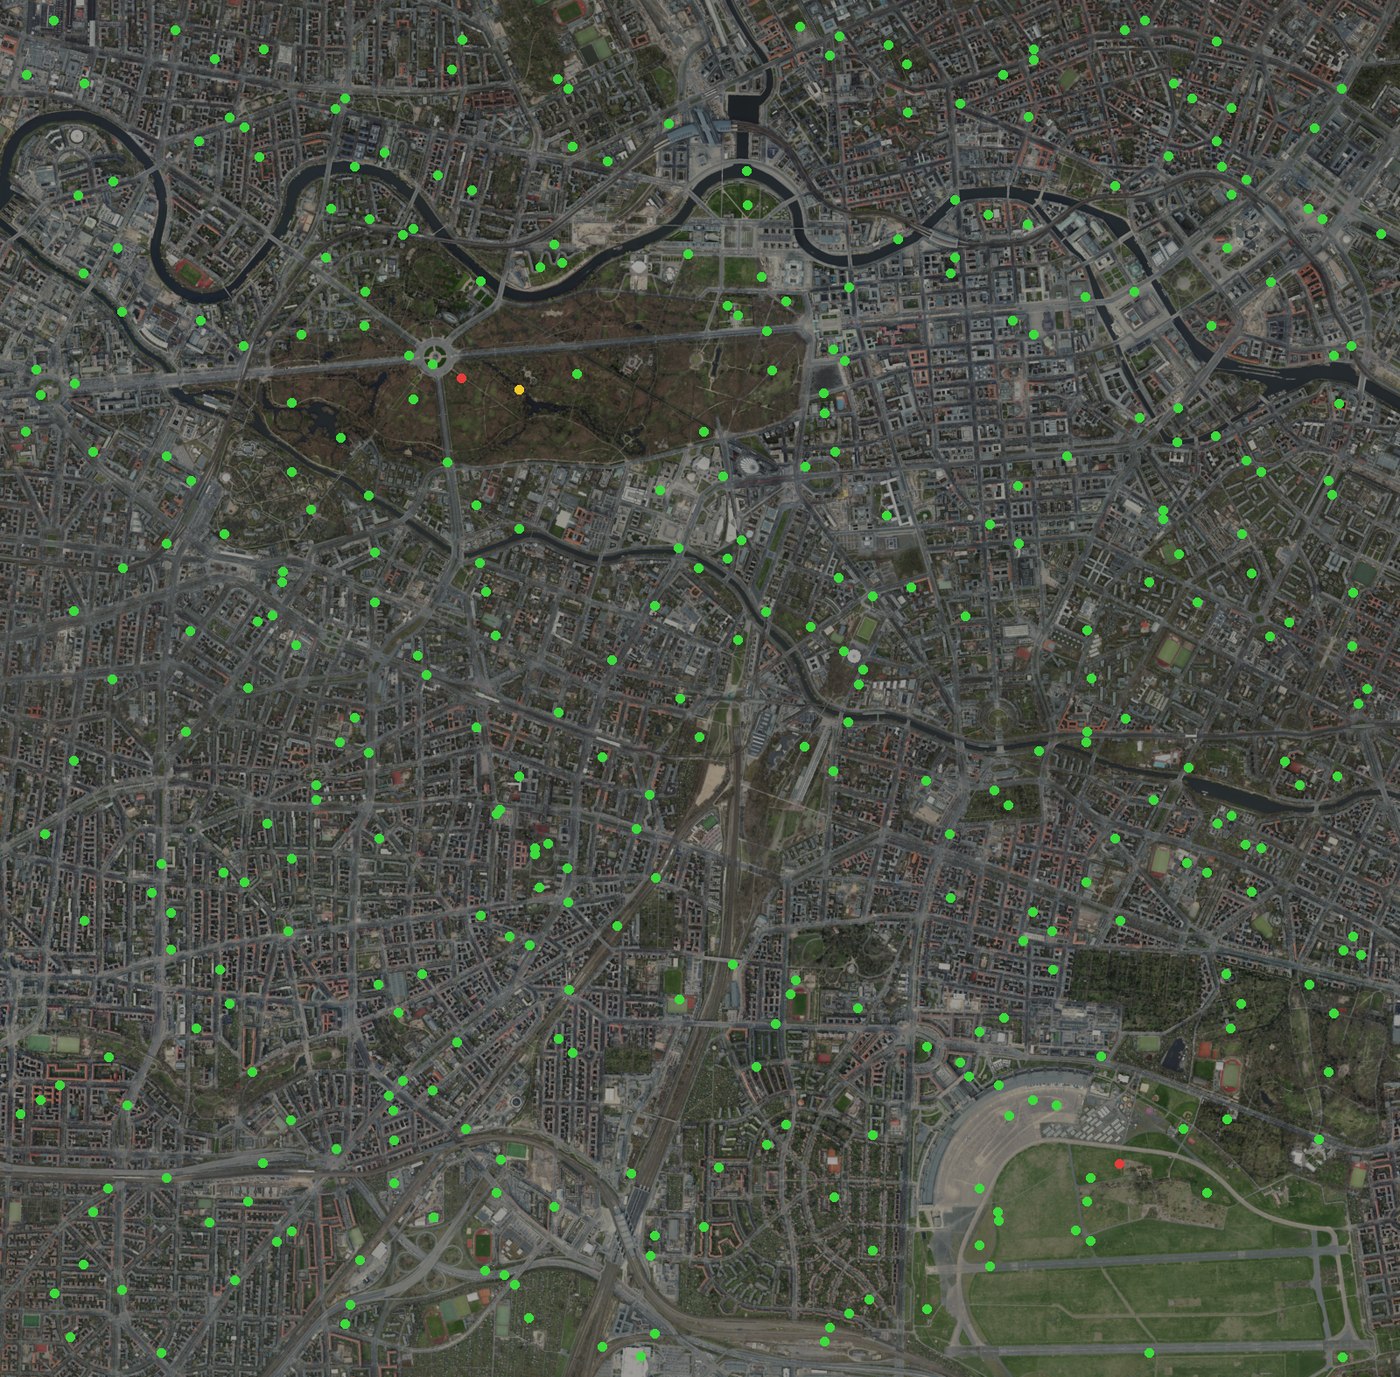
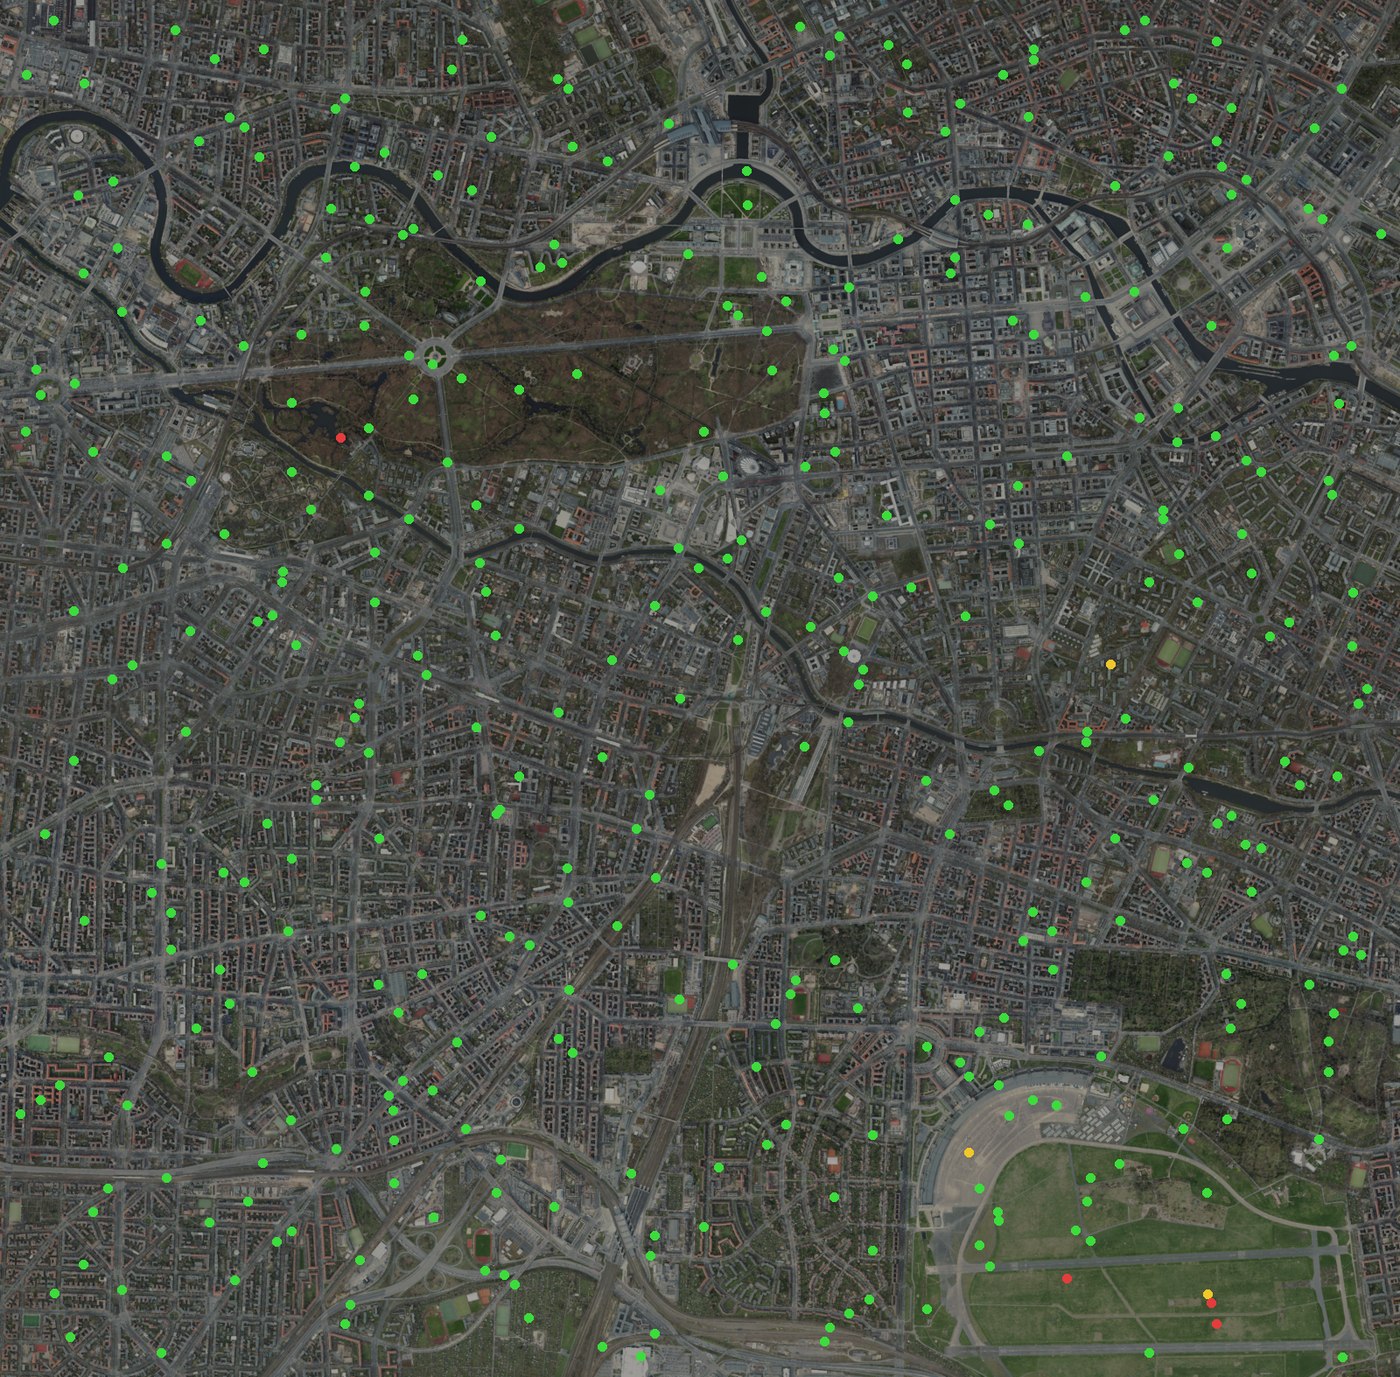
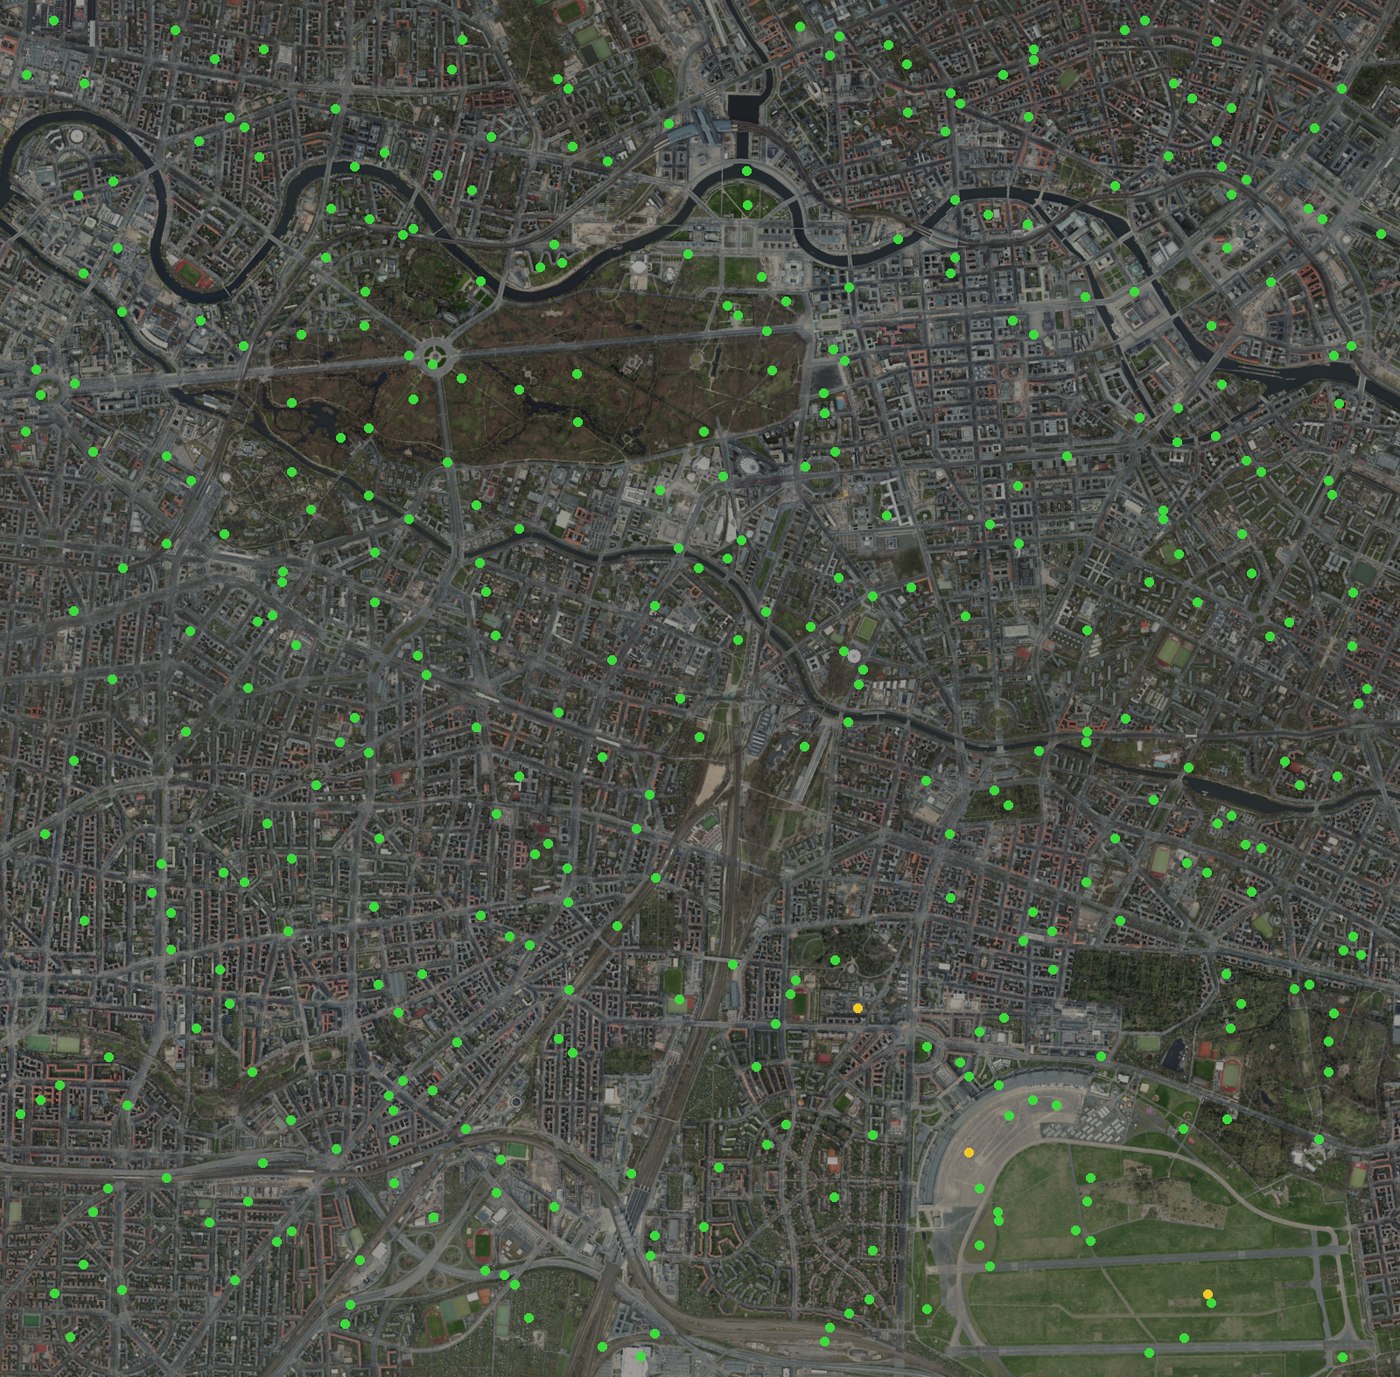
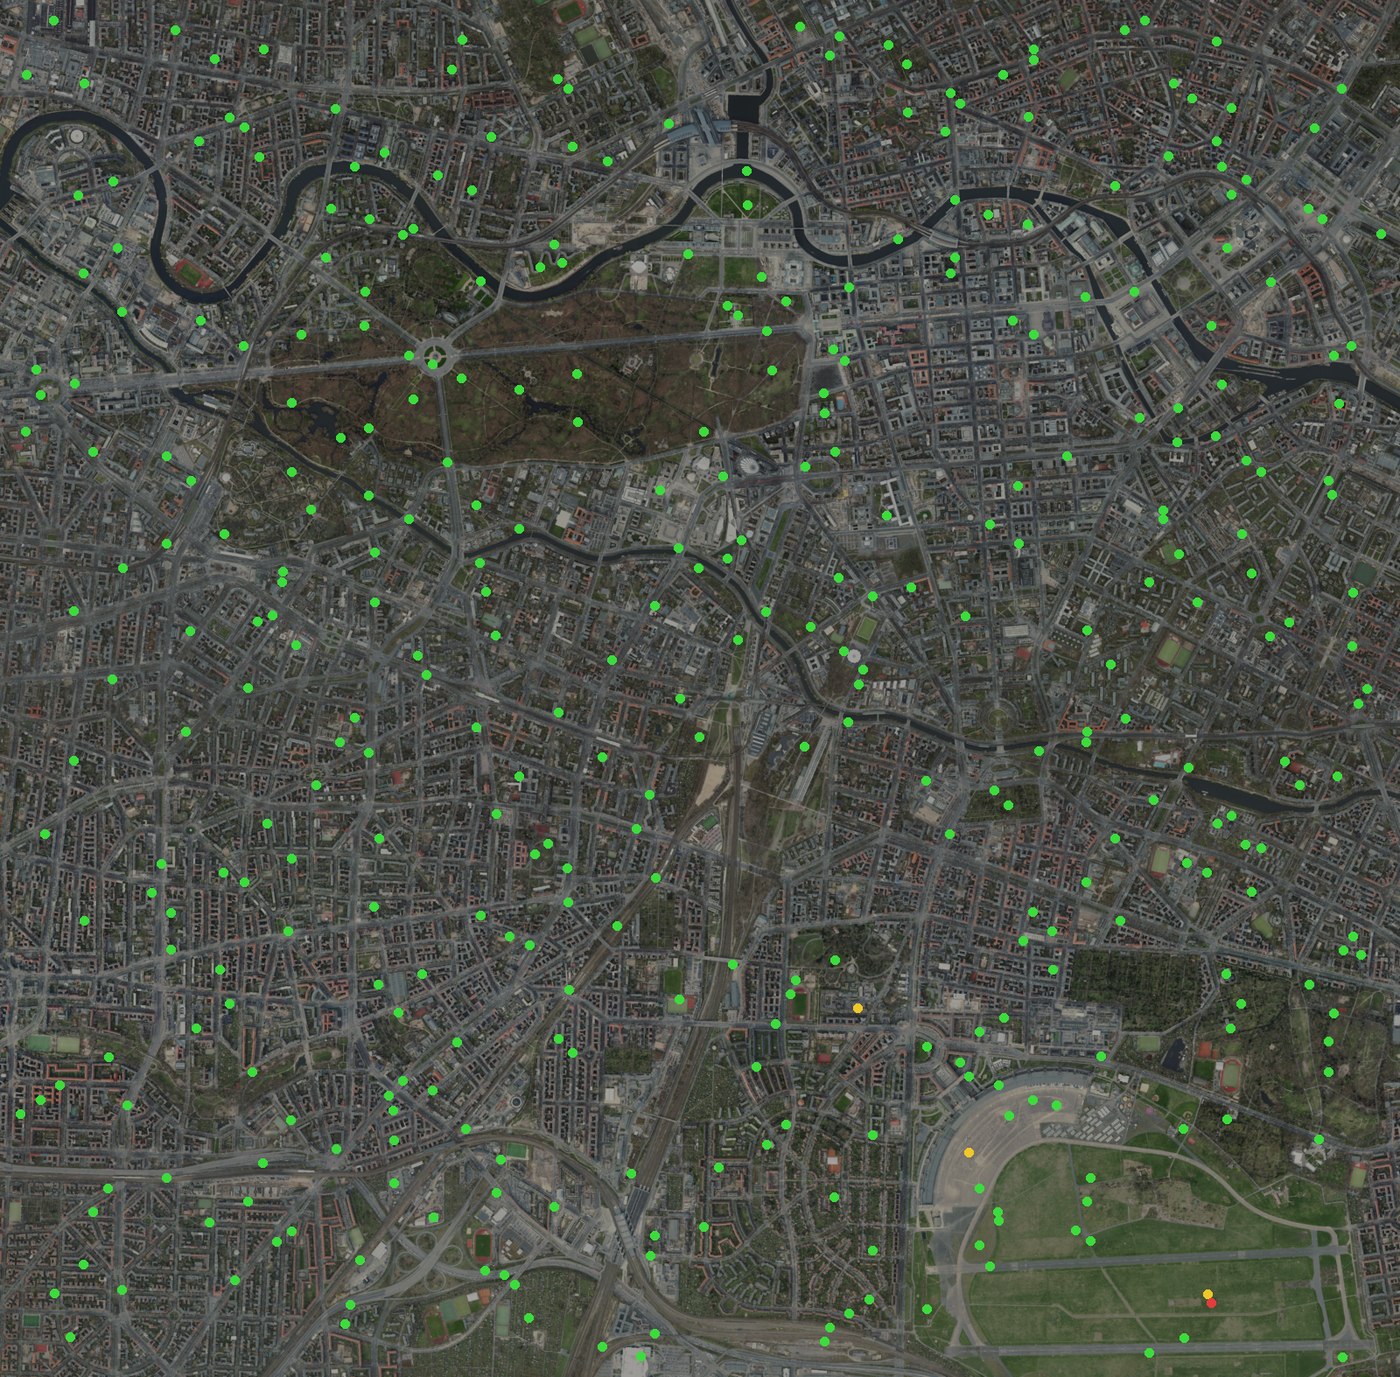
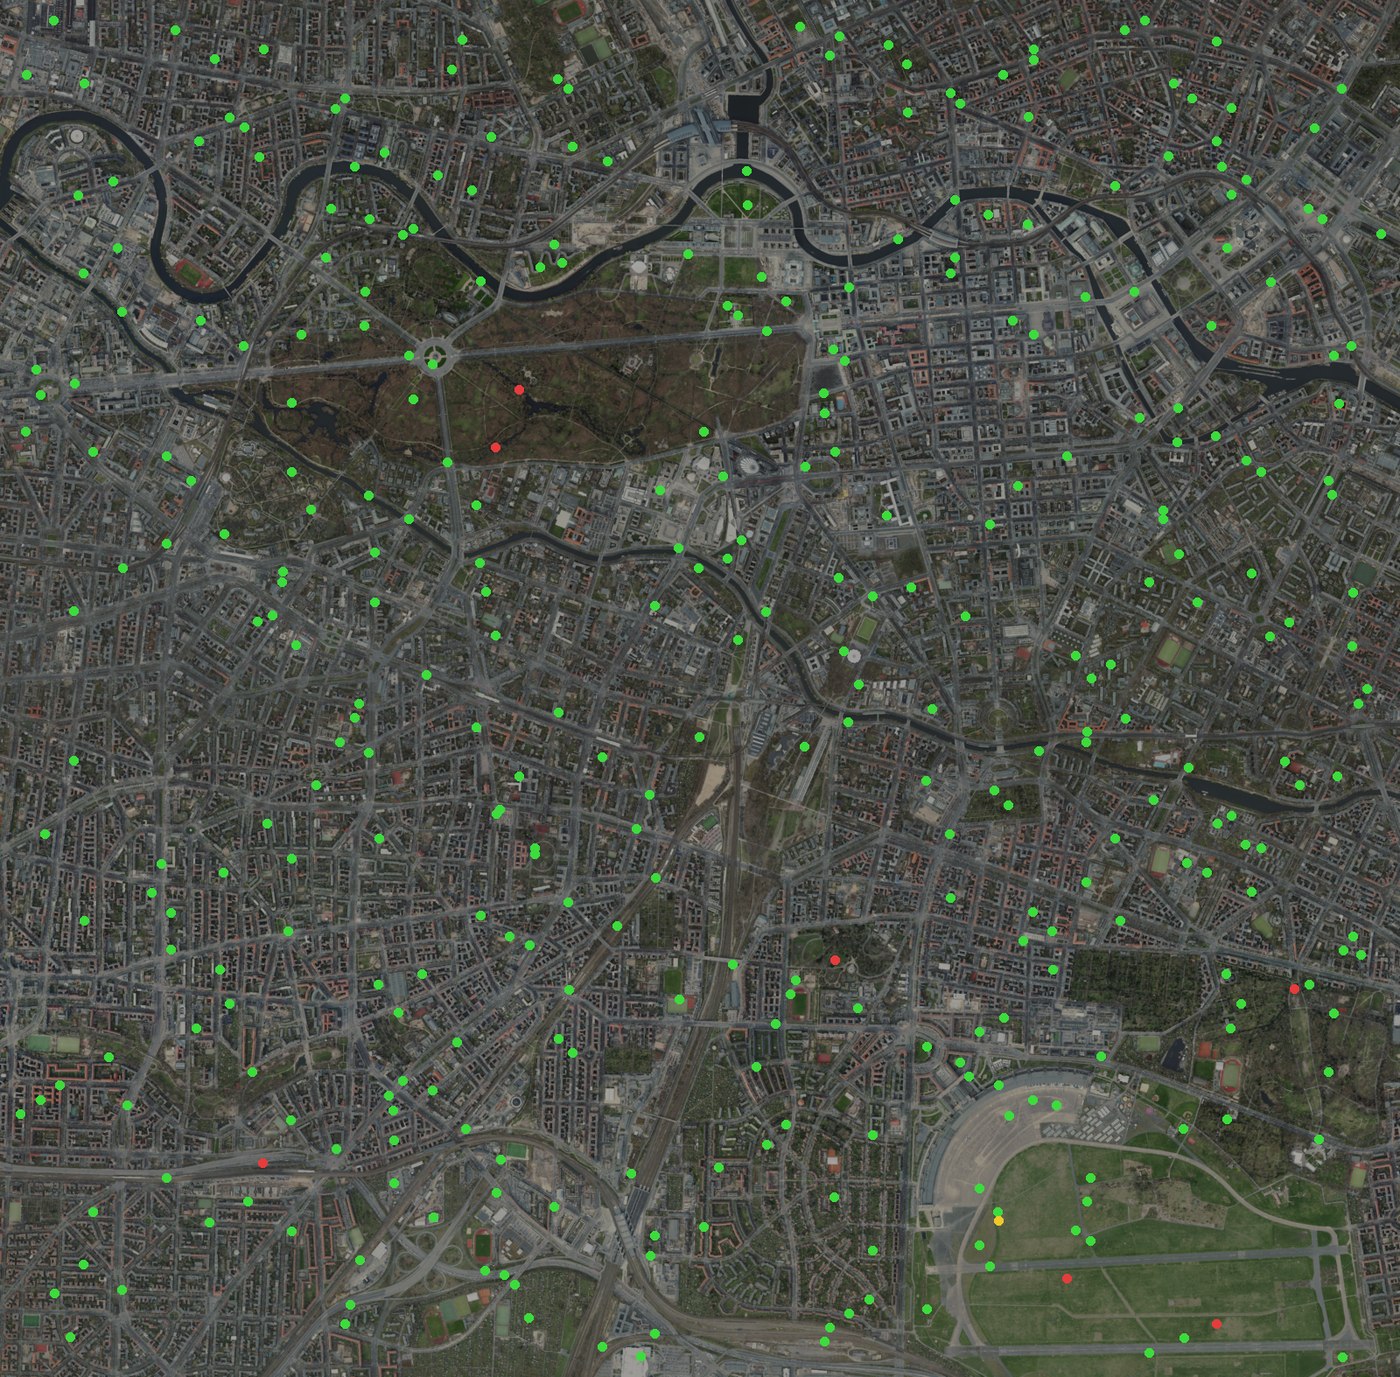
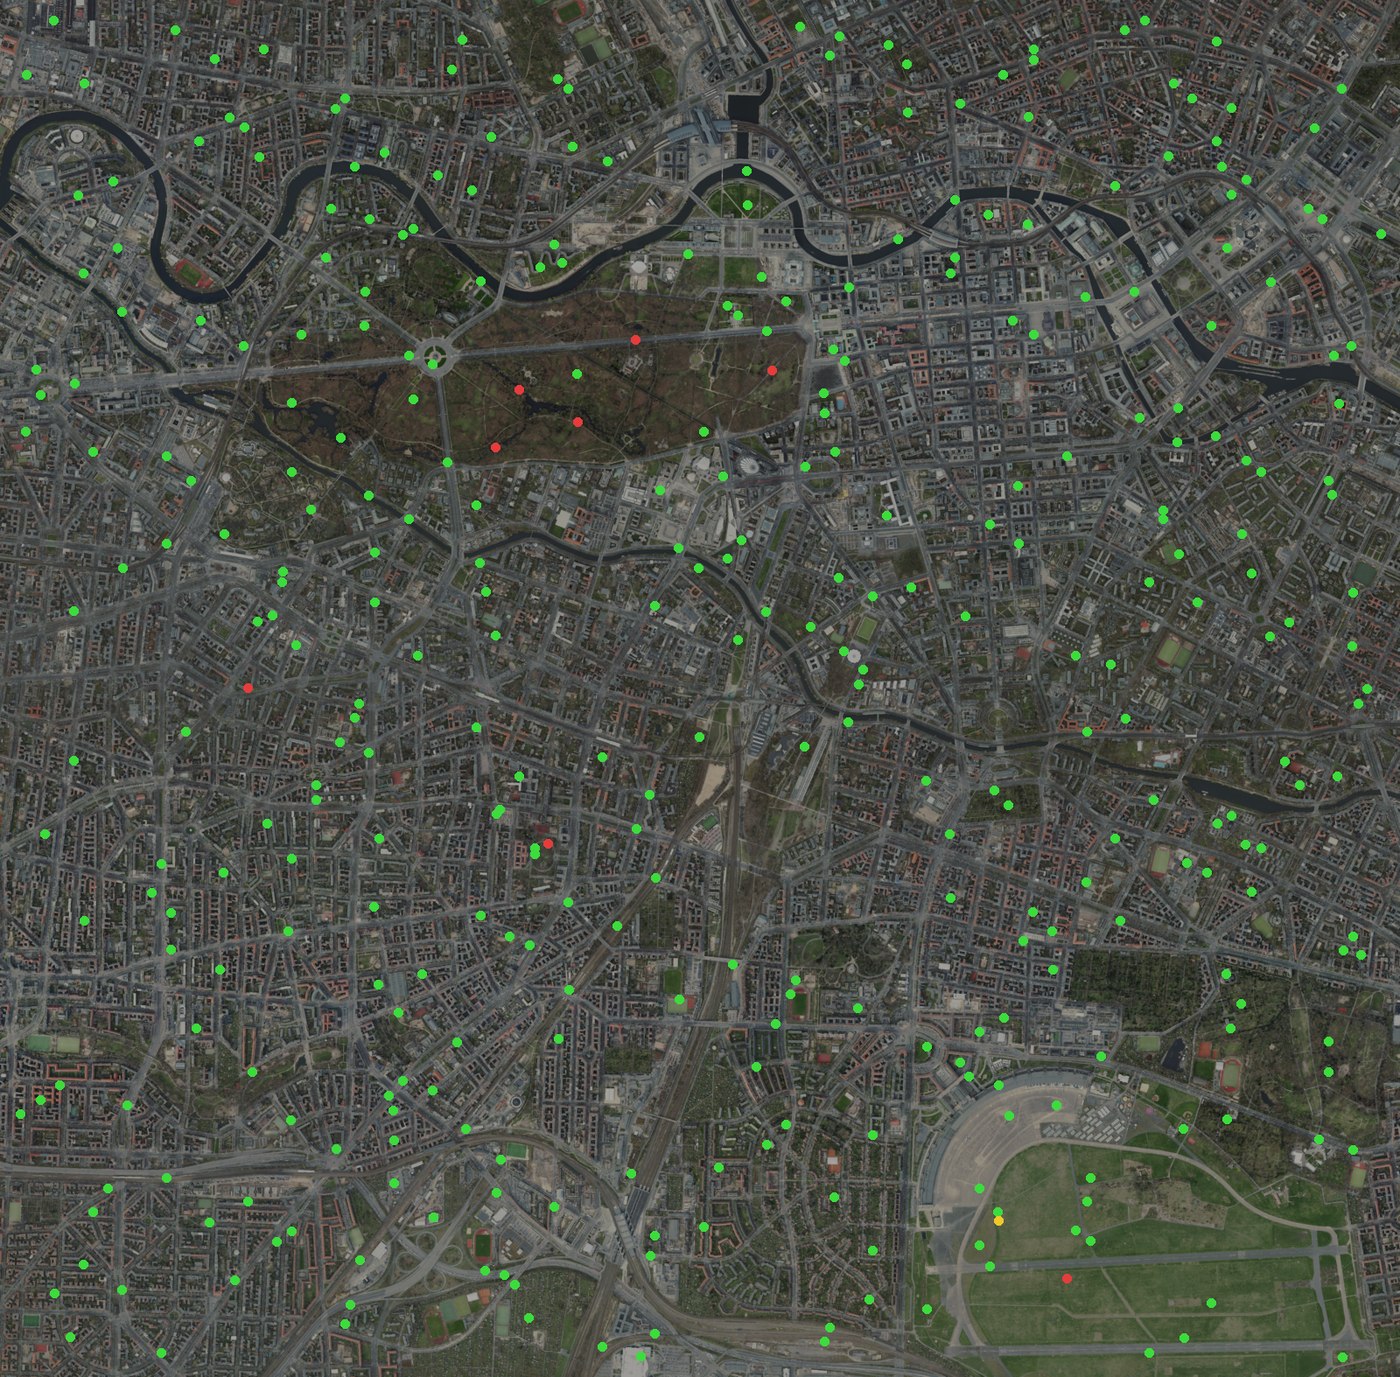
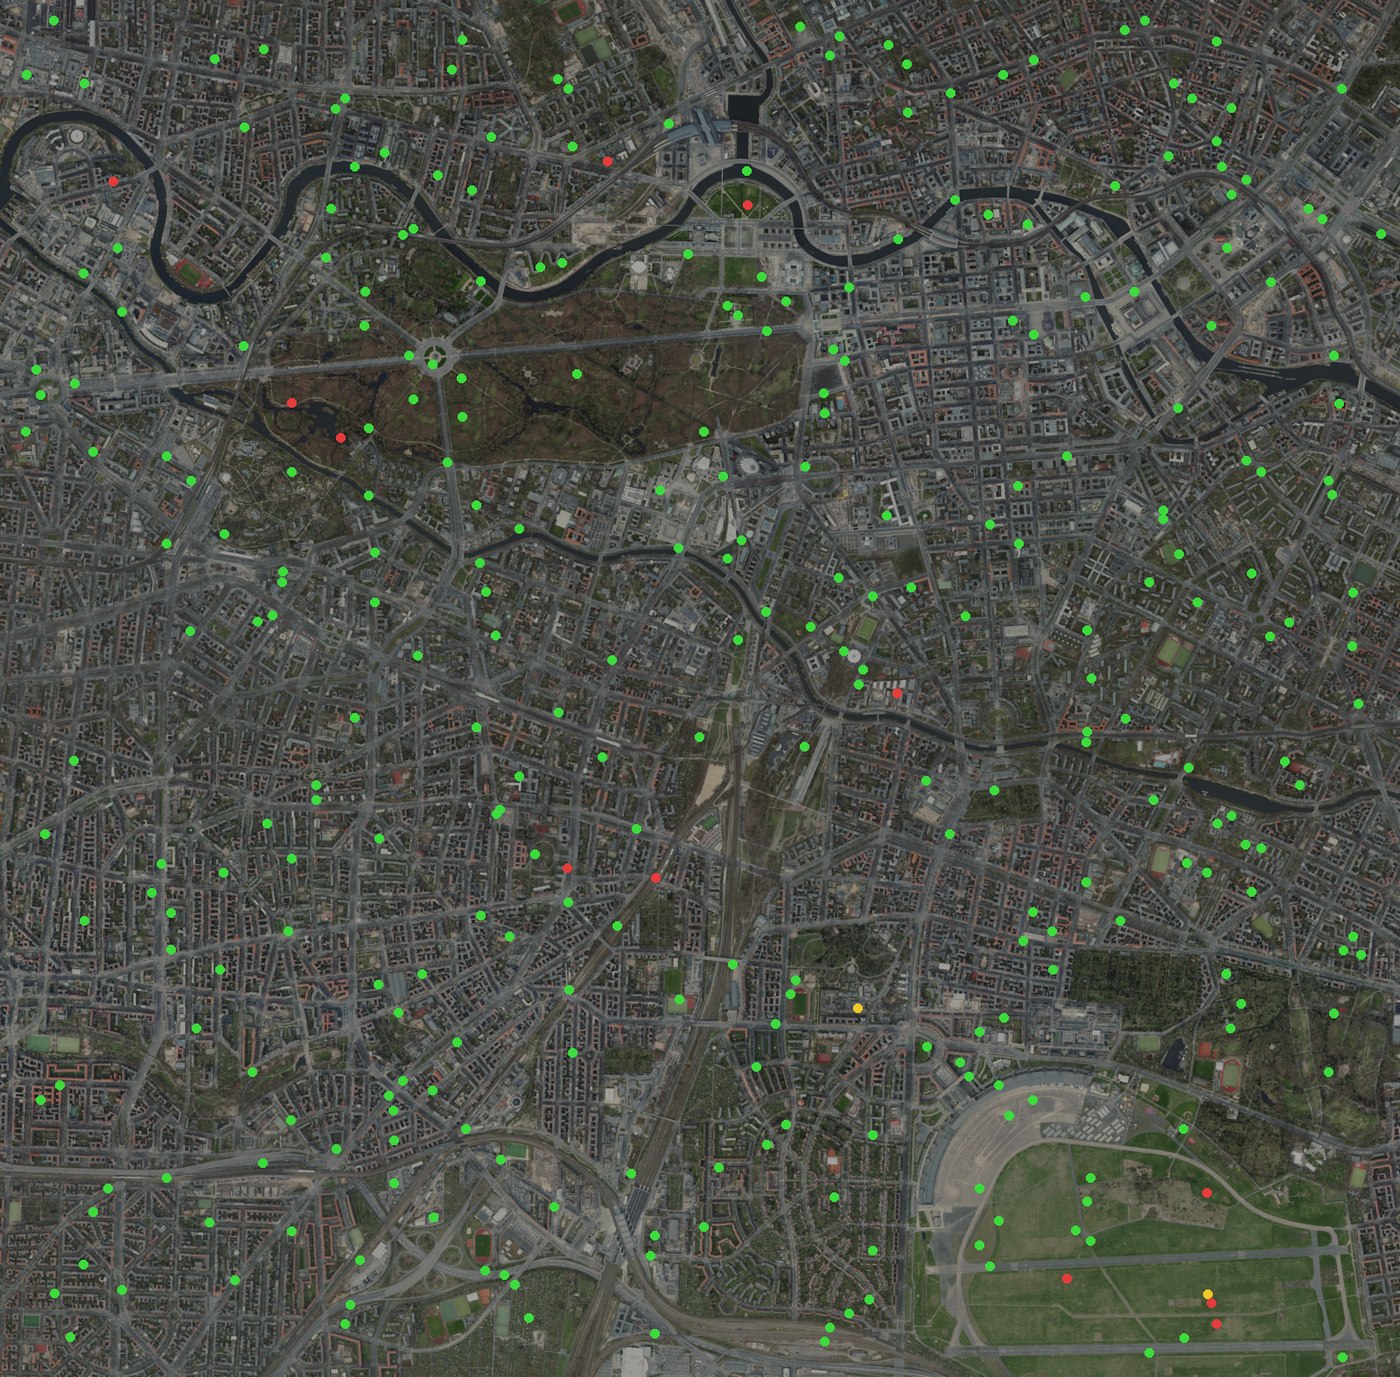
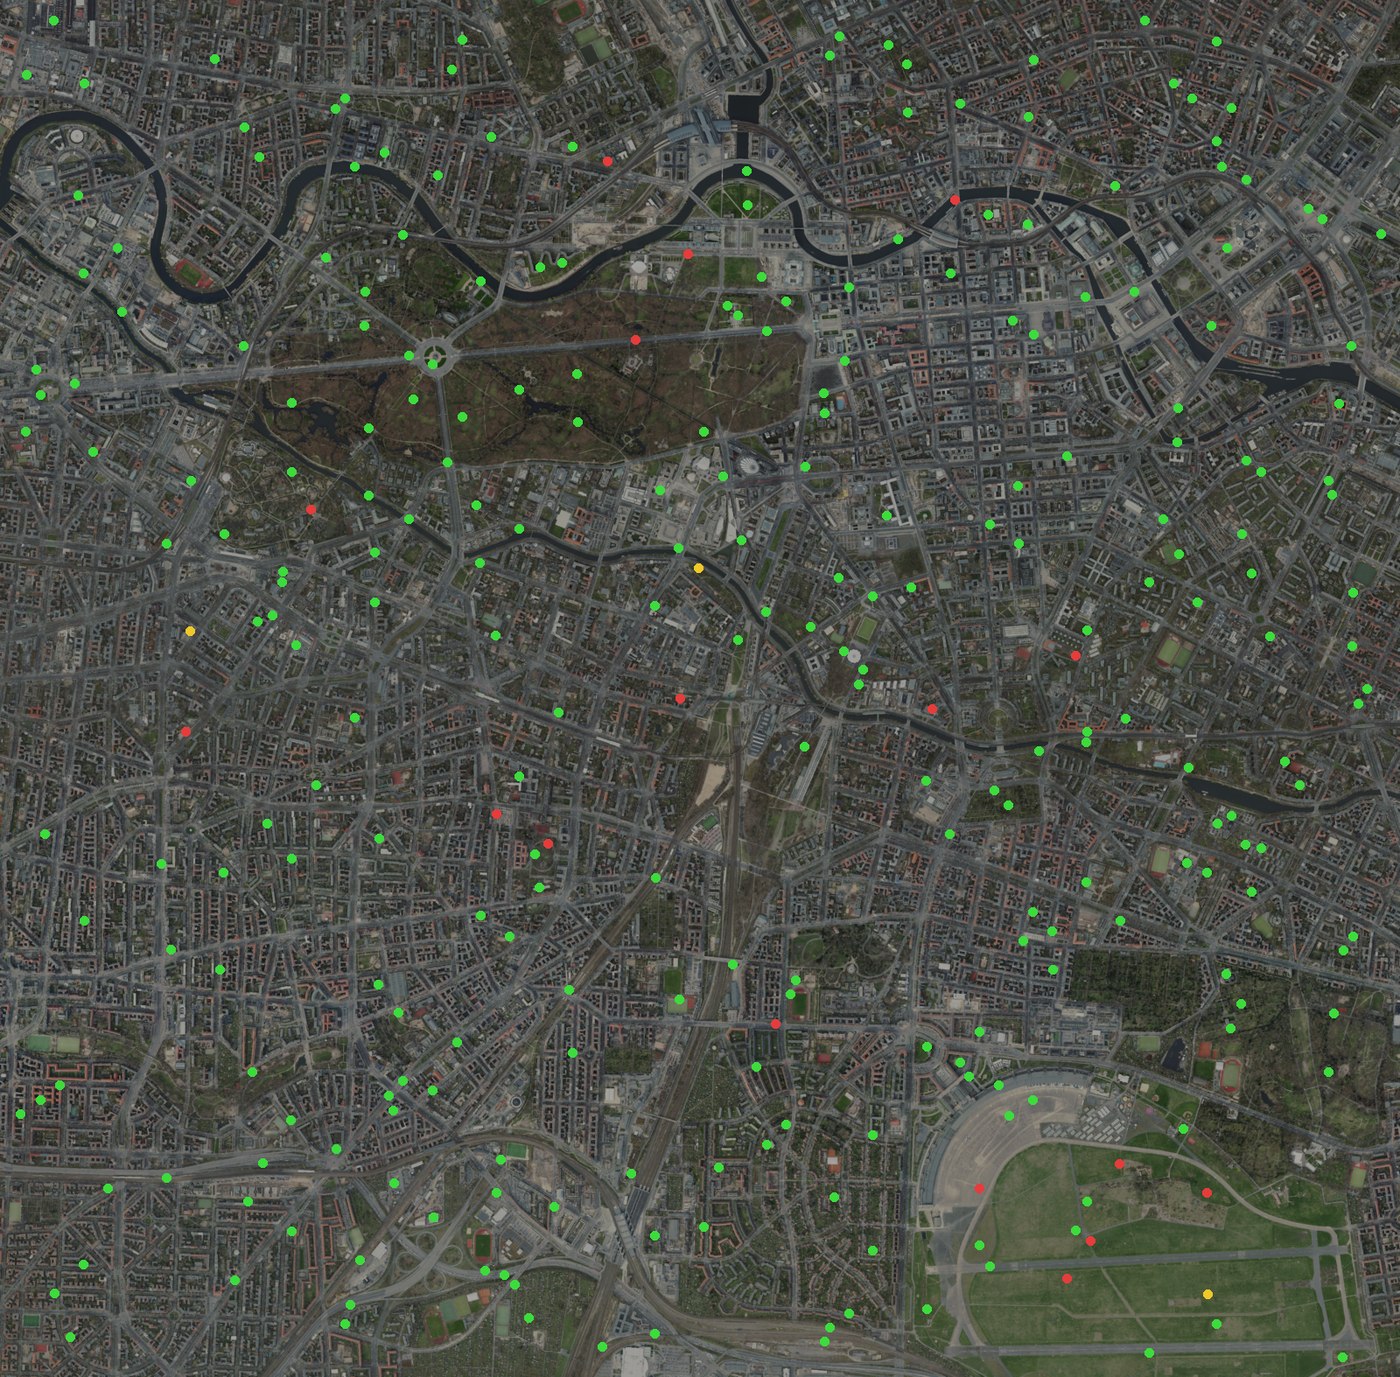
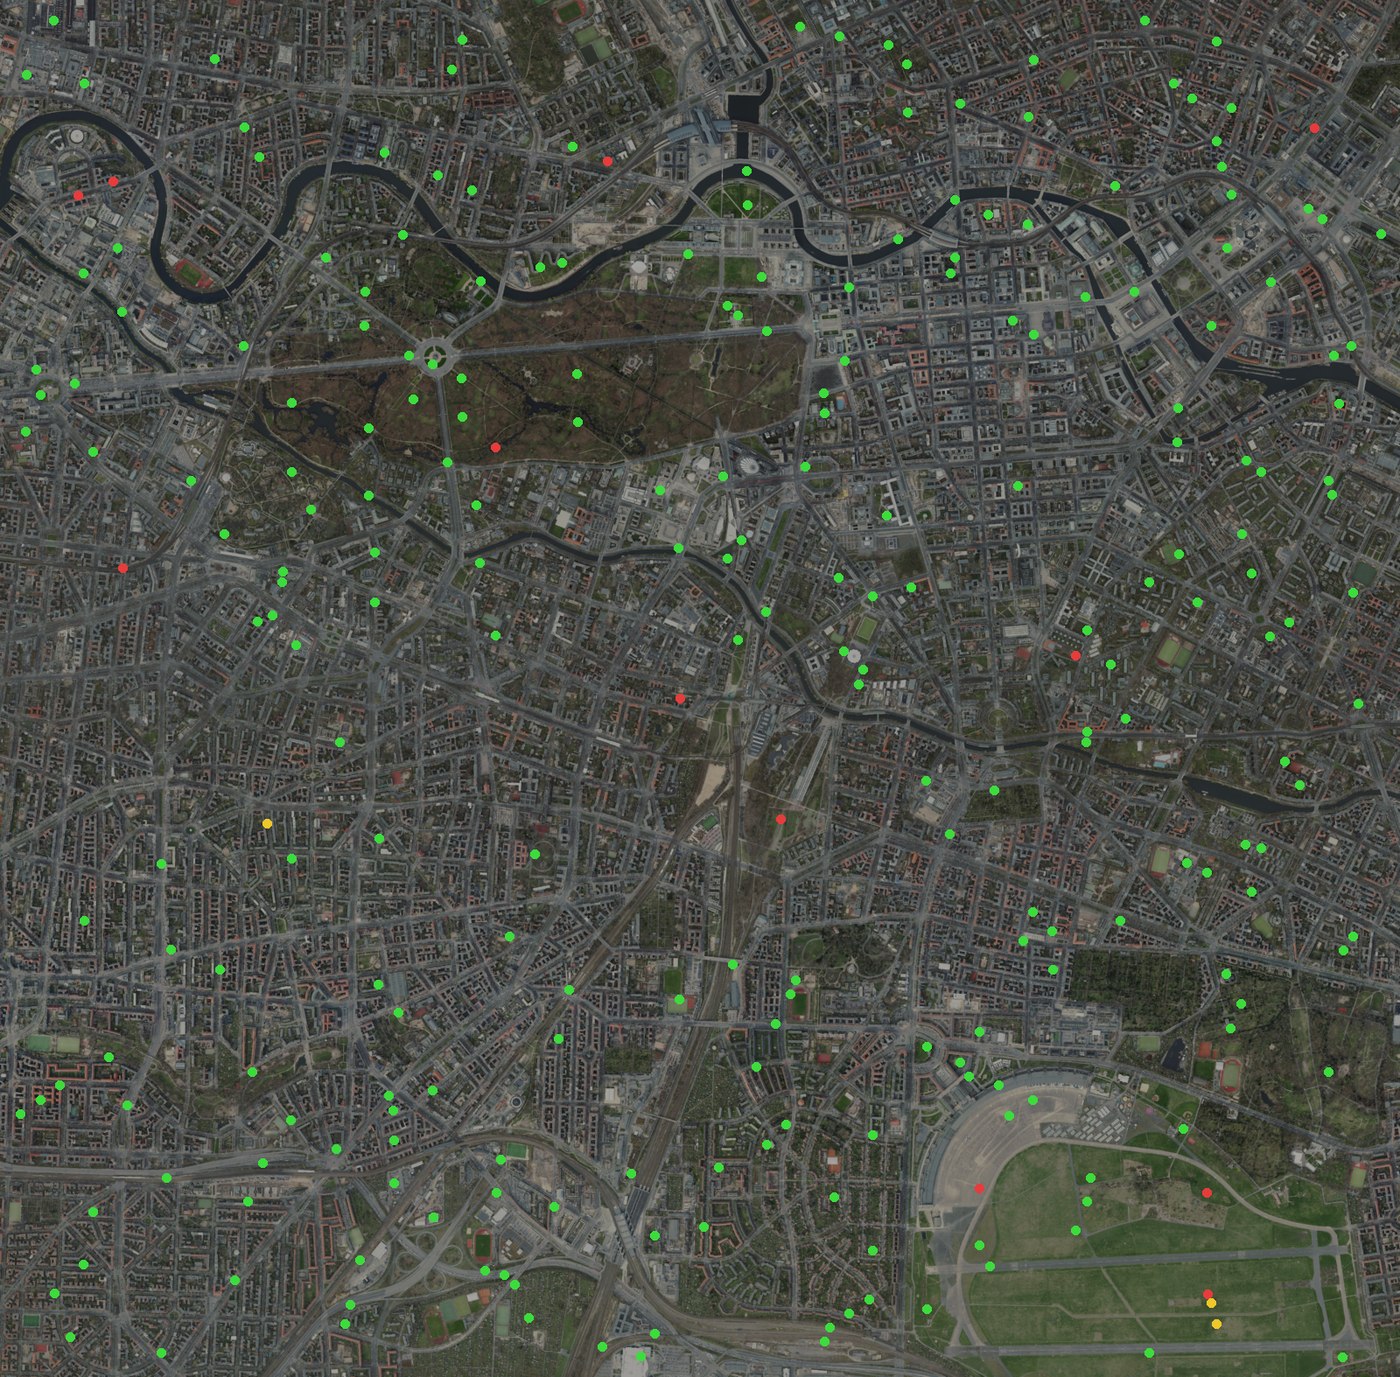
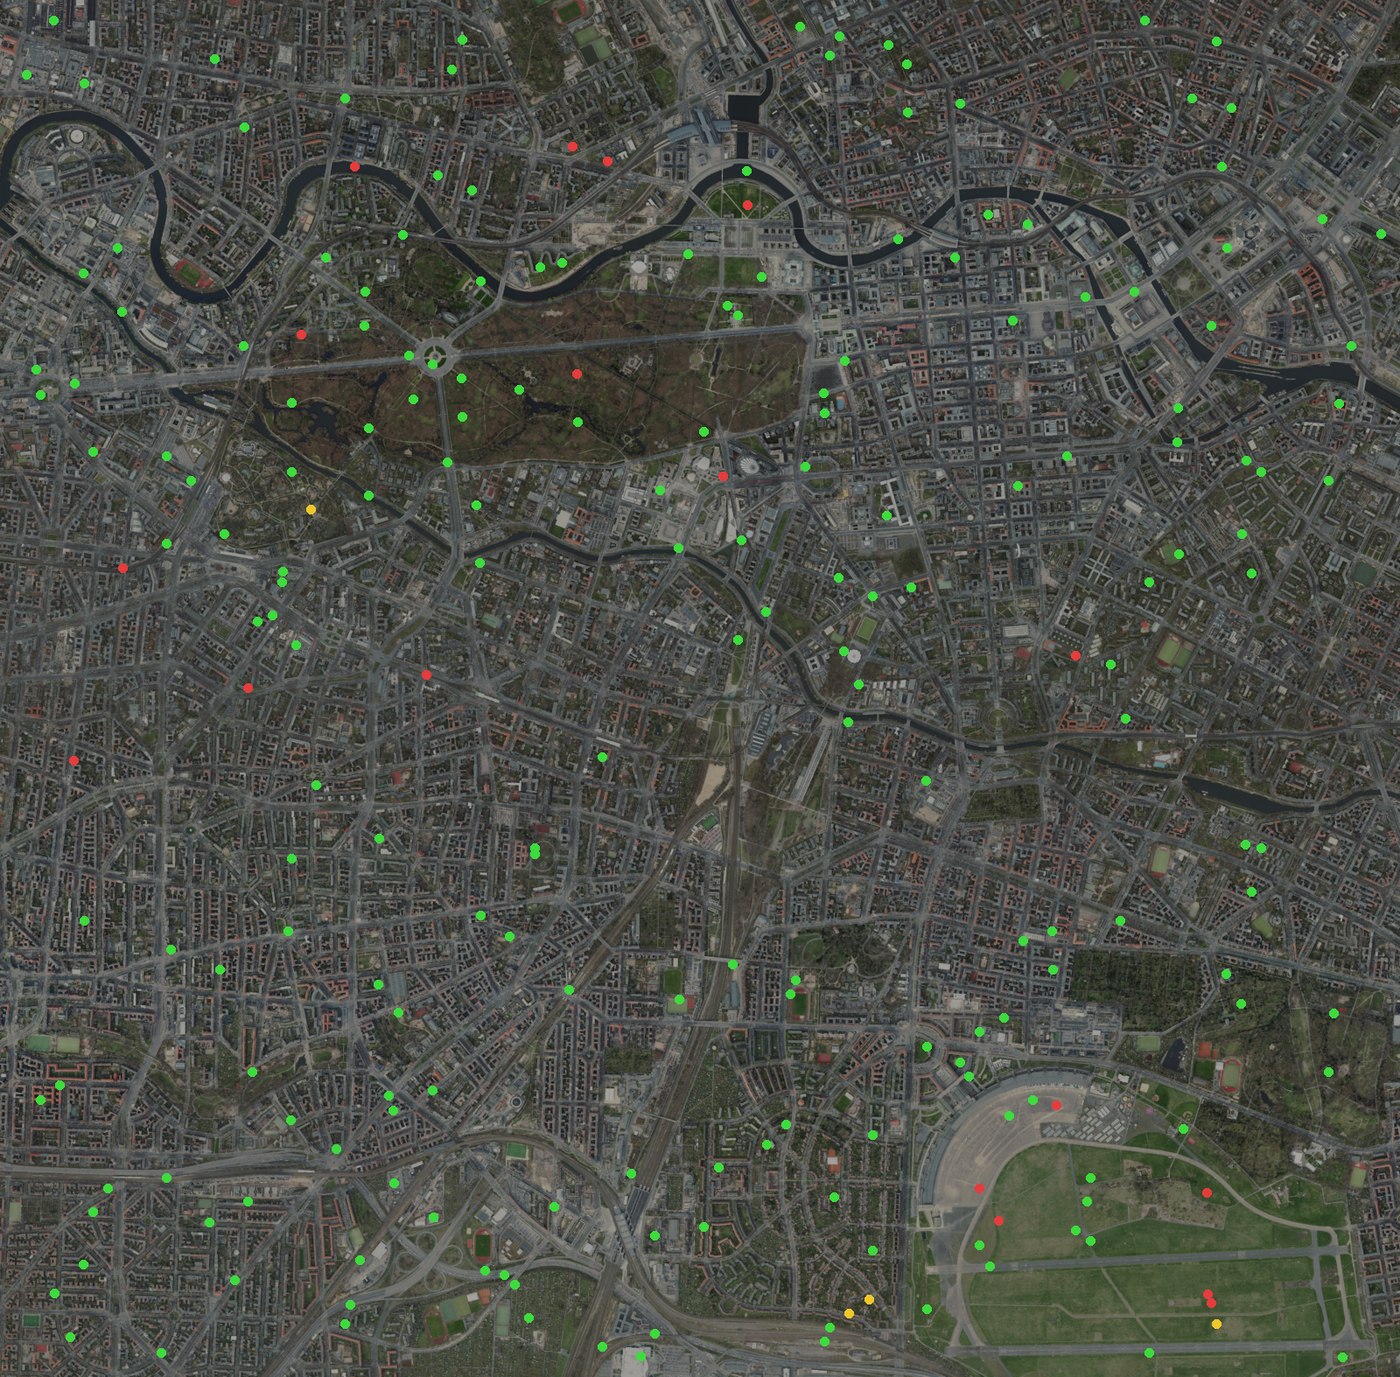
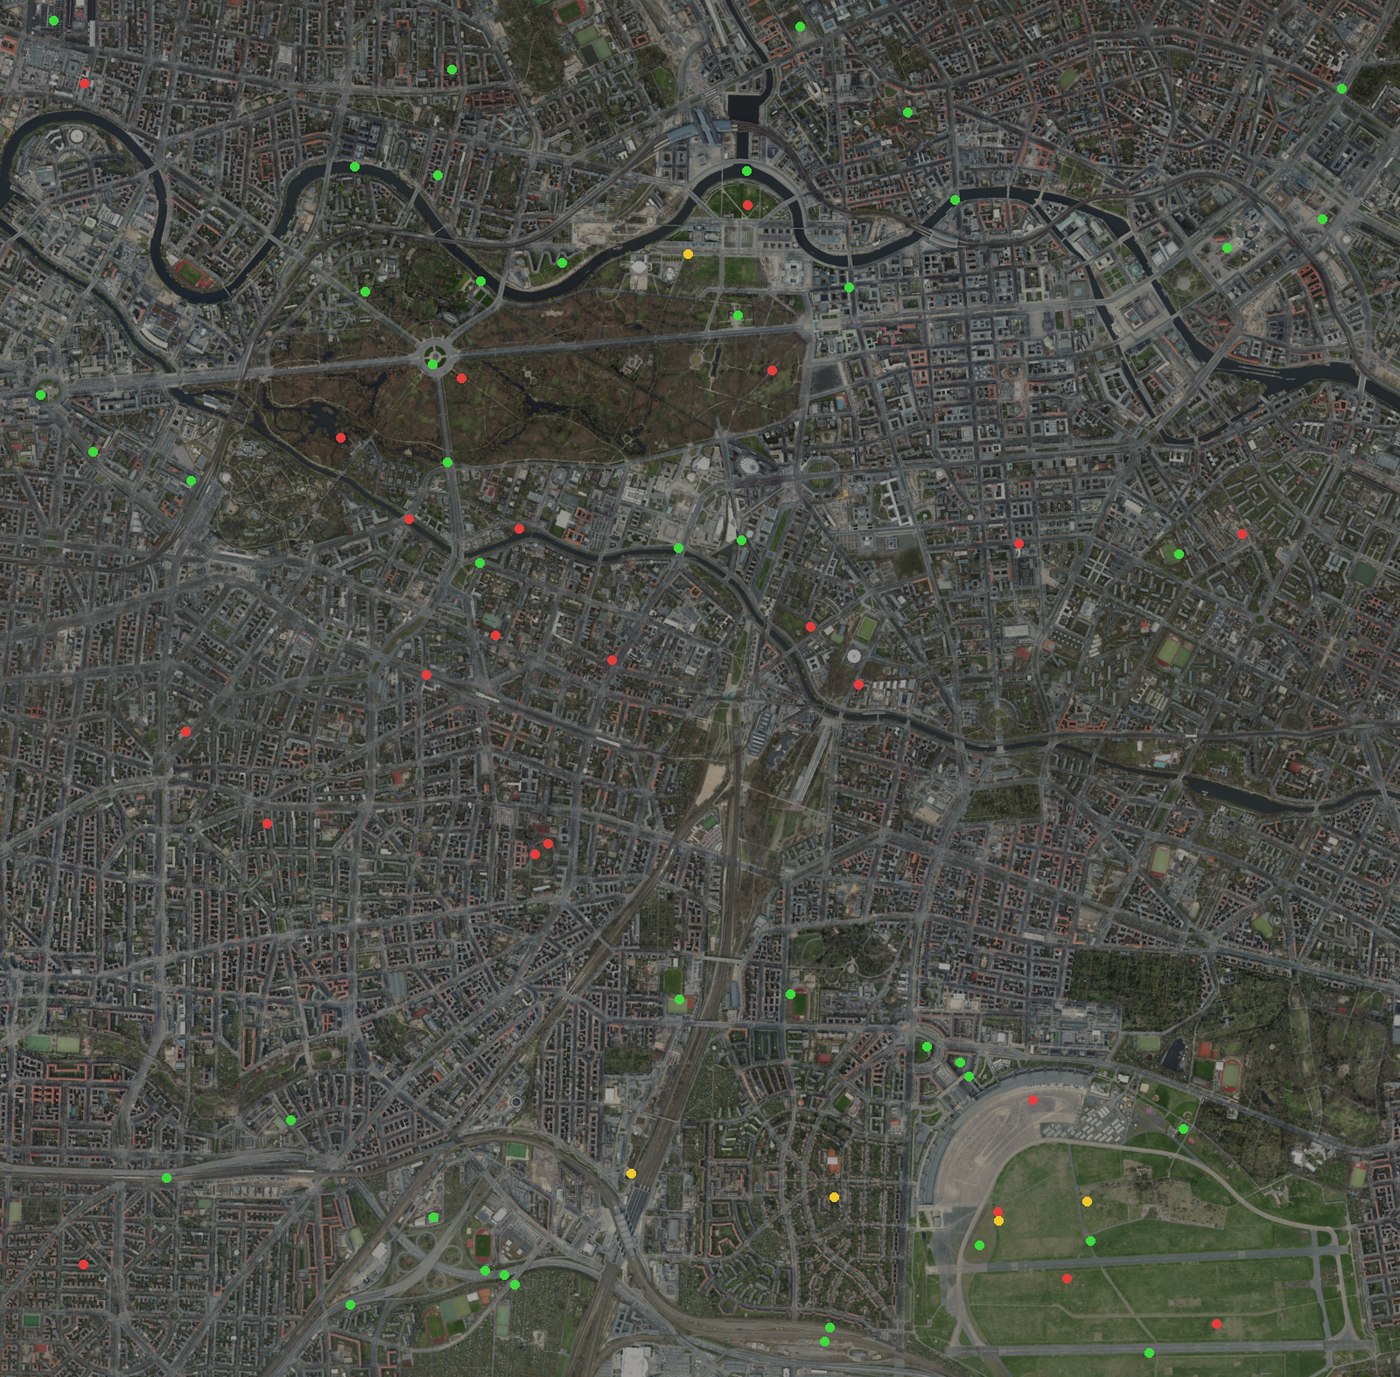
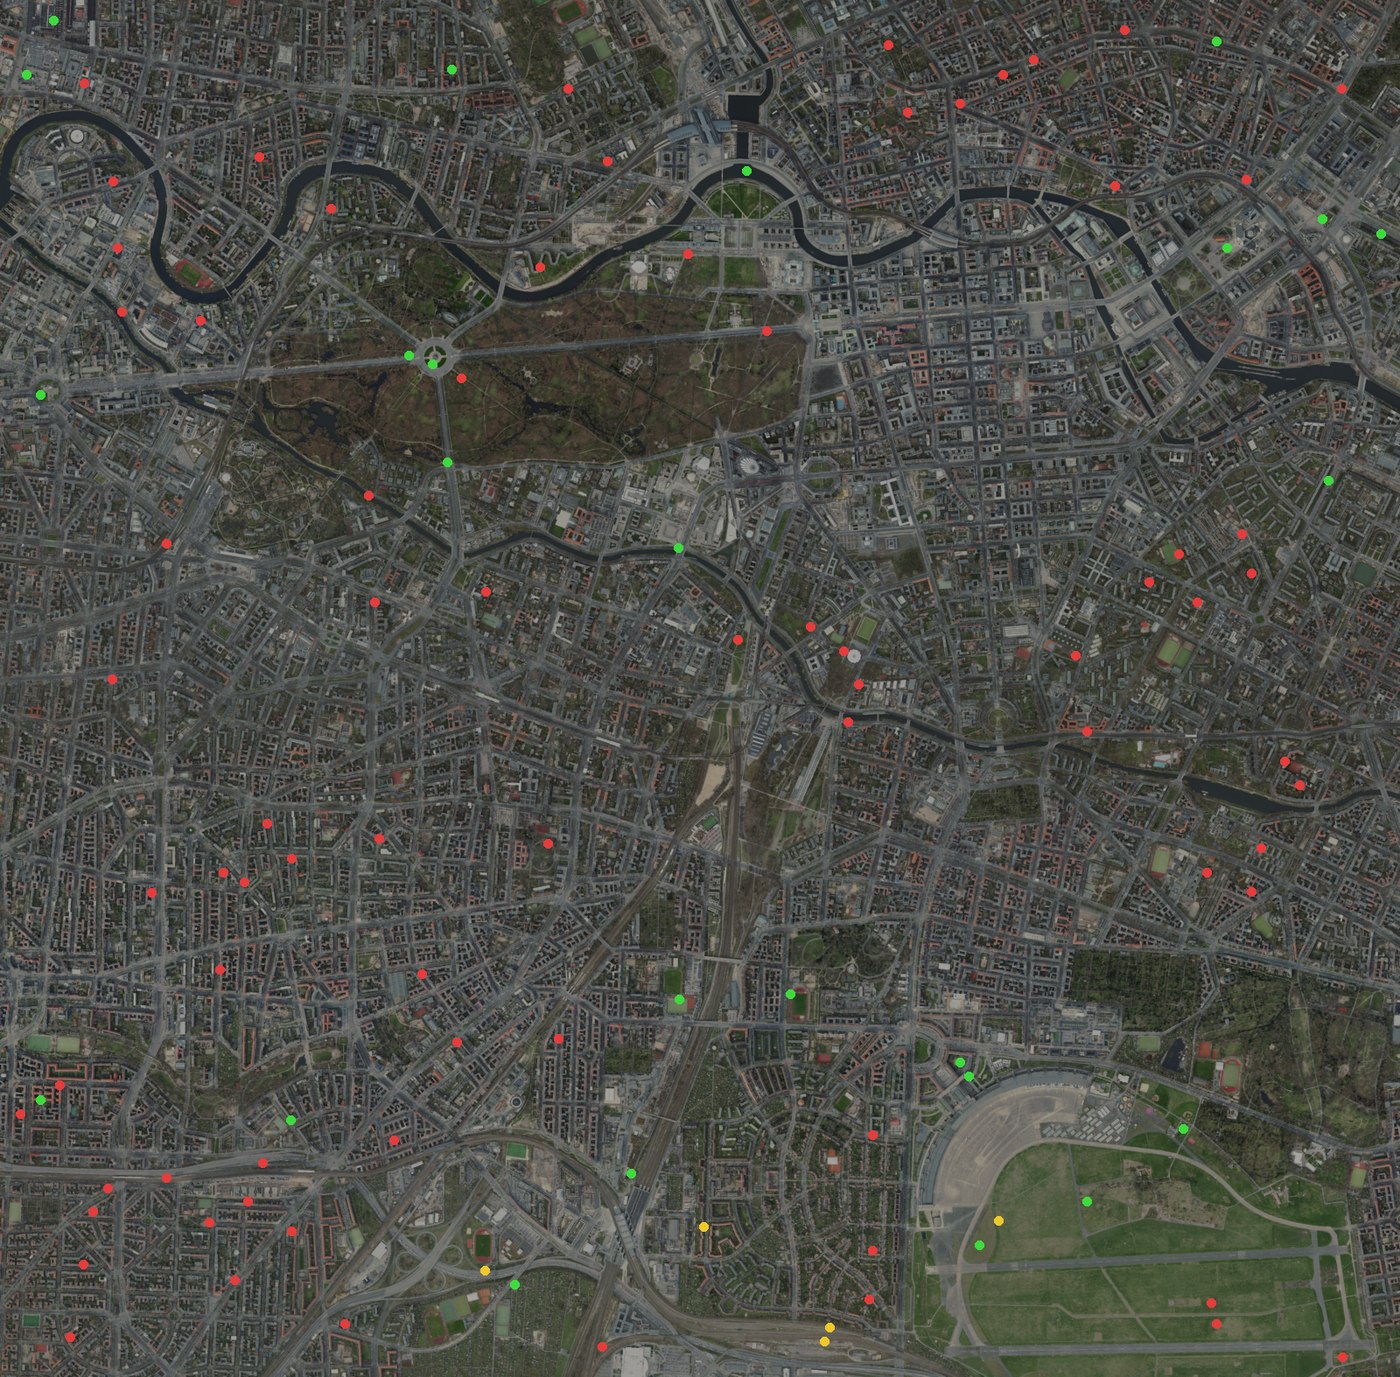
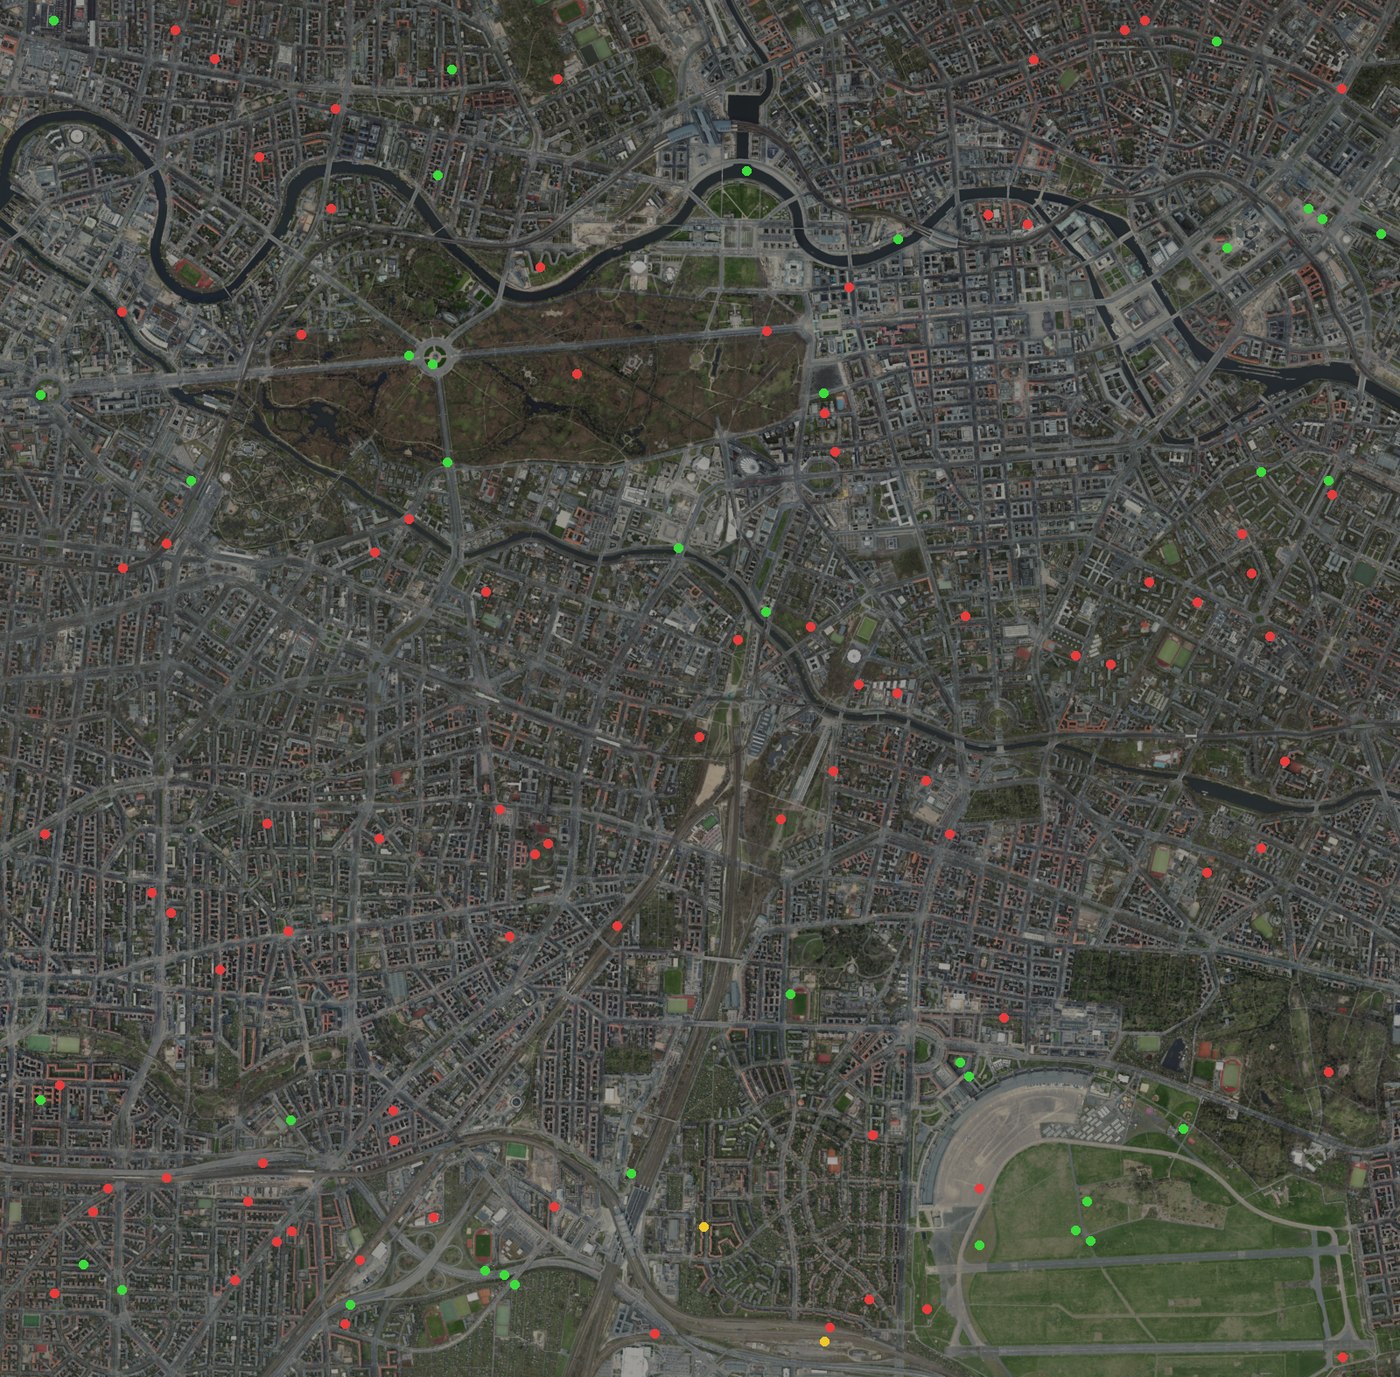
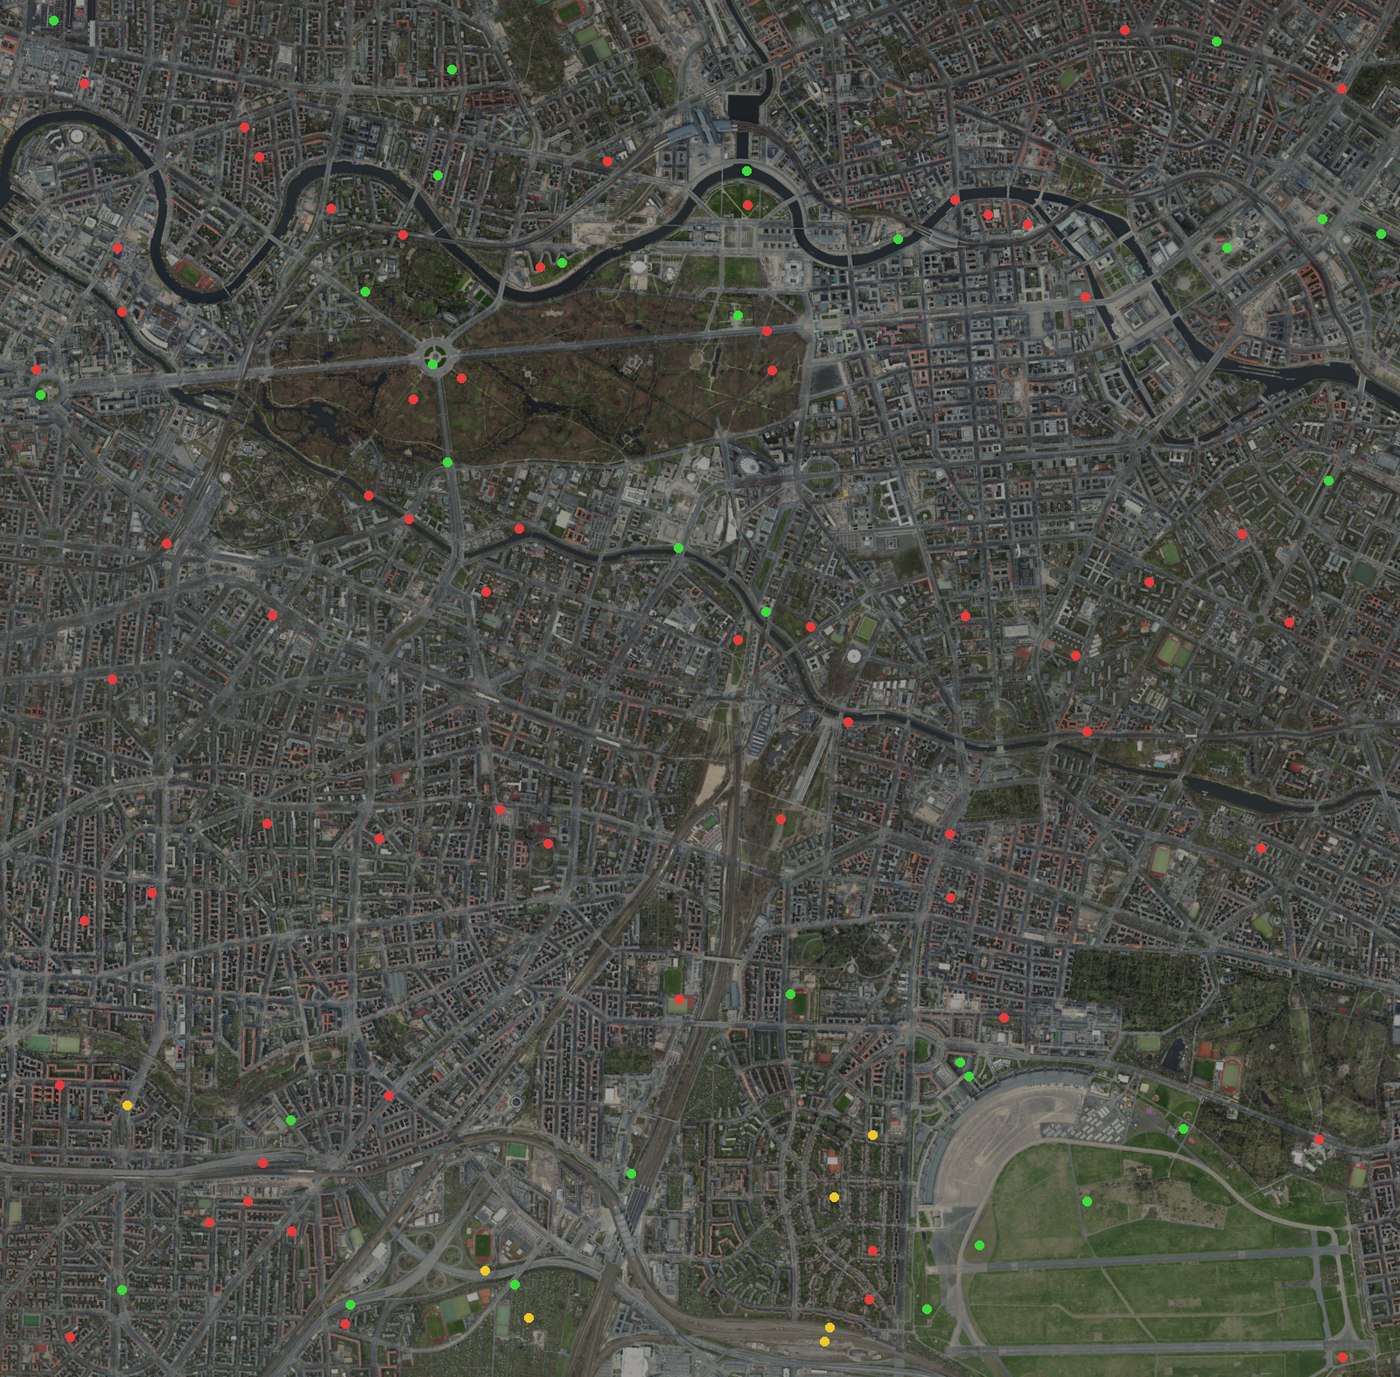
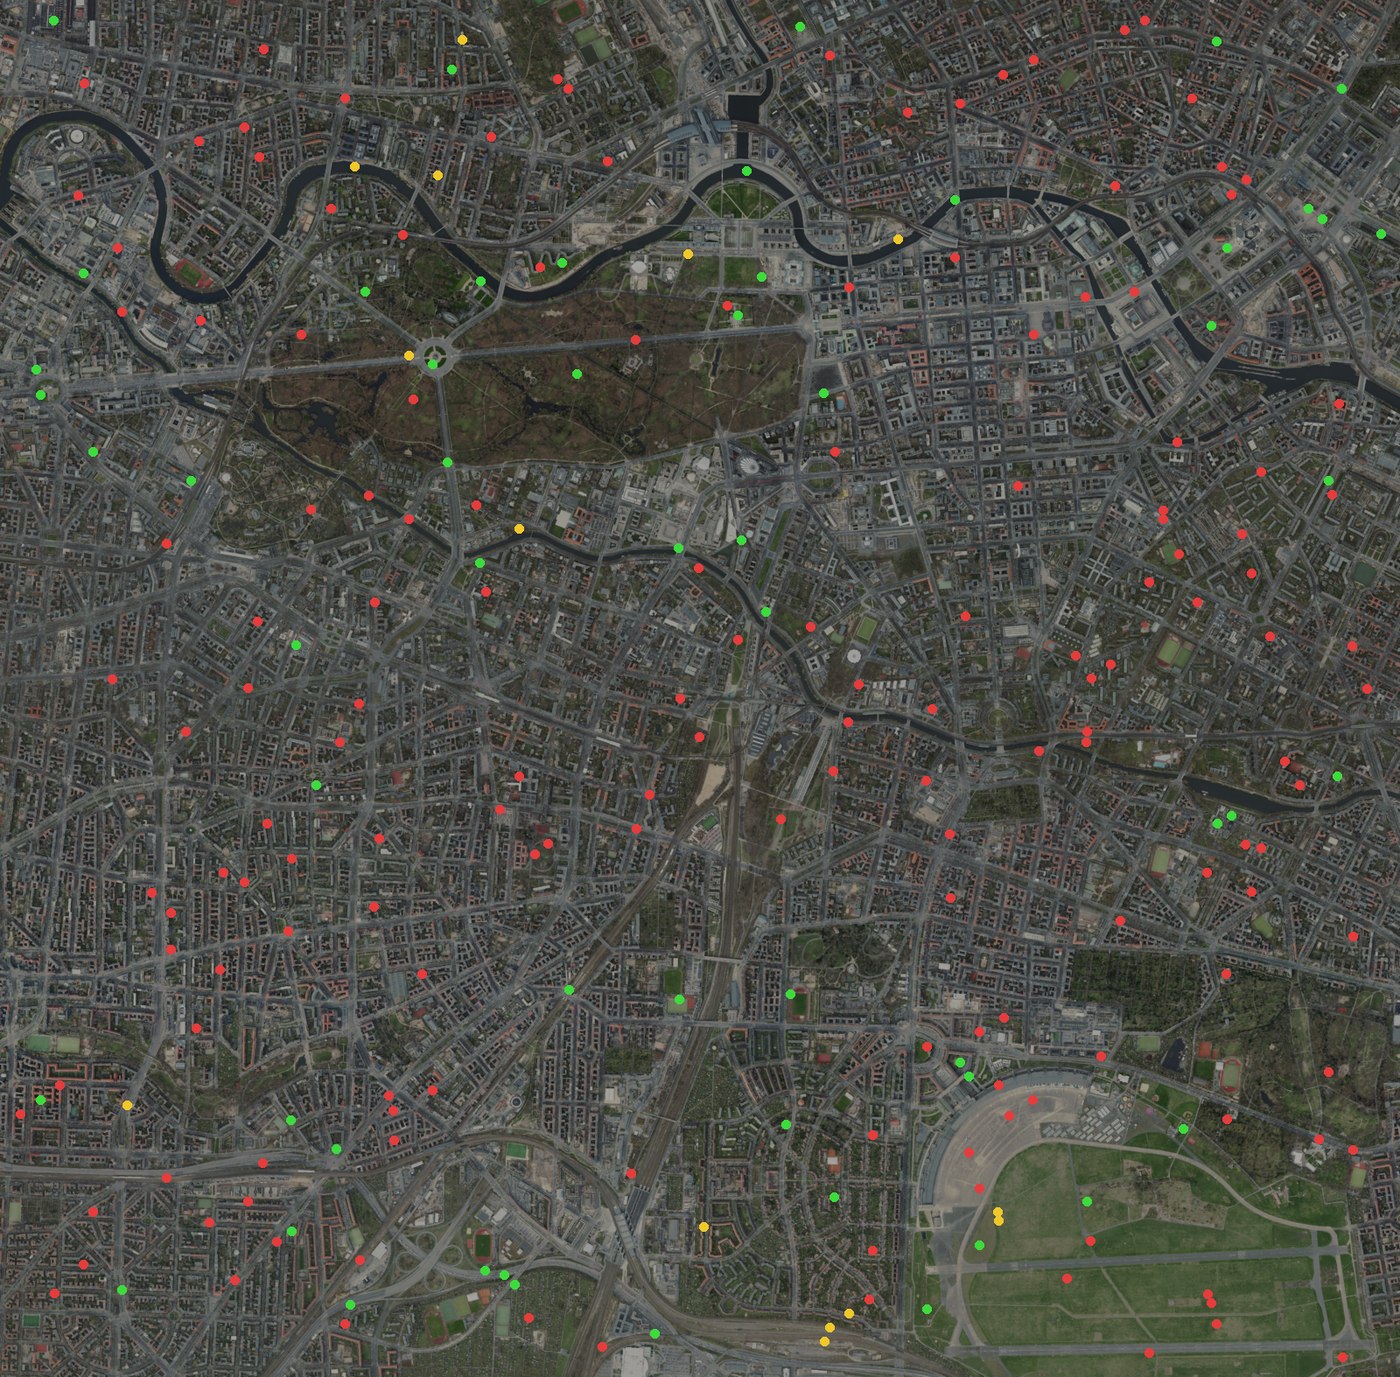
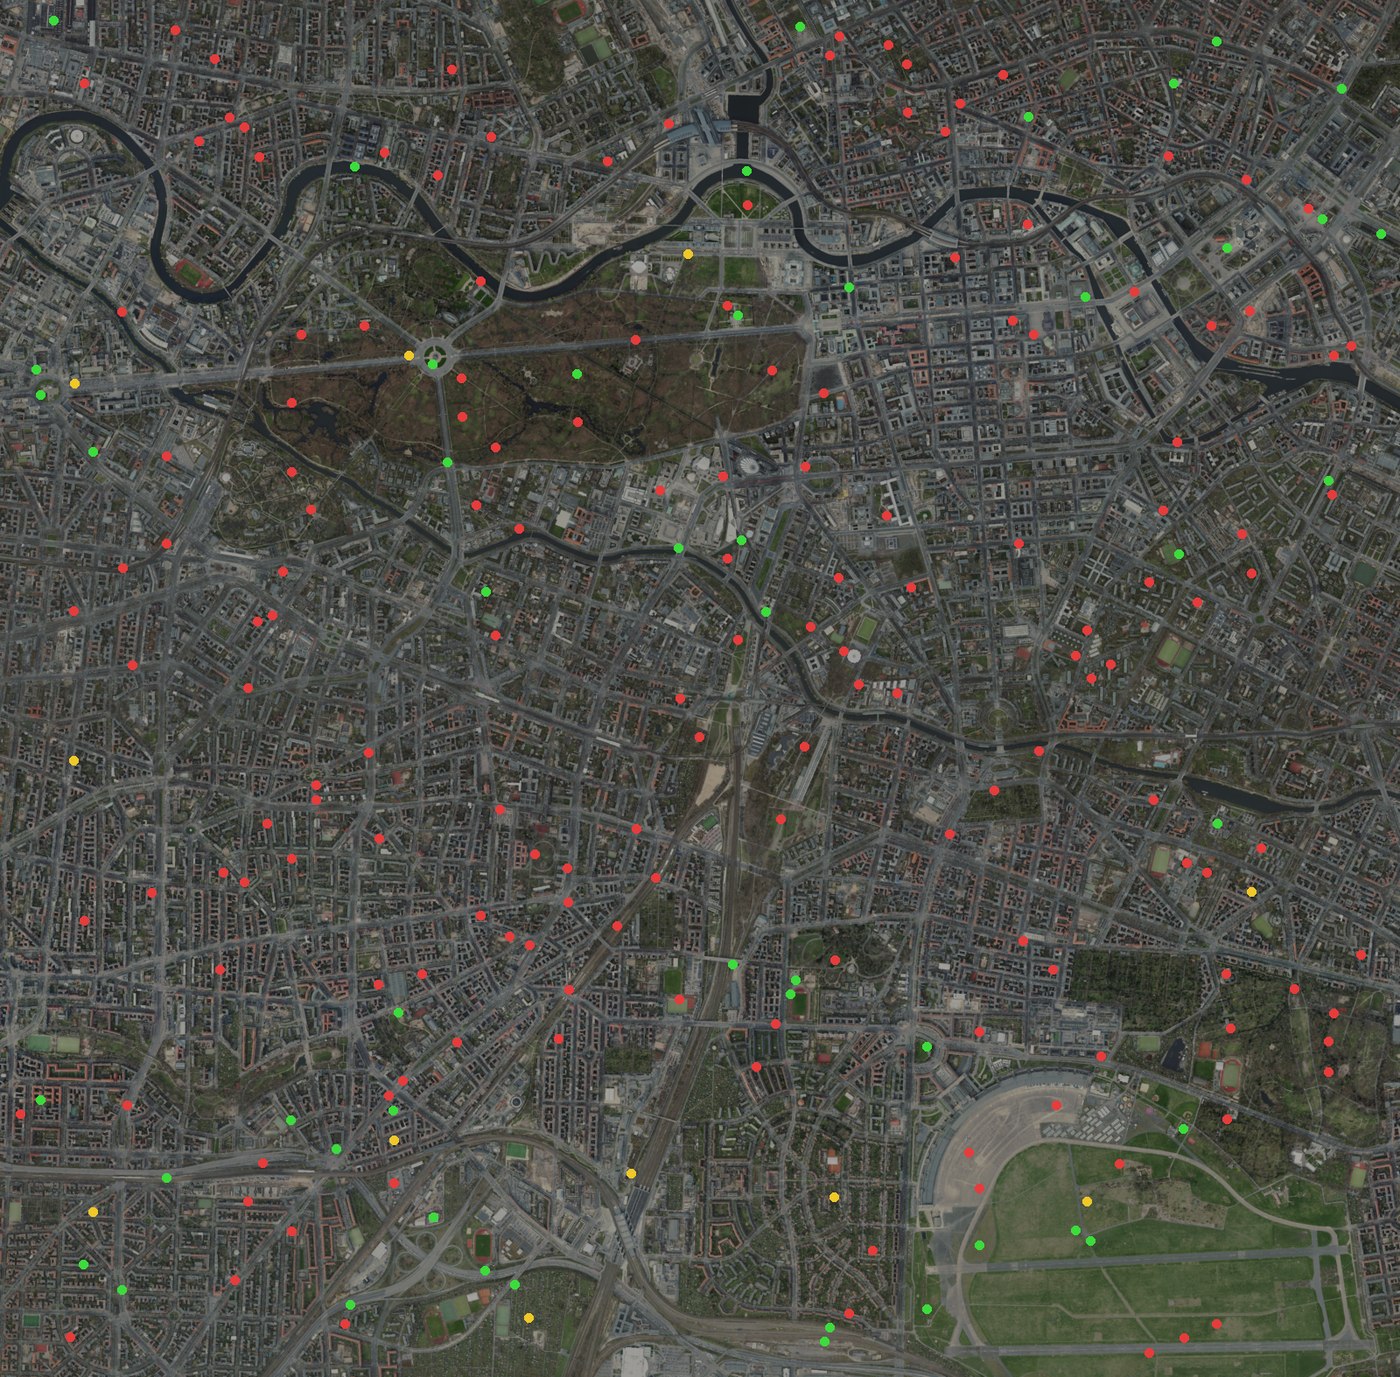
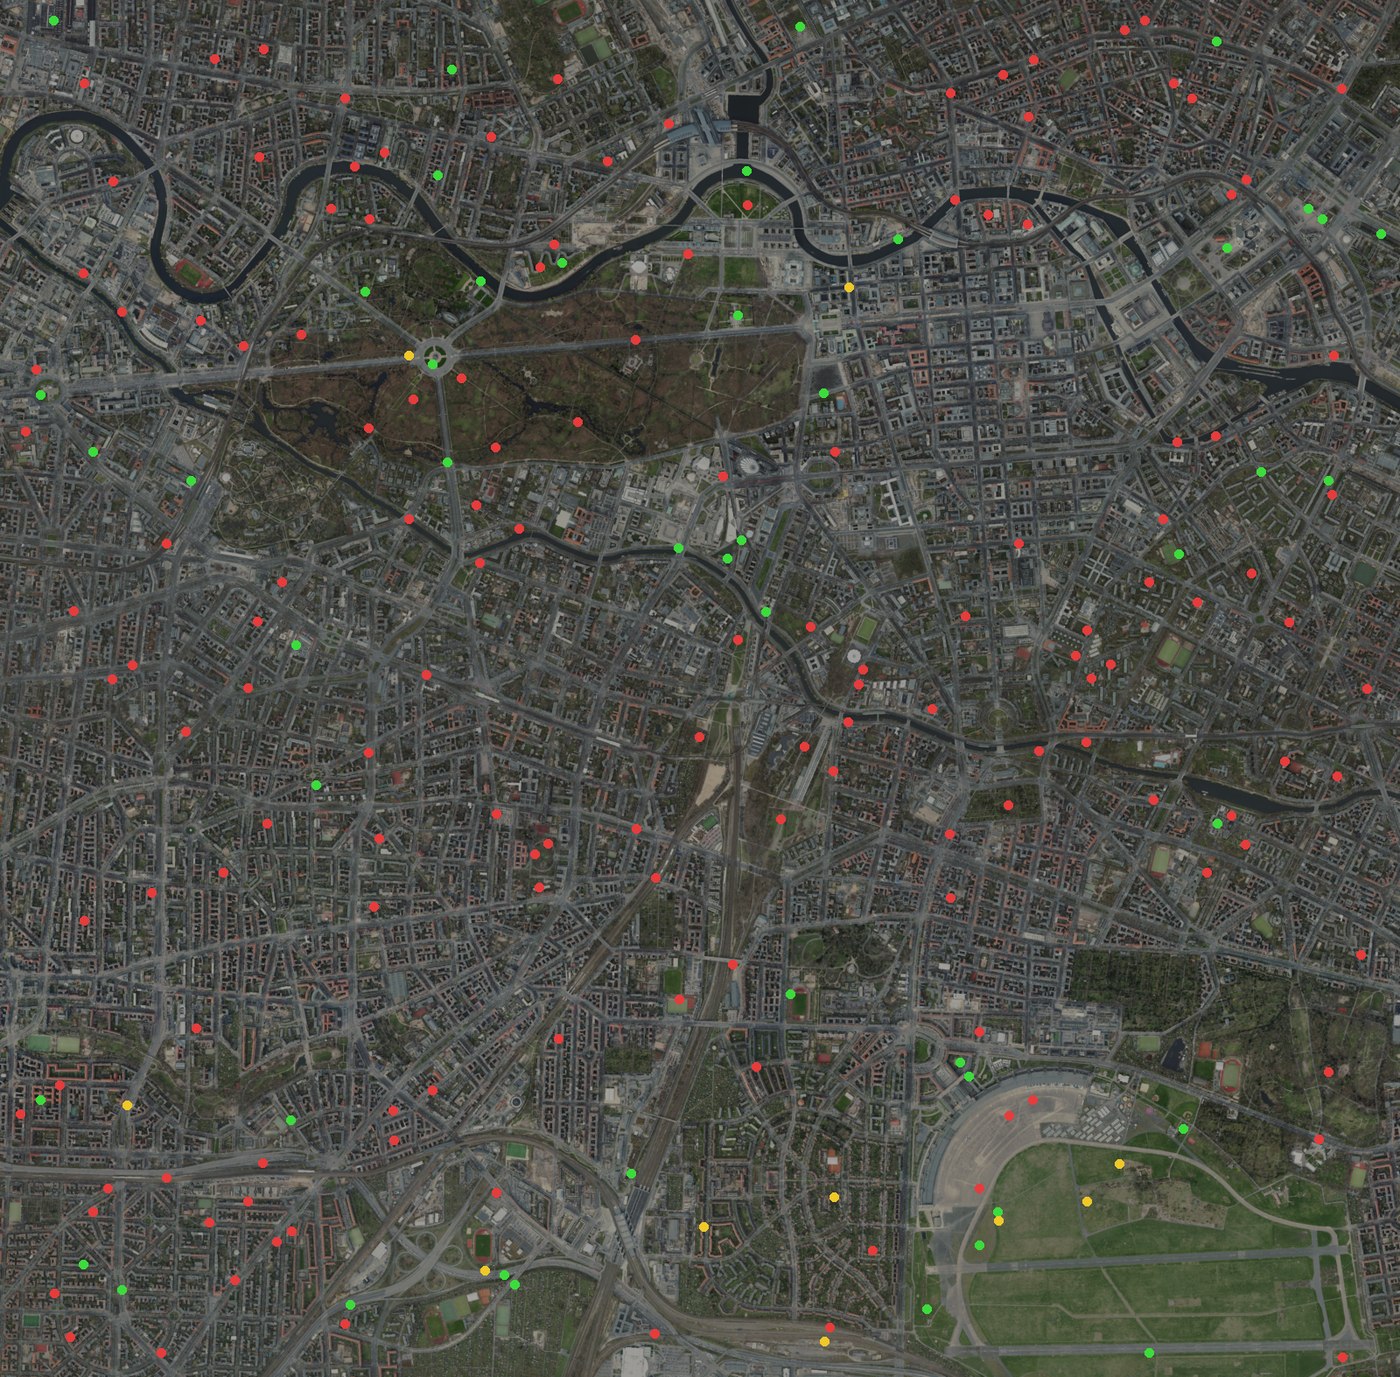
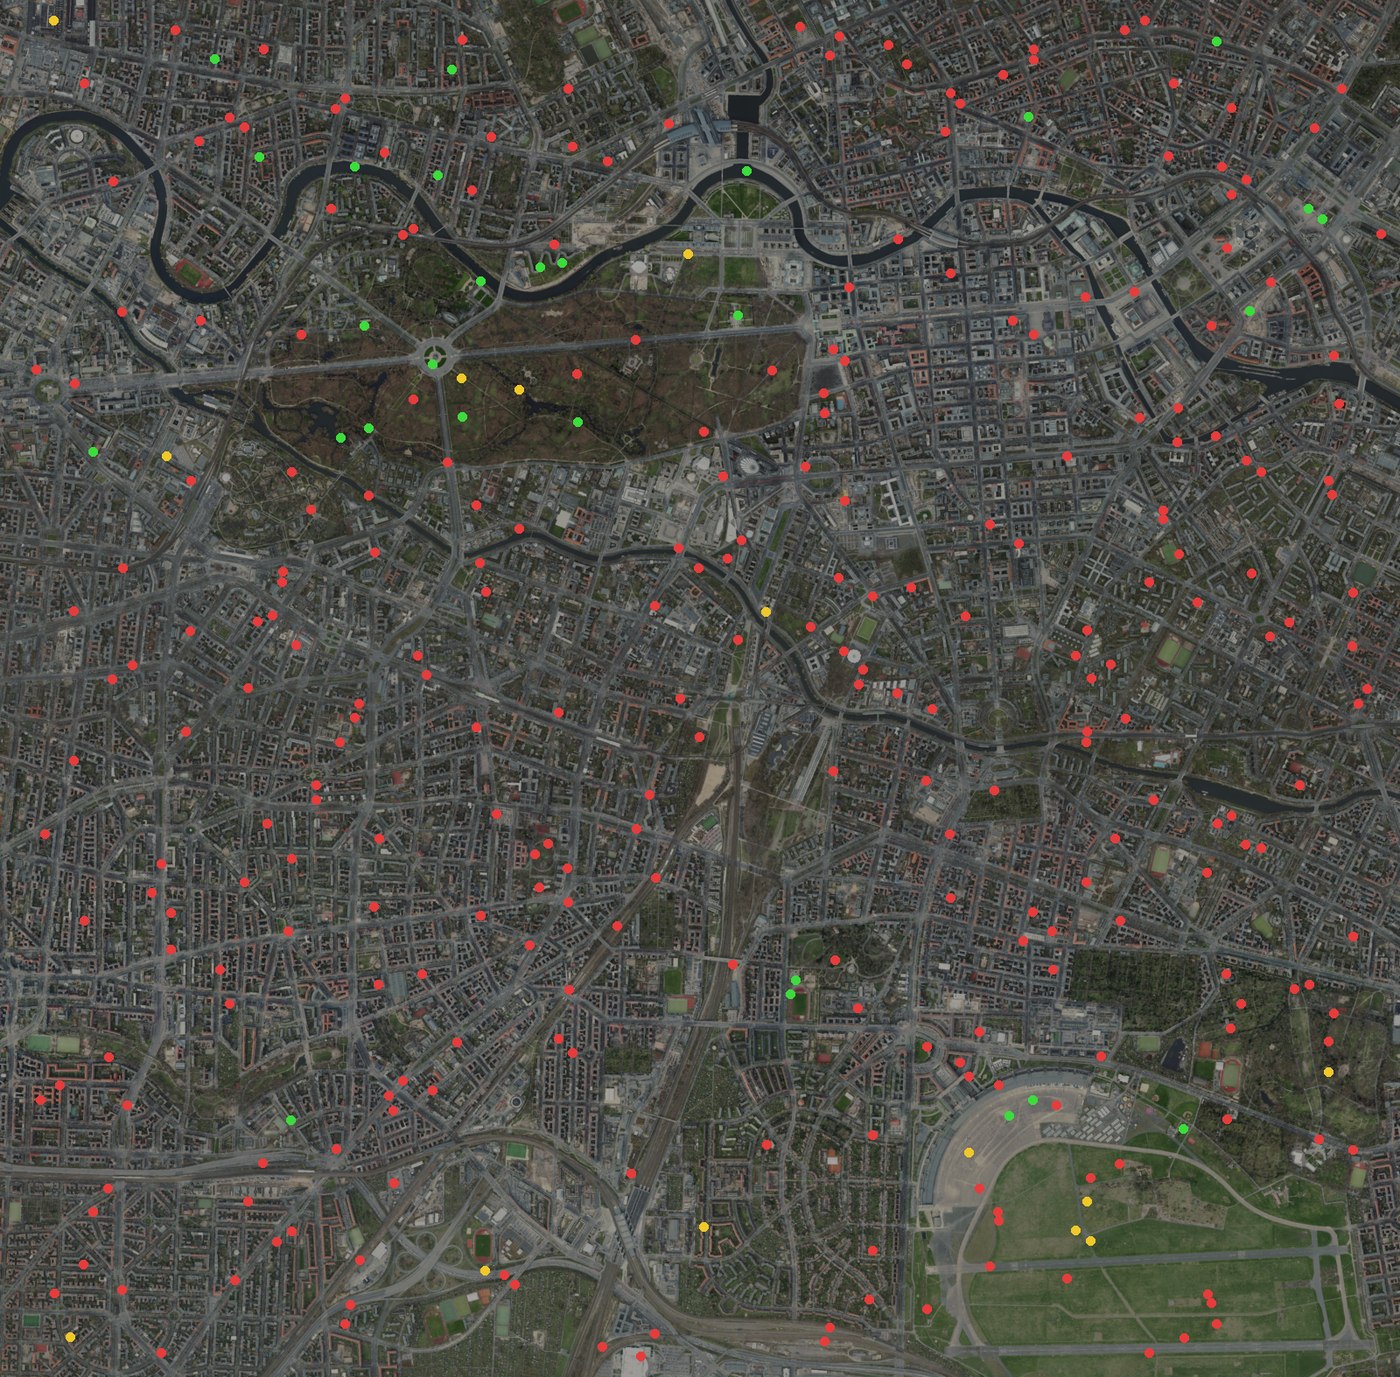
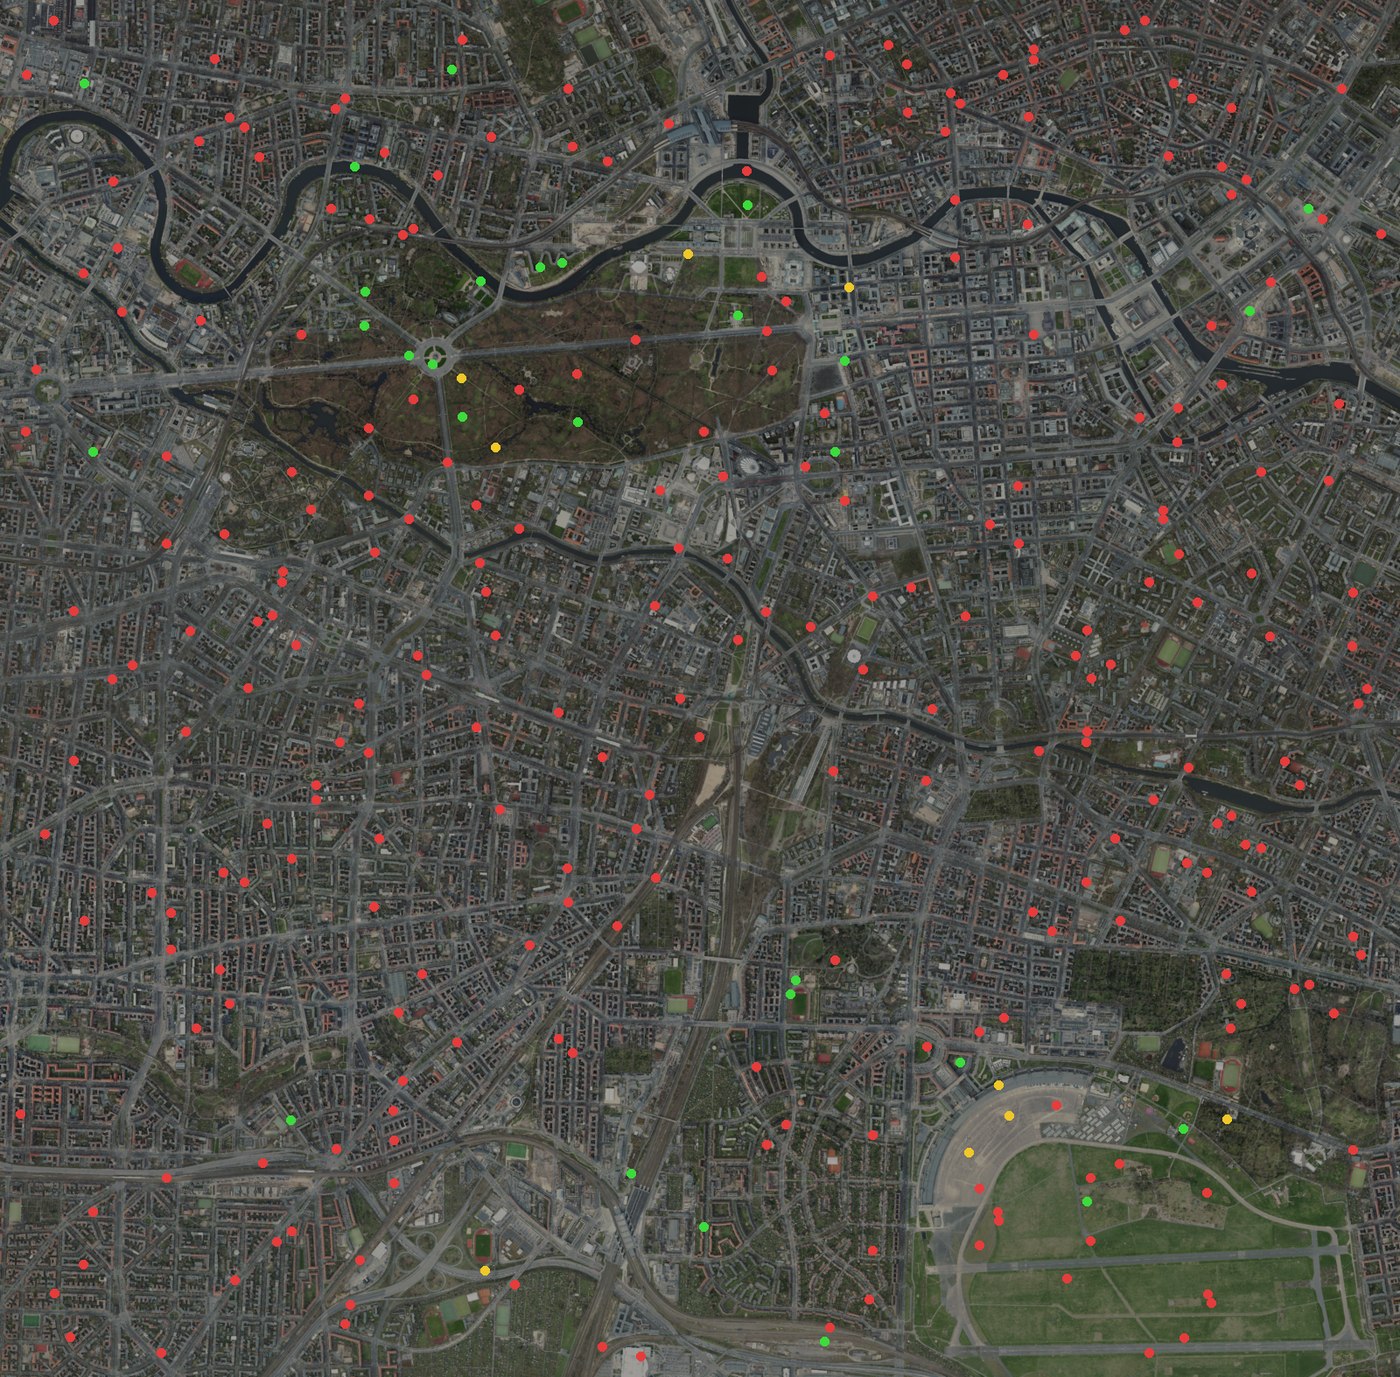
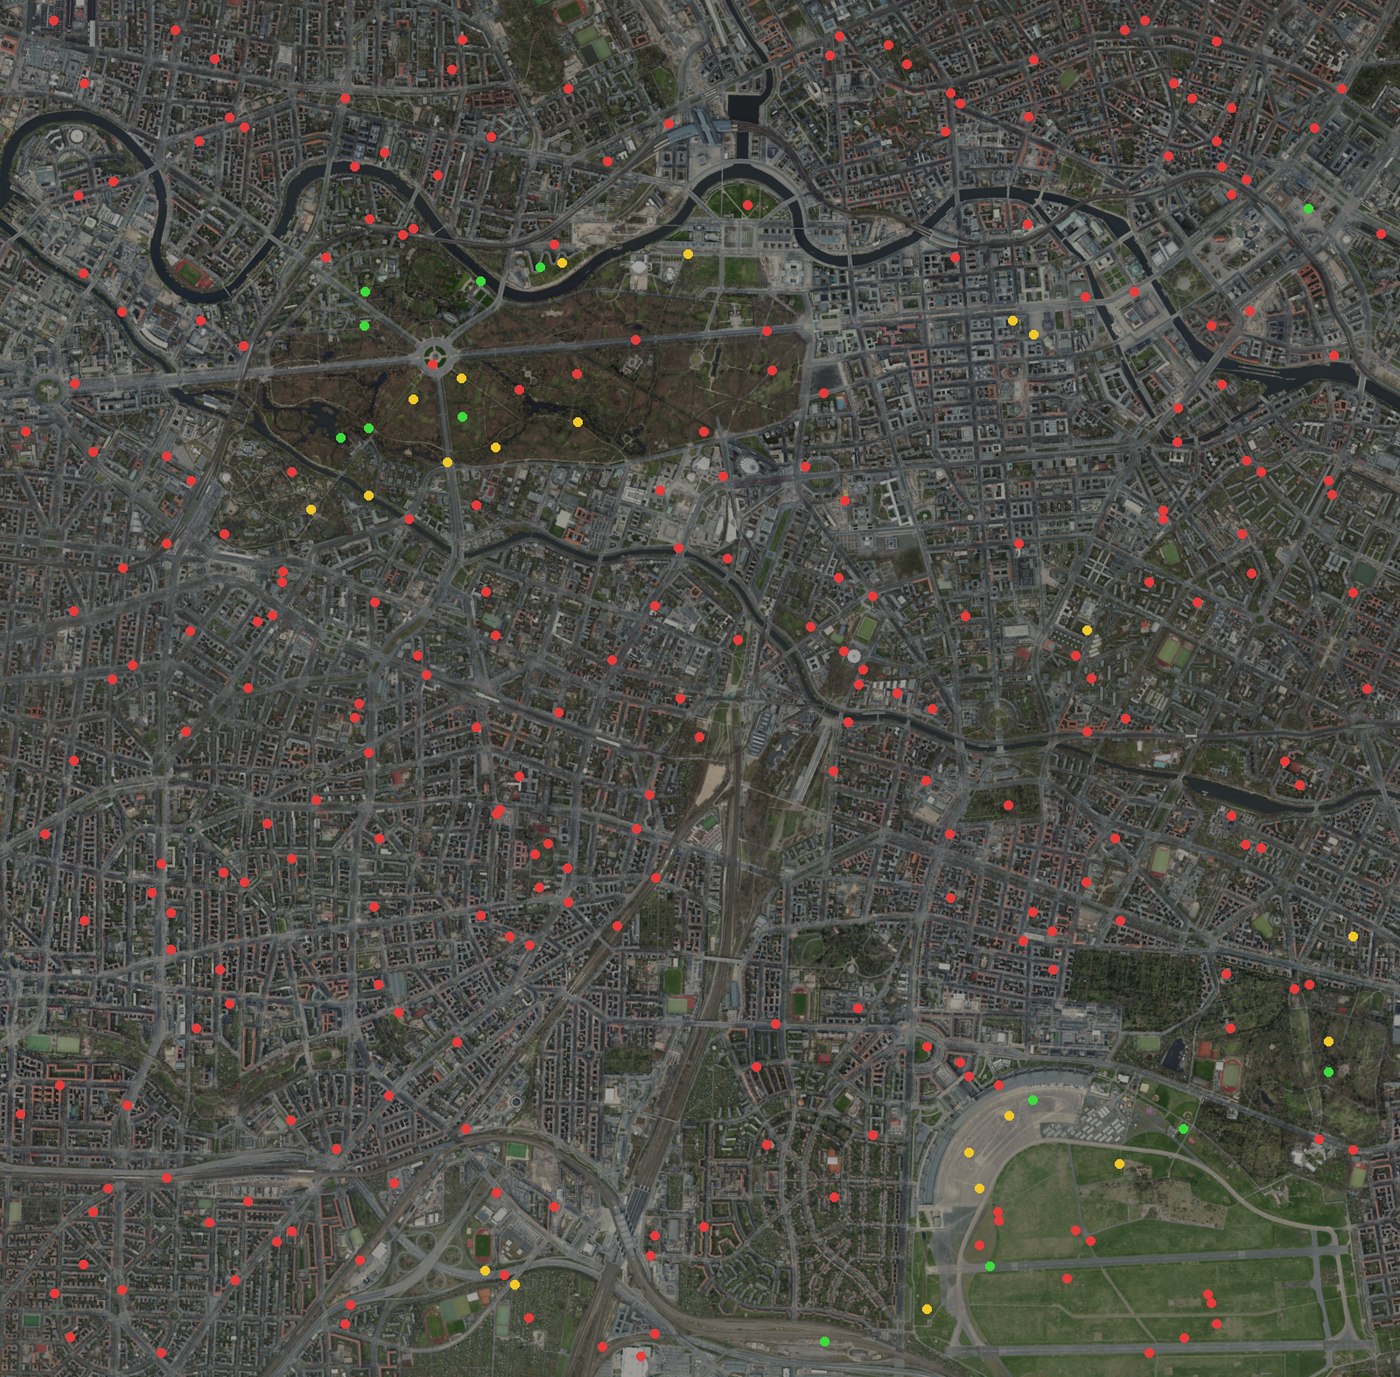
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 36–36 m across lighting
One real test, end to end
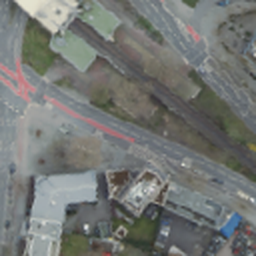
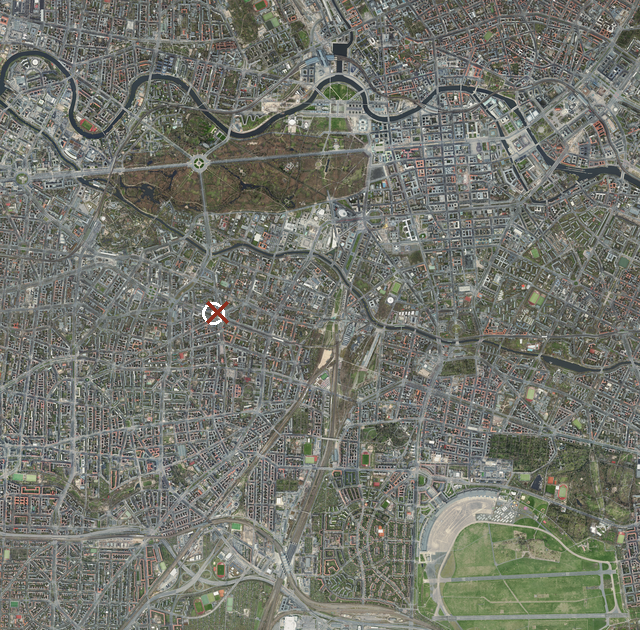
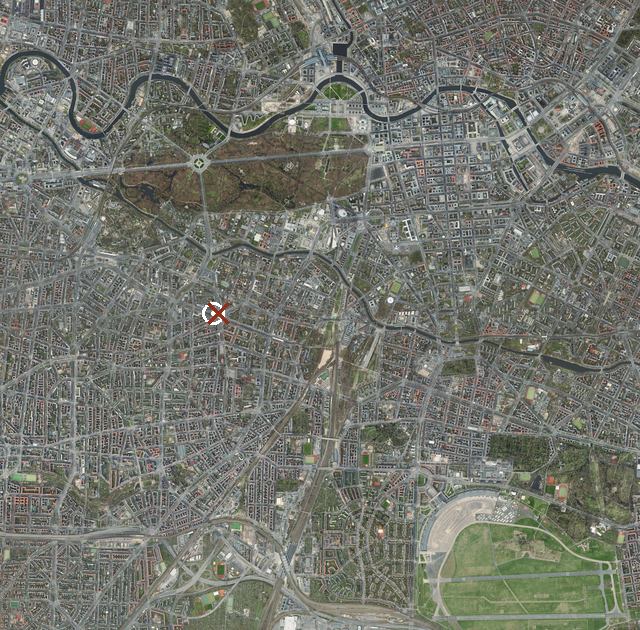
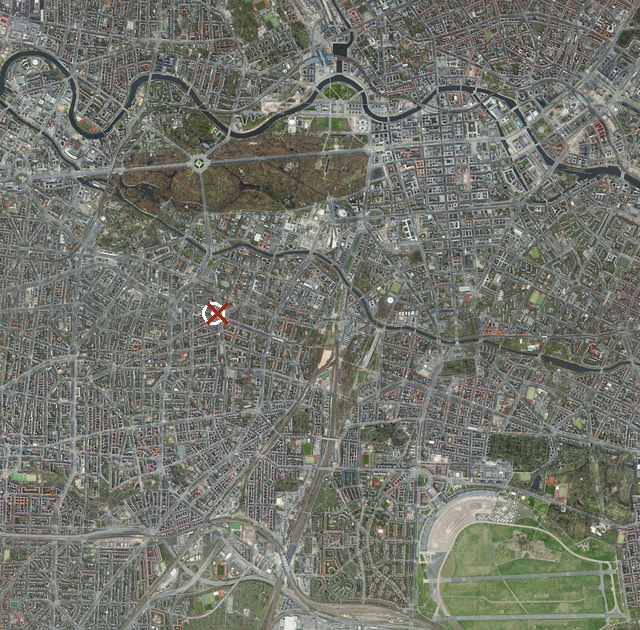
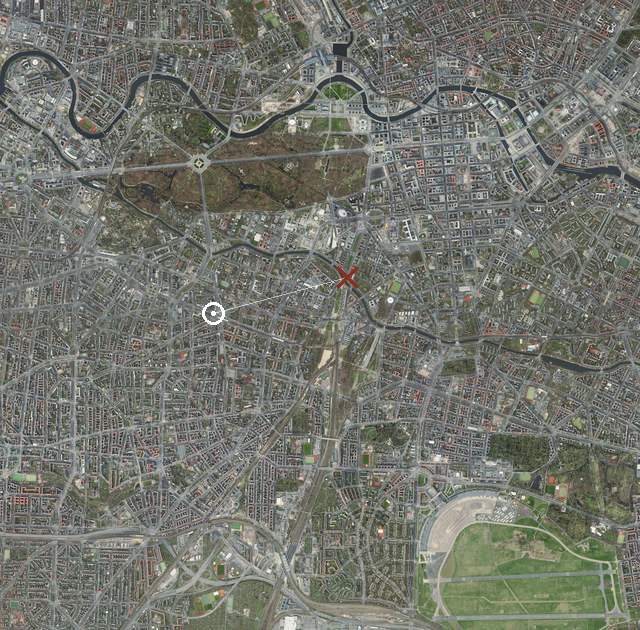
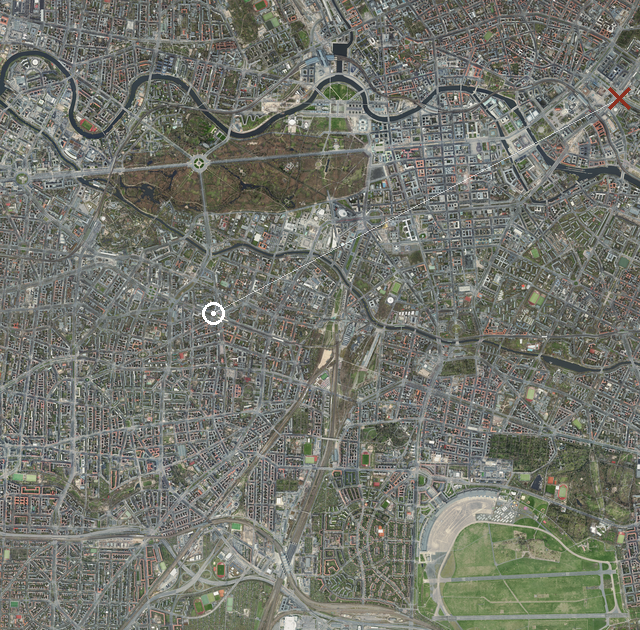
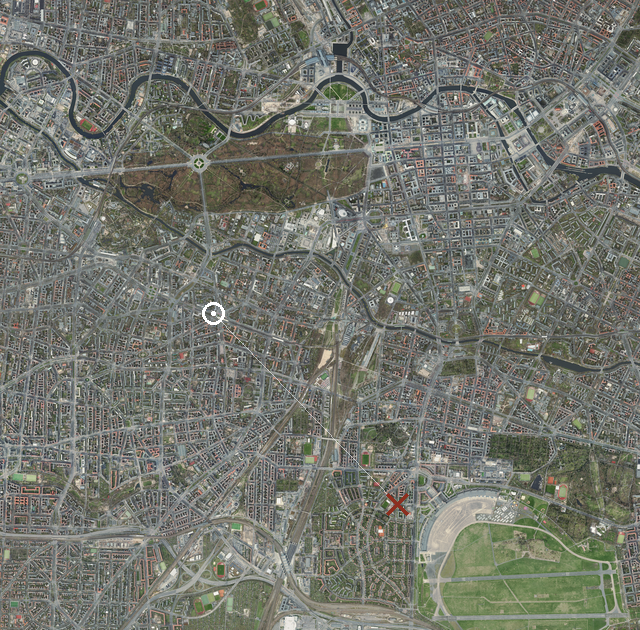
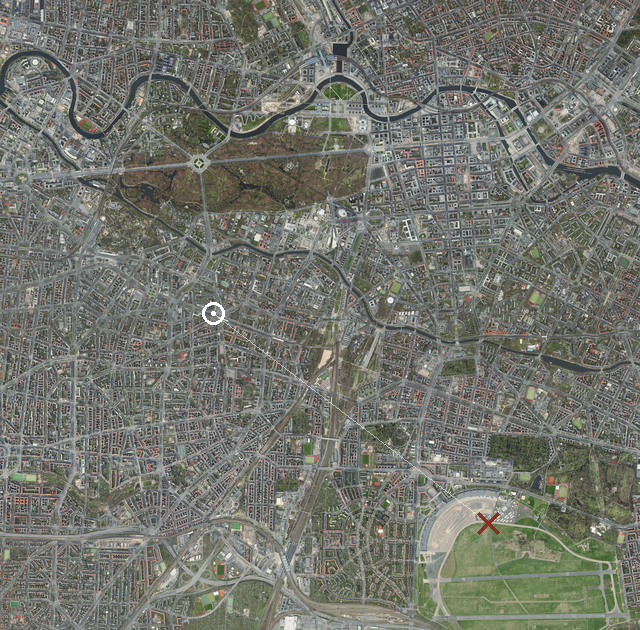
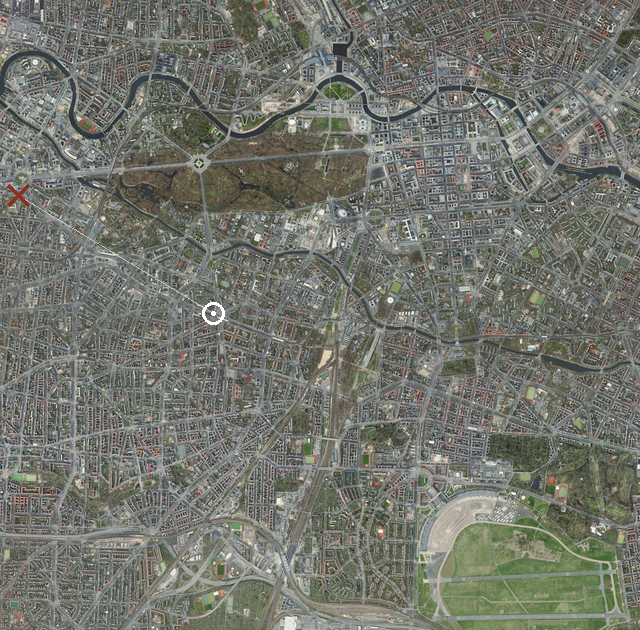
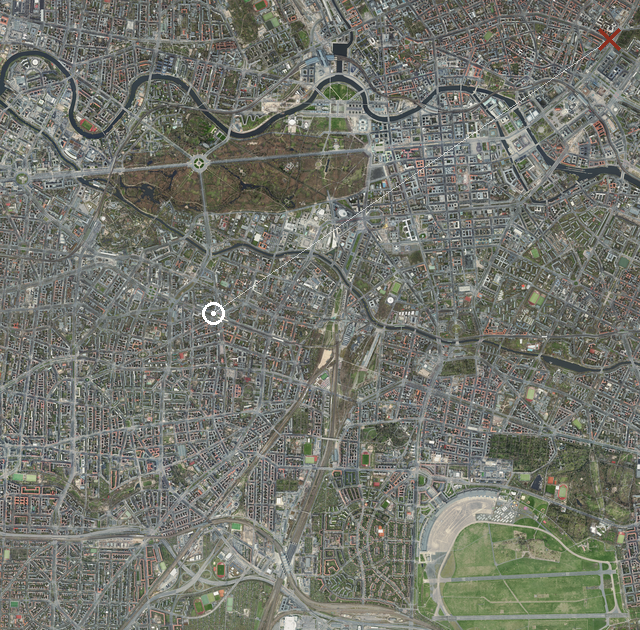
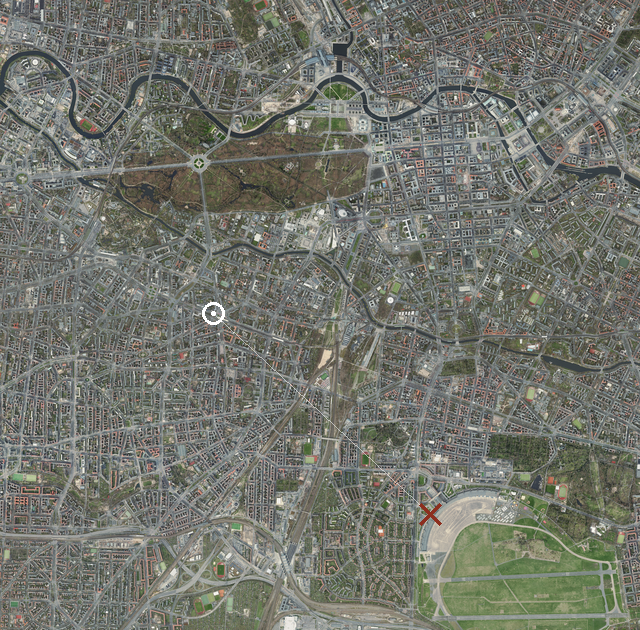
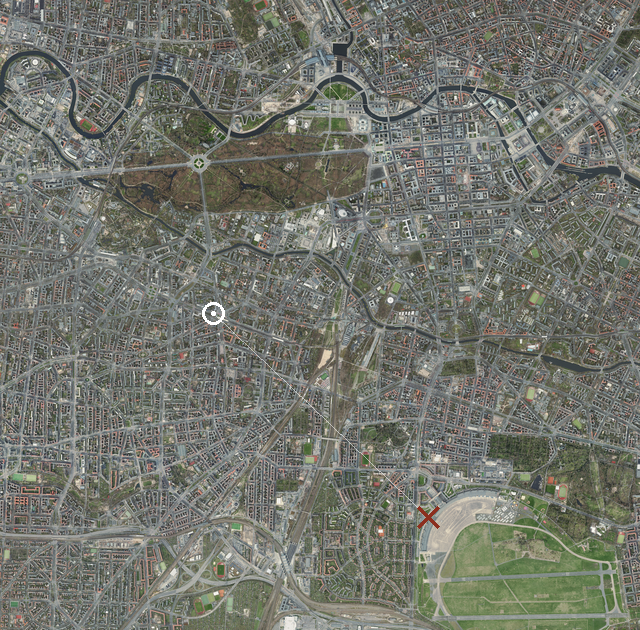
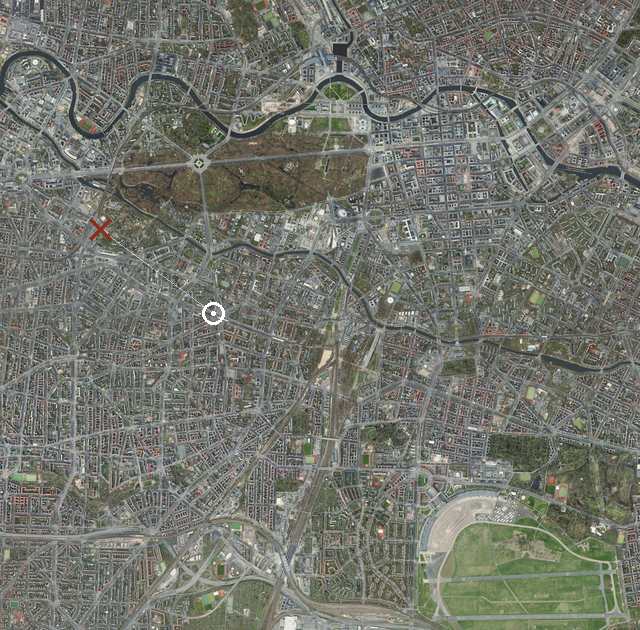
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
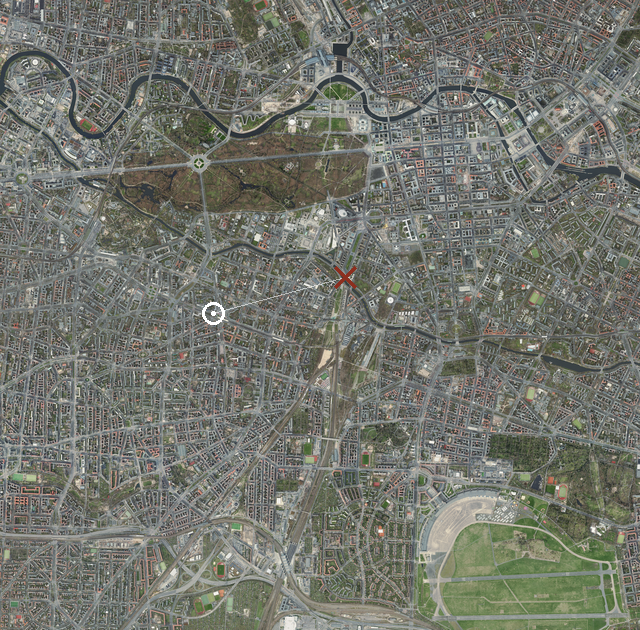
→
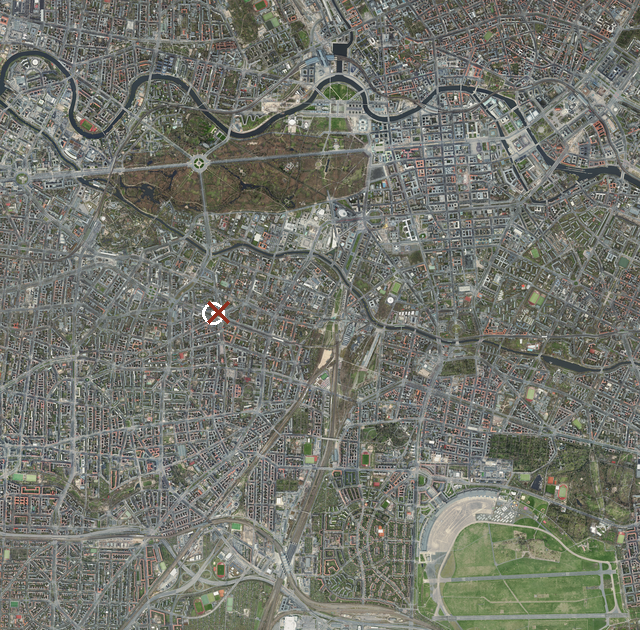
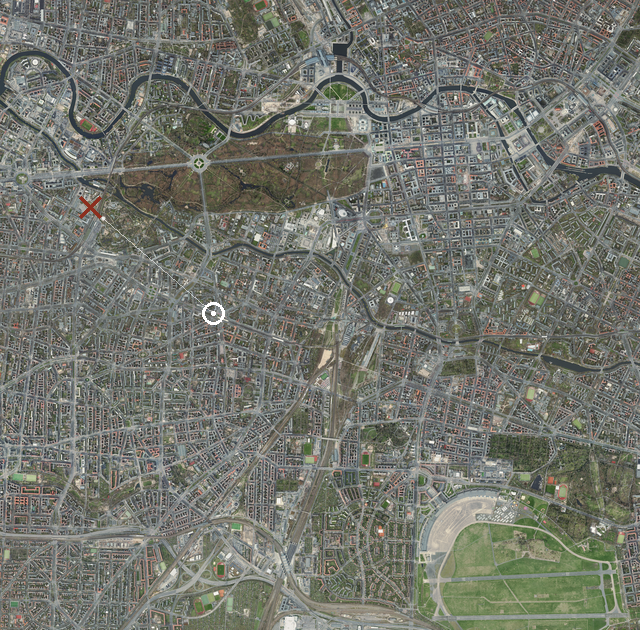
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
52.5 m
miss, this crop
0.99
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.10091% usablecov 0.92
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 82.5 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
10,843 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 3 m 18 s · implement (Opus) 55 s · train 1 area 181 m 21 s · score 2 m 38 s · samples 4 s · publish 1 s · whole experiment 172 m 27 s
ts 2026-11-03T11:41:49 · commit 2e90e35d55f9 ·
parent dab31721f36e · artifacts runs/20261103_084926_experiment28 ·
agent model — · took 172 m 23 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py414 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.LARGER IN-GRAPH ENLARGEMENT (capture-holdout era, experiment 28): the 128 pxframe is now resized in-graph (same bilinear op, fixed size) toINPUT_PX = 288 (2.25x) instead of 224, so the read levels become 112x18x18(after features[5]) and 320x9x9 (after features[7]), and the MixStyle pointssee 24x72x72, 40x36x36, 80x18x18. No new parameters: GAP keeps the 112-dplace feature, so prototypes and ONNX size are unchanged. Rationale:experiment 15's FixRes-style scale-matching step pushed further, so Berlin'ssmall aerial structures (cars, roof edges, kerbs, tree crowns) reach thepretrained filters at a scale closer to the one their ImageNet invariance waslearned on.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x9x9 at 288 px
INPUT_PX =288# frame is bilinearly resized to this before the pretrained trunk: 2.25x enlargement, beyond ImageNet's 224 (exp 28)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x9x9 at 288 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x18x18 at 288 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x72x72, 40x36x36, 80x18x18 at 288 px)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# INPUT_PX forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x18x18 after features[5], 320x9x9 after features[7], on the 288 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 18, 18]
h_deep = h # [B, 320, 9, 9]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py714 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.Experiment 28: 224 -> 288 (INPUT_PX = 288, 2.25x enlargement); theEfficientNet-B0 read levels become 112x18x18 and 320x9x9.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (18 at 288 px; was 14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (9 at 288 px; was 7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), "
f"two-level 112->56 ({MID_HW}x{MID_HW}) + 320->56 ({DEEP_HW}x{DEEP_HW}) -> 112 place feature, "
"MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Patchwork surveys: random rectangles of every training view are replaced by the SAME ground from another survey (or, sometimes, by unrelated ground), so a place must be recognised from whatever survives local change 1f8f06ad
worse than champion: 0.110 vs 0.078
augmentationpivot
0.110
133 m 19 s
$3.03
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
We teach the model Berlin from three aerial photographs taken in different years, then test it on a fourth it has never seen. Between photographs, little pieces of the city change: trees gain leaves, shadows move, a car park fills up, a building site grows. So while training, we cut random rectangles out of each picture and fill them with the same spot as it looked in another year's photograph, or occasionally with a piece of somewhere else entirely. The model can no longer rely on one or two memorable details; it has to recognise the place from everything around them, which is what it must do when the new photograph has changed a few details of its own.
What it cost
design agent
$1.17
figure agent
$1.09
implementation agent
$0.77
total
$3.03
by model — claude-opus-5-5 $3.03
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.110 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Champion exp 20 (0.0777) on held-out truedop_2024: usable 93.0%, false fix 0.75% (3 frames), abstain 6.25% (25 frames); the three training photographs score 100% usable / 0% false at the same held-out viewpoints, so the whole remaining score is the survey gap, and it is mostly abstention. Every survey-invariance mechanism this era has kept or tried acts on the WHOLE frame at once: photometric/blur nuisance (exp 4), MixStyle feature statistics (exp 14), weight averaging (exp 20), JS consistency of beliefs across surveys (exp 23, reverted), and the pretrained trunks (exps 12-19). None of them touches what actually differs LOCALLY between two surveys of the same ground: one block's trees are in leaf in one capture and bare in another, a courtyard is in shadow in one and lit in the next, a car park is full or empty, a construction site has moved on. A GAP-pooled place descriptor trained on three captures can lean on whichever few distinctive patches all three happen to agree on; when one of those patches differs in 2024, the descriptor moves off its prototype, the committee members' mass spreads, and the frame abstains (or, rarely, lands confidently elsewhere). The four captures are registered to one grid within 1 px, so the training set already contains the exact local substitutions a fourth survey makes: the same pixels of ground as photographed by another survey. Pasting rectangles of another training survey into a view, at the same ground position and heading, manufactures a new 'survey' per view whose season, shadow and contents vary REGION BY REGION, a combinatorial family the three whole photographs never show. A smaller share of rectangles filled with unrelated ground (another position in the batch) stands in for change that no training survey contains (new buildings, demolition). The training signal is then: the label stays put while any ~10-40% of the frame changes, so the descriptor must spread its evidence across the frame's stable structure instead of a few fingerprint patches. Builds on exp 6 (pixel blending of whole surveys, reverted on the from-scratch trunk of that time) by making the mixing spatial and local rather than a global alpha blend, and on exp 14's insight that cross-survey mixing helps, carried from feature statistics to content. Plateau note: exps 21-26 were four reverts of training-procedure and trunk-weight variations; this changes a stage never questioned in the era, the CONTENT of the training views (only their photometry, sharpness and heading have ever been randomised).
Method
model/train.py only. New function survey_patchwork(x, alt, foreign) applied per member, per batch, in run_epoch: with probability PATCH_P = 0.6 per view, draw PATCH_K = 3 axis-aligned rectangles (each independently active with prob 0.7; side lengths uniform in [12, 48] px, centres uniform over the 128 px frame, clipped to it). Each active rectangle takes its pixels from `alt` (the same position, same heading, a DIFFERENT training capture, cut by one extra gpu_crops call per batch) with prob 0.75, else from `foreign` (the batch's own clean crops under a random permutation, i.e. other ground). Applied to the clean crop before augment_views, so photometric nuisance acts on the composite as a whole. Labels, targets, loss, model, decode and export are unchanged. BN recalibration of the averaged model is left as it is (no patchwork), so the exported statistics match whole, unedited frames.
Expected outcome
mission_score 0.078 -> ~0.05-0.06 on truedop_2024, mainly through abstention: abstain 6.25% -> ~4%, usable 93.0% -> ~95%, false fix stays <= 1.0% (the committee's min-mass confidence is untouched; foreign-ground rectangles teach that unfamiliar content is not evidence for any place, which if anything sharpens honesty). Training-capture diagnostics stay ~0.000 (100% usable): the edit removes nothing from clean frames, which are still 40% of views. Training top1 on augmented views reads a few points lower by design. If 2024 usable does NOT move while training diagnostics hold, local content change is not what separates the surveys and the gap is global (geometry/scale/sensor), which narrows the search. Wall-clock: +1 gpu_crops per batch and cheap masking, ~+5% over the champion's ~110 min.
Result
mission score = 0.110178 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.110178 vs best 0.077671); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 37–37 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
54.2 m
miss, this crop
0.95
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.11091% usablecov 0.93
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.3 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,725 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 41 s · implement (Opus) 3 m 23 s · train 1 area 125 m 07 s · score 1 m 49 s · samples 4 s · publish 4 s · whole experiment 133 m 26 s
ts 2026-11-02T17:18:40 · commit 1f8f06ad16c9 ·
parent bdc95c4e92ff · artifacts runs/20261102_150521_experiment27 ·
agent model — · took 133 m 19 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py408 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.PATCHWORK SURVEYS (capture-holdout era, experiment 27): training-only changein model/train.py (survey_patchwork) — random rectangles of training views arereplaced by the same ground from another training capture or by unrelatedground. Nothing in this file's graph changed; the deployed model is unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py778 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.PATCHWORK SURVEYS (experiment 27): in run_epoch, each member's view of amini-batch is passed through survey_patchwork() before augment_views(). Withprobability PATCH_P per view, up to PATCH_K axis-aligned rectangles (eachactive with prob PATCH_RECT_P, sides U[PATCH_MIN_PX, PATCH_MAX_PX] px) arereplaced by the SAME ground at the same heading from a DIFFERENT trainingcapture (one extra gpu_crops call per batch; the captures are registered onone grid), or, with prob PATCH_FOREIGN_P, by another view of the batch(unrelated ground). Labels, targets, loss, model and export are unchanged;recalibrate_bn and survey_diag still see whole, unedited frames.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)# Survey patchwork (training only, experiment 27).
PATCH_P =0.6# per-view probability of any patchwork
PATCH_K =3# rectangles per view
PATCH_RECT_P =0.7# each rectangle independently active
PATCH_MIN_PX =12# side length range (width and height independent)
PATCH_MAX_PX =48
PATCH_FOREIGN_P =0.25# active rectangle filled from foreign ground instead of the alternate surveydef survey_patchwork(x: torch.Tensor, alt: torch.Tensor,
foreign: torch.Tensor)-> torch.Tensor:"""Replace random rectangles of each view by the same ground from another training capture (`alt`, pixel-registered with x) or, with prob PATCH_FOREIGN_P, by unrelated ground (`foreign`). All [B,3,H,W] in [0,1]. Fully vectorised on the device; hard edges; foreign wins on overlap."""
B,_, H, W = x.shape
dev = x.device
K = PATCH_K
view_on = torch.rand(B,1, device=dev)< PATCH_P
active = view_on &(torch.rand(B, K, device=dev)< PATCH_RECT_P)# [B,K]
w = torch.randint(PATCH_MIN_PX, PATCH_MAX_PX +1,(B, K), device=dev)
h = torch.randint(PATCH_MIN_PX, PATCH_MAX_PX +1,(B, K), device=dev)
cxr = torch.randint(0, W,(B, K), device=dev)
cyr = torch.randint(0, H,(B, K), device=dev)
x0 =(cxr - w //2).clamp(0, W); x1 =(cxr + w //2).clamp(0, W)
y0 =(cyr - h //2).clamp(0, H); y1 =(cyr + h //2).clamp(0, H)
ax = torch.arange(W, device=dev).view(1,1,1, W)
ay = torch.arange(H, device=dev).view(1,1, H,1)
inside =((ax >= x0[...,None,None])&(ax < x1[...,None,None])&(ay >= y0[...,None,None])&(ay < y1[...,None,None]))# [B,K,H,W]
is_for = torch.rand(B, K, device=dev)< PATCH_FOREIGN_P
sel_alt =(active &~is_for)[...,None,None]
sel_for =(active & is_for)[...,None,None]
m_alt =(inside & sel_alt).any(dim=1, keepdim=True).to(x.dtype)# [B,1,H,W]
m_for =(inside & sel_for).any(dim=1, keepdim=True).to(x.dtype)
out = x *(1- m_alt)+ alt * m_alt
return out *(1- m_for)+ foreign * m_for
def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])# Patchwork sources: same ground + heading from a DIFFERENT# training capture (pixel-registered), and other ground.if n_caps >=2:
alt_cap =(cap_b + torch.randint(1, n_caps, cap_b.shape,
device=cap_b.device))% n_caps
else:
alt_cap = cap_b
xb_alt = gpu_crops(scene, alt_cap, cx[idx], cy[idx], ang[idx])
xb_for = xb0[torch.randperm(B, device=xb0.device)]
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(survey_patchwork(xb0, xb_alt, xb_for))with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
print(f"[{area}] survey patchwork (train only): p={PATCH_P} k={PATCH_K} "
f"rect_p={PATCH_RECT_P} side_px=[{PATCH_MIN_PX},{PATCH_MAX_PX}] "
f"foreign_p={PATCH_FOREIGN_P} alt=same position+heading, different "
f"training capture", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported), ""survey patchwork (random rectangles from another training ""capture at the same ground, or from foreign ground; train only)"),"patchwork":{"p": PATCH_P,"k": PATCH_K,"rect_p": PATCH_RECT_P,"side_px":[PATCH_MIN_PX, PATCH_MAX_PX],"foreign_p": PATCH_FOREIGN_P,"alt_source":"same position+heading, different training capture"},"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Probe first, then fine-tune, actually trained: one extra opening epoch trains only the head on the FROZEN ImageNet trunk before the usual fine-tune (LP-FT; re-run of experiment 21, which never reached a GPU) a5c71e3e
worse than champion: 0.090 vs 0.078
trainingpivot
0.090
126 m 27 s
$3.26
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model's 'eyes' were borrowed from a network that had already looked at a million everyday photos, and that borrowed vision is what lets it recognise Berlin in a photograph it has never seen. Until now we started teaching the eyes and the brand-new 'map-reading' part at the same moment - so in the first hours the confused new part was yanking the borrowed eyes around. Now the map-reading part first practises for one round with the eyes held still, and only then are both tuned together, so the eyes keep more of what made them useful. (This idea was planned once before, but the rented computer could not be reached, so it was never actually tried.)
What it cost
design agent
$1.64
implementation agent
$0.83
figure agent
$0.79
total
$3.26
by model — claude-opus-5-5 $3.26
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.090 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Experiment 21's hypothesis was never tested. Its run died before training on an infrastructure error: train_berlin.log ends in botocore EndpointConnectionError ('Could not connect to the endpoint URL: https://ec2.eu-central-1.amazonaws.com/'), so the scorer recorded 1e9 and the harness marked it REVERTED. That verdict says nothing about LP-FT, exactly as experiment 17's crash said nothing about ring pooling (re-run as 18) and experiment 24's said nothing about Noisy Student weights (re-run as 25); issue #13 has since stopped cloud failures passing as refuted ideas. The champion is still experiment 20 (0.0777: truedop_2024 usable 93.0%, false 0.75% = 3 frames, abstain 6.25% = 25 frames; the three training photographs 100% usable / 0% false at the same held-out viewpoints), and model/ is identical to the code experiment 21 branched from, so its reasoning stands unchanged. The reasoning: every large step on the never-seen photograph this era came from what the pretrained trunk brought with it (exp 12 MobileNetV3-Small 10.75% -> 49.5% usable; exp 16 MobileNetV2 86.75%; exp 19 EfficientNet-B0 92.5%), and exp 20 showed that HOW the trunk is trained still moves the held-out number (a better point on the same trajectory: +0.5 usable, false 1.0% -> 0.75%). Today the trunk is fine-tuned from step 1 jointly with a randomly initialised head (prototypes std 0.01 over 2,970 tiles, random lifts, random embed BatchNorm), so the earliest, largest gradients into the pretrained blocks come from a head that knows no tile yet, and the trunk BatchNorm statistics start drifting at the same moment. Kumar et al. (ICLR 2022, 'Fine-Tuning can Distort Pretrained Features and Underperform Out-of-Distribution') show that full fine-tuning from a random head distorts pretrained features along in-domain directions and costs out-of-distribution accuracy while in-domain accuracy is unchanged; training the head on the frozen trunk first (LP-FT) removes most of that loss. That is our split precisely: in-domain saturated at 100%, held-out survey at 93%. It also answers the plateau the right way: the last three trained experiments (22 continuous vantages, 23 cross-survey consistency loss, 25 Noisy Student init) changed sampling, loss and init and none moved the held-out number beyond noise; the one stage never questioned since exp 12 is the trunk's fine-tuning procedure ('0.1x LR from step 1'). Exp 25 is mild evidence against a pure 'better init' story, which makes the complementary question - does the fine-tune PRESERVE whatever the init brings - the informative next test. Builds on experiment 20 (champion) and lifts experiment 21's never-run implementation verbatim.
Method
model/train.py only: prepend HEAD_WARMUP_EPOCHS = 1 extra epoch before the existing fine-tuning run. During it every member's pretrained trunk (m.trunk: EfficientNet-B0 features[0..7]) is frozen - requires_grad False on all trunk parameters and m.trunk kept in eval mode, so its BatchNorm running stats stay at their ImageNet values and stochastic depth is off - and only the head parameters (both 1x1 lifts, embed BatchNorm1d, prototypes, offset head) train, at the head LR 1e-3, with the same losses, augmentation, MixStyle and paired-survey batches as today. After that epoch the trunk is unfrozen and the existing EPOCHS-epoch run follows exactly as now (trunk at 0.1x, cosine LR multiplier 1.0 -> 0.1 over those EPOCHS epochs, weight averaging from fine-tune epoch EPOCHS//2+1, BN recalibration, export). Total epochs = EPOCHS + 1; the warm-up epoch is cheaper than a normal one (no trunk backward). The implementation is lifted verbatim from experiment 21's never-executed model_src/train.py.
Expected outcome
On truedop_2024, 400 frames (one frame = 0.25 points): mission 0.078 -> ~0.055-0.070; usable_fix_rate 93.0% -> ~94-95% (abstentions converting to usable fixes as each member's tile belief on the foreign photograph rides less-distorted ImageNet features and the two members agree more often); false_fix_rate at or below 0.75%; abstain 6.25% -> ~4.5-5.5%. train_capture_diagnostics stay ~100% usable / 0% false; median error ~36 m unchanged; model size (31.7 MB) and host latency (~49 ms) identical - same graph. Signals to read in train_berlin.log: after the warm-up epoch, top1 on training views should already be substantial (near zero would mean the probe was too short and the experiment tests less than intended); end-of-run xs_cos_same / xsurvey_agree at or above experiment 20's. Refutation: usable flat or down (within +-2 frames counts as flat) with training diagnostics unchanged says feature distortion by the random head is not what limits the survey gap here (plausibly the 0.1x trunk LR and weight averaging already protect the features), and that the remaining ~7% need new information - a different view of the frame, or more photographs - rather than a gentler fine-tune.
Result
mission score = 0.090179 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.090179 vs best 0.077671); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 37–37 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
52.6 m
miss, this crop
0.97
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.09092% usablecov 0.94
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,963,224
8
6,709 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 51 s · implement (Opus) 1 m 22 s · train 1 area 120 m 05 s · score 1 m 48 s · samples 4 s · publish 4 s · whole experiment 126 m 34 s
ts 2026-11-02T15:04:57 · commit a5c71e3e701a ·
parent bd6f1b274a15 · artifacts runs/20261102_125830_experiment26 ·
agent model — · took 126 m 27 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py774 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.HEAD WARM-UP (experiment 26, LP-FT; designed as experiment 21, which neverreached a GPU): HEAD_WARMUP_EPOCHS extra openingepoch(s) run BEFORE the existing fine-tuning run. During them every member'spretrained trunk is frozen — requires_grad False on all trunk parameters andm.trunk held in eval mode (BatchNorm running stats stay at their ImageNetvalues, stochastic depth off) — and only the head (both 1x1 lifts, embedBatchNorm1d, prototypes, offset head) trains at the head LR 1e-3, with thesame losses, augmentation, MixStyle (a separate Member module, still in trainmode) and paired-survey batches. The LR scheduler is not stepped during thewarm-up, so the fine-tune schedule starts fresh at multiplier 1.0. Then thetrunk is unfrozen and the previous EPOCHS-epoch run follows unchanged (trunkat 0.1x, cosine 1.0 -> 0.1, weight averaging from fine-tune epochEPOCHS//2 + 1, BN recalibration, export). The optimiser is not rebuilt: thehead's Adam state carries over; the trunk's starts fresh at unfreeze. So therandom head's first gradients never reach the borrowed features (Kumar etal., ICLR 2022). Total epochs = EPOCHS + HEAD_WARMUP_EPOCHS.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
HEAD_WARMUP_EPOCHS =1# extra opening epoch(s): head trains on the FROZEN pretrained trunk (LP-FT)
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None,
freeze_trunk: bool =False):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only. `freeze_trunk` (head warm-up): every member's trunk is held in eval mode (BN running stats frozen, stochastic depth off); the caller has set requires_grad False on the trunk parameters."""
model.train()if freeze_trunk:for m in model.members:
m.trunk.eval()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}# HEAD WARM-UP (LP-FT): head only, frozen trunk (weights + BN stats), no# sched.step() so the fine-tune schedule below starts at multiplier 1.0.
warm ={"top1":None,"member_top1":None,"agree":None,"clean_top1":None}for p in trunk_params:
p.requires_grad_(False)for w in range(HEAD_WARMUP_EPOCHS):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh, averager=None,
freeze_trunk=True)
wdiag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
w_top1 = stats["correct"]/ max(seen,1)
w_by_cap ={nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
w_member =[round(c / max(seen,1),4)for c in stats["member_correct"]]
w_agree = round(stats["agree"]/ max(seen,1),4)
warm ={"top1": round(w_top1,4),"member_top1": w_member,"agree": w_agree,"clean_top1": wdiag["clean_top1"]}
print(f"[{area}] warmup (frozen trunk) {w +1}/{HEAD_WARMUP_EPOCHS} "
f"loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={w_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} trunk_lr=frozen "
f"top1_by_capture={w_by_cap} "
f"member_top1={w_member} agree_rate={w_agree:.4f} "
f"xs_cos_same={wdiag['xs_cos_same']} xs_cos_diff={wdiag['xs_cos_diff']} "
f"wpv={wdiag['wpv']} xsurvey_agree={wdiag['xsurvey_agree']} "
f"clean_top1={wdiag['clean_top1']}", flush=True)for p in trunk_params:
p.requires_grad_(True)for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops":(epochs + HEAD_WARMUP_EPOCHS)* len(crops)* n_caps,"epochs": epochs,"head_warmup_epochs": HEAD_WARMUP_EPOCHS,"total_epochs": epochs + HEAD_WARMUP_EPOCHS,"warmup_top1": warm["top1"],"warmup_member_top1": warm["member_top1"],"warmup_agree_rate": warm["agree"],"warmup_clean_top1": warm["clean_top1"],"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), head linear-probed on the frozen "
f"trunk for {HEAD_WARMUP_EPOCHS} epoch(s), then fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen":(epochs + HEAD_WARMUP_EPOCHS)* len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported), ""head-only warm-up epoch on the frozen trunk before fine-tuning (LP-FT)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Same eyes, more worldly upbringing, actually trained: each member's EfficientNet-B0 trunk starts from Noisy Student weights instead of plain ImageNet weights (re-run of experiment 24, which never reached a GPU) f0d553b7
worse than champion: 0.083 vs 0.078
architecturepivot
0.083
126 m 01 s
$2.65
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The UAV's 'eyes' are a pair of image-recognition networks that learn from a large collection of everyday photos before they learn Berlin. Each time we gave them better early training, they got much better at recognising Berlin in a photograph they had never seen. The chip has no room for bigger eyes, so we keep exactly the same eyes but swap in a version first trained on 300 million photos, many of them deliberately blurred, noisy or with altered colours. We already tried this once, but the cloud computer never started, so the idea was never actually tested.
What it cost
implementation agent
$1.15
design agent
$1.02
figure agent
$0.49
total
$2.65
by model — claude-opus-5-5 $2.65
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.083 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Experiment 24's hypothesis was never tested. Its run died before training: AWS had no g6.xlarge capacity in any eu-central-1 zone (spot or on-demand; train_berlin.log ends 'no capacity for g6.xlarge anywhere in the region'), so the scorer recorded 1e9 and the harness marked it REVERTED. That verdict says nothing about Noisy Student weights, just as experiment 17's crash said nothing about ring pooling (re-run as 18). The same is true of experiment 21 (LP-FT, AWS endpoint connection error). The reasoning stands unchanged on the current champion (exp 20, mission 0.0777: usable 93.0%, false 0.75%, abstain 6.25% on held-out truedop_2024; the three training photographs at 100% usable at the same viewpoints). Every large step on the never-seen photograph in this era came from what the trunk brought with it: from-scratch -> MobileNetV3-Small 10.75% -> 49.5% usable (exp 12), MobileNetV2 86.75% (exp 16), EfficientNet-B0 92.5% (exp 19). Since then, changes to the training procedure have given at most half a point (exp 20 weight averaging, kept) or lost ground (exp 22 continuous vantages 0.103, exp 23 cross-survey JS consistency 0.090). Bigger trunks are ruled out by the size gate (two B0 members = 31.7 MB of 33.6 MB), so this changes the trunk's KNOWLEDGE and keeps its SIZE: same EfficientNet-B0, initialised from the Noisy Student checkpoint (Xie et al. 2020; ImageNet + 300M pseudo-labelled JFT images under RandAugment, dropout and stochastic depth). Its headline result is out-of-distribution robustness (ImageNet-C/-P/-A: blur, noise, brightness, contrast, weather), and that is the photometric half of a survey change. No experiment in any era has varied the pretraining SOURCE of a fixed architecture. Builds on experiment 20 (champion) and is otherwise identical to experiment 24's pre-registered design, whose code survives in runs/20261102_104104_experiment24/model_src/.
Method
ONE change, identical to experiment 24: the file each member's trunk is initialised from goes from torchvision IMAGENET1K_V1 (model/pretrained/effb0_features7.pt) to timm's tf_efficientnet_b0.ns_jft_in1k, ported into torchvision's features[0..7] layout (model/pretrained/effb0ns_features7.pt, already baked and numerically checked by experiment 24's port script model/pretrained/port_effb0_ns.py; both files are still on disk). The TF checkpoint was trained with 'SAME' padding, so the five stride-2 convs (the stem, and the first depthwise conv of stages 2, 3, 4 and 6) pad asymmetrically (Conv2dSame), and trunk BatchNorm eps = 1e-3. Parameter count, ONNX size (+ a few Pad nodes), read levels, MixStyle, cosine head, committee, decode, losses, augmentation, schedule, weight averaging and BN recalibration are all unchanged from experiment 20.
Expected outcome
Same as pre-registered for experiment 24: mission_score 0.0777 -> ~0.055-0.065 (best guess 0.06), mostly from abstentions turning into usable fixes: usable_fix_rate 93.0% -> ~94.5-95.5%, abstain 6.25% -> ~4-5%, false_fix_rate roughly flat at 0.5-1.0% (2-4 of 400 frames). Training-capture diagnostics should stay ~100% usable. Refutation: mission >= 0.0777 with usable <= 93% means the pretraining source of a fixed architecture is not what limits cross-survey transfer here. A far worse result (usable < 85%) would first be checked for a porting fault: padding asymmetry or an eps mismatch.
Result
mission score = 0.082672 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.082672 vs best 0.077671); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 36–36 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
53.4 m
miss, this crop
0.96
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.08392% usablecov 0.93
Fits the aircraft?all deployment gates passed largest per-area model 30,987 KB (limit 4,096 KB) · single-frame inference 49.4 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,814 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 1 m 41 s · implement (Opus) 2 m 19 s · train 1 area 119 m 52 s · score 1 m 50 s · samples 4 s · publish 4 s · whole experiment 126 m 08 s
ts 2026-11-02T12:57:16 · commit f0d553b7fc26 ·
parent c88409728d31 · artifacts runs/20261102_105115_experiment25 ·
agent model — · took 126 m 01 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py472 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.NOISY STUDENT TRUNK WEIGHTS (capture-holdout era, experiment 25 — re-run of24, which never trained: no AWS capacity): the sameEfficientNet-B0 features[0..7] architecture, but each member's trunk isinitialised from timm's tf_efficientnet_b0.ns_jft_in1k (Noisy Student, Xie etal. CVPR 2020: ImageNet + 300M pseudo-labelled JFT images under RandAugment,dropout and stochastic depth; Apache-2.0) instead of torchvisionIMAGENET1K_V1. The checkpoint was trained in TensorFlow, so the trunk is builtby build_tf_same_trunk(): every BatchNorm uses eps 1e-3, and the five stride-2convs (stem; first depthwise conv of features[2], [3], [4], [6]) areConv2dSame — TF 'SAME' padding, the extra row/column at bottom/right — at thesame module paths, so the keys are torchvision's. At 224 px the pads arestem (0,1), features[2] (0,1), [3] (1,2), [4] (0,1), [6] (1,2), exported asconstant Pad nodes. The tensors are ported once, offline, bymodel/pretrained/port_effb0_ns.py (explicit name-by-name mapping, shape- andcoverage-checked, then a mandatory numeric check of every read level againstan independent reference forward) into model/pretrained/effb0ns_features7.pt;nothing is downloaded at train or inference time. Parameter count, readlevels, MixStyle points and everything downstream are unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0ns_features7.pt"
TRUNK_WEIGHTS ="tf_efficientnet_b0.ns_jft_in1k (Noisy Student, Apache-2.0)"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Conv2dSame(nn.Conv2d):"""nn.Conv2d with TensorFlow 'SAME' padding computed from the input size (asymmetric: the extra row/column goes bottom/right). Construct with padding=0. Pads are plain Python ints, so the ONNX export traces them as a constant Pad node at the fixed 224 px input."""def forward(self, x):
ih, iw = int(x.shape[-2]), int(x.shape[-1])
kh, kw =self.weight.shape[-2],self.weight.shape[-1]
sh, sw =self.stride
dh, dw =self.dilation
pad_h = max((math.ceil(ih / sh)-1)* sh +(kh -1)* dh +1- ih,0)
pad_w = max((math.ceil(iw / sw)-1)* sw +(kw -1)* dw +1- iw,0)if pad_h >0or pad_w >0:
x = F.pad(x,[pad_w //2, pad_w - pad_w //2, pad_h //2, pad_h - pad_h //2])return F.conv2d(x,self.weight,self.bias,self.stride,0,self.dilation,self.groups)def _to_conv_same(conv: nn.Conv2d)-> Conv2dSame:return Conv2dSame(conv.in_channels, conv.out_channels, conv.kernel_size,
stride=conv.stride, padding=0, dilation=conv.dilation,
groups=conv.groups, bias=conv.bias isnotNone)def build_tf_same_trunk()-> nn.Sequential:"""Un-loaded EfficientNet-B0 features[0..7] adapted to the TensorFlow conventions the Noisy Student checkpoint was trained with: BatchNorm eps 1e-3 everywhere, and every stride-2 conv (stem features[0][0]; the depthwise conv of the first block of stages features[2], [3], [4], [6]) swapped in place for a Conv2dSame, so the state-dict keys are unchanged. Stride-1 convs keep torchvision's symmetric k//2 padding (== TF SAME for odd kernels). Shared by build_pretrained_trunk() and the port script."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]for m in trunk.modules():if isinstance(m, nn.BatchNorm2d):
m.eps =1e-3
trunk[0][0]= _to_conv_same(trunk[0][0])for i in(2,3,4,6):
dw = trunk[i][0].block[1][0]assert isinstance(dw, nn.Conv2d)and dw.stride ==(2,2)and dw.groups == dw.in_channels, \
f"features[{i}][0] depthwise conv is not the stride-2 dw conv: {dw}"
trunk[i][0].block[1][0]= _to_conv_same(dw)
n_s2 = sum(1for m in trunk.modules()if isinstance(m, nn.Conv2d)and m.stride !=(1,1)andnot isinstance(m, Conv2dSame))assert n_s2 ==0, f"{n_s2} strided conv(s) left with symmetric padding"
return trunk
def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with Noisy Student weights (ported to torchvision's layout, TF-same padding, BN eps 1e-3) loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = build_tf_same_trunk()
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py728 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.NOISY STUDENT WEIGHTS (experiment 25, re-run of 24, which never trained: noAWS capacity): the trunk architecture is unchanged,but each member's EfficientNet-B0 features[0..7] now starts from timm'stf_efficientnet_b0.ns_jft_in1k (Noisy Student, Google/timm, Apache-2.0),ported offline into torchvision's layout (model/pretrained/port_effb0_ns.py ->model/pretrained/effb0ns_features7.pt) and run with the TF conventions it wastrained with (TF-same padding on the stride-2 convs, BN eps 1e-3; seemodel.model.build_tf_same_trunk). Nothing here changes: optimiser groups,schedule, epochs, AUG, MixStyle, weight averaging, BN recalibration,survey_diag, chunking and targets are as in experiment 20.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS, TRUNK_WEIGHTS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"{TRUNK_WEIGHTS} (TF-same padding, BN eps 1e-3) loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:tf_efficientnet_b0.ns_jft_in1k (Noisy Student, timm/Google, ""Apache-2.0) ported to torchvision features[0..7] with TF-same padding, ""fine-tuned at 0.1x LR; experiment 25 (re-run of 24, which never trained: ""no AWS capacity)"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""Noisy Student (tf_efficientnet_b0.ns_jft_in1k) EfficientNet-B0 features[0..7] trunk ""per member, TF-same padding, BN eps 1e-3 (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] (Noisy Student weights, "
f"TF-same padding on stride-2 convs, BN eps 1e-3), two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"trunk_weights": f"{TRUNK_WEIGHTS}; experiment 25 (re-run of 24, which never trained: no AWS capacity)","amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Same eyes, more worldly upbringing: each member's EfficientNet-B0 trunk carries Noisy Student weights (semi-supervised on 300M photographs with injected noise, Apache-2.0) instead of plain ImageNet weights — identical architecture, identical size f55c8c48
training or scoring crashed — no result
architecture
gated fail
9 m 59 s
$4.07
gated fail
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The UAV's 'eyes' are a pair of image-recognition networks that were first taught on a big collection of everyday photos before we teach them Berlin. Every time we gave them better schooling, they got much better at recognising Berlin in a photograph they had never seen. We can't make the eyes bigger any more (the chip has no room), so this time we keep exactly the same eyes but swap in a version that was schooled on 300 million photos, deliberately shown blurred, noisy, re-coloured versions as it learned. That upbringing is known to make it far less thrown by changes in lighting and image quality — which is much of what changes between two aerial surveys of the same city.
What it cost
implementation agent
$1.65
design agent
$1.41
figure agent
$1.00
total
$4.07
by model — claude-opus-5-5 $4.07
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it failed the gate
This design never produced a score at all: training or scoring failed outright (usually a bug in the proposed model or training code, or a model that couldn't be exported and scored). With no numbers to judge it on, it counts as a failure and was rolled back.
Hypothesis
On this ruler, every large step on the never-seen truedop_2024 photograph came from WHAT THE TRUNK BROUGHT WITH IT, not from what it learned from three Berlin surveys: from-scratch -> ImageNet MobileNetV3-Small 10.75% -> 49.5% usable (exp 12), MobileNetV2 86.75% (exp 16), EfficientNet-B0 92.5% (exp 19). Since then the training-procedure levers have given at most half a point (exp 20 weight averaging, 93.0% usable / 0.75% false / 6.25% abstain, mission 0.0777, kept) or lost ground (exp 22 continuous vantages 0.103, exp 23 cross-survey JS consistency 0.090, both reverted; exp 18 ring pooling flat). The three training photographs sit at 100% usable at the same held-out viewpoints, so the residual is purely the survey gap, and the invariance that closes it has so far come from pretraining. The obvious next trunk step is closed by the size gate: two EfficientNet-B0 members already weigh 31.7 MB of 33.6 MB. So this experiment changes the trunk's KNOWLEDGE without changing its SIZE: the same EfficientNet-B0 architecture, but initialised from the Noisy Student checkpoint (Xie et al., CVPR 2020: student trained on ImageNet + 300M pseudo-labelled JFT images under RandAugment, dropout and stochastic depth noise). The paper's headline finding is precisely out-of-distribution robustness beyond what in-domain accuracy predicts — large gains on ImageNet-C (corruptions: blur, noise, brightness, contrast, weather), ImageNet-P and ImageNet-A — and those corruption families are the photometric part of a survey change (exposure, colour balance, haze, sharpness), while 300M diverse photographs give a broader texture/structure prior than 1.3M. In-domain the B0 student is also ~1 point better (78.8 vs 77.7 top-1). This is 'better borrowed eyes' (exps 12/16/19, all kept) taken along the one axis the size gate leaves open: training data and noise of the pretraining, not parameter count. Nothing in this era or the 83 earlier experiments ever varied the pretraining SOURCE of a fixed architecture; every pretrained trunk has been torchvision IMAGENET1K_V1. Builds on experiment 20 (the champion) with everything else — resize, read levels, lifts, MixStyle, cosine head, committee, decode, losses, augmentation, schedule, weight averaging + BN recalibration — unchanged.
Method
ONE change: the pretrained file each member's trunk is loaded from. A one-time port script converts timm's tf_efficientnet_b0.ns_jft_in1k checkpoint into torchvision's efficientnet_b0.features[0..7] key layout (verbatim tensors, shape-checked, numerically verified against timm), baked to model/pretrained/effb0ns_features7.pt. Because the TF checkpoint was trained with TensorFlow 'SAME' padding, every stride-2 convolution in the trunk (stem + the first depthwise conv of stages 2, 3, 4 and 6) pads asymmetrically (TF-same, extra row/column at bottom/right) instead of symmetrically, and the trunk's BatchNorm eps is 1e-3 (TF's). Parameter count, ONNX size (+ a few Pad nodes), read levels (112x14x14, 320x7x7), MixStyle points and everything downstream are unchanged.
Expected outcome
mission_score 0.0777 -> ~0.055-0.065 (best guess 0.06). The gain should come mostly from abstentions converting to usable fixes: usable_fix_rate 93.0% -> ~94.5-95.5%, abstain 6.25% -> ~4-5%, false_fix_rate roughly flat at 0.5-1.0% (2-4 of 400 frames). Training-capture diagnostics should stay ~100% usable. Refutation: if mission >= 0.0777 with usable <= 93%, the pretraining source of a fixed architecture is not what limits cross-survey transfer at this point and the next lever is not trunk weights. A result far worse (e.g. usable < 85%) would first be checked for a porting fault (the port's numeric check is meant to rule that out up front).
Result
mission score = 1000000000.0 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1000000000.0 vs best 0.077671); change discarded
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
No per-area results recorded for this run.
Fits the aircraft?all deployment gates passed largest per-area model — (limit 4,096 KB) · single-frame inference — on one CPU thread (proxy limit 250 ms)
Where this experiment's time went: design (Opus) 3 m 45 s · implement (Opus) 4 m 11 s · train 1 m 44 s · samples 4 s · publish 1 s · whole experiment 10 m 03 s
ts 2026-11-02T10:51:03 · commit f55c8c48ccaf ·
parent f55c8c48ccaf · artifacts runs/20261102_104104_experiment24 ·
agent model — · took 9 m 59 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py471 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.NOISY STUDENT TRUNK WEIGHTS (capture-holdout era, experiment 24): the sameEfficientNet-B0 features[0..7] architecture, but each member's trunk isinitialised from timm's tf_efficientnet_b0.ns_jft_in1k (Noisy Student, Xie etal. CVPR 2020: ImageNet + 300M pseudo-labelled JFT images under RandAugment,dropout and stochastic depth; Apache-2.0) instead of torchvisionIMAGENET1K_V1. The checkpoint was trained in TensorFlow, so the trunk is builtby build_tf_same_trunk(): every BatchNorm uses eps 1e-3, and the five stride-2convs (stem; first depthwise conv of features[2], [3], [4], [6]) areConv2dSame — TF 'SAME' padding, the extra row/column at bottom/right — at thesame module paths, so the keys are torchvision's. At 224 px the pads arestem (0,1), features[2] (0,1), [3] (1,2), [4] (0,1), [6] (1,2), exported asconstant Pad nodes. The tensors are ported once, offline, bymodel/pretrained/port_effb0_ns.py (explicit name-by-name mapping, shape- andcoverage-checked, then a mandatory numeric check of every read level againstan independent reference forward) into model/pretrained/effb0ns_features7.pt;nothing is downloaded at train or inference time. Parameter count, readlevels, MixStyle points and everything downstream are unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0ns_features7.pt"
TRUNK_WEIGHTS ="tf_efficientnet_b0.ns_jft_in1k (Noisy Student, Apache-2.0)"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Conv2dSame(nn.Conv2d):"""nn.Conv2d with TensorFlow 'SAME' padding computed from the input size (asymmetric: the extra row/column goes bottom/right). Construct with padding=0. Pads are plain Python ints, so the ONNX export traces them as a constant Pad node at the fixed 224 px input."""def forward(self, x):
ih, iw = int(x.shape[-2]), int(x.shape[-1])
kh, kw =self.weight.shape[-2],self.weight.shape[-1]
sh, sw =self.stride
dh, dw =self.dilation
pad_h = max((math.ceil(ih / sh)-1)* sh +(kh -1)* dh +1- ih,0)
pad_w = max((math.ceil(iw / sw)-1)* sw +(kw -1)* dw +1- iw,0)if pad_h >0or pad_w >0:
x = F.pad(x,[pad_w //2, pad_w - pad_w //2, pad_h //2, pad_h - pad_h //2])return F.conv2d(x,self.weight,self.bias,self.stride,0,self.dilation,self.groups)def _to_conv_same(conv: nn.Conv2d)-> Conv2dSame:return Conv2dSame(conv.in_channels, conv.out_channels, conv.kernel_size,
stride=conv.stride, padding=0, dilation=conv.dilation,
groups=conv.groups, bias=conv.bias isnotNone)def build_tf_same_trunk()-> nn.Sequential:"""Un-loaded EfficientNet-B0 features[0..7] adapted to the TensorFlow conventions the Noisy Student checkpoint was trained with: BatchNorm eps 1e-3 everywhere, and every stride-2 conv (stem features[0][0]; the depthwise conv of the first block of stages features[2], [3], [4], [6]) swapped in place for a Conv2dSame, so the state-dict keys are unchanged. Stride-1 convs keep torchvision's symmetric k//2 padding (== TF SAME for odd kernels). Shared by build_pretrained_trunk() and the port script."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]for m in trunk.modules():if isinstance(m, nn.BatchNorm2d):
m.eps =1e-3
trunk[0][0]= _to_conv_same(trunk[0][0])for i in(2,3,4,6):
dw = trunk[i][0].block[1][0]assert isinstance(dw, nn.Conv2d)and dw.stride ==(2,2)and dw.groups == dw.in_channels, \
f"features[{i}][0] depthwise conv is not the stride-2 dw conv: {dw}"
trunk[i][0].block[1][0]= _to_conv_same(dw)
n_s2 = sum(1for m in trunk.modules()if isinstance(m, nn.Conv2d)and m.stride !=(1,1)andnot isinstance(m, Conv2dSame))assert n_s2 ==0, f"{n_s2} strided conv(s) left with symmetric padding"
return trunk
def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with Noisy Student weights (ported to torchvision's layout, TF-same padding, BN eps 1e-3) loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = build_tf_same_trunk()
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py726 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.NOISY STUDENT WEIGHTS (experiment 24): the trunk architecture is unchanged,but each member's EfficientNet-B0 features[0..7] now starts from timm'stf_efficientnet_b0.ns_jft_in1k (Noisy Student, Google/timm, Apache-2.0),ported offline into torchvision's layout (model/pretrained/port_effb0_ns.py ->model/pretrained/effb0ns_features7.pt) and run with the TF conventions it wastrained with (TF-same padding on the stride-2 convs, BN eps 1e-3; seemodel.model.build_tf_same_trunk). Nothing here changes: optimiser groups,schedule, epochs, AUG, MixStyle, weight averaging, BN recalibration,survey_diag, chunking and targets are as in experiment 20.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS, TRUNK_WEIGHTS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"{TRUNK_WEIGHTS} (TF-same padding, BN eps 1e-3) loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:tf_efficientnet_b0.ns_jft_in1k (Noisy Student, timm/Google, ""Apache-2.0) ported to torchvision features[0..7] with TF-same padding, ""fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""Noisy Student (tf_efficientnet_b0.ns_jft_in1k) EfficientNet-B0 features[0..7] trunk ""per member, TF-same padding, BN eps 1e-3 (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] (Noisy Student weights, "
f"TF-same padding on stride-2 convs, BN eps 1e-3), two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"trunk_weights": TRUNK_WEIGHTS,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Same place, same belief: each member's tile-belief map for one place must agree across the three survey photographs (Jensen-Shannon consistency, AugMix-style), trained on batches that hold every place in all three surveys 4a3afb08
worse than champion: 0.090 vs 0.078
loss
0.090
121 m 20 s
$3.20
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model learns Berlin from three different aerial photographs taken in different years and seasons. Until now it was graded on each photograph separately, so it could recognise a street corner in one photo with total certainty and only half-heartedly in another, and nobody minded. Now, every time it studies a place, it sees that place in all three photographs at once and is also marked down whenever its three answers disagree — so it learns to be equally sure about a place whatever photograph it is looking at, which is what it needs when the UAV's own camera shows it a fourth.
What it cost
design agent
$1.41
implementation agent
$0.93
figure agent
$0.85
total
$3.20
by model — claude-opus-5-5 $3.20
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.090 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Champion exp 20 (0.0777) on held-out truedop_2024: usable 93.0%, false 0.75% (3 frames), abstain 6.25% (25 frames); the three training photographs score 100% usable / 0% false at the same held-out viewpoints. So what remains is purely the survey gap, and it is mostly ABSTENTION: on a foreign photograph a member's belief spreads off the right 3x3 block (min-member block mass < 0.3). The run's own clean diagnostic shows the same gap INSIDE training: on 512 fixed clean training-lattice places, each member's argmax tile agrees across the three training surveys only 84% of the time (xsurvey_agree [0.844, 0.844]) while per-survey clean top1 is ~0.88-0.91 — i.e. the loss never asks a member to hold the SAME belief about a place in two photographs; it asks each photograph separately to hit the label, and CE is satisfied by survey-specific routes to it, with survey-specific confidence. Two facts about the code make this sharper than it looks: (1) the cross-entropy cannot see agreement at all, and (2) although chunks are 'paired' (every position in all three surveys), run_epoch draws each 64-view mini-batch by a random permutation of the 4,095-view chunk, so the three survey views of a place almost never meet in one gradient step. Every earlier attempt at cross-survey invariance acted on the FEATURE (exp 3: cosine of GAP features, from scratch, reverted; exp 9: within-place variance penalty, crashed at 1e9, never measured; exp 8: DINOv2 distillation, from scratch, reverted), before the pretrained trunk existed and never on the thing the confidence gate actually reads. This experiment acts on the OUTPUT: the belief distribution over 2,970 tiles. Following AugMix (Hendrycks et al., ICLR 2020), whose Jensen-Shannon consistency across augmented views is the component that most improved accuracy AND calibration under distribution shift, each member's deployed softmax for one place in the three surveys is pulled toward their mixture. A member that already knows the place in two surveys gets a gradient telling its third view to put its belief in the same place with the same sharpness — exactly the behaviour an abstaining 2024 frame lacks. Since the photometric augmentation is drawn independently per view, the term also asks for agreement across re-photographing nuisances. Builds on exp 2 (paired-survey batches, kept) by finally making the pairing reach the gradient, and on exps 3/9 by moving their invariance goal from feature space to belief space on today's pretrained trunk. Architecture, graph, decode, committee, MixStyle, margin loss, augmentation, schedule and weight averaging all unchanged; the members stay independent (no cross-member term).
Method
model/train.py only. (a) Mini-batches are built from whole PLACES: permute the chunk's positions, take P = BATCH_SIZE // n_caps = 21 positions per batch and all n_caps = 3 survey views of each (63 views, survey-grouped), instead of a random permutation of views. (b) Per member, add LAMBDA_JSD * JSD where JSD = mean over places of (1/K) sum_k KL(p_k || pbar), p_k = softmax(COS_SCALE * cos) (the deployed, margin-free belief) of the place's view in survey k, pbar = mean_k p_k. LAMBDA_JSD = 6.0. Same grouping in the BN recalibration pass. Nothing else changes.
Expected outcome
Predicted on truedop_2024: mission 0.078 -> ~0.050-0.070; usable_fix_rate 93.0% -> ~94-95.5%, gained mainly from abstentions (6.25% -> ~4-5%) whose min-member block mass rises above 0.3 because a member's belief on a new survey is now trained to be as sharp, in the same place, as on the others; false_fix_rate at or below 0.75% (the consistency term also penalises one survey's confident-elsewhere belief, so it should not rise). train_capture_diagnostics stay ~100% usable. Training-log signals: the clean survey diagnostic xsurvey_agree should rise from 0.844 toward >=0.9 and the logged per-epoch jsd should fall well below its epoch-1 value; xs_cos_same should rise modestly. Refutation: 2024 usable flat or down with xsurvey_agree clearly up means agreement among the three training surveys does not transfer to the fourth (the abstentions are about content the three never show, e.g. 2024-only construction), and the next lever is data/views rather than invariance. If xsurvey_agree does not rise, the term was too weak or overpowered by CE and the hypothesis is untested at this weight. A drop in usable together with lower mean_max_softmax means the term smoothed beliefs (over-regularised) rather than aligning them.
Result
mission score = 0.090183 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.090183 vs best 0.077671); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 39–39 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
54.3 m
miss, this crop
0.92
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.09092% usablecov 0.93
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.3 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,606 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 26 s · implement (Opus) 1 m 31 s · train 1 area 115 m 14 s · score 1 m 48 s · samples 4 s · publish 4 s · whole experiment 121 m 26 s
ts 2026-11-02T10:40:42 · commit 4a3afb0835e6 ·
parent 4a3afb0835e6 · artifacts runs/20261102_083922_experiment23 ·
agent model — · took 121 m 20 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py767 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.CROSS-SURVEY BELIEF CONSISTENCY (experiment 23): mini-batches are now builtfrom whole PLACES — the chunk's positions are permuted and each batch takesplaces_per_batch = BATCH_SIZE // n_caps positions (21 for 3 captures) with ALLn_caps survey views of each, contiguous and place-major (63 views), instead ofa random permutation of views, so the three surveys of a place always meet inone gradient step. Per member, besides its own loss_fn, a Jensen-Shannonconsistency term (AugMix-style) is added with weight LAMBDA_JSD: for eachplace, (1/K) sum_k KL(p_k || pbar), where p_k = softmax(COS_SCALE * cos) isthe member's deployed, margin-free belief on the place's view in survey k andpbar the mean over k; gradients flow through all K views and the mixture. Nocross-member term — members stay independent. recalibrate_bn() uses the samegrouped batching. The per-epoch mean JSD is logged as jsd.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
LAMBDA_JSD =6.0# weight of the per-member cross-survey Jensen-Shannon consistency term
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def place_batches(n, n_caps, places_per_batch, device):"""Survey-grouped mini-batch indices over one chunk of n position-major views (view j = position j // n_caps, capture j % n_caps): permute the positions, take places_per_batch of them per batch and every capture of each, place-major with the K views of a place contiguous."""
n_pos = n // n_caps
pperm = torch.randperm(n_pos, device=device)
ar = torch.arange(n_caps, device=device)for i in range(0, n_pos, places_per_batch):
pidx = pperm[i:i + places_per_batch]yield(pidx.unsqueeze(1)* n_caps + ar).reshape(-1)def check_grouping(cap_idx_cpu, n_caps):"""The grouped batching relies on chunk_views' position-major order; check it on the CPU tensor rather than trust it."""
n = len(cap_idx_cpu)assert n % n_caps ==0, f"chunk of {n} views not divisible by {n_caps} captures"
expected = torch.arange(n_caps, dtype=cap_idx_cpu.dtype).repeat(n // n_caps)assert torch.equal(cap_idx_cpu, expected), \
"chunk views are not position-major (capture = j % n_caps)"class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
places_per_batch = max(1, BATCH_SIZE // n_caps)
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
check_grouping(views[5], n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)for idx in place_batches(n, n_caps, places_per_batch, device):if done >= n_batches:break
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
jsd_sum = torch.zeros((), device=device)
seen =0
places_per_batch = max(1, BATCH_SIZE // n_caps)
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)if ci ==0:
check_grouping(views[5], n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)for idx in place_batches(n, n_caps, places_per_batch, device):
B = len(idx)
P = B // n_caps
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)# Cross-survey Jensen-Shannon consistency of the deployed belief.
logp = F.log_softmax(logits_k, dim=1).view(P, n_caps,-1)
p = logp.exp()
log_m = p.mean(dim=1, keepdim=True).clamp_min(1e-7).log()
jsd_k =(p *(logp - log_m)).sum(dim=2).mean()
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)+ LAMBDA_JSD * jsd_k
jsd_sum += jsd_k.detach()* B / N_MEMBERS
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree),"jsd_sum": float(jsd_sum)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}
final_jsd =0.0
places_per_batch = max(1, BATCH_SIZE // n_caps)for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
final_jsd = round(stats["jsd_sum"]/ max(seen,1),6)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} jsd={stats['jsd_sum']/ max(seen,1):.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported), "
f"survey-grouped batches ({places_per_batch} places x all {n_caps} surveys), "
f"per-member cross-survey Jensen-Shannon belief consistency (lambda {LAMBDA_JSD})"),"lambda_jsd": LAMBDA_JSD,"places_per_batch": places_per_batch,"batch_views": places_per_batch * n_caps,"final_jsd": final_jsd,"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Continuous vantages: every training framing is shifted by a fresh random offset of up to ±12 px, so over an epoch the training views cover the ground continuously instead of standing on the fixed 24 m lattice d1fb6f8a
worse than champion: 0.103 vs 0.078
augmentation
0.103
225 m 40 s
$2.90
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model studied Berlin from a fixed grid of spots 24 metres apart, the same spots every time, so it could partly memorise 'how this exact framing of this exact photo looks'. Now every time it studies a place, the camera is nudged a random few metres sideways first, so it never sees exactly the same picture twice. It has to learn what the place looks like, not what one framing looks like, and that should carry better to a photograph it has never seen.
What it cost
design agent
$1.26
figure agent
$0.92
implementation agent
$0.72
total
$2.90
by model — claude-opus-5-5 $2.90
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.103 it didn't beat the champion's 0.078, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Champion exp 20 (0.0777): on held-out truedop_2024, usable 93.0%, false fix 0.75%, abstain 6.25%. The same eval viewpoints on the three training photographs score 100% usable / 0% false. Every position-sampling choice in this era has been the same: train.py shows each place only at the 72,712 exact lattice centres, 24 px apart, with heading as the only geometric variation. So each lattice framing appears three times per epoch (once per survey) at the same pixel-exact framing, over 8 epochs. A network with ~31 MB of weights can fit that discrete set of framings as framing-plus-survey fingerprints. That fit costs nothing on the training photographs (100%) but gives no structural invariance on a new photograph. Every eval view stands 11-17 m off-lattice, so on 2024 the model faces a new photograph AND an unseen framing at once. Its remaining abstentions are where the two members' beliefs stop agreeing. CLAUDE.md's Prignitz-detour record names this exact mechanism, continuous-vantage training with ±12 px jitter, as 'designed and implemented; never trained' and as the natural next move. That detour also showed that whatever fixes look-alike confusions has to act during training, not at decode time. This era has never touched how training positions are sampled; arch_json shows every change in exps 12-21 went to the trunk, head, augmentation pixels or weight schedule. Hypothesis: re-drawing each framing at a continuous random offset every time it is used makes any two uses of a place differ in framing. That removes the pixel-exact framing fingerprint as a solution and pushes both members toward the layout that survives a shift, which is also what survives a change of survey. The result should be more members agreeing on 2024, and so fewer abstentions. Note, stated plainly: with ±12 px jitter some training framings on the TRAINING photographs fall close to eval vantages. That is legitimate (deployment views are arbitrary vantages over mapped ground, and §4 says the model is shown all of its box), but it makes the logged train_capture_diagnostics less informative as a viewpoint test. The scored question, a never-seen photograph, is untouched: truedop_2024 is never loaded. Experiment 21 (LP-FT) is not re-run here. It died on a laptop DNS failure during its final epoch, so its verdict is void, but its training curves through epoch 7 matched exp 20's to the third decimal (top1 0.9062 vs 0.9056, xs_cos_same 0.783 vs 0.787), so a re-run is expected to land within noise.
Method
model/train.py only. chunk_views() gains a per-position random offset (dx, dy), each drawn uniformly from the integers in [-12, +12] px (half the lattice stride). The offset is drawn once per position per use and SHARED across the three captures, the same way the heading is already shared, so the paired-survey design is kept. It is applied to the crop centre before cutting, and the targets (pos, cell_idx) are computed from the shifted centre. Shifted centres are clamped so the crop window stays inside the raster. Positions whose ±12 px jitter box could reach the region-holdout buffer get zero jitter (precomputed once), so the holdout diagnostic stays clean. Used in run_epoch and recalibrate_bn. survey_diag stays on the exact lattice. Nothing else changes: model.py, the losses, augmentation, MixStyle, committee, weight averaging, EPOCHS, and the export are all as in exp 20.
Expected outcome
mission_score 0.078 -> ~0.055-0.065: usable 93.0% -> ~94.5-95.5%, mostly from abstentions turning into usable fixes (abstain 6.25% -> ~4.5%), with false fix flat at ≤1.0%. Training-photograph diagnostics stay ~100% usable. Final training top1 (augmented, vs containing cell) may read 1-2 points lower than exp 20's 0.910, because shifted views sit nearer cell borders more often; that is expected and is not a regression. Refutation: if 2024 usable does not rise above 93.0%, then framing fingerprints were not what limited the new-photograph fixes. In that case the residual is purely photographic (survey content: season, construction, shadows), and the next lever is what the model sees, not where it stands. Wall time is unchanged (no extra compute per crop).
Result
mission score = 0.102676 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.102676 vs best 0.077671); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 36–36 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
50.9 m
miss, this crop
0.98
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.10392% usablecov 0.93
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,529 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 4 m 01 s · implement (Opus) 1 m 04 s · train 1 area 218 m 28 s · score 1 m 49 s · samples 4 s · publish 4 s · whole experiment 225 m 46 s
ts 2026-11-02T08:38:56 · commit d1fb6f8aff89 ·
parent d1fb6f8aff89 · artifacts runs/20261102_045316_experiment22 ·
agent model — · took 225 m 40 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py761 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.CONTINUOUS VANTAGES (capture-holdout era, experiment 22): every time alattice position is used in run_epoch or recalibrate_bn, chunk_views() shiftsits crop centre by a fresh integer offset (dx, dy), each uniform in[-JITTER_PX, +JITTER_PX] (half the 24 px lattice stride), SHARED across thetraining captures like the heading, so over an epoch the training framingstile the ground continuously instead of standing on the fixed lattice. Thecell/tent/offset targets follow the shifted centre; centres are clamped sothe window stays inside the raster; positions whose jitter box could reachthe region-holdout buffer (jit_ok False, precomputed once with the frozen_window_hits_holdout) stay on the lattice. survey_diag stays on the exactlattice.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, _window_hits_holdout, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
JITTER_PX =12# max per-axis training-framing offset (half of dataset.STRIDE_PX = 24)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps, jit_ok=None, jitter_px=0):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. jitter_px > 0 (experiment 22): each position's centre is shifted by one integer (dx, dy) uniform in [-jitter_px, jitter_px], shared across the captures like the heading (drawn AFTER the heading), zeroed where jit_ok is False (holdout buffer), and clamped so gpu_crops' window [c - hw, c + hw - 1] stays inside the raster. Targets use the shifted xy. """
gw,_= grid_dims(meta)
idx_t = torch.as_tensor(indices, dtype=torch.int64)
xy = crop_xy[idx_t]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared headingif jitter_px >0:
dx = torch.as_tensor(rng.integers(-jitter_px, jitter_px +1, size=len(indices)),
dtype=torch.int64)
dy = torch.as_tensor(rng.integers(-jitter_px, jitter_px +1, size=len(indices)),
dtype=torch.int64)if jit_ok isnotNone:
ok = jit_ok[idx_t].to(torch.int64)
dx = dx * ok; dy = dy * ok
hw = WINDOW_PX //2+1
x =(xy[:,0]+ dx).clamp(hw, meta["width"]- hw)
y =(xy[:,1]+ dy).clamp(hw, meta["height"]- hw)
xy = torch.stack([x, y], dim=1)
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches, jit_ok=None):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps, jit_ok=jit_ok, jitter_px=JITTER_PX)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None, jit_ok=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps, jit_ok=jit_ok, jitter_px=JITTER_PX)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)# Continuous vantages: a position may jitter only if no shift inside its# ±JITTER_PX box can bring the window into the region-holdout buffer. The# holdout blocks and the window are axis-aligned squares, so the four# corner shifts bound every shift in the box.
hw_j = WINDOW_PX //2+1
jit_ok = torch.tensor([not any(_window_hits_holdout(area, int(cx)+ sx, int(cy)+ sy, hw_j)for sx in(-JITTER_PX, JITTER_PX)for sy in(-JITTER_PX, JITTER_PX))for cx, cy in crop_xy.tolist()], dtype=torch.bool)
n_jit = int(jit_ok.sum())
print(f"[{area}] jitter ±{JITTER_PX} px on {n_jit}/{len(jit_ok)} positions "
f"(rest held at lattice: holdout buffer)", flush=True)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone),
jit_ok=jit_ok)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} jitter=±{JITTER_PX}px lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES,
jit_ok=jit_ok)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported), "
f"continuous-vantage jitter ±{JITTER_PX} px per use, shared across captures"),"jitter_px": JITTER_PX,"jitter_positions": n_jit,"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Probe first, then fine-tune: one extra opening epoch trains only the head on the FROZEN ImageNet trunk, so the random tile head's first gradients cannot distort the borrowed eyes (LP-FT) 3e9d902e
training or scoring crashed — no result
training
gated fail
109 m 59 s
$2.64
gated fail
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model's 'eyes' were borrowed from a network that had already looked at a million everyday photos, and that borrowed vision is what lets it recognise Berlin in a photograph it has never seen. Until now we started teaching the eyes and the brand-new 'map-reading' part at the same moment — so in the first hours the confused new part was yanking the borrowed eyes around. Now the map-reading part first practises for one round with the eyes held still, and only then are both tuned together, so the eyes keep more of what made them useful.
What it cost
design agent
$0.96
figure agent
$0.88
implementation agent
$0.80
total
$2.64
by model — claude-opus-5-5 $2.64
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it failed the gate
This design never produced a score at all: training or scoring failed outright (usually a bug in the proposed model or training code, or a model that couldn't be exported and scored). With no numbers to judge it on, it counts as a failure and was rolled back.
Hypothesis
Every large step on the held-out truedop_2024 photograph in this era came from the ImageNet-pretrained trunk (exp 12: 10.75% -> 49.5% usable; exp 16 MobileNetV2: 86.75%; exp 19 EfficientNet-B0: 92.5%), i.e. what transfers to a never-seen survey is the invariance the trunk brought from a million photographs, not what it learned from three. Experiment 20 (champion, 0.078: usable 93.0%, false 0.75%, abstain 6.25%) shows that how the trunk is TRAINED still matters out-of-domain: a better point on the same trajectory bought 0.5 points of usable and cut false fixes from 1.0% to 0.75% while the three training photographs stayed at 100%. The size gate (31.7 MB of 33.6 MB) closes the capacity road, so the remaining lever is the fine-tuning procedure. Today the trunk is fine-tuned from step 1 jointly with a RANDOMLY INITIALISED head (prototypes std 0.01 over 2,970 tiles, random 1x1 lifts, random embed BatchNorm): the earliest, largest gradients reaching the pretrained blocks are noise from a head that does not yet know any tile, and their trunk BatchNorm running stats start adapting at the same moment. Kumar et al. (ICLR 2022, 'Fine-Tuning can Distort Pretrained Features and Underperform Out-of-Distribution') prove and measure exactly this: full fine-tuning from a random head distorts the pretrained features along the directions the in-domain data uses and leaves the rest behind, which costs out-of-distribution accuracy (~7-10 points OOD on their benchmarks) while in-distribution accuracy is unchanged or better; training the head first on the frozen trunk (linear probe, then fine-tune: LP-FT) removes most of that loss. That is our split precisely: in-domain saturated at 100%, out-of-domain at 93%. Nothing in this era (searched hypothesis/method for freeze/probe/warm-up: none) nor in the 83 earlier experiments ever trained the head before the trunk; the trunk's training procedure since exp 12 has been 'fine-tune at 0.1x from step 1' unchanged. Builds on experiment 20 (the champion) with architecture, graph, losses, augmentation, MixStyle, committee, the fine-tune schedule and weight averaging all unchanged.
Method
model/train.py only: prepend HEAD_WARMUP_EPOCHS = 1 extra epoch before the existing fine-tuning run. During it every member's pretrained trunk (m.trunk: EfficientNet-B0 features[0..7]) is frozen — requires_grad False on all trunk parameters and m.trunk kept in eval mode, so its BatchNorm running stats stay at their ImageNet values and stochastic depth is off — and only the head parameters (both 1x1 lifts, embed BatchNorm1d, prototypes, offset head) train, at the head LR 1e-3, with the same losses, augmentation, MixStyle and paired-survey batches as today. After that epoch the trunk is unfrozen and the existing EPOCHS-epoch run follows exactly as now (trunk at 0.1x, cosine LR multiplier 1.0 -> 0.1 over those EPOCHS epochs, weight averaging from fine-tune epoch EPOCHS//2+1, BN recalibration, export). Total epochs = EPOCHS + 1; the warm-up epoch is cheaper than a normal one (no trunk backward).
Expected outcome
Predicted on truedop_2024: mission 0.078 -> ~0.050-0.065; usable_fix_rate 93.0% -> ~94-95.5% (gain mostly from abstentions converting to usable fixes, as each member's tile belief on a foreign photograph rides less-distorted ImageNet features and the two members agree more often), false_fix_rate at or below 0.75%, abstain 6.25% -> ~4-5%. train_capture_diagnostics stay ~100% usable (LP-FT does not cost in-domain accuracy); median error ~36 m unchanged; model size and latency identical (same graph). Logged signals to read: after the warm-up epoch, top1 on the training views should already be substantial (frozen ImageNet GAP features + MLP lift can separate many tiles) — if it is near zero, the probe phase was too short to give the fine-tune a good head and the experiment tests less than intended; the end-of-run survey_diag xs_cos_same / xsurvey_agree should be at or above experiment 20's. Refutation: 2024 usable flat or down with the training diagnostics unchanged says feature distortion by the random head is not what limits the survey gap at this point (plausibly because the 0.1x trunk LR and weight averaging already protect the features), and that the remaining 7% abstentions need new information (more photographs, a different view of the frame) rather than a gentler fine-tune.
Result
mission score = 1000000000.0 (previous best 0.077671) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1000000000.0 vs best 0.077671); change discarded
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
No per-area results recorded for this run.
Fits the aircraft?all deployment gates passed largest per-area model — (limit 4,096 KB) · single-frame inference — on one CPU thread (proxy limit 250 ms)
Where this experiment's time went: design (Opus) 1 m 59 s · implement (Opus) 1 m 30 s · train 106 m 12 s · samples 4 s · whole experiment 110 m 02 s
ts 2026-11-02T04:53:04 · commit 3e9d902e15c1 ·
parent 3e9d902e15c1 · artifacts runs/20261102_030305_experiment21 ·
agent model — · took 109 m 59 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py773 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.HEAD WARM-UP (experiment 21, LP-FT): HEAD_WARMUP_EPOCHS extra openingepoch(s) run BEFORE the existing fine-tuning run. During them every member'spretrained trunk is frozen — requires_grad False on all trunk parameters andm.trunk held in eval mode (BatchNorm running stats stay at their ImageNetvalues, stochastic depth off) — and only the head (both 1x1 lifts, embedBatchNorm1d, prototypes, offset head) trains at the head LR 1e-3, with thesame losses, augmentation, MixStyle (a separate Member module, still in trainmode) and paired-survey batches. The LR scheduler is not stepped during thewarm-up, so the fine-tune schedule starts fresh at multiplier 1.0. Then thetrunk is unfrozen and the previous EPOCHS-epoch run follows unchanged (trunkat 0.1x, cosine 1.0 -> 0.1, weight averaging from fine-tune epochEPOCHS//2 + 1, BN recalibration, export). The optimiser is not rebuilt: thehead's Adam state carries over; the trunk's starts fresh at unfreeze. So therandom head's first gradients never reach the borrowed features (Kumar etal., ICLR 2022). Total epochs = EPOCHS + HEAD_WARMUP_EPOCHS.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
HEAD_WARMUP_EPOCHS =1# extra opening epoch(s): head trains on the FROZEN pretrained trunk (LP-FT)
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None,
freeze_trunk: bool =False):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only. `freeze_trunk` (head warm-up): every member's trunk is held in eval mode (BN running stats frozen, stochastic depth off); the caller has set requires_grad False on the trunk parameters."""
model.train()if freeze_trunk:for m in model.members:
m.trunk.eval()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}# HEAD WARM-UP (LP-FT): head only, frozen trunk (weights + BN stats), no# sched.step() so the fine-tune schedule below starts at multiplier 1.0.
warm ={"top1":None,"member_top1":None,"agree":None,"clean_top1":None}for p in trunk_params:
p.requires_grad_(False)for w in range(HEAD_WARMUP_EPOCHS):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh, averager=None,
freeze_trunk=True)
wdiag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
w_top1 = stats["correct"]/ max(seen,1)
w_by_cap ={nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
w_member =[round(c / max(seen,1),4)for c in stats["member_correct"]]
w_agree = round(stats["agree"]/ max(seen,1),4)
warm ={"top1": round(w_top1,4),"member_top1": w_member,"agree": w_agree,"clean_top1": wdiag["clean_top1"]}
print(f"[{area}] warmup (frozen trunk) {w +1}/{HEAD_WARMUP_EPOCHS} "
f"loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={w_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} trunk_lr=frozen "
f"top1_by_capture={w_by_cap} "
f"member_top1={w_member} agree_rate={w_agree:.4f} "
f"xs_cos_same={wdiag['xs_cos_same']} xs_cos_diff={wdiag['xs_cos_diff']} "
f"wpv={wdiag['wpv']} xsurvey_agree={wdiag['xsurvey_agree']} "
f"clean_top1={wdiag['clean_top1']}", flush=True)for p in trunk_params:
p.requires_grad_(True)for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops":(epochs + HEAD_WARMUP_EPOCHS)* len(crops)* n_caps,"epochs": epochs,"head_warmup_epochs": HEAD_WARMUP_EPOCHS,"total_epochs": epochs + HEAD_WARMUP_EPOCHS,"warmup_top1": warm["top1"],"warmup_member_top1": warm["member_top1"],"warmup_agree_rate": warm["agree"],"warmup_clean_top1": warm["clean_top1"],"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), head linear-probed on the frozen "
f"trunk for {HEAD_WARMUP_EPOCHS} epoch(s), then fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen":(epochs + HEAD_WARMUP_EPOCHS)* len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported), ""head-only warm-up epoch on the frozen trunk before fine-tuning (LP-FT)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Fly the average, not the last step: the exported model is the uniform average of the weights visited over the second half of training (SWAD/SWA-style dense weight averaging), with BatchNorm statistics recalibrated for the averaged weights 0c598205
new best: 0.085 → 0.078
training
0.078
121 m 52 s
$2.76
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Training a model is like a hiker wandering downhill in fog: where they happen to be standing at the moment we stop is a bit random, and often on a narrow ledge where a small change in the ground (a new photograph of the city) sends them tumbling. Instead of keeping the hiker's last footprint, we average all the spots they stood on during the second half of the walk. That average lands in the middle of a broad, flat valley, so a photograph taken in a different year, season or light moves the model's answer less. The UAV carries exactly the same size of model; only the choice of which version we ship has changed.
What it cost
design agent
$1.08
figure agent
$0.91
implementation agent
$0.77
total
$2.76
by model — claude-opus-5-5 $2.76
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.085 to 0.078 — 0.008 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
Every architectural lever this era pulled has been the trunk, and the size gate now closes that road: experiment 19's export is 31.7 MB against a 32 MiB (33.6 MB) fp32 ceiling, so a bigger or third trunk cannot be added. What remains on the held-out truedop_2024 photograph is 6.5% abstention and 1.0% false fixes (usable 92.5%, mission 0.085), while the three training photographs read 100% usable / 0% false at the same held-out viewpoints: the residual is entirely the survey gap. A never-seen photograph is a shift of the input distribution, and the domain-generalisation literature is consistent on what a training procedure can do about such a shift with no extra capacity: the solution found by SGD's last iterate sits in a sharp region whose loss rises quickly under shift, while the average of the weights visited along the late trajectory sits in a flatter, wider minimum whose test loss rises much more slowly (SWA, Izmailov et al. UAI 2018; SWAD, Cha et al. NeurIPS 2021, which made dense weight averaging the strongest single domain-generalisation method on DomainBed, consistently beating ERM by 1.5-3 points out-of-domain, with gains concentrated in the shifted domains rather than the in-domain ones). That is exactly our split: in-domain is saturated (100%), out-of-domain is 92.5%. Nothing in 19 experiments of this era, nor any of the 83 earlier ones (searched: no EMA/SWA/weight-averaging row in lineage_history), has changed WHICH point of the trajectory is flown; every export is the last iterate of an 8-epoch run whose loss was still falling (6.16 -> 5.40 over epochs 5-8) and whose learning rate never drops below 0.1x, so the last iterate is still being kicked around by single-batch noise. Averaging is also the natural partner of the committee gate: frames abstain when one member's belief on the consensus block falls below 0.3, and a flatter member's softmax moves less when the photograph changes, so frames currently lost to one member wobbling should convert to usable fixes. Builds on experiment 19 (the champion) unchanged in architecture.
Method
model/train.py only: keep a running UNIFORM average of every member parameter, updated every AVG_EVERY = 4 optimiser steps from the first step of epoch AVG_START_EPOCH = epochs // 2 + 1 (epoch 5 of 8) to the end of training (~13.6k steps -> ~3.4k snapshots). After the last epoch, load the averaged parameters into the model, recalibrate every BatchNorm layer's running statistics for the averaged weights with one no-grad pass of BN_RECAL_BATCHES = 400 augmented paired-survey training batches (cumulative averaging, momentum=None), and export THAT model. The architecture, deployed graph, losses, augmentation, schedule, epochs and optimiser are unchanged.
Expected outcome
Predicted on truedop_2024: mission 0.085 -> ~0.055-0.070; usable_fix_rate 92.5% -> ~94-95% (most of the gain from abstentions converting to usable fixes as the committee members' beliefs become more stable under the survey shift), false_fix_rate staying at or below 1.0%, abstain_rate 6.5% -> ~4-5%. train_capture_diagnostics should stay at ~100% usable (an average of good late-trajectory points is not worse in-domain); median error ~36 m roughly unchanged. Model size and latency identical (same graph, same parameter count). Refutation: usable on 2024 flat or down with the train diagnostics unchanged would say the residual survey gap is not a sharpness/flatness effect, and that the last 7.5% must be bought with new information (data or capacity), not with a better point on the same trajectory. If the survey_diag logged on the averaged model shows higher xs_cos_same / xsurvey_agree than the last iterate's but 2024 does not move, that also is informative and should be recorded.
Result
mission score = 0.077671 (previous best 0.085172) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 36–36 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
48.9 m
miss, this crop
0.98
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.07893% usablecov 0.94
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.8 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,598 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 01 s · implement (Opus) 1 m 08 s · train 1 area 116 m 36 s · score 1 m 48 s · samples 4 s · publish 4 s · whole experiment 121 m 59 s
ts 2026-11-02T03:02:43 · commit 0c598205035a ·
parent 0d22d24b7146 · artifacts runs/20261102_010051_experiment20 ·
agent model — · took 121 m 52 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py712 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.WEIGHT AVERAGING (experiment 20): from the first step of epoch epochs//2 + 1(1-based) to the end of training, a WeightAverager keeps a uniform runningmean of every model PARAMETER, updated every AVG_EVERY optimiser steps(SWA/SWAD-style dense averaging; Python-int counters, foreach lerp, no hostsyncs). After the last epoch the averaged parameters are loaded into themodel, every BatchNorm layer's running statistics are reset and re-measured(cumulative, momentum=None) by recalibrate_bn() over BN_RECAL_BATCHESaugmented paired-survey training batches in train mode with no grad, and THATmodel is exported. Buffers are re-measured, never averaged. The per-epochsurvey_diag still measures the last iterate; a final survey_diag on theaveraged model is logged beside it. Graph, parameter count, losses,augmentation, schedule and optimiser are unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
AVG_EVERY =4# optimiser steps between weight snapshots
BN_RECAL_BATCHES =400# augmented training batches used to re-measure BN stats of the averaged model# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)class WeightAverager:"""Uniform running mean of every model parameter (never buffers), snapshotted every AVG_EVERY optimiser steps. Counters are Python ints and the update is an on-device foreach lerp, so nothing stalls the GPU queue."""def __init__(self, model):self.params =[p for p in model.parameters()]self.avg =Noneself.n =0self.step =0def maybe_update(self):self.step +=1ifself.step % AVG_EVERY !=0:returnwith torch.no_grad():ifself.avg isNone:self.avg =[p.detach().clone()for p inself.params]self.n =1returnself.n +=1
cur =[p.detach()for p inself.params]
w =1.0/self.n
try:
torch._foreach_lerp_(self.avg, cur, w)except(AttributeError, RuntimeError, NotImplementedError):for a, p in zip(self.avg, cur):
a.lerp_(p, w)def copy_to(self, model):with torch.no_grad():for p, a in zip(model.parameters(),self.avg):
p.copy_(a)def recalibrate_bn(model, scene, crop_xy, meta, rng, device, n_caps,
pos_per_chunk, n_batches):"""Reset and re-measure every BatchNorm layer's running statistics for the current (averaged) weights: train mode (batch stats, MixStyle and stochastic depth as in training), no grad, cumulative averaging (momentum=None), over n_batches augmented paired-survey training batches drawn exactly like run_epoch. No parameter is touched. Returns the number of batches actually used."""
bns =[m for m in model.modules()if isinstance(m,(torch.nn.BatchNorm1d, torch.nn.BatchNorm2d))]
saved =[m.momentum for m in bns]for m in bns:
m.reset_running_stats()
m.momentum =None
model.train()
done =0
order = rng.permutation(len(crop_xy))with torch.no_grad():for start in range(0, len(order), pos_per_chunk):if done >= n_batches:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, _cell_idx, _pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):if done >= n_batches:break
idx = perm[i:i + BATCH_SIZE]
xb0 = gpu_crops(scene, cap_idx[idx], cx[idx], cy[idx], ang[idx])for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
member(xb_k)
done +=1for m, mom in zip(bns, saved):
m.momentum = mom
return done
def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None, averager=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()if averager isnotNone:
averager.maybe_update()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
averager = WeightAverager(model)
avg_start = epochs //2# 0-based; epoch epochs//2 + 1 (1-based)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}, weight averaging from epoch {avg_start +1} "
f"every {AVG_EVERY} steps")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh,
averager=(averager if epoch >= avg_start elseNone))
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)# Weight averaging: fly the average of the late trajectory, not the last step.
last_diag = diag
bn_recal_done =0if averager.avg isNone:
print(f"[{area}] weight averaging skipped: no snapshots taken "
f"(exporting the last iterate)", flush=True)
avg_diag = last_diag
else:
averager.copy_to(model)
bn_recal_done = recalibrate_bn(model, scene, crop_xy, meta, rng, device,
n_caps, pos_per_chunk, BN_RECAL_BATCHES)
avg_diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
print(f"[{area}] averaged model: n_snapshots={averager.n} from epoch "
f"{avg_start +1} every {AVG_EVERY} steps, bn_recal_batches={bn_recal_done} "
f"xs_cos_same={avg_diag['xs_cos_same']} xs_cos_diff={avg_diag['xs_cos_diff']} "
f"wpv={avg_diag['wpv']} xsurvey_agree={avg_diag['xsurvey_agree']} "
f"clean_top1={avg_diag['clean_top1']} | last iterate: "
f"xs_cos_same={last_diag.get('xs_cos_same')} "
f"xs_cos_diff={last_diag.get('xs_cos_diff')} "
f"wpv={last_diag.get('wpv')} "
f"xsurvey_agree={last_diag.get('xsurvey_agree')} "
f"clean_top1={last_diag.get('clean_top1')}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk, "
"uniform weight average over the second half of training ""with BN recalibration (exported)"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": avg_diag.get("xs_cos_same"),"final_xs_cos_diff": avg_diag.get("xs_cos_diff"),"final_wpv": avg_diag.get("wpv"),"final_xsurvey_agree": avg_diag.get("xsurvey_agree"),"final_clean_top1": avg_diag.get("clean_top1"),"last_iterate_xs_cos_same": last_diag.get("xs_cos_same"),"last_iterate_wpv": last_diag.get("wpv"),"last_iterate_xsurvey_agree": last_diag.get("xsurvey_agree"),"last_iterate_clean_top1": last_diag.get("clean_top1"),"weight_averaging":{"kind":"uniform SWA/SWAD-style parameter average","start_epoch_1based": avg_start +1,"every_steps": AVG_EVERY,"n_snapshots": averager.n,"bn_recalibration_batches": BN_RECAL_BATCHES,"bn_recalibration_batches_used": bn_recal_done,"buffers":"re-measured, not averaged"},}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Sharper borrowed eyes: each member's MobileNetV2 trunk is replaced by an ImageNet-pretrained EfficientNet-B0 trunk (stem + all seven MBConv stages, Apache-2.0), read at the same two strides (112x14x14 and 320x7x7 at 224 px) f8ce7046
new best: 0.155 → 0.085
architecture
0.085
147 m 09 s
$3.43
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model recognises Berlin through a pair of borrowed eyes: image-recognition networks first trained on a million everyday photos, then taught the city. Every time we gave it better eyes, it got better at recognising Berlin in a photograph it had never seen. This experiment swaps in EfficientNet-B0, the sharpest pair that still fits the UAV's memory budget. It was trained to recognise things regardless of lighting and colour, and that is exactly what differs between two surveys of the same street.
What it cost
implementation agent
$1.41
design agent
$1.28
figure agent
$0.74
total
$3.43
by model — claude-opus-5-5 $3.43
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.155 to 0.085 — 0.070 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
On this ruler only the quality of the pretrained trunk has moved the held-out truedop_2024 photograph by a large step. From-scratch to MobileNetV3-Small took it from 10.75% to 49.5% usable (exp 12). Reading deeper gave 60.25% (exp 13), MixStyle 65.5% (exp 14), native 224 px input 74.25% (exp 15), and MobileNetV2 86.75% (exp 16, mission 0.155: false fix 2.25%, abstain 11%). Everything since then has been around the trunk and has not moved: exp 18's ring pooling scored 0.158, which is within noise of the champion. The three training photographs are saturated: in exp 16 and 18 bb_dop20, truedop_2022 and truedop_2023 are all 100% usable and 0% false fix at the same held-out viewpoints. So the remaining 0.155 is entirely survey gap, and most of it is abstention: 11% of 2024 frames fall under 0.3 committee confidence, while the confident answers are already 97.5% right (0.8675 of 0.89 coverage). What turns a 2024 abstention into a fix is the place feature landing closer to its prototype despite season, shadow and colour changes. That is the invariance the ImageNet trunk supplies, and it has grown with trunk strength at every step (MNv3-S 67.7% ImageNet top-1, MNv2 71.9%). EfficientNet-B0 is the strongest permissively licensed torchvision trunk that fits the gate: 77.7% top-1, squeeze-excite channel attention, and compound-scaled depth/width trained with heavy RandAugment-style photometric augmentation, i.e. invariances learned under exactly the nuisances that separate surveys. Its stride-16 and stride-32 outputs (112x14x14, 320x7x7 at 224 px) match the two levels the current place feature reads, so no other stage has to change. Size: features[0..7] is about 3.60M parameters, plus about 0.36M per member for lifts, prototypes and offset head, about 7.9M in total. That is about 31.6 MB, roughly 30.1 MiB fp32, against the 32 MiB gate, and BN folding at export lowers it slightly. The same arithmetic predicts exp 16's measured 17.39 MB for MobileNetV2 exactly. This is the trunk-family axis that every gain came from, not a variation of the refuted mechanisms (consistency losses, distillation, blending, decode changes).
Method
In model/model.py, each Member's trunk = torchvision efficientnet_b0 features[0..7] (stem + seven MBConv stages; the final 320->1280 1x1 conv features[8] is excluded), with IMAGENET1K_V1 weights loaded strict from a new baked file model/pretrained/effb0_features7.pt. The mid read level moves to after features[5] (112x14x14 at 224 px, stride 16) and the deep level to after features[7] (320x7x7, stride 32). Each level keeps its own 1x1 lift to 56 -> GAP -> concat to the same 112-d feature. MixStyle moves to the stride-equivalent points after features[2], [3] and [4] (24x56x56, 40x28x28, 80x14x14: stride 4/8/16, as before). Everything else is unchanged: the 128->224 in-graph resize, ImageNet normalisation, cosine-prototype head, committee min-mass confidence, pooling, offset, losses, augmentation, LR split (trunk at 0.1x) and epochs.
Expected outcome
Mission 0.155 -> about 0.09-0.12 on truedop_2024, driven mostly by abstentions becoming usable fixes: usable 86.75% -> about 89-92%, abstain 11% -> about 6-9%, false fix flat at about 2-2.5% (the committee's min-mass gate is unchanged and the confident answers are already 97.5% right). Training-capture diagnostics stay at about 0.000 (saturated). Exported fp32 ONNX about 30 MiB (under the 32 MiB gate); host latency proxy about 30-45 ms (under 250 ms). Training wall-clock rises by about 1.3-1.8x versus exp 16 because B0 has more FLOPs and SiLU/SE layers. REFUTATION: if 2024 usable does not rise above 87.5% (no change beyond the exp 16/18 noise band of about 0.5 pt), trunk strength in the ImageNet family has saturated as a lever. The next move is then the training data or signal (e.g. continuous-vantage or geometric jitter, or a cross-survey objective on the strong trunk), not a still bigger trunk.
Result
mission score = 0.085172 (previous best 0.155176) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 36–36 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
44.8 m
miss, this crop
0.98
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.08592% usablecov 0.94
Fits the aircraft?all deployment gates passed largest per-area model 30,951 KB (limit 4,096 KB) · single-frame inference 48.6 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,536 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 3 m 23 s · implement (Opus) 26 m 41 s · train 1 area 114 m 56 s · score 1 m 48 s · samples 5 s · publish 4 s · whole experiment 147 m 16 s
ts 2026-11-02T00:59:59 · commit f8ce70469b21 ·
parent 5eb62c306a21 · artifacts runs/20261101_223250_experiment19 ·
agent model — · took 147 m 09 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py403 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.EFFICIENTNET-B0 TRUNK (capture-holdout era, experiment 19): each member'sMobileNetV2 trunk is replaced by torchvision's EfficientNet-B0 stem + allseven MBConv stages (features[0..7], IMAGENET1K_V1, Apache-2.0 weights /BSD-3 code; the final 320->1280 1x1 conv features[8] is excluded), loadedstrict from the baked file model/pretrained/effb0_features7.pt (verbatimtorchvision tensors incl. BN running stats; nothing is downloaded).torchvision's default stochastic depth (0.2) is kept: active only in trainmode, identity in eval/export. The two read levels keep their strides: afterfeatures[5] (112x14x14 at 224 px, stride 16) and after features[7] (320x7x7,stride 32), each through its own 1x1 lift to 56 -> GAP -> concat to the same112-d feature. MixStyle moves to the stride-equivalent points: afterfeatures[2], [3], [4] (24x56x56, 40x28x28, 80x14x14). Head, committee,decode, losses and the 128->224 in-graph resize are unchanged; thepretrained stages are still fine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import efficientnet_b0
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =8# efficientnet_b0.features[:8] = stem + 7 MBConv stages -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[7]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =6# features[:6] -> 112x14x14 at 224 px, stride 16
TRUNK_MID_CH =112
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"effb0_features7.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(2,3,4)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 40x28x28, 80x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""EfficientNet-B0 features[0..7] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy. torchvision's default stochastic depth (0.2) is kept (train-mode only; identity in eval/export)."""
trunk = efficientnet_b0(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: shape-check both read levels on a dummy# 224 px forward, in eval mode, then restore the train/eval state.
was_training = trunk.training
trunk.eval()with torch.no_grad():
h = torch.zeros(1,3, INPUT_PX, INPUT_PX)
h_mid =Nonefor i, blk in enumerate(trunk):
h = blk(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h
trunk.train(was_training)
exp_mid =[1, TRUNK_MID_CH, INPUT_PX //16, INPUT_PX //16]
exp_out =[1, TRUNK_OUT_CH, INPUT_PX //32, INPUT_PX //32]assert list(h_mid.shape)== exp_mid, f"trunk mid shape {list(h_mid.shape)} != {exp_mid}"
assert list(h.shape)== exp_out, f"trunk out shape {list(h.shape)} != {exp_out}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained EfficientNet-B0 trunk read at two depths (112x14x14 after features[5], 320x7x7 after features[7], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 8 pretrained stages, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[2]/[3]/[4]. h_mid is taken after features[5].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 112, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py578 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.EFFICIENTNET-B0 TRUNK (experiment 19): each member's trunk is nowImageNet-pretrained EfficientNet-B0 features[0..7] (model.model, Apache-2.0weights / BSD-3 code, loaded strict from the bakedmodel/pretrained/effb0_features7.pt; torchvision's default stochastic depth0.2 kept, train mode only), read after features[5] (112x14x14) andfeatures[7] (320x7x7), each lifted to 56 and concatenated to 112; MixStyleruns after stages 2/3/4 (stride 4/8/16). The training loop, optimiser groups,schedule, augmentation and targets are unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: efficientnet_b0 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:efficientnet_b0 IMAGENET1K_V1 features[0..7] ""(torchvision, Apache-2.0 weights), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained EfficientNet-B0 features[0..7] trunk per member (0.1x LR), ""two-level 112->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""stages 2/3/4 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"efficientnet_b0 features[0..{TRUNK_BLOCKS -1}], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Ring pooling, actually trained: the place description keeps WHERE in the frame things are (centre / middle ring / edge) instead of one average over the whole frame (re-run of experiment 17, which crashed before training) ec350b82
worse than champion: 0.158 vs 0.155
architecture
0.158
94 m 09 s
$2.78
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now each navigator described a photo by tipping all its little observations into one bag: 'there are flat roofs, some trees, a wide road', without saying where in the picture they were. A new survey changes many of those observations (leaves, shadows, parked cars) but not the layout of the city. Now the navigator keeps three bags: what is right underneath, what is in a ring around that, and what is at the edge. That still works whichever way the UAV faces, and it describes the arrangement of the place. Experiment 17 tried exactly this but crashed on a typo before it trained, so this is the first real test.
What it cost
design agent
$1.05
implementation agent
$1.01
figure agent
$0.72
total
$2.78
by model — claude-opus-5-5 $2.78
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 0.158 it didn't beat the champion's 0.155, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Experiment 17's hypothesis was never tested. Its run died 30 s into training on a NameError in a log line (train.py used N_RINGS and RING_EDGES from model.model without importing them), so the scorer recorded 1e9 and the harness marked it REVERTED; that verdict says nothing about ring pooling. The reasoning stands unchanged on the current champion (exp 16: truedop_2024 mission 0.155, usable 86.75%, false fix 2.25%, abstain 11%; all three training photographs 100% usable / 0% false fix at the same held-out viewpoints, so the remaining loss is purely the survey gap). Every member's place feature is a global average (GAP) of its 14x14 and 7x7 trunk maps: an orderless bag that records WHICH roofs, canopy, road surface and shadows are in the 128 m frame but not WHERE. The bag's contents are what a new survey changes (season, sun angle, cars, construction); the spatial arrangement of blocks and streets around the point under the aircraft is what it preserves, and GAP throws that away. Concentric-ring pooling (separate means over the centre disc, middle annulus and outer ring) is just as invariant to heading about the frame centre as GAP, but keeps radial layout. Expectation: part of the 11% abstentions, which on this design are frames where a member or the 3x3 block splits belief between look-alike places with similar bags of texture, become confident correct fixes. Named risk, stated before the run: ring pooling is less tolerant of translation than GAP. The training lattice is 24 m and eval views stand 11-17 m off it, comparable to the 21 px radius of the centre disc, so the centre ring's content shifts substantially between the nearest training vantage and the eval view. If ring pooling fails, the train_capture_diagnostics separate the two explanations: if the training photographs also lose usable fixes at held-out viewpoints, the cause is viewpoint (translation) sensitivity; if they stay at ~100% while 2024 falls, radial layout is itself survey-specific at this resolution. Builds on the exp 12-16 lineage unchanged and reuses experiment 17's implementation verbatim plus the one missing import; no earlier-era experiment changed the pooling of a pretrained trunk.
Method
Copy experiment 17's model/model.py and model/train.py from runs/20261101_204833_experiment17/model_src/ (they are the exp 16 champion plus ring pooling) and add the missing import of N_RINGS and RING_EDGES to train.py's `from model.model import (...)`. Mechanism, unchanged from exp 17: in Member.embed the two `.mean(dim=(2,3))` GAP reductions are replaced by fixed, parameter-free concentric-ring pooling (3 rings at normalised radius thresholds 1/3 and 2/3, masks as registered buffers, one matmul per level). The place feature goes from 112-d to 336-d (56 lift channels x 3 rings x 2 levels); embed BatchNorm, cosine prototypes and offset head grow with EMBED_DIM. Nothing else changes.
Expected outcome
mission_score 0.155 -> ~0.10-0.13 on truedop_2024: usable_fix_rate 0.8675 -> ~0.89-0.91, mostly from abstentions (11% -> ~7-9%); false_fix_rate stays <= 0.025 (confidence gate unchanged); median error roughly flat (~32-35 m; the cell head sets resolution). train_capture_diagnostics stay ~0.000-0.01. Refuted if mission >= 0.155. Read the failure mode from the diagnostics as described in the hypothesis: training-photograph usable falling below ~98% means translation sensitivity (the next move would be continuous-vantage jitter in training, or softer/overlapping rings), training photographs at ~100% with 2024 down means radial layout is survey-specific and the orderless average was the more robust summary. Exported fp32 ONNX ~17.4 MB -> ~20-23 MB (gate 32 MiB); host latency ~22 ms, essentially unchanged; training wall time about exp 16's.
Result
mission score = 0.157671 (previous best 0.155176) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (0.157671 vs best 0.155176); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 35–35 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
54.5 m
miss, this crop
0.94
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.15886% usablecov 0.88
Fits the aircraft?all deployment gates passed largest per-area model 22,194 KB (limit 4,096 KB) · single-frame inference 21.7 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
5,005 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 04 s · implement (Opus) 2 m 42 s · train 1 area 88 m 12 s · score 54 s · samples 4 s · publish 3 s · whole experiment 94 m 15 s
ts 2026-11-01T22:31:48 · commit ec350b82b5b0 ·
parent ec350b82b5b0 · artifacts runs/20261101_205738_experiment18 ·
agent model — · took 94 m 09 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py419 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw pooled feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.RING POOLING (capture-holdout era, experiment 17): the two global averagepoolings in Member.embed() are replaced by fixed, parameter-free,concentric-ring pooling. For each read level (14x14 mid, 7x7 deep), threering masks over the grid are registered as buffers (bake into the ONNX asconstants): with cell centre (i+0.5, j+0.5), frame centre (H/2, W/2) andradius r normalised by H/2, ring 0 = r < 1/3 (what is under the aircraft),ring 1 = 1/3 <= r < 2/3, ring 2 = r >= 2/3 (corners included). Each mask isnormalised to sum 1, so each ring's output is the mean of the lifted featureover that ring (one MatMul). The pooling is invariant to rotation about theframe centre (masks are symmetric under 90-degree rotation) yet keeps theradial layout that GAP threw away. 56 x 3 rings x 2 levels = 336-d placefeature (was 112); embed_bn, prototypes and offset head grow with EMBED_DIM.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v2
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
LIFT_DIM =56# per-level lift width
N_RINGS =3# concentric pooling rings per read level (exp 17)
RING_EDGES =(1/3,2/3)# normalised-radius ring thresholds
EMBED_DIM =2* LIFT_DIM * N_RINGS # 56 x 3 rings x 2 levels = 336 place feature / prototype / offset-head width
TRUNK_BLOCKS =18# mobilenet_v2.features[:18] = stem + 17 IR blocks -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[17]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =14# features[:14] -> 96x14x14 at 224 px, stride 16
TRUNK_MID_CH =96
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv2_features17.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(3,6,10)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 32x28x28, 64x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV2 features[0..17] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v2(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: the last block must emit TRUNK_OUT_CH.
last_ch = trunk[-1].conv[-1].num_features # final BN of the last InvertedResidual
mid_ch = trunk[TRUNK_MID_BLOCKS -1].conv[-1].num_features
assert last_ch == TRUNK_OUT_CH, f"trunk out channels {last_ch} != {TRUNK_OUT_CH}"
assert mid_ch == TRUNK_MID_CH, f"trunk mid channels {mid_ch} != {TRUNK_MID_CH}"
return trunk
def ring_masks(hw: int)-> torch.Tensor:"""float32 [N_RINGS, hw*hw] concentric-ring pooling masks, each row summing to 1. Flatten order is row-major (H then W), matching tensor.flatten(2)."""
c = hw /2.0
i = np.arange(hw)[:,None]+0.5
j = np.arange(hw)[None,:]+0.5
r =(np.sqrt((i - c)**2+(j - c)**2)/(hw /2.0)).reshape(-1)
edges =(0.0,)+ tuple(RING_EDGES)+(np.inf,)
rows =[]for k in range(N_RINGS):
m =((r >= edges[k])&(r < edges[k +1])).astype(np.float32)assert m.sum()>=1, f"ring {k} empty at {hw}x{hw}"
rows.append(m / m.sum())return torch.tensor(np.stack(rows), dtype=torch.float32)class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV2 trunk read at two depths (96x14x14 after features[13], 320x7x7 after features[17], on the 224 px resized input) -> one 1x1 lift per level -> concentric-ring pooling (3 rings) -> concat (336-d) -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 18 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))# Fixed ring-pooling masks (buffers, not parameters): bake into the ONNX.self.register_buffer("ring_mid", ring_masks(MID_HW))self.register_buffer("ring_deep", ring_masks(DEEP_HW))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]@staticmethod
def _ring_pool(h, masks):"""h [B, C, H, W], masks [K, H*W] -> [B, C*K] per-ring means."""
B, C, H, W = h.shape
assert H * W == masks.shape[1], f"map {H}x{W} does not match ring masks {tuple(masks.shape)}"
return torch.matmul(h.flatten(2), masks.t()).flatten(1)def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw ring-pooled feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[3]/[6]/[10]. h_mid is taken after features[13].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 96, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self._ring_pool(self.lift_mid(h_mid),self.ring_mid),self._ring_pool(self.lift_deep(h_deep),self.ring_deep)], dim=1)# [B, 336]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py573 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, N_RINGS,
PRETRAINED_TRUNK_PATH, RING_EDGES, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: mobilenet_v2 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW}, ring-pooled x{N_RINGS} -> {EMBED_DIM}-d, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v2 IMAGENET1K_V1 features[0..17] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV2 features[0..17] trunk per member (0.1x LR), ""two-level 96->56 (14x14) + 320->56 (7x7), concentric-ring pooling ""(3 rings) -> 336-d place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""blocks 3/6/10 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v2 features[0..17], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}), "
f"concentric-ring pooling ({N_RINGS} rings) -> {EMBED_DIM}-d place feature"),"embed_dim": EMBED_DIM,"n_rings": N_RINGS,"ring_edges": list(RING_EDGES),"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Ring pooling: the place description keeps WHERE in the frame things are (centre / middle ring / edge), not one average over the whole 128 m frame aba2697a
training or scoring crashed — no result
architecture
gated fail
8 m 54 s
$3.25
gated fail
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now each navigator described a photo by tipping all its little observations into one bag - 'there are flat roofs, some trees, a wide road' - without saying where in the picture they were. A new survey changes many of those observations (leaves, shadows, parked cars) but not the layout of the city. Now the navigator keeps three bags instead of one: what is right underneath, what is in a ring around that, and what is at the edge. That still works whichever way the UAV is facing, but it describes the arrangement of the place, which stays the same from one photograph to the next.
What it cost
figure agent
$1.26
design agent
$1.18
implementation agent
$0.81
total
$3.25
by model — claude-opus-5-5 $3.25
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it failed the gate
This design never produced a score at all: training or scoring failed outright (usually a bug in the proposed model or training code, or a model that couldn't be exported and scored). With no numbers to judge it on, it counts as a failure and was rolled back.
Hypothesis
Experiments 12-16 took held-out truedop_2024 from 10.75% to 86.75% usable (exp 16: mission 0.155, usable 0.8675, false fix 0.0225, abstain 0.11) by improving only the trunk, and the three training photographs now sit at 100% usable / 0% false fix on the same held-out viewpoints, so what is left is purely the survey gap. One stage has never been questioned in the whole era: every member's place feature is a GLOBAL AVERAGE (GAP) of its 14x14 and 7x7 trunk maps. GAP is an orderless bag of local features: it says WHICH roofs, trees, road surfaces and shadows are in the 128 m frame, but not where. That is exactly the part of the description that a new survey corrupts (season changes canopy, sun angle changes shadows, cars and construction differ), while the part a new survey preserves - the spatial arrangement of buildings, streets and blocks relative to the point the aircraft is over - is thrown away. GAP was the natural choice because frames arrive at arbitrary headings and an average is rotation-invariant; but rotation invariance does not need orderlessness. Concentric-ring pooling (mean over the centre disc, the middle annulus and the outer ring, separately, then concatenated) is equally invariant to heading about the frame centre and keeps the radial layout: 'a courtyard under me, a block of flat roofs around it, a wide road at the edge' instead of 'some courtyard, some roofs, some road'. The frame centre is by construction the labelled position (training views are rotated about the crop centre, eval error is measured at the crop centre), so the centre ring in particular carries the most position-specific content, and neighbouring cells that share the same bag of textures but differ in arrangement become separable. I expect this to (a) convert part of the 11% abstentions, which on this design are frames where the two members or the 3x3 block split their belief between look-alike places, into confident correct fixes, and (b) not raise false fixes, since the confidence gate is unchanged. Builds on the experiment 12-16 lineage (trunk, committee, cosine head and MixStyle all kept as-is); no earlier-era experiment changed the pooling of a pretrained trunk, so this is new on any ruler.
Method
In model/model.py Member.embed only: replace the two GAP reductions (.mean(dim=(2,3))) with fixed, parameter-free, rotation-invariant concentric-ring pooling. For each read level (mid 14x14 after features[13], deep 7x7 after features[17], both at the 224 px input), three fixed ring masks over the grid are registered as buffers: cell centre (i+0.5, j+0.5), frame centre (H/2, W/2), radius r normalised by the inscribed half-width H/2; ring 0 = r < 1/3, ring 1 = 1/3 <= r < 2/3, ring 2 = r >= 2/3 (includes the corners). Each mask is normalised to sum 1, so ring k's output is the mean of the lifted feature over that ring. The lifted 56-channel map of each level becomes 56 x 3 = 168 numbers; the place feature f is the concatenation of both levels, 336-d (was 112). EMBED_DIM becomes 336; the BatchNorm1d, cosine-prototype matrix (n_cells x 336) and offset head grow accordingly. Nothing else changes: trunk, lifts, MixStyle, 128->224 resize, committee, cosine scale/margin, block decode, confidence gate, losses, augmentation, epochs.
Expected outcome
mission_score 0.155 -> ~0.10-0.12 on truedop_2024: usable_fix_rate 0.8675 -> ~0.90 (abstentions 11% -> ~8%), false_fix_rate stays <= 0.025, median error roughly flat or slightly lower (~30-34 m; the cell head, not the pooling, sets the resolution). train_capture_diagnostics stay at ~0.000 (100% usable). Training-time top1 should rise faster per epoch than exp 16 (0.894 at epoch 8). Refutation: if usable on 2024 does not rise (or falls) while training-capture top1 rises, the radial layout is itself survey-specific at this resolution (e.g. shadows displace edges) and the orderless average was the more survey-robust summary - which would be informative: it points at the trunk/training signal, not the pooling, as the remaining lever. Model size ~17.4 MB -> ~23 MB fp32 (prototypes 2970x336 per member), well under the 32 MiB gate; host latency essentially unchanged (~22 ms).
Result
mission score = 1000000000.0 (previous best 0.155176) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1000000000.0 vs best 0.155176); change discarded
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
No per-area results recorded for this run.
Fits the aircraft?all deployment gates passed largest per-area model — (limit 4,096 KB) · single-frame inference — on one CPU thread (proxy limit 250 ms)
Where this experiment's time went: design (Opus) 2 m 59 s · implement (Opus) 1 m 36 s · train 4 m 00 s · samples 4 s · publish 1 s · whole experiment 8 m 57 s
ts 2026-11-01T20:57:27 · commit aba2697a2e4d ·
parent aba2697a2e4d · artifacts runs/20261101_204833_experiment17 ·
agent model — · took 8 m 54 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py419 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw pooled feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.RING POOLING (capture-holdout era, experiment 17): the two global averagepoolings in Member.embed() are replaced by fixed, parameter-free,concentric-ring pooling. For each read level (14x14 mid, 7x7 deep), threering masks over the grid are registered as buffers (bake into the ONNX asconstants): with cell centre (i+0.5, j+0.5), frame centre (H/2, W/2) andradius r normalised by H/2, ring 0 = r < 1/3 (what is under the aircraft),ring 1 = 1/3 <= r < 2/3, ring 2 = r >= 2/3 (corners included). Each mask isnormalised to sum 1, so each ring's output is the mean of the lifted featureover that ring (one MatMul). The pooling is invariant to rotation about theframe centre (masks are symmetric under 90-degree rotation) yet keeps theradial layout that GAP threw away. 56 x 3 rings x 2 levels = 336-d placefeature (was 112); embed_bn, prototypes and offset head grow with EMBED_DIM.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v2
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
LIFT_DIM =56# per-level lift width
N_RINGS =3# concentric pooling rings per read level (exp 17)
RING_EDGES =(1/3,2/3)# normalised-radius ring thresholds
EMBED_DIM =2* LIFT_DIM * N_RINGS # 56 x 3 rings x 2 levels = 336 place feature / prototype / offset-head width
TRUNK_BLOCKS =18# mobilenet_v2.features[:18] = stem + 17 IR blocks -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[17]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =14# features[:14] -> 96x14x14 at 224 px, stride 16
TRUNK_MID_CH =96
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv2_features17.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(3,6,10)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 32x28x28, 64x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV2 features[0..17] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v2(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: the last block must emit TRUNK_OUT_CH.
last_ch = trunk[-1].conv[-1].num_features # final BN of the last InvertedResidual
mid_ch = trunk[TRUNK_MID_BLOCKS -1].conv[-1].num_features
assert last_ch == TRUNK_OUT_CH, f"trunk out channels {last_ch} != {TRUNK_OUT_CH}"
assert mid_ch == TRUNK_MID_CH, f"trunk mid channels {mid_ch} != {TRUNK_MID_CH}"
return trunk
def ring_masks(hw: int)-> torch.Tensor:"""float32 [N_RINGS, hw*hw] concentric-ring pooling masks, each row summing to 1. Flatten order is row-major (H then W), matching tensor.flatten(2)."""
c = hw /2.0
i = np.arange(hw)[:,None]+0.5
j = np.arange(hw)[None,:]+0.5
r =(np.sqrt((i - c)**2+(j - c)**2)/(hw /2.0)).reshape(-1)
edges =(0.0,)+ tuple(RING_EDGES)+(np.inf,)
rows =[]for k in range(N_RINGS):
m =((r >= edges[k])&(r < edges[k +1])).astype(np.float32)assert m.sum()>=1, f"ring {k} empty at {hw}x{hw}"
rows.append(m / m.sum())return torch.tensor(np.stack(rows), dtype=torch.float32)class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV2 trunk read at two depths (96x14x14 after features[13], 320x7x7 after features[17], on the 224 px resized input) -> one 1x1 lift per level -> concentric-ring pooling (3 rings) -> concat (336-d) -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 18 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))# Fixed ring-pooling masks (buffers, not parameters): bake into the ONNX.self.register_buffer("ring_mid", ring_masks(MID_HW))self.register_buffer("ring_deep", ring_masks(DEEP_HW))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]@staticmethod
def _ring_pool(h, masks):"""h [B, C, H, W], masks [K, H*W] -> [B, C*K] per-ring means."""
B, C, H, W = h.shape
assert H * W == masks.shape[1], f"map {H}x{W} does not match ring masks {tuple(masks.shape)}"
return torch.matmul(h.flatten(2), masks.t()).flatten(1)def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw ring-pooled feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[3]/[6]/[10]. h_mid is taken after features[13].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 96, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self._ring_pool(self.lift_mid(h_mid),self.ring_mid),self._ring_pool(self.lift_deep(h_deep),self.ring_deep)], dim=1)# [B, 336]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py572 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: mobilenet_v2 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW}, ring-pooled x{N_RINGS} -> {EMBED_DIM}-d, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v2 IMAGENET1K_V1 features[0..17] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV2 features[0..17] trunk per member (0.1x LR), ""two-level 96->56 (14x14) + 320->56 (7x7), concentric-ring pooling ""(3 rings) -> 336-d place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""blocks 3/6/10 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v2 features[0..17], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}), "
f"concentric-ring pooling ({N_RINGS} rings) -> {EMBED_DIM}-d place feature"),"embed_dim": EMBED_DIM,"n_rings": N_RINGS,"ring_edges": list(RING_EDGES),"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Better borrowed eyes: each member's MobileNetV3-Small trunk is replaced by an ImageNet-pretrained MobileNetV2 trunk (stronger, wider; BSD-3), read at the same two depths (14x14 and 7x7 at 224 px) a4393f88
new best: 0.293 → 0.155
architecture
0.155
94 m 20 s
$3.27
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model recognises places using a pair of 'eyes' borrowed from a network that learned to see from a million everyday photos. Each time we gave those borrowed eyes a bigger role, the model got better at recognising Berlin in a photograph it had never seen. This time we swap the smallest such pair of eyes for a sharper, wider one from the same family, so that the same street looks more like itself across different surveys, seasons and shadows, and the model abstains less often.
What it cost
design agent
$1.29
implementation agent
$1.09
figure agent
$0.90
total
$3.27
by model — claude-opus-5-5 $3.27
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.293 to 0.155 — 0.138 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
Every gain on the held-out 2024 photograph in this era came from the pretrained trunk, and from nothing else: swapping the from-scratch trunk for ImageNet MobileNetV3-Small took 2024 from 10.75% to 49.5% usable (exp 12), reading two blocks deeper took it to 60.25% (exp 13), style-mixing inside it to 65.5% (exp 14), and showing it the frame at its native 224 px to 74.25% (exp 15, mission 0.293, false fix 3.5%, abstain 22.25%). Eleven experiments that changed the heads, losses, decode and training signal around a from-scratch trunk never left a 6-14% band. The training photographs are already at 98-99% usable at the same held-out viewpoints, so what is missing is not memory but the invariance of the description of a place to a change of survey: exp 15's survey diagnostic shows the within-place variance fraction flat at ~0.235 from epoch 1 to epoch 8 and cross-survey same-place cosine flat at ~0.67. Fine-tuning does not create that invariance; the pretrained features bring it with them, and the network has only ever been given the weakest ImageNet trunk in torchvision (MobileNetV3-Small, 67.7% top-1). MobileNetV2 (71.9% top-1, ~3x wider at the read levels: 96 and 320 channels vs 48 and 96) is the next trunk up and is already cached locally as torchvision IMAGENET1K_V1. The remaining loss is mostly ABSTENTION (22.25% vs 3.5% false fix): the committee's confidence (min member mass on the consensus 3x3 block) falls under 0.3 when a foreign photograph's description lands between prototypes. A trunk whose description of a place moves less between surveys puts more of each member's mass on the right block, converting abstentions into usable fixes. Builds directly on experiments 12-15 (this is exp 12's swap again, one rung higher); everything else in the exp 15 champion is held fixed so the difference is the trunk.
Method
In model/model.py, each committee Member's trunk becomes torchvision mobilenet_v2 features[0..17] (stem + all 17 inverted-residual blocks, final 1280-channel 1x1 conv excluded), ImageNet IMAGENET1K_V1 weights baked into a new file model/pretrained/mnv2_features17.pt and loaded strict, fine-tuned at the same 0.1x LR. The place feature reads the same two levels by stride: after features[13] (96 ch, 14x14 at 224 px, stride 16, replacing MNV3-S's 48ch level) and after features[17] (320 ch, 7x7, stride 32, replacing MNV3-S's 96ch level), each through its own 1x1 lift to 56 -> GAP -> concat to the same 112-d feature. MixStyle moves to the stride-equivalent points of the new trunk (after features[3], [6], [10]: stride 4/8/16). Head, committee, decode, losses, augmentation, schedule, epochs and the 128->224 in-graph resize are unchanged. CUDA-only bf16 autocast on the member forward passes is added to keep wall time near the current round (infrastructure, not part of the hypothesis).
Expected outcome
mission_score 0.293 -> ~0.20-0.24 on truedop_2024: usable_fix_rate 74.25% -> ~79-83%, mainly by converting abstentions (22.25% -> ~14-17%), false_fix_rate staying at or below ~4%. Training-capture diagnostics stay at 0.01-0.03. Survey diagnostic: within-place variance fraction (wpv) below exp 15's ~0.235 and xs_cos_same above ~0.67 — if 2024 improves while wpv does not move, the gain came from capacity/memory rather than invariance, which the conclusion must say. Refuted if mission >= 0.293. Exported fp32 ONNX ~16-19 MB (gate 32 MiB); host latency ~25-40 ms (gate 250 ms). Training wall time expected ~1.5-2x exp 15's 35 min.
Result
mission score = 0.155176 (previous best 0.292699) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 34–34 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
54.1 m
miss, this crop
0.88
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.15587% usablecov 0.89
Fits the aircraft?all deployment gates passed largest per-area model 16,978 KB (limit 4,096 KB) · single-frame inference 21.7 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
4,986 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 53 s · implement (Opus) 1 m 56 s · train 1 area 88 m 18 s · score 52 s · samples 5 s · publish 4 s · whole experiment 94 m 26 s
ts 2026-11-01T20:48:01 · commit a4393f88370f ·
parent ad6774b489b2 · artifacts runs/20261101_191341_experiment16 ·
agent model — · took 94 m 20 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py376 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.MOBILENETV2 TRUNK (capture-holdout era, experiment 16): each member'sMobileNetV3-Small trunk is replaced by torchvision's MobileNetV2 stem + all 17inverted-residual blocks (features[0..17], IMAGENET1K_V1, BSD-3; the final1280-channel 1x1 conv features[18] is excluded), loaded strict from the bakedfile model/pretrained/mnv2_features17.pt (verbatim torchvision tensors incl.BN running stats; nothing is downloaded). The two read levels keep theirstrides: after features[13] (96x14x14 at 224 px, stride 16) and afterfeatures[17] (320x7x7, stride 32), each through its own 1x1 lift to 56 ->GAP -> concat to the same 112-d feature. MixStyle moves to thestride-equivalent points of the new trunk: after features[3], [6], [10](24x56x56, 32x28x28, 64x14x14). Head, committee, decode, losses and the128->224 in-graph resize are unchanged; the pretrained blocks are stillfine-tuned at TRUNK_LR_MULT.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v2
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =18# mobilenet_v2.features[:18] = stem + 17 IR blocks -> 320x7x7 at 224 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =320# deep level (after features[17]): 320x7x7 at 224 px, stride 32
TRUNK_MID_BLOCKS =14# features[:14] -> 96x14x14 at 224 px, stride 16
TRUNK_MID_CH =96
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv2_features17.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(3,6,10)# features[i] after which MixStyle runs: stride 4/8/16 (24x56x56, 32x28x28, 64x14x14)
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV2 features[0..17] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v2(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)# Fail loudly on a wrong slice: the last block must emit TRUNK_OUT_CH.
last_ch = trunk[-1].conv[-1].num_features # final BN of the last InvertedResidual
mid_ch = trunk[TRUNK_MID_BLOCKS -1].conv[-1].num_features
assert last_ch == TRUNK_OUT_CH, f"trunk out channels {last_ch} != {TRUNK_OUT_CH}"
assert mid_ch == TRUNK_MID_CH, f"trunk mid channels {mid_ch} != {TRUNK_MID_CH}"
return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV2 trunk read at two depths (96x14x14 after features[13], 320x7x7 after features[17], on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 18 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[3]/[6]/[10]. h_mid is taken after features[13].
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 96, 14, 14]
h_deep = h # [B, 320, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py569 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.MOBILENETV2 TRUNK (experiment 16): each member's trunk is nowImageNet-pretrained MobileNetV2 features[0..17] (model.model, BSD-3, loadedstrict from the baked model/pretrained/mnv2_features17.pt), read afterfeatures[13] (96x14x14) and features[17] (320x7x7), each lifted to 56 andconcatenated to 112; MixStyle runs after blocks 3/6/10 (stride 4/8/16). OnCUDA only, the member forward pass runs under bf16 autocast (no GradScaler)and its outputs are cast back to fp32 before targets/loss/statistics; onMPS/CPU nothing changes, and survey_diag and the export stay fp32.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)with torch.autocast(device_type="cuda", dtype=torch.bfloat16,
enabled=(device =="cuda")):
cos_k, off_k = member(xb_k)
cos_k = cos_k.float(); off_k = off_k.float()
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
amp_desc ="bf16 autocast on member forward (cuda only)"if device =="cuda"else"off"
print(f"[{area}] trunk: mobilenet_v2 features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only), "
f"amp={amp_desc}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v2 IMAGENET1K_V1 features[0..17] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV2 features[0..17] trunk per member (0.1x LR), ""two-level 96->56 (14x14) + 320->56 (7x7) -> 112 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""blocks 3/6/10 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v2 features[0..17], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"amp": amp_desc,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Look at Berlin at the borrowed eyes' native scale: the 128 px frame is resized in-graph to 224 px (ImageNet's training resolution) before the pretrained trunk, so its 8x8/4x4 place maps become 14x14/7x7 0335e1ef
new best: 0.395 → 0.293
architecture
0.293
40 m 51 s
$3.34
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
We borrowed a pair of eyes trained on a million everyday photos, but we have been showing them Berlin through a keyhole: our camera frames are about half the size of the pictures those eyes learned on, so every roof and street looks shrunken and blurry to them. This experiment simply enlarges each frame to the size the eyes are used to before they look. Nothing new is learned or added — the same eyes just get to see the city at the scale where they are good at telling what is permanent (the street grid, the buildings) from what changes between photo flights (cars, shadows, colours).
What it cost
figure agent
$1.39
design agent
$1.11
implementation agent
$0.85
total
$3.34
by model — claude-opus-5-5 $3.34
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.395 to 0.293 — 0.103 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
Builds directly on experiments 12-14, the only designs on this ruler that moved the held-out photograph: swapping in an ImageNet-pretrained trunk took truedop_2024 from 10.75% to 49.5% usable (exp 12), reading it two blocks deeper took it to 60.25% (exp 13), and mixing survey style inside it took it to 65.5% (exp 14, usable 0.655 / false fix 0.05 / abstain 0.295, mission 0.395). Every gain came from the pretrained trunk's invariance doing more of the work. Meanwhile the training photographs sit at 95.5-97% usable at the same held-out viewpoints (train_capture_diagnostics 0.058 / 0.033 / 0.043) and the clean survey diagnostic has stopped moving (xs_cos_same 0.657 -> 0.656, wpv 0.236 -> 0.240, xsurvey_agree 0.74 -> 0.72 from exp 13 to 14): MixStyle helped the score without making the embedding of a place any more survey-independent, so the remaining 30-point gap is the trunk not yet describing a place in survey-free terms. One thing about how the trunk is used has never been questioned: SCALE. MobileNetV3-Small learned its invariant features on 224 px images, but we feed it 128 px, so every filter sees structure at 0.57x the size it was trained on, its stem throws away half the resolution at the first layer (2 m per feature after the stem), and the deep 96-channel level we read is a 4x4 map — 16 samples of 32 m each, averaged into the place feature. Train/test resolution mismatch is a known, large effect on pretrained-feature transfer (Touvron et al., FixRes, NeurIPS 2019), and here it is compounded by the GAP over a tiny map: a single car, shadow or construction patch that differs between surveys owns 1/16 of the deep descriptor. Resizing the frame to 224 px in-graph changes no weights and adds no parameters: the same pretrained filters see roofs, street edges and tree crowns at the scale their invariance was learned at, and the place feature averages 196 (mid) and 49 (deep) cells instead of 64 and 16, diluting survey-specific transients. This is the input-scale/decode-resolution family, absent from all 97 experiments in either database.
Method
ONE change, in model/model.py Member.embed(): the [0,1] 128x128 input is bilinearly resized to INPUT_PX = 224 (a fixed output size, in the exported graph) before ImageNet normalisation and the trunk. Trunk, lifts, MixStyle insertion points, cosine-prototype head, committee decode, losses, augmentation, schedule, epochs and the ONNX I/O contract are all unchanged. The trunk's maps at the two read levels become 48x14x14 (after block 8) and 96x7x7 (after block 10); GAP makes the place feature shape-agnostic, so EMBED_DIM stays 112 and the exported weights are byte-for-byte the same size.
Expected outcome
truedop_2024 usable 0.655 -> 0.70-0.76, false fix held at or below 0.05 (the min-over-members gate is untouched), abstain falling correspondingly: mission 0.395 -> ~0.29-0.34. Training-capture diagnostics stay near 0.03-0.06 (they are already saturated), so the memorisation-vs-ground gap should narrow by ~5-10 usable points. Survey diagnostic: xs_cos_same up from 0.656 toward 0.70+, wpv down from 0.24, xsurvey_agree up from 0.72-0.73 — if the score improves while these do not move, the gain came from finer spatial averaging rather than better invariance, which is still informative. Falsifier: if 2024 usable stays at or below 0.66 while the training captures hold, input scale is not the bottleneck and the next move is more/other pretrained capacity rather than resolution. Cost: ~3x trunk FLOPs; host latency proxy ~4 ms -> ~12-15 ms (gate 250 ms); model bytes unchanged (7.45 MB fp32); training on the g6 ~17 min -> ~40-50 min, an acceptable round. On-chip latency roughly triples too; at the 1-10 s fix schedule that is a cost worth measuring, not a blocker.
Result
mission score = 0.292699 (previous best 0.395212) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 39–39 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
50.8 m
miss, this crop
0.66
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.29374% usablecov 0.78
Fits the aircraft?all deployment gates passed largest per-area model 7,279 KB (limit 4,096 KB) · single-frame inference 9.0 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
1,850 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 13 s · implement (Opus) 1 m 37 s · train 1 area 36 m 15 s · score 26 s · samples 4 s · publish 3 s · whole experiment 40 m 57 s
ts 2026-11-01T19:13:08 · commit 0335e1efeb74 ·
parent 98cf22d88209 · artifacts runs/20261101_183217_experiment15 ·
agent model — · took 40 m 51 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py356 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.NATIVE-SCALE INPUT (capture-holdout era, experiment 15): the 128 px frame isresized in-graph (bilinear, fixed output size) to INPUT_PX = 224, MobileNetV3'sImageNet training resolution, as the first operation of Member.embed(), beforeImageNet normalisation. The pretrained filters therefore see structure at thescale their invariance was learned at (FixRes-style train/test resolutionmatching), and the two read levels become 48x14x14 (after block 8) and 96x7x7(after block 10). No new parameters; GAP keeps the place feature at 112-d; theexternal input contract stays 1x3x128x128.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v3_small
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =11# mobilenet_v3_small.features[:11] = stem + 10 IR blocks -> 96x4x4 at 128 px
INPUT_PX =224# frame is bilinearly resized to this before the pretrained trunk (ImageNet training resolution)
TRUNK_OUT_CH =96# deep level (after block 10)
TRUNK_MID_BLOCKS =9# features[:9] -> 48x8x8 at 128 px (the exp-12 level)
TRUNK_MID_CH =48
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv3s_features10.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(1,3,6)# indices into trunk (features[i]) after which MixStyle runs
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV3-Small features[0..10] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v3_small(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV3-Small trunk read at two depths (14x14 after block 8, 7x7 after block 10, on the 224 px resized input) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 11 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""# Native-scale input: fixed-size bilinear upsample 128 -> INPUT_PX# (plain ONNX Resize, no antialias), before ImageNet normalisation.
x = F.interpolate(x, size=(INPUT_PX, INPUT_PX), mode="bilinear", align_corners=False)
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[1]/[3]/[6]. h_mid is taken after block 8 as before.
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 48, 14, 14]
h_deep = h # [B, 96, 7, 7]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py554 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4 at 128 px; 14x14/7x7 since exp 15), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.NATIVE-SCALE INPUT (experiment 15): crops are still cut and augmented atCROP_PX = 128; the bilinear resize to INPUT_PX = 224 (MobileNetV3's ImageNetresolution) lives inside model.model.Member.embed, so training views,survey_diag and the ONNX export all see it identically. The two read levelsbecome 48x14x14 and 96x7x7.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, INPUT_PX, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
MID_HW = INPUT_PX //16# mid read level spatial size (14 at 224 px)
DEEP_HW = INPUT_PX //32# deep read level spatial size (7 at 224 px)
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
cos_k, off_k = member(xb_k)
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
print(f"[{area}] trunk: mobilenet_v3_small features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, input {CROP_PX}->{INPUT_PX} px bilinear (in-graph), "
f"lifts {TRUNK_MID_CH}->{LIFT_DIM} @{MID_HW}x{MID_HW} + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @{DEEP_HW}x{DEEP_HW} -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only)", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..10] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV3-Small features[0..10] trunk per member (0.1x LR), ""two-level 8x8 + 4x4 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""blocks 1/3/6 (train only), "
f"frame resized in-graph {CROP_PX}->{INPUT_PX} px before the trunk"),"input_px": INPUT_PX,"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v3_small features[0..10], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} ({MID_HW}x{MID_HW}) + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} ({DEEP_HW}x{DEEP_HW}) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Cross-survey style mixing inside the borrowed eyes: during training, the early trunk layers' per-channel feature statistics (the 'look' of a photograph) are randomly blended with another view's from a different survey, so the place description cannot key on any one survey's style 3c1f3700
new best: 0.435 → 0.395
augmentation
0.395
26 m 13 s
$1.81
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Each of the three aerial surveys of Berlin has its own 'look': one is a lush summer, one bare winter trees, one early spring, each processed by a different camera and lab. The model's early layers notice that look as overall averages, a bit like a photo filter. While training, we now randomly swap a blend of another survey's filter onto each picture inside the model, keeping the streets and rooftops exactly where they are. The model sees every street in many in-between styles, so a fourth survey with a style it has never seen looks like more of the same, and it has to recognise the place itself.
What it cost
design agent
$0.97
implementation agent
$0.84
total
$1.81
by model — claude-opus-5-5 $1.81
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.435 to 0.395 — 0.040 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
Builds on experiments 12-13 (pretrained trunk, kept) and experiment 4 (pixel-level nuisance randomisation, kept), and is the feature-level successor to experiment 6 (pixel blending of surveys, reverted). Experiments 12->13 moved held-out truedop_2024 usable from 10.75% to 49.5% to 60.25% (false fix 7.0 -> 5.5 -> 3.75%) purely by giving the place feature more of the ImageNet trunk's invariance: the stage that decides what a place looks like is where transfer to a new survey is won. But the trunk still encodes survey: exp 13's clean survey diagnostic on TRAINING positions ends at xs_cos_same 0.657, within-place variance fraction 0.235 and cross-survey argmax agreement only ~0.74 between the three training photographs, while the training photographs themselves score 0.013-0.038 (97-99% usable) and the held-out one 0.435 with 36% abstention. So a quarter of the embedding's variance is still 'which survey', and on a fourth survey that shifts the embedding off its tile prototype, which the committee min-mass gate turns into an abstention (coverage 64%, but 94% of answered frames correct). The answer is not more decode gating; it is a trunk whose mid-level features carry less survey style. Pixel-level augmentation (exp 4) can only perturb global exposure/colour/blur; the survey differences that remain (season, canopy, shadow length, texture rendering, sharpening/compression of each orthophoto pipeline) live in the per-channel mean and std of early CNN feature maps, which is exactly what style-transfer work identifies as 'style' (AdaIN). MixStyle (Zhou et al., ICLR 2021) regularises a pretrained CNN against unseen domains by replacing, at random during training, each instance's early-layer channel statistics with a convex mix of its own and another instance's. Our batches are survey-mixed by construction (paired-position interleave), so the partner is a different survey's photograph about two-thirds of the time: every place is shown wearing styles interpolated between the three surveys, which is the continuum experiment 6 tried to create in pixel space but with the content (spatial layout of the feature map) left intact rather than ghosted. A fourth survey's style is far more likely to fall inside that continuum than on one of three points.
Method
Training-only change in model/model.py: add a parameter-free MixStyle module and apply it inside Member.embed() after MobileNetV3-Small trunk blocks features[1], features[3] and features[6] (outputs 16x32x32, 24x16x16, 40x8x8 at 128 px input: the early/mid levels where channel statistics encode style, not the deep 96x4x4 level that carries layout). In training mode with probability p=0.5 per batch per insertion point: per-instance per-channel mean mu and std sig over H,W (sig = sqrt(var+1e-6), both detached), normalise x_hat=(x-mu)/sig, draw lambda ~ Beta(0.1,0.1) per instance, pick partner by a random permutation of the batch, mix mu_mix = lambda*mu + (1-lambda)*mu[perm], sig_mix likewise, output x_hat*sig_mix + mu_mix. In eval mode (and therefore in the ONNX export and the survey diagnostic) it is the identity, so the deployed graph is unchanged. Each committee member draws its own MixStyle randomness (they already get independent augment_views draws). Nothing else changes: same trunk, lifts, cosine head, committee decode, losses, augmentation, LR groups, epochs.
Expected outcome
truedop_2024 mission 0.435 -> ~0.33-0.38: usable 60.25% -> 65-70% (abstentions converting to confident correct fixes as each place's embedding moves less with survey), false fix held at <=4% (the committee gate is unchanged). Training-capture diagnostics stay within ~0.02 of today (0.013-0.038), possibly slightly worse, since the model loses some survey-specific shortcuts. Logged survey diagnostic should show wpv falling below 0.235 and xsurvey_agree rising above ~0.74. Refutation: if wpv falls but 2024 usable does not rise, early-layer style was not what separates 2024 from the training surveys and the remaining gap is content (season/canopy/construction), pointing next at the deep layers or at the training targets rather than at style. If usable falls, the mixing removed signal the pretrained invariances were already handling.
Result
mission score = 0.395212 (previous best 0.435206) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 42–42 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
44.4 m
miss, this crop
0.25
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.39566% usablecov 0.70
Fits the aircraft?all deployment gates passed largest per-area model 7,278 KB (limit 4,096 KB) · single-frame inference 4.1 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
1,012 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 14 s · implement (Opus) 1 m 20 s · train 1 area 22 m 04 s · score 16 s · samples 4 s · publish 4 s · whole experiment 26 m 19 s
ts 2026-11-01T18:28:46 · commit 3c1f370080dc ·
parent f646897562e0 · artifacts runs/20261101_180233_experiment14 ·
agent model — · took 26 m 13 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py343 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.CROSS-SURVEY STYLE MIXING (capture-holdout era, experiment 14): aparameter-free MixStyle module (Zhou et al., ICLR 2021) runs insideMember.embed() after trunk blocks features[1], features[3] and features[6](16x32x32, 24x16x16, 40x8x8 at 128 px: the early/mid levels whose per-channelmean/std encode photographic 'style'). In training mode, with probabilityMIXSTYLE_P = 0.5 per batch per insertion point, each instance's per-channelspatial mean and std (detached) are replaced by a convex mix of its own and apartner's, lambda ~ Beta(0.1, 0.1) per instance, partner = a randompermutation of the survey-mixed batch, so a place is shown wearing stylesinterpolated between the training surveys while its spatial layout is kept.In eval mode (and so in the ONNX export and the survey diagnostic) it is theidentity: the deployed graph is unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v3_small
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =11# mobilenet_v3_small.features[:11] = stem + 10 IR blocks -> 96x4x4 at 128 px
TRUNK_OUT_CH =96# deep level (after block 10)
TRUNK_MID_BLOCKS =9# features[:9] -> 48x8x8 at 128 px (the exp-12 level)
TRUNK_MID_CH =48
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv3s_features10.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent target
MIXSTYLE_AFTER =(1,3,6)# indices into trunk (features[i]) after which MixStyle runs
MIXSTYLE_P =0.5# per-batch, per-insertion-point probability of mixing
MIXSTYLE_ALPHA =0.1# Beta(alpha, alpha) for the per-instance mixing weight
MIXSTYLE_EPS =1e-6def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV3-Small features[0..10] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v3_small(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)return trunk
class MixStyle(nn.Module):"""Training-only feature-statistic mixing (no parameters, no buffers). Identity in eval mode, so it never appears in the exported graph."""def __init__(self, p=MIXSTYLE_P, alpha=MIXSTYLE_ALPHA, eps=MIXSTYLE_EPS):
super().__init__()self.p = p
self.alpha = alpha
self.eps = eps
def forward(self, x):# CPU RNG draw once per batch per insertion point: no device sync.ifnotself.training or x.shape[0]<2or torch.rand(1).item()>self.p:return x
B = x.shape[0]
mu = x.mean(dim=(2,3), keepdim=True)
var = x.var(dim=(2,3), keepdim=True)
sig =(var +self.eps).sqrt()
mu, sig = mu.detach(), sig.detach()
x_norm =(x - mu)/ sig
# Sample on CPU then move (MPS lacks some Beta kernels).
lmda = torch.distributions.Beta(torch.tensor(self.alpha), torch.tensor(self.alpha)) \
.sample((B,1,1,1)).to(device=x.device, dtype=x.dtype)
perm = torch.randperm(B, device=x.device)
mu_mix = mu * lmda + mu[perm]*(1- lmda)
sig_mix = sig * lmda + sig[perm]*(1- lmda)return x_norm * sig_mix + mu_mix
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV3-Small trunk read at two depths (8x8 after block 8, 4x4 after block 10) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 11 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)# Stateless, parameter-free; deliberately NOT inside self.trunk.self.mixstyle = MixStyle()def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""
xn =(x -self.in_mean)/self.in_std
# Blocks run one by one so MixStyle (train-only; identity in eval) can# follow features[1]/[3]/[6]. h_mid is taken after block 8 as before.
h = xn
h_mid =Nonefor i, blk in enumerate(self.trunk):
h = blk(h)if i in MIXSTYLE_AFTER:
h =self.mixstyle(h)if i == TRUNK_MID_BLOCKS -1:
h_mid = h # [B, 48, 8, 8]
h_deep = h # [B, 96, 4, 4]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py542 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.STYLE MIXING (experiment 14): model.model.MixStyle blends each trainingview's per-channel feature mean/std after trunk blocks 1/3/6 with a batchpartner's (usually another survey's), p=0.5, Beta(0.1,0.1); it is identity ineval mode, so survey_diag and the export measure the mixing-free embedding.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, LIFT_DIM,
MIXSTYLE_AFTER, MIXSTYLE_ALPHA, MIXSTYLE_P, N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
cos_k, off_k = member(xb_k)
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
print(f"[{area}] trunk: mobilenet_v3_small features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, lifts {TRUNK_MID_CH}->{LIFT_DIM} @8x8 + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @4x4 -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}, MixStyle after blocks {list(MIXSTYLE_AFTER)} "
f"p={MIXSTYLE_P} alpha={MIXSTYLE_ALPHA} (train only)", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..10] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV3-Small features[0..10] trunk per member (0.1x LR), ""two-level 8x8 + 4x4 place feature, ""MixStyle cross-survey feature-statistic mixing after trunk ""blocks 1/3/6 (train only)"),"mixstyle":{"after_blocks": list(MIXSTYLE_AFTER),"p": MIXSTYLE_P,"alpha": MIXSTYLE_ALPHA},"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v3_small features[0..10], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} (8x8) + {TRUNK_OUT_CH}->{LIFT_DIM} (4x4) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Deeper borrowed eyes: each member's place description also reads two further ImageNet-pretrained MobileNetV3-Small blocks (96 channels, 4x4), alongside the 48-channel 8x8 level it reads today 07d19b92
new best: 0.560 → 0.435
architecture
0.435
26 m 22 s
$4.91
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last time we gave the model a pair of eyes that had already looked at a million ordinary photographs, and it suddenly started recognising Berlin in a photo it had never seen. But we only used the first, simplest part of those eyes — the part that notices edges and textures, which change a lot between summer and winter or bright and dull light. This experiment also plugs in the next, deeper part, which notices how things are arranged (this road meets that row of roofs next to that park), and that changes much less from one photograph to the next. The model keeps the detail it already had and gains the bigger picture.
What it cost
figure agent
$2.96
design agent
$1.05
implementation agent
$0.90
total
$4.91
by model — claude-sonnet-5 $2.96 · claude-opus-5-5 $1.96
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 0.560 to 0.435 — 0.125 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
Experiment 12 is the only design on this ruler that moved the held-out photograph out of the 6-14% usable band: swapping the from-scratch trunk for nine ImageNet-pretrained MobileNetV3-Small blocks took truedop_2024 from 10.75% to 49.5% usable (false fix 7.0% -> 5.5%), with every other stage held fixed. That is a direct measurement that what transfers to a never-seen survey is the pretrained trunk's photometric/semantic invariance, and the remaining loss is now almost all abstention (45%), not false fixes (5.5%): when it answers it is right 90% of the time; it just does not recognise the place often enough. The training photographs sit at 96-98% usable at the same held-out viewpoints, so the gap is still the survey, not the viewpoint. Experiment 12 cut the pretrained network at its shallowest useful point (features[0..8], 48 channels at stride 16) -- the levels that encode edges and local texture, i.e. exactly the levels whose responses still change with exposure, season and shadow. In ImageNet-trained CNNs, invariance to colour, contrast and texture detail grows with depth; the next two blocks (features 9-10, 96 channels at stride 32, 128 m frame -> 4x4) respond to arrangements of parts (road junction + roof row + tree line) rather than their pixel texture. Giving the place descriptor access to that level, while keeping the current 8x8 level so nothing experiment 12 relied on is removed, should let more 2024 frames land on the same prototype direction as their training-survey twins, converting abstentions into usable fixes. This is distinct from experiment 5 (from-scratch extra stride-2 stages, which wrecked training fit because new layers had to learn whole-frame layout from three photographs): here the deeper blocks arrive pretrained on a million photographs and are only fine-tuned at 0.1x LR. Earlier-era exp 26/27/28 also used features[0..10], but under a region-holdout eval and six synthetic lighting buckets; their verdicts do not transfer. The weights are already baked: model/pretrained/mnv3s_features10.pt (verified at design time: loads strict into mobilenet_v3_small().features[:11], output 96x4x4 at 128 px, 576,464 params, and its blocks 0-8 are tensor-identical to mnv3s_features8.pt).
Method
model/model.py only changes the trunk/lift of Member: the trunk becomes mobilenet_v3_small features[:11] loaded strict from model/pretrained/mnv3s_features10.pt, split into two Sequentials (blocks 0-8 -> 48x8x8, blocks 9-10 -> 96x4x4); two 1x1 lifts (48->56 and 96->56, each Conv+BN+ReLU) are GAP-pooled and concatenated into the same 112-d feature f that feeds the unchanged BatchNorm1d -> L2 -> cosine-prototype head and offset head. Everything else (committee of 2, cosine head + margin, belief pooling decode, confidence gate, training loop, augmentation, epochs, 0.1x trunk LR) is unchanged.
Expected outcome
truedop_2024 usable_fix_rate 49.5% -> ~57% (plausible range 52-63%), false_fix_rate roughly flat at 4-7%, abstention 45% -> ~38%; mission_score 0.560 -> ~0.48 (kept if < 0.560). Train-capture diagnostics stay ~0.02-0.05 (the deeper level adds invariance, not memorisation capacity worth mentioning). The standing check applies: an improvement must come through usable_fix_rate rising. Refutation: if 2024 usable stays <= 50% or false fixes rise past ~8%, depth of the pretrained descriptor is not the bottleneck and the next experiment should target the survey gap through training signal or decode instead. Size: ~2.4 MB fp32 per member trunk + heads -> total ONNX ~7-8 MB, inside 32 MiB; host latency well under 250 ms (exp 12: 2.65 ms).
Result
mission score = 0.435206 (previous best 0.560226) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 41–41 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
1.48 km
miss, this crop
0.21
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.43560% usablecov 0.64
Fits the aircraft?all deployment gates passed largest per-area model 7,278 KB (limit 4,096 KB) · single-frame inference 3.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
956 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Opus) 2 m 10 s · implement (Opus) 2 m 14 s · train 1 area 21 m 24 s · score 16 s · samples 4 s · publish 3 s · whole experiment 26 m 28 s
ts 2026-11-01T18:02:10 · commit 07d19b923d01 ·
parent d10b5e9ebef5 · artifacts runs/20261101_173548_experiment13 ·
agent model — · took 26 m 22 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py286 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.DEEPER PRETRAINED TRUNK (capture-holdout era, experiment 13): each member'strunk is deepened to MobileNetV3-Small features[0..10] (stem + ten IR blocks,IMAGENET1K_V1, BSD-3), loaded strict from the baked filemodel/pretrained/mnv3s_features10.pt (blocks 0-8 tensor-identical tomnv3s_features8.pt). The place feature reads TWO levels of it: the 48x8x8 mapafter block 8 (the level experiment 12 used) and the 96x4x4 map after block 10.Each level has its own trainable 1x1 lift to LIFT_DIM = 56 (+ BatchNorm +ReLU), is GAP-pooled, and the two halves are concatenated into the same112-d feature f feeding the unchanged BatchNorm1d -> L2 -> cosine-prototypehead and offset head. All eleven pretrained blocks are fine-tuned atTRUNK_LR_MULT; the two lifts train at the head LR.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v3_small
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# concatenated lift output / prototype / offset-head width (as exp 11)
LIFT_DIM = EMBED_DIM //2# per-level lift width (56 + 56 = 112)
TRUNK_BLOCKS =11# mobilenet_v3_small.features[:11] = stem + 10 IR blocks -> 96x4x4 at 128 px
TRUNK_OUT_CH =96# deep level (after block 10)
TRUNK_MID_BLOCKS =9# features[:9] -> 48x8x8 at 128 px (the exp-12 level)
TRUNK_MID_CH =48
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv3s_features10.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent targetdef grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV3-Small features[0..10] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v3_small(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)return trunk
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV3-Small trunk read at two depths (8x8 after block 8, 4x4 after block 10) -> one 1x1 lift per level -> GAP -> concat -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()# One Sequential holding exactly the 11 pretrained blocks, so# trunk_parameters()/head_parameters() split cleanly; embed() runs it# in two slices (slicing shares the same submodules).self.trunk = build_pretrained_trunk()self.lift_mid = nn.Sequential(nn.Conv2d(TRUNK_MID_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.lift_deep = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, LIFT_DIM,1, bias=False),
nn.BatchNorm2d(LIFT_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: both lifts, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""
xn =(x -self.in_mean)/self.in_std
h_mid =self.trunk[:TRUNK_MID_BLOCKS](xn)# [B, 48, 8, 8]
h_deep =self.trunk[TRUNK_MID_BLOCKS:](h_mid)# [B, 96, 4, 4]
f = torch.cat([self.lift_mid(h_mid).mean(dim=(2,3)),self.lift_deep(h_deep).mean(dim=(2,3))], dim=1)# [B, 112]
e =F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py532 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12, deepened in experiment 13): each member'strunk is ImageNet-pretrained MobileNetV3-Small features[0..10] (model.model,BSD-3, loaded strict from the baked model/pretrained/mnv3s_features10.pt),read at two depths (48x8x8 and 96x4x4), each through its own trainable 1x1lift to 56, concatenated to 112.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM, LIFT_DIM,
N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_MID_CH, TRUNK_OUT_CH, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
cos_k, off_k = member(xb_k)
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
print(f"[{area}] trunk: mobilenet_v3_small features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, lifts {TRUNK_MID_CH}->{LIFT_DIM} @8x8 + "
f"{TRUNK_OUT_CH}->{LIFT_DIM} @4x4 -> {EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..10] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV3-Small features[0..10] trunk per member (0.1x LR), ""two-level 8x8 + 4x4 place feature"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk":(f"mobilenet_v3_small features[0..10], two-level 1x1 lift "
f"{TRUNK_MID_CH}->{LIFT_DIM} (8x8) + {TRUNK_OUT_CH}->{LIFT_DIM} (4x4) "
f"-> {EMBED_DIM}"),"embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported fp32 ONNX ≤ 32 MiB per area
(~8 MiB once int8-quantised for the P4), host latency proxy ≤ 250 ms
(see pipeline/score.py). Size is no longer the tight constraint; latency
and power on the chip are, so a bigger model still has to earn its keep.
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Borrowed eyes: each committee member's from-scratch trunk is replaced by ImageNet-pretrained MobileNetV3-Small blocks (BSD-3, baked in model/pretrained), fine-tuned at a tenth of the learning rate, so the place descriptor starts from invariances learned on a million photographs instead of three 64d06484
starting line: mission score 0.560
architecture
0.560
31 m 56 s
$6.96
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the UAV's two 'navigators' had eyes that were grown from scratch by looking at only three aerial photographs of Berlin, so they learned those three photographs' quirks - that day's shadows, that camera's colours - and a fourth photograph of the same streets looked foreign to them. This experiment gives each navigator eyes that have already looked at about a million ordinary photographs and learned what edges, roads, roofs and textures look like in general, under all kinds of light and seasons; we then teach those eyes Berlin on top, gently, so the general knowledge is not overwritten. The hope is that eyes which already ignore lighting and season will recognise a Berlin street in a photograph they have never seen, which is exactly the test. Everything after the eyes - how the two navigators vote, how confidence is decided - stays the same.
What it cost
design agent
$5.81
implementation agent
$1.14
total
$6.96
by model — claude-fable-5-1 $5.81 · claude-opus-5-5 $1.14
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The first scoreable run of this lineage, so there was nothing to beat — it sets the mission score (0.560) that every later experiment must improve on. Its code is committed as the starting point later experiments branch from.
Hypothesis
Eleven experiments on this ruler have moved every stage except the one that decides what a place looks like. The held-out 2024 usable-fix rate has sat in a 6-14% band through all of them (exp 2: 7.0, exp 4: 11.75, exp 5: 12.5, exp 6: 14.2, exp 7: 7.5, exp 8: 9.2, exp 10: 6.3, exp 11: 10.75) while everything around it swung: training-survey fit at the same held-out viewpoints ranged 18% to 95% usable (exp 5 lifted it to 72-81% and 2024 stayed at 12.5%; exp 11 lifted it to 65-77% and 2024 read 10.75%), and the gate took 2024 false fixes from 43% to 7% (exps 7 and 11) without touching usable. The champion's own survey diagnostic says why: after the cosine head, each member still names the same cell for the same place in all three TRAINING surveys only 43-46% of the time (xsurvey_agree, clean lattice crops, heading 0), its within-place variance fraction did not move (0.286 vs 0.295 in exp 7; exp 11 predicted < 0.15), and clean per-survey top1 is 57-67% on photographs it trained on. Three fingerprints per tile remain the solution the trunk finds, whatever head, gate or auxiliary sits on it (exps 3, 8, 9, 10 all tried to pull the feature together and none bit), because the trunk itself - four plain 3x3 stride-2 convs, 150k parameters, initialised at random, 'Feature extractor' changed:true only once in this era (exp 5, which added depth on top of the same four layers) - has only ever seen three photographs of one city and has no reason to prefer the structure they share over the texture that tells them apart. This experiment changes what the trunk IS: each member's conv stack becomes torchvision's MobileNetV3-Small stem + first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3, 190,520 parameters, 128x128 -> 48x8x8, same 8x8 grid and stride-16 the current trunk produces), followed by a trainable 1x1 lift 48->112 so the exp-11 cosine head, prototypes, offset head, pooling and committee gate are byte-for-byte the same design. The pretrained blocks are fine-tuned at a tenth of the head's learning rate so the invariances they arrive with are adapted to Berlin, not overwritten by it. The weights are already in the repository (model/pretrained/mnv3s_features8.pt, 195,168 values, verbatim torchvision tensors, loaded strict in the four-area era by commit 2d6f2cd's _build_pretrained_trunk, and the AWS code package ships the whole model/ directory, so nothing is downloaded on the box). Why this is the family the evidence points at and not another training signal: the one external representation this era has measured (exp 8's probe, three TRAINING captures only) found a place across surveys 95% of the time when aligned, 70% under the eval's 12 px shift and 23% under shift+rotation, against 90% / 7-11% / 1% for raw pixels - features learned on natural images at scale carry both the cross-survey and the off-lattice tolerance the eval demands, and exp 8 failed not because that was wrong but because a 1M-parameter student could not absorb it through distillation (student-teacher cosine 0.40 against 0.55 needed). Deploying pretrained features directly sidesteps distillation entirely: the invariance is in the weights on day one, and fine-tuning at 0.1x only has to attach Berlin's 2,970 prototypes to it. MobileNetV3-Small at features[0..8] is the right slice for this harness, not DINOv2: it is a CNN the ESP32-P4 toolchain ingests, its slice fits the 4 MiB gate twice over with the full 112-d head (design-stage sizing on the exact graph, runs/_probe_exp12_pretrained.py: two members export to 3,542,960 bytes, 3.38 MiB, 1,058,420 parameters, 1.3 ms host latency), and it is permissively licensed. Honest reading of the earlier-era record: the four-area era ran this trunk for ~30 experiments (its src_ids 11-40) and those models re-score at 1.77-2.00 on this ruler, but every one of them was trained on ONE photograph under a sigmoid confidence head that never abstains (false fix 77-99%, usable 0-0.5%), so their numbers measure a broken gate, not the trunk's cross-survey behaviour; the trunk has never been trained on three surveys, never under the committee gate, never under the cosine head, and never under paired batches with photometric randomisation. This is the 'change what the trunk is' move that exp 11's own decision rule (b) named for the case that compactness across three surveys did not reach a fourth, and that exp 7's rule (a) named as the accuracy move once the gate was in place; both conditions now hold. The deployed graph changes (new trunk, same head and decode); the training loss, targets, paired batches, augmentation, committee, schedule shape and views per epoch do not. Library L2 lists pretrained-feature routes as the largest documented effect in the scene-coordinate literature (ACE-G / R-SCoRe); this is that route in its deployable form.
Method
model/model.py: Member.features (four from-scratch stride-2 convs at MEMBER_CHANS) is replaced by trunk = mobilenet_v3_small(weights=None).features[:9] with the state dict loaded strict from model/pretrained/mnv3s_features8.pt (prefix 'features.' stripped), followed by lift = Conv2d(48, 112, 1, bias=False) + BatchNorm2d + ReLU; ImageNet mean/std normalisation is applied to the [0,1] input inside Member.embed via registered buffers so the ONNX contract is unchanged. embed_bn, prototypes [n_cells x 112], off_head, forward(), the committee decode, loss_fn and export_onnx are untouched. model/train.py: the optimiser gets two parameter groups - the pretrained trunk blocks at 1e-3 * TRUNK_LR_MULT (0.1) and everything else at 1e-3 - under a LambdaLR with the same cosine shape as today's schedule (multiplier 1.0 -> 0.1 over the run, i.e. head 1e-3 -> 1e-4 as now, trunk 1e-4 -> 1e-5); train_info records init = pretrained and the trunk description. Nothing else changes: paired-survey chunks, augment_views, tent targets, residual offset targets, two members with independent augmentation draws, survey_diag, epochs, batch size.
Expected outcome
Mechanical checks that must hold or the mechanism did not bite: the training log prints a line confirming the strict load of model/pretrained/mnv3s_features8.pt for both members; exported bytes read ~3,542,960 (design-stage mock of the exact graph; anything above 4,194,304 is an implementation error, not a result) and host latency ~1.5 ms; per-member augmented top1 at epoch 8 is at or above exp 11's 0.58 (a pretrained init fits faster, not slower) and the member agreement rate on training views is at or above exp 11's 0.54. The diagnostic the mechanism is aimed at: each member's clean cross-survey argmax agreement (xsurvey_agree, same cell named in all three training surveys) rises from exp 11's 0.43-0.46 to above 0.55 by epoch 8, and the within-place variance fraction (wpv) falls from 0.286 to below 0.22 - i.e. the pretrained features describe a place more alike across the three surveys than the from-scratch features did. Primary (held-out truedop_2024): 0.963 -> predicted 0.85-0.95, through usable_fix_rate: 10.75% -> 15-25%, with false_fix_rate 7% -> 6-12% (both members start from the same ImageNet weights, so they are less diverse than two random inits and will agree more often on 2024 frames; the bet is that the extra agreement is enriched for correct fixes because the shared features are survey-invariant, and the committee's logged agreement rate is the check). 2024 coverage: 0.1775 -> 0.25-0.40. 2024 median error among confident frames (55 m) stays below 100 m. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.358 / 0.373 / 0.253 on exp 11, usable 66 / 65 / 77%) are predicted to IMPROVE to 0.20-0.35 (usable 70-85%); the evidence that matters is the gap between those three numbers and the 2024 score narrowing, not the training numbers alone. Decision rules: (a) 2024 usable up by >= 4 points with false fix <= 12% -> supported; the next experiment either extends the slice to features[0..9] at a narrower embedding (96 ch at 4x4, whole-frame receptive field, exp 5's finding transplanted onto invariant features; sizing in the probe: needs D <= 80 to fit) or lowers the trunk multiplier further / freezes the stem and blocks 1-3 to keep more of the ImageNet invariance. (b) xsurvey_agree > 0.55 but 2024 usable flat (<= 12.5%) -> ImageNet features fine-tuned on three surveys still describe a fourth differently; retry once with the trunk FROZEN (linear-probe regime, TRUNK_LR_MULT 0) to separate 'the features cannot do it' from 'fine-tuning destroyed them' before closing the family; if that is flat too, move to survey-bagged members (each member trained on two of the three surveys, giving an in-training foreign-survey signal for the gate). (c) per-member top1 < 0.45 at epoch 8 -> the trunk cannot adapt at 0.1x or the 48->112 lift is the bottleneck; retry once with TRUNK_LR_MULT 1.0, nothing else changed. (d) false fix rises above 14% with usable up -> the two members share ImageNet-derived confusions; the next experiment restores diversity by giving the members different pretrained slices (features[0..7] vs [0..8]) or different frozen depths, not by reverting to from-scratch. (e) the box fails on 'import torchvision' or on the weight file -> infrastructure (torchvision is in the Modal image and the AWS Deep Learning PyTorch AMI; the code package ships model/pretrained), not a verdict; rerun. Standing check: the score must move through usable_fix_rate; an improvement through false_fix_rate alone with usable flat means the pretrained features made the members more honest, not more knowledgeable - still kept, but rule (b) applies to the next design.
Result
mission score = 0.560226 (previous best 0.96288) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json. At the time it scored 1e9: exported fp32 ONNX 4,347,119 bytes over the old 4 MiB gate; that record is kept as metrics_at_the_time_size_gate.json.
Conclusion
KEPT (promoted 2026-11-01) — REVERTED at the time only because the exported model was ~150 KB over the old, underived 4 MiB fp32 size gate. The gate was re-derived from current ESP32-P4 boards as 32 MiB fp32 (~8 MiB int8), issue #8; re-scored from its own saved model at 0.560226: usable 49.5%, false fix 5.5% on truedop_2024 (exp 11: 10.75% / 7.0%). Committed as 64d0648.
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 45–45 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
1.50 km
miss, this crop
0.15
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.56050% usablecov 0.55
Fits the aircraft?all deployment gates passed largest per-area model 4,245 KB (limit 4,096 KB) · single-frame inference — on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
750 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 11 m 15 s · implement (Opus) 2 m 10 s · train 1 area 18 m 11 s · samples 4 s · publish 4 s · whole experiment 32 m 02 s
ts 2026-11-01T17:32:35 · commit 64d06484788e ·
parent 97f4c177dc6b · artifacts runs/20261101_170039_experiment12 ·
agent model — · took 31 m 56 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py261 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own trunk + lift + its owncell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.PRETRAINED TRUNK (capture-holdout era, experiment 12): each member'sfrom-scratch conv trunk is replaced by torchvision's MobileNetV3-Small stem +first eight inverted-residual blocks (features[0..8], IMAGENET1K_V1, BSD-3;128x128 -> 48x8x8, the same 8x8 grid as before), loaded strict from the bakedfile model/pretrained/mnv3s_features8.pt (verbatim torchvision tensors, sonothing is downloaded at train or inference time), followed by a trainable1x1 lift 48 -> EMBED_DIM + BatchNorm + ReLU. Each member builds its ownindependent copy of the weights. ImageNet mean/std normalisation of the [0,1]input is applied inside Member.embed via registered buffers, so it bakes intothe ONNX graph and the input contract is unchanged. train.py fine-tunes thepretrained blocks at TRUNK_LR_MULT (0.1) times the head learning rate, so theImageNet invariances are adapted to Berlin rather than overwritten by it.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from torchvision.models import mobilenet_v3_small
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
EMBED_DIM =112# lift output / prototype / offset-head width (as exp 11)
TRUNK_BLOCKS =9# mobilenet_v3_small.features[:9] = stem + 8 IR blocks -> 48x8x8 at 128 px
TRUNK_OUT_CH =48
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv3s_features8.pt"
TRUNK_LR_MULT =0.1# pretrained blocks train at this multiple of the head LR
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent targetdef grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))def build_pretrained_trunk()-> nn.Sequential:"""MobileNetV3-Small features[0..8] with ImageNet weights loaded STRICT from the baked file (keys prefixed 'features.'). Call once per member so each owns an independent copy."""
trunk = mobilenet_v3_small(weights=None).features[:TRUNK_BLOCKS]
sd = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
trunk.load_state_dict({k[len("features."):]: v for k, v in sd.items()}, strict=True)return trunk
class Member(nn.Module):"""One independent localizer: pretrained MobileNetV3-Small trunk -> 1x1 lift -> GAP -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int):
super().__init__()self.trunk = build_pretrained_trunk()self.lift = nn.Sequential(nn.Conv2d(TRUNK_OUT_CH, EMBED_DIM,1, bias=False),
nn.BatchNorm2d(EMBED_DIM), nn.ReLU(inplace=True))self.register_buffer("in_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("in_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))self.embed_bn = nn.BatchNorm1d(EMBED_DIM)self.prototypes = nn.Parameter(torch.empty(n_cells, EMBED_DIM))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(EMBED_DIM,2)def trunk_parameters(self):"""Pretrained trunk parameters (fine-tuned at TRUNK_LR_MULT x LR)."""return list(self.trunk.parameters())def head_parameters(self):"""Everything not in self.trunk: lift, embed_bn, prototypes, off_head."""
trunk_ids ={id(p)for p inself.trunk.parameters()}return[p for p inself.parameters()if id(p)notin trunk_ids]def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]. x is float [0,1]; ImageNet normalisation is in-graph."""
f =self.lift(self.trunk((x -self.in_mean)/self.in_std)).mean(dim=(2,3))
e = F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py526 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.PRETRAINED TRUNK (experiment 12): each member's trunk is now ImageNet-pretrained MobileNetV3-Small features[0..8] (model.model, BSD-3, loaded strictfrom the baked model/pretrained/mnv3s_features8.pt) + a trainable 1x1 lift.The optimiser has two parameter groups: the pretrained trunk blocks atTRUNK_LR_MULT (0.1) x the head LR, everything else at 1e-3, both decayed byone LambdaLR of the previous cosine shape (multiplier 1.0 -> 0.1 over the run:head 1e-3 -> 1e-4 as before, trunk 1e-4 -> 1e-5). Trunk BatchNorm layers stayin train mode so their running stats adapt to aerial imagery.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import math
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, EMBED_DIM,
N_MEMBERS, PRETRAINED_TRUNK_PATH, TRUNK_BLOCKS,
TRUNK_LR_MULT, TRUNK_OUT_CH, build_model, export_onnx,
grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
cos_k, off_k = member(xb_k)
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
print(f"[{area}] trunk: mobilenet_v3_small features[0..{TRUNK_BLOCKS -1}] "
f"IMAGENET1K_V1 loaded strict from {PRETRAINED_TRUNK_PATH.name} "
f"x {N_MEMBERS} members, lift {TRUNK_OUT_CH}->{EMBED_DIM}, "
f"trunk lr x{TRUNK_LR_MULT}", flush=True)
trunk_params =[p for m in model.members for p in m.trunk_parameters()]
head_params =[p for m in model.members for p in m.head_parameters()]
all_ids =[id(p)for p in model.parameters()]
grouped =[id(p)for p in trunk_params + head_params]assert len(grouped)== len(all_ids)== len(set(grouped))and set(grouped)== set(all_ids), \
"optimiser groups must cover every parameter exactly once"
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-3* TRUNK_LR_MULT},{"params": head_params,"lr":1e-3}])# Same cosine shape as before for both groups: multiplier 1.0 -> 0.1 over# the run (head 1e-3 -> 1e-4, trunk 1e-4 -> 1e-5), stepped once per epoch.
sched = torch.optim.lr_scheduler.LambdaLR(
opt,lambda e:0.1+0.9*0.5*(1+ math.cos(math.pi * e / epochs)))
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={opt.param_groups[1]['lr']:.2e} "
f"trunk_lr={opt.param_groups[0]['lr']:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":("pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..8] ""(torchvision, BSD-3), fine-tuned at 0.1x LR"),# §9"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin, ""ImageNet-pretrained MobileNetV3-Small trunk per member (0.1x LR)"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"trunk": f"mobilenet_v3_small features[0..8] + 1x1 lift {TRUNK_OUT_CH}->{EMBED_DIM}","embed_dim": EMBED_DIM,"trunk_lr_mult": TRUNK_LR_MULT,"pretrained_file": PRETRAINED_TRUNK_PATH.name,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell with **no usable fix at all** scores FAIL — you cannot pass by
abstaining on everything. There is no coverage floor: a model that answers
on only a small share of frames but is right when it answers is exactly
what this score rewards.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
One direction per tile: a normalised-prototype cosine head with an additive margin replaces the affine cell classifier, so every survey's picture of a place must point the same way 11a9de98
starting line: mission score 0.963
architecture
0.963
26 m 56 s
$10.02
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model's last step was a big lookup table that could quietly keep three separate 'looks' for every map tile - one per survey photograph it trained on - and a fourth photograph matched none of them. We replace that table with a compass: every map tile gets exactly one direction, and every picture of a place, from whichever survey, is trained to point that way with a safety margin against the neighbouring tiles. This is the same trick face recognition uses to know one person across many photos instead of memorising each photo. If it works, a photograph the model has never seen should still point at the right tile, because that is now the only way the model knows how to point.
What it cost
design agent
$6.35
figure agent
$2.69
implementation agent
$0.99
total
$10.02
by model — claude-fable-5-1 $6.35 · claude-sonnet-5 $2.69 · claude-opus-5-5 $0.99
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The first scoreable run of this lineage, so there was nothing to beat — it sets the mission score (0.963) that every later experiment must improve on. Its code is committed as the starting point later experiments branch from.
Hypothesis
Ten experiments on this ruler leave the held-out 2024 photograph at 7.5% usable (exp 7, 1.096), with usable never outside 7-14% while the training photographs ranged 17-96% at the same held-out viewpoints: the deployed feature of a place still moves with the survey, and the cell head tolerates that. The exp 9 design-stage probe measured it on the champion's own exported graph (runs/_probe_exp9_wpv.py, three TRAINING captures only): a change of survey moves a member's pooled feature 30% as far as a change of place (within-place variance fraction 0.295), and the SAME member names the same cell for the same place in two training surveys only 28-40% of the time. Three attempts to close that spread were all AUXILIARY terms added beside an affine softmax head and none got a fair test: exp 3's cosine term was satisfied for free by post-ReLU positivity (0.966 at epoch 1), exp 9's standardised variance penalty at weight 10 collapsed training (top1 0.008), exp 10's reconstruction target left the head free to read survey cues beside the canonical ones. The common cause is not the targets but the HEAD: an affine linear classifier (w_c . f + b_c) over an unnormalised feature can raise a sample's margin by growing feature and weight norms instead of by reducing angular spread, so it is content to store a summer, a leaf-off and an early-spring signature of each tile as three directions inside one wide cone (exp 2 did exactly that: 95% usable on each training photograph, 7% on the fourth). This is the problem face recognition solved a decade ago for one identity across many photographs: normalise the feature AND the class prototype so the logit is a pure cosine, scale it by a fixed s, and train with an additive margin (NormFace, Wang et al. 2017; CosFace, Wang et al. 2018). With norms fixed, the ONLY way to lower the loss is angular - pull every photograph of a tile toward that tile's single prototype direction and push the 2,970 prototypes apart - so intra-class compactness across surveys becomes the main objective rather than a side term: it cannot be vacuous (the embedding is batch-normalised before normalisation, so unrelated places sit near cosine 0, not 0.7), it cannot collapse (2,970 prototypes must separate), and it cannot be side-stepped by norm growth. A fourth survey's feature of a place then only has to land inside the compact cap around the prototype it was trained to share with three others, rather than inside one of three memorised directions. The design-stage probe for THIS experiment (runs/_probe_exp11_illum.py) closed the alternative explanation first: no fixed input transform - grey, chromaticity, local contrast normalisation, gradient magnitude, or the Maddern illumination-invariant channel at any alpha - makes the same place more alike across the training surveys than raw RGB (same-place correlation 0.52 for RGB vs 0.32-0.42 for every transform), and deep-shadow state disagrees on only 4-8% of pixels, so the gap is not shadows or colour that a preprocessing step could remove; it has to be closed where the feature is read. The 'Map-cell classifier' stage has never carried changed:true in this era except for exp 7's averaging; this experiment changes how it reads the feature, on both committee members, and leaves trunk, pooling, offset head, committee gate, paired batches and nuisance randomisation untouched. Library L2 rank 1 (cross-survey latent consistency) is what this delivers, by parameterisation instead of by loss.
Method
In model/model.py each Member's affine cell head nn.Linear(112, n_cells) is replaced by: GAP feature -> BatchNorm1d(112) -> L2-normalise -> cosine against an L2-normalised prototype matrix W [n_cells x 112] (bias-free); deployed logits = COS_SCALE * cos with COS_SCALE = 30. In training only (model.loss_fn), an additive margin COS_MARGIN = 0.25 is subtracted from the cosine of the target cells in proportion to the tent target (full margin on the dominant cell, fractional on its tent neighbours): logits_train = s * (cos - m * t / t.max()), then the existing soft cross-entropy against the tent target and the existing smooth-L1 residual offset loss. The offset head still reads the raw GAP feature. Committee decode, block pooling, min-over-members gate and export contract are byte-for-byte the same shape; only the cell-logit computation changes. model/train.py adds an epoch-end clean diagnostic on a fixed set of 512 training-lattice positions in all three training captures (heading 0, no augmentation): per member, the cross-survey cosine of the normalised embedding for the same place vs random pairs, the within-place variance fraction (exp 9 probe definition), the fraction of positions on which the member names the same cell in all three surveys, and clean top1 per capture.
Expected outcome
Mechanical checks that must hold or the mechanism did not bite: on the clean diagnostic set, each member's cross-survey argmax agreement (same cell named in all three training surveys) rises from the champion's 0.28-0.40 (exp 9 probe) to above 0.60 by epoch 8, and its within-place variance fraction falls from 0.295 to below 0.15, while the same-place vs random-pair cosine gap of the normalised embedding exceeds 0.5; augmented per-member top1 (argmax of cos, unaffected by the margin) ends at or above exp 7's 0.35 and the member agreement rate at or above 0.35 (the loss VALUE is not comparable to exp 7's 9.08 because the margin inflates it by design); exported bytes read ~3,947,000 (a design-stage mock of the exact head, runs/_probe_exp11_headsize.py, exported at 3,947,074 bytes with 966,372 parameters and ran in onnxruntime; BatchNorm1d adds 448 parameters per member, the bias is removed) and host latency ~2 ms. Primary (held-out truedop_2024): 1.096 -> predicted 0.95-1.05, through usable_fix_rate: 7.5% -> 12-20%, with false_fix_rate 17% -> 12-20% (direction uncertain: the margin is removed at inference so confident frames are MORE confident than in training, which raises coverage on both right and wrong frames; the committee gate still requires both members to name the same block). 2024 coverage: 0.245 -> 0.30-0.45; the 0.2 FAIL floor is not expected to bind because a prototype head trained with a margin produces sharper, not flatter, beliefs. 2024 median error among confident frames (1,342 m) should fall below 800 m. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.833 / 0.845 / 0.703 on exp 7, usable 22 / 18 / 32%, coverage 0.27 / 0.20 / 0.34) are predicted to IMPROVE to 0.50-0.70 (usable 35-50%), because a cosine head with a margin is also a tighter fit of the training task; the evidence that matters is the 2024-vs-training gap narrowing, not the training numbers alone. Decision rules: (a) agreement > 0.60 AND 2024 usable up by >= 4 points -> supported; the next experiment either tunes (s, m) once or puts exp 5's whole-frame trunk under the cosine head, since its fit gain on the training surveys may now transfer. (b) agreement > 0.60 but 2024 usable flat (<= 9.5%) -> compactness across THESE three surveys, now genuinely achieved by the main objective, does not reach a fourth; close the feature-compactness line for the era in both its auxiliary and structural forms, and move to a family that changes what the trunk is - a permissively-licensed pretrained deployed trunk (torchvision mobilenet_v3_small features[0..8], BSD-3, never tried in this era) - or to survey-bagged members (each member trained on two of the three surveys, giving an in-training foreign-survey measurement no experiment has had). (c) agreement stays < 0.45 at m = 0.25 -> the margin did not compact; retry once with COS_MARGIN 0.40, nothing else changed. (d) 2024 coverage < 0.2 (FAIL) -> beliefs too flat at s = 30 for the frozen 0.3 block-mass threshold; retry once with COS_SCALE 45, nothing else changed. Standing check: the score must move through usable_fix_rate; an improvement through false_fix_rate alone with usable flat means the head taught honesty, not place - still kept, but rule (b) applies to the next design.
Result
mission score = 0.96288 (previous best 1.095578) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json. At the time it scored 1e9 under the 20% coverage floor (coverage 17.75%); that record is kept as metrics_at_the_time_coverage_floor.json.
Conclusion
KEPT (promoted 2026-11-01) — REVERTED at the time only because the scorer's 20% coverage floor failed it. The floor was replaced by a usable-fix rule (issue #5); re-scored from its own saved model at 0.96288, the era's best (usable 10.75%, false fix 7.0%). Committed as 11a9de9.
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 55–55 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
2.16 km
miss, this crop
0.15
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
0.96311% usablecov 0.18
Fits the aircraft?all deployment gates passed largest per-area model 3,857 KB (limit 4,096 KB) · single-frame inference 1.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
401 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 13 m 30 s · implement (Opus) 1 m 47 s · train 1 area 11 m 10 s · score 11 s · samples 4 s · publish 4 s · whole experiment 27 m 02 s
ts 2026-11-01T16:47:35 · commit 11a9de98fa1e ·
parent b8a2f17aa7c9 · artifacts runs/20261101_162039_experiment11 ·
agent model — · took 26 m 56 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py220 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own conv trunk atMEMBER_CHANS + its own cell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.NORMALISED-PROTOTYPE COSINE HEAD (capture-holdout era, experiment 11): eachmember's affine cell head (w_c . f + b_c) is replaced by GAP feature ->BatchNorm1d -> L2-normalise -> cosine against an L2-normalised, bias-freeprototype matrix [n_cells x D]. Member.forward() returns those COSINES; thedeployed logits are COS_SCALE * cos (no margin). In training only, loss_fnsubtracts an additive margin COS_MARGIN from the target cells' cosine inproportion to the tent target (CosFace-style; full margin on the dominantcell, fractional on its tent neighbours). Why: an affine head over anunnormalised feature can raise its margin by growing feature and weight norms,so it may keep one direction per survey inside a wide cone for each tile. Withnorms fixed, the only way to lower the loss is angular, so every survey'spicture of a tile must point at that tile's single prototype. The offset headstill reads the raw GAP feature.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
MEMBER_CHANS =[3,24,48,96,112]# per-member trunk widths (size gate)
COS_SCALE =30.0# fixed logit scale s: deployed logits = s * cos
COS_MARGIN =0.25# training-only additive cosine margin m on the tent targetdef grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Member(nn.Module):"""One independent localizer: conv trunk -> GAP -> (C-way cell COSINES against normalised prototypes, within-cell offset)."""def __init__(self, n_cells: int, chans=MEMBER_CHANS):
super().__init__()
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.embed_bn = nn.BatchNorm1d(chans[-1])self.prototypes = nn.Parameter(torch.empty(n_cells, chans[-1]))
nn.init.normal_(self.prototypes, std=0.01)self.off_head = nn.Linear(chans[-1],2)def embed(self, x):"""(e, f): e = unit-length centred embedding [B, D]; f = raw GAP feature [B, D]."""
f =self.features(x).mean(dim=(2,3))
e = F.normalize(self.embed_bn(f), dim=1)return e, f
def forward(self, x):
e, f =self.embed(x)
cos = F.linear(e, F.normalize(self.prototypes, dim=1))# [B, n_cells] in [-1, 1]# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.return cos, torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (cosines, offset) for the loss; logits are COS_SCALE * cosines. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (cosines, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(COS_SCALE * c, dim=1)for c,_in outs]# no margin deployed
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(cos: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Additive-margin soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. cos is the member's [B, n_cells] cosine matrix (NOT logits). The training logits are COS_SCALE * (cos - COS_MARGIN * t_hat), where t_hat is the tent target rescaled so its dominant cell is 1.0 (tent neighbours fractional, the label-smoothing floor ~0): the margin is applied in proportion to the target and only in training. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
t_hat = soft_target / soft_target.max(dim=1, keepdim=True).values.clamp_min(1e-9)
logits = COS_SCALE *(cos - COS_MARGIN * t_hat)
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py497 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.COSINE HEAD (experiment 11): each member's forward() now returns COSINESagainst L2-normalised cell prototypes, not logits. The scaled, margin-freelogits COS_SCALE * cos are what the residual offset target, top1, agreementand the committee belief statistics read; the training-only additive marginlives inside loss_fn, which takes the cosines. At the end of every epoch aclean SURVEY DIAGNOSTIC (survey_diag) cuts 512 fixed training-latticepositions at heading 0, no augmentation, from each TRAINING capture only, andlogs per member: the same-place vs random-pair cosine of the normalisedembedding across surveys, the within-place variance fraction (0 = oneembedding per place regardless of survey), the fraction of positions on whichthe member names the same cell in every survey, and clean top1 per capture.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, COS_MARGIN, COS_SCALE, MEMBER_CHANS,
N_MEMBERS, build_model, export_onnx, grid_dims,
loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
cos_k, off_k = member(xb_k)
logits_k = COS_SCALE * cos_k # deployed, margin-free logits
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(cos_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx):"""Clean cross-survey diagnostic on fixed TRAINING-lattice positions (diag_idx), heading 0, no augmentation, TRAINING captures only. Per member: xs_cos_same / xs_cos_diff (mean over capture pairs of the cosine of the normalised embedding for the same place / a fixed random pairing), wpv (within-place variance fraction, exp 9 probe definition), xsurvey_agree (same argmax cell in every capture), clean_top1 (per capture)."""
gw,_= grid_dims(meta)
was_training = model.training
model.eval()
xy = crop_xy[torch.as_tensor(diag_idx, dtype=torch.int64)]
P = len(xy)
cells =((xy[:,1]// CELL_PX)* gw + xy[:,0]// CELL_PX).numpy()
E =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P, D]
A =[[None]* n_caps for_in range(N_MEMBERS)]# [member][cap] -> [P]with torch.no_grad():for k in range(n_caps):
es =[[]for_in range(N_MEMBERS)]
args =[[]for_in range(N_MEMBERS)]for s in range(0, P,64):
cx = xy[s:s +64,0].to(device)
cy = xy[s:s +64,1].to(device)
b = len(cx)
cap = torch.full((b,), k, dtype=torch.int64, device=device)
x = gpu_crops(scene, cap, cx, cy, torch.zeros(b, device=device))for m, member in enumerate(model.members):
e,_= member.embed(x)
cos = F.linear(e, F.normalize(member.prototypes, dim=1))
es[m].append(e.cpu())
args[m].append(cos.argmax(dim=1).cpu())for m in range(N_MEMBERS):
E[m][k]= torch.cat(es[m]).numpy().astype(np.float64)
A[m][k]= torch.cat(args[m]).numpy()if was_training:
model.train()
perm = np.random.default_rng(54321).permutation(P)
pairs =[(a, b)for a in range(n_caps)for b in range(a +1, n_caps)]
out ={"xs_cos_same":[],"xs_cos_diff":[],"wpv":[],"xsurvey_agree":[],"clean_top1":[]}for m in range(N_MEMBERS):if pairs:
same = np.mean([np.mean(np.sum(E[m][a]* E[m][b], axis=1))for a, b in pairs])
diff = np.mean([np.mean(np.sum(E[m][a]* E[m][b][perm], axis=1))for a, b in pairs])else:
same = diff = float("nan")
X = np.stack(E[m])# [K, P, D]
flat = X.reshape(-1, X.shape[-1])
Z =(X - flat.mean(0))/(flat.std(0)+1e-6)
w = float(((Z - Z.mean(axis=0, keepdims=True))**2).mean())
Am = np.stack(A[m])# [K, P]
agree = float(np.mean(np.all(Am == Am[0:1], axis=0)))
top1 =[round(float(np.mean(Am[k]== cells)),4)for k in range(n_caps)]
out["xs_cos_same"].append(round(float(same),4))
out["xs_cos_diff"].append(round(float(diff),4))
out["wpv"].append(round(w,4))
out["xsurvey_agree"].append(round(agree,4))
out["clean_top1"].append(top1)return out
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0# Fixed for the run: clean survey-diagnostic positions (training lattice).
diag_idx = np.random.default_rng(12345).choice(
len(crop_xy), min(512, len(crop_xy)), replace=False)
diag ={}for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
diag = survey_diag(model, scene, crop_xy, meta, device, n_caps, diag_idx)
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"xs_cos_same={diag['xs_cos_same']} xs_cos_diff={diag['xs_cos_diff']} "
f"wpv={diag['wpv']} xsurvey_agree={diag['xsurvey_agree']} "
f"clean_top1={diag['clean_top1']}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""normalised-prototype cosine head with additive margin"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"member_chans": MEMBER_CHANS,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"head":(f"normalised-prototype cosine, BatchNorm1d embedding, s={COS_SCALE}, "
f"train-only additive margin m={COS_MARGIN} on the tent target"),"cos_scale": COS_SCALE,"cos_margin": COS_MARGIN,"final_xs_cos_same": diag.get("xs_cos_same"),"final_xs_cos_diff": diag.get("xs_cos_diff"),"final_wpv": diag.get("wpv"),"final_xsurvey_agree": diag.get("xsurvey_agree"),"final_clean_top1": diag.get("clean_top1"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Canonical-composite reconstruction: each member's 8x8 feature map must repaint the per-pixel MEDIAN of the three training surveys (a picture of Berlin in which anything seen in only one survey is gone), through a training-only decoder that never flies ed3332a7
worse than champion: 1.141 vs 1.096
loss
1.141
46 m 10 s
$9.92
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Three aerial photographs of the same Berlin street disagree about the parked cars, the shadows and the leaves on the trees, but they agree about the roads, the canals and the building footprints. We make a fourth picture of the whole city by majority vote, pixel by pixel: anything that appears in only one photograph simply vanishes, and what two or three agree on stays. During training, the two navigators are shown one real photograph of a place and asked to sketch, in coarse strokes, what that majority-vote picture of the place looks like. The only way to pass the sketching test is to notice the permanent features and ignore the fleeting ones, which is exactly the habit a navigator needs when the UAV's own camera takes a fifth photograph nobody has. The sketching pad is thrown away before the model flies; only the habit stays.
What it cost
design agent
$5.98
figure agent
$2.96
implementation agent
$0.98
total
$9.92
by model — claude-fable-5-1 $5.98 · claude-sonnet-5 $2.96 · claude-opus-5-5 $0.98
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 1.141 it didn't beat the champion's 1.096, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Nine experiments on this ruler leave the held-out 2024 photograph at 7.5% usable / 17% false fix (exp 7, 1.096) with usable never outside 7-12.5%, and they say, read together, that the deployed feature of a place is still built from survey-specific content: exp 5 lifted the TRAINING photographs to 72-81% usable at the same held-out viewpoints and 2024 did not move (12.5%), so the trunk learns three survey-specific layouts; exp 4's photometric randomisation (the only mechanism that ever moved 2024 accuracy, 7% -> 11.75%) removed the GLOBAL part of a survey change, and the remaining part is CONTENT - shadows of a different sun, parked cars, construction, canopy state, true-ortho artefacts - which no per-view photometric draw can synthesise. Three attempts to make the feature survey-invariant through the three surveys themselves did not get a fair test: exp 3's cosine term was vacuous on non-negative GAP features (0.966 at epoch 1), exp 9's batch-standardised within-place variance penalty at weight 10 destroyed training outright (train top1 0.008 after 8 epochs, member 0 collapsed to a constant answer, xsurvey_agree 0.74 at top1 0.0003 - a training collapse, NOT a verdict on invariance; it is recorded here so it is not read as one), and exp 8's external teacher gave the student a target it could not reach (student-teacher cosine 0.40 against the 0.55 needed; the teacher's own cross-survey cosine was only 0.46-0.53). The common failure is the TARGET: a latent-consistency target can be satisfied for free or collapse, and a 22M-parameter teacher's semantics are not representable by a 1M-parameter CNN. This experiment gives the trunk a target that is survey-invariant BY CONSTRUCTION, cannot collapse, cannot be satisfied for free, and is trivially representable: the per-pixel median of the three training captures after per-survey global colour normalisation. The captures are pixel-aligned on one grid (<= 1 px), so at every pixel the median keeps the value two or three surveys agree on and discards whatever is unique to one photograph: a car, that survey's shadow where the other two are lit, one season's canopy, one year's construction, the leaning roof of the standard DOP against the two true orthos. Design-stage probe on the three TRAINING captures only (runs/_probe_exp10_canon.py, 300 random lattice places at random headings, 4 m/px standardised crops; truedop_2024 never opened): two real surveys of the same place correlate 0.575-0.622 with each other, while each survey correlates 0.812-0.851 with the composite - the composite is the picture the three photographs have in common, and it is much closer to every one of them than they are to each other, so a view from ANY survey can be asked to produce it; nearest-neighbour retrieval over the 300 places from one survey to the composite is 96-100% when aligned (and 12-20% under the eval's 12 px shift - shift tolerance remains the CNN's job, exactly as exp 6's probe found for survey-to-survey matching). Mechanism: a training-only decoder per member (two 3x3 convs with 2x upsampling, ~84k parameters, discarded before export) takes that member's 8x8x112 trunk feature map of its augmented own-survey view and must repaint the composite crop of the same position and heading at 32x32 (4 m/px), standardised per crop per channel so exposure and colour balance are not part of the target; MSE against it is added to the member's loss at weight 3. Each of the 64 feature cells then has to carry the stable coarse structure of its own 16 px patch (inside its 31 px receptive field - exp 5's 'bag of 31 m texture patches' becomes a bag of canonical-structure patches) and is paid nothing for carrying the survey-specific content the median removed; the pooled vector the cell head reads is a sum of exactly those descriptors. This is the library's L1-B (training-only reconstruction auxiliary, 'lives entirely in the never-flies lane') and L2's rule (predict a target that does not move; every expensive part is scaffolding dropped before export), re-aimed from lighting canonicalisation to survey canonicalisation, and it is the four-area era's exps 23/24/43 (redraw-the-clean-daytime-crop auxiliaries, verdicts void, measured on never-seen ground under a median metric) given a target that only this era's data asset makes possible: there was one photograph per place then, and a median needs three. It differs from exp 6 (blends as INPUTS: ghosted, physically meaningless frames the model had to classify) in that the composite is a TARGET and the inputs stay real photographs; from exp 8 in that the target is an image a two-layer decoder can certainly paint from 112-d local features, not a foundation model's semantics; and from exps 3/9 in that a fixed pixel-space target has no vacuous optimum (chance MSE is 1.0 by construction) and no collapsed one (a constant prediction scores exactly chance). The deployed graph is unchanged byte-for-byte (3,942,411 bytes).
Method
model/model.py: Member gains forward_train(x) -> (logits, offset, fmap) alongside the untouched forward(); a new training-only CanonDecoder (8x8x112 -> 32x32x3, not a submodule of CellLocNet, never exported) and constants CANON_PX = 32, RECON_WEIGHT = 3.0. model/train.py: after the training captures are resident on the device, build_canonical() computes once, from those captures only, the per-pixel per-channel median of the globally colour-normalised surveys as a uint8 [1,3,H,W] raster; per mini-batch the composite crop at the batch's own (cx, cy, heading) is cut with the existing gpu_crops(), average-pooled 4x to 32x32 and standardised per crop per channel; each member's own decoder repaints it from the fmap of that member's augmented view and MSE x 3.0 is added to the member's tent-CE + offset loss. Decoder parameters join the same Adam/cosine optimiser; per-member recon MSE is logged per epoch; export is unchanged.
Expected outcome
Mechanical checks that must hold or the mechanism did not bite: the logged per-member reconstruction MSE (chance = 1.0 by construction of the standardised target) falls below 0.5 for both members by epoch 8, with the loss falling monotonically; per-member augmented top1 ends within 0.05 of exp 7's 0.35 and the member agreement rate at or above 0.33 (the auxiliary must not have crowded out the cell task - exp 9's collapse signature, top1 near 0.001, would mean the weight is wrong, not that the idea is); exported bytes read exactly 3,942,411 and host latency ~2 ms (the deployed graph is untouched). Primary (held-out truedop_2024): 1.096 -> predicted 0.96-1.06, through usable_fix_rate for the first time since exp 5: 7.5% -> 10-15%, with false_fix_rate 17% -> 11-16% (members whose local descriptors encode the common picture agree on 2024 frames for the same reason they agree on training frames, so the confident set is enriched for correct fixes). 2024 coverage: 0.245 -> 0.27-0.38; the 0.2 FAIL floor is not expected to bind, because a shared canonical target should raise member agreement, not lower it. 2024 median error among confident frames (1,342 m) should fall below 800 m. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.833 / 0.845 / 0.703 on exp 7, usable 22 / 18 / 32%) are predicted to IMPROVE slightly to 0.60-0.80 (the auxiliary is also a regulariser for an underfit trunk, and the composite is 81-85% correlated with every training survey); the evidence that matters is the gap between those three numbers and the 2024 score narrowing, not the training numbers alone. Decision rules: (a) recon < 0.5 AND 2024 usable up by >= 3 points with false fix not rising -> supported; the next experiment either sharpens the target (64x64 at 2 m/px, or the composite's gradient-magnitude map so only edges count) or puts exp 5's whole-frame trunk on top, since its fit gain on the training surveys may now transfer. (b) recon < 0.5 but 2024 usable flat (<= 9%) -> the trunk carries the canonical structure for the decoder AND the survey cues for the head side by side in 112 dims; the next move is to make the head read the decoder's bottleneck (a capacity-allocation experiment), not another auxiliary. (c) recon stays >= 0.7 -> the decoder cannot paint 4 m/px structure from 31 px receptive-field features at weight 3, or the weight is too low; retry once with RECON_WEIGHT 10 before concluding anything (the term is bounded - MSE to a standardised target through a decoder - so, unlike exp 9's penalty, a 3x larger weight cannot produce a degenerate trunk). (d) 2024 coverage < 0.2 (FAIL) -> the auxiliary made the members disagree more on the foreign photograph; note it, and the next step is the same loss with the committee gate relaxed to the geometric mean of the two block masses, nothing else changed. Standing check: the score must move through usable_fix_rate; an improvement through false_fix_rate alone with usable flat means the composite taught honesty, not place - still kept, but rule (b) applies to the next design.
Result
mission score = 1.140627 (previous best 1.095578) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1.140627 vs best 1.095578); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 1,782–1,782 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
4.97 km
miss, this crop
0.07
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.1416% usablecov 0.27
Fits the aircraft?all deployment gates passed largest per-area model 3,850 KB (limit 4,096 KB) · single-frame inference 1.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
531 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 12 m 10 s · implement (Opus) 2 m 00 s · train 1 area 13 m 06 s · score 11 s · samples 4 s · publish 4 s · whole experiment 46 m 16 s
ts 2026-11-01T16:15:38 · commit ed3332a7d456 ·
parent 8ff675b454f1 · artifacts runs/20261101_152928_experiment10 ·
agent model — · took 46 m 10 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py230 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own conv trunk atMEMBER_CHANS + its own cell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.CANONICAL-COMPOSITE RECONSTRUCTION (capture-holdout era, experiment 10,training-only): train.py builds, once per run and from the TRAINING capturesonly, the per-pixel per-channel median of the globally colour-normalisedsurveys — a picture of the area in which anything seen in only one survey isgone. Each Member gets its own CanonDecoder (8x8x112 -> 32x32x3, two 3x3 convswith 2x upsampling) that must repaint that composite at the view's own positionand heading (avg-pooled to CANON_PX = 32, i.e. 4 m/px, standardised per crop perchannel) from the member's pre-pooling feature map (Member.forward_train); theMSE is added to the member's loss at RECON_WEIGHT. The decoders are notsubmodules of CellLocNet and are never exported: the deployed graph isunchanged. Design probe (training captures only, 4 m/px standardised crops):survey<->survey correlation 0.58-0.62, survey<->composite 0.81-0.85.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
MEMBER_CHANS =[3,24,48,96,112]# per-member trunk widths (size gate)
CANON_PX =32# composite target edge in px (128 px crop average-pooled 4x -> 4 m/px)
RECON_WEIGHT =3.0# weight of the reconstruction MSE per memberdef grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Member(nn.Module):"""One independent localizer: conv trunk -> GAP -> (C-way cell logits, within-cell offset)."""def __init__(self, n_cells: int, chans=MEMBER_CHANS):
super().__init__()
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1], n_cells)self.off_head = nn.Linear(chans[-1],2)def forward(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward_train(self, x):"""Training-only: (logits, offset, fmap) where fmap is the pre-pooling [B, 112, 8, 8] trunk feature map read by the CanonDecoder. forward() is deliberately left separate so the traced graph cannot change."""
fmap =self.features(x)# [B, 112, 8, 8]
f = fmap.mean(dim=(2,3))returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5, fmap
class CanonDecoder(nn.Module):"""Training-only: repaints the canonical composite crop (CANON_PX square, 3 channels, standardised) from a member's 8x8 feature map. Discarded before export; never a submodule of CellLocNet."""def __init__(self, cin=MEMBER_CHANS[-1]):
super().__init__()self.net = nn.Sequential(
nn.Conv2d(cin,64,3, padding=1), nn.BatchNorm2d(64), nn.ReLU(inplace=True),
nn.Upsample(scale_factor=2, mode="nearest"),# 8 -> 16
nn.Conv2d(64,32,3, padding=1), nn.BatchNorm2d(32), nn.ReLU(inplace=True),
nn.Upsample(scale_factor=2, mode="nearest"),# 16 -> 32
nn.Conv2d(32,3,3, padding=1))def forward(self, fmap):returnself.net(fmap)# [B, 3, 32, 32]def recon_loss_fn(pred: torch.Tensor, target: torch.Tensor)-> torch.Tensor:return F.mse_loss(pred, target)class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (logits, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(l, dim=1)for l,_in outs]
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py483 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.CANONICAL-COMPOSITE RECONSTRUCTION (experiment 10): build_canonical() computesonce, from the resident TRAINING captures only (load_scene never loads the evalcapture), the per-pixel per-channel median of the globally colour-normalisedsurveys — whatever only one photograph shows is gone. Per mini-batch thecomposite is cut at the batch's own (cx, cy, heading), average-pooled toCANON_PX and standardised per crop per channel; each member's own training-onlyCanonDecoder repaints it from that member's 8x8 feature map of its augmentedview, and RECON_WEIGHT x MSE is added to the member's loss. Decoders share theoptimiser, are never exported, and per-member recon MSE is logged per epoch(chance = 1.0 by construction of the standardised target).Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from PIL import Image
from model.model import(CANON_PX, CELL_PX, MEMBER_CHANS, N_MEMBERS,
RECON_WEIGHT, CanonDecoder, build_model, export_onnx,
grid_dims, loss_fn, recon_loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def build_canonical(scene_u8: torch.Tensor, area: str ="", slab: int =256)-> torch.Tensor:"""Per-pixel per-channel median of the globally colour-normalised TRAINING captures. scene_u8: uint8 [K,3,H,W] on the device — exactly what load_scene() loaded via buckets(meta, "train"); the eval capture is never in it. Returns uint8 [1,3,H,W] on the same device. Processed in row slabs so no float copy of a whole raster is ever resident."""
t0 = time.time()
K, C, H, W = scene_u8.shape
dev = scene_u8.device
# a. per-survey per-channel mean/std; per-slab sums in float32 then# accumulated on the CPU in float64 (MPS has no float64).
s1_64 = np.zeros((K, C), dtype=np.float64)
s2_64 = np.zeros((K, C), dtype=np.float64)for r in range(0, H, slab):
x = scene_u8[:,:, r:r + slab].float()
s1_64 += x.sum(dim=(2,3)).cpu().double().numpy()
s2_64 +=(x * x).sum(dim=(2,3)).cpu().double().numpy()
n = float(H * W)
mean64 = s1_64 / n
std64 = np.sqrt(np.maximum(s2_64 / n - mean64 **2,1e-6))
mean = torch.tensor(mean64, dtype=torch.float32, device=dev)
std = torch.tensor(std64, dtype=torch.float32, device=dev)
m_avg = mean.mean(0)
s_avg = std.mean(0)
out = torch.empty(1, C, H, W, dtype=torch.uint8, device=dev)for r in range(0, H, slab):
x = scene_u8[:,:, r:r + slab].float()
norm =((x - mean[:,:,None,None])/ std[:,:,None,None]* s_avg[None,:,None,None]+ m_avg[None,:,None,None])
med = norm.sort(dim=0).values[K //2]
out[0,:, r:r + slab]= med.clamp(0,255).round().to(torch.uint8)
print(f"[{area}] canonical composite built from {K} training captures in "
f"{time.time()- t0:.1f}s, channel means={[round(v,2)for v in m_avg.cpu().tolist()]}",
flush=True)return out
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, canon, decoders, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
decoders.train()
recon_sum = torch.zeros(N_MEMBERS, device=device)
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])# Canonical composite target at the same geometry, computed once# per mini-batch and shared by both members (clean, unaugmented).
tgt = gpu_crops(canon, torch.zeros_like(cap_b), cx[idx], cy[idx], ang[idx])
tgt = F.avg_pool2d(tgt, CROP_PX // CANON_PX)# [B,3,32,32]
tgt =(tgt - tgt.mean(dim=(2,3), keepdim=True))/ \
(tgt.std(dim=(2,3), keepdim=True)+0.02)
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]
rec_terms =[]for k, member in enumerate(model.members):
xb_k = augment_views(xb0)
logits_k, off_k, fmap_k = member.forward_train(xb_k)
off_t_k = residual_offset_target(model, logits_k, pb, meta)
rec_k = recon_loss_fn(decoders[k](fmap_k), tgt)
loss = loss + loss_fn(logits_k, off_k, soft_t, off_t_k)+ RECON_WEIGHT * rec_k
member_logits.append(logits_k)
rec_terms.append(rec_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():for k, rec_k in enumerate(rec_terms):
recon_sum[k]+= rec_k.detach()* B
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree),"recon_sum": recon_sum.cpu().tolist()}def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)# Created AFTER build_model so the members' seeded init is unchanged.
decoders = nn.ModuleList(CanonDecoder()for_in range(N_MEMBERS)).to(device)
opt = torch.optim.Adam(list(model.parameters())+ list(decoders.parameters()),
lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
canon = build_canonical(scene, area)
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0
final_recon =[1.0]* N_MEMBERS
for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh, canon, decoders)
sched.step()
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
final_recon =[round(r / max(seen,1),4)for r in stats["recon_sum"]]
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"recon={final_recon}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""canonical-composite reconstruction auxiliary per member"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"member_chans": MEMBER_CHANS,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"recon_weight": RECON_WEIGHT,"canon_px": CANON_PX,"final_recon": final_recon,"canonical_target":("per-pixel per-channel median of the globally colour-normalised ""TRAINING captures, cut at the view geometry, avg-pooled to 32x32, ""standardised per crop per channel; decoder training-only, never exported"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Within-place variance penalty: each member's pooled feature of one place, standardised against its spread across places, must be the same in all three surveys 0000746a
not one usable fix
loss
gated fail
32 m 26 s
$7.67
gated fail
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Each of the UAV's two navigators boils a photo down to a short description of the place it is looking at - 112 numbers. We checked what happens to that description when the SAME spot is shown in two of the training photographs taken in different years: it changes by about a third of the amount it would change if you showed a completely different place, and most of that change is season and shadow, not geography. So the navigators have partly been describing the photograph rather than the ground, and a brand-new photograph gets a description that matches nowhere. The fix is a rule during training: every time a spot is shown in all three photographs at once, the three descriptions must come out the same, judged against how much descriptions differ between places. Whatever in a description tracks the time of year gets squeezed out; whatever tracks the streets and buildings stays. Nothing the UAV carries changes - only what it was taught to pay attention to.
What it cost
design agent
$5.39
figure agent
$1.32
implementation agent
$0.96
total
$7.67
by model — claude-fable-5-1 $5.39 · claude-sonnet-5 $1.32 · claude-opus-5-5 $0.96
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it failed the gate
The model trained, but on the held-out photograph it did not produce a single usable fix — it either stayed silent on every frame or was wrong every time it answered. Silence alone scores 1.0, so a model like this could otherwise win just by saying nothing; it is scored as a failure instead, and was rolled back.
Hypothesis
The held-out 2024 photograph's usable-fix rate has sat at 7-12.5% through seven designs because the deployed feature of a place still changes with the survey, and no experiment has yet actually forbidden that. Experiment 3 tried (cosine between L2-normalised GAP features of the same position in different surveys) and was reverted, but a design-stage probe on the current champion's exported graph shows its metric could never have bitten: the RAW cosine between the pooled features of two DIFFERENT places is 0.70 (runs/_probe_exp9_wpv.py, 400 lattice positions, three TRAINING captures only, truedop_2024 never opened), because post-ReLU average-pooled features share a large positive common component. A same-place cross-survey cosine of 0.966 at epoch 1 and 0.935 at the end therefore meant 'the features are post-ReLU', not 'the three surveys agree' - and experiment 6 dismissed feature invariance on exactly that misreading ('the three training appearances were mapped to nearly the same vector'). Measured properly, with the batch mean removed, the champion's same-place cross-survey cosine is 0.69 and different-place is 0.00; as a within-place variance fraction of the per-dimension standardised feature (0 = identical feature in all surveys, 1 = a survey change moves the feature as far as a change of place), the three training surveys read 0.295, versus 0.152 for two independent draws of the photometric augmentation on one survey - the kept exposure/sharpness randomisation (exp 4) covers only half of what a change of survey does to the feature, and nothing in the training signal addresses the other half. The consequence is visible in the same probe: the SAME member, shown the SAME place at the SAME heading in two training surveys, names the same cell only 28-40% of the time (per-survey top1 34-46%), so even on photographs it trained on, the committee's agreement gate is largely gating survey-driven feature drift, not place knowledge; on a fourth survey the drift is at least as large and the cell beliefs land elsewhere. The remedy is the library's L2 rank-1 mechanism (cross-survey latent consistency, SSL4EO's top rung) implemented so that it cannot be satisfied for free: standardise every dimension of each member's 112-d pooled feature over the mini-batch (zero mean, unit variance), then penalise the variance that remains WITHIN a position across its three surveys' views, scaled so unrelated views read 1.0. Standardisation per dimension means a feature dimension that mostly encodes survey state (canopy greenness, shadow strength, colour pipeline) has within-place variance near its total variance and is penalised hardest, while a dimension that encodes place is nearly free - the trunk is pushed, over 218k paired views per epoch and all 2,970 places at once, to discard the directions along which the three surveys differ and keep the ones along which places differ. That is the domain-generalisation bet of this era stated as a loss: the fourth survey's deviations (season, sun angle, cars, pipeline) are assumed to lie largely in the span of the deviations between a summer standard DOP, a leaf-off true-ortho and an early-spring true-ortho, and a feature made invariant to that span transfers. No projector (a projector would let the deployed feature keep survey content and discard it only downstream, the opposite of what the linear cell head needs), no stop-gradient (the batch standard deviation in the denominator carries gradient on purpose: it is VICReg's variance term in disguise, and the 2,970-way cross-entropy on the same vector makes collapse impossible). It is one loss term on the existing committee; the exported graph is byte-identical.
Method
Add INV_WEIGHT * invariance_loss(feat_k, n_caps) to each committee member's loss in model/train.py, where feat_k is that member's post-ReLU global-average-pooled 112-d trunk feature (the exact tensor its cell head reads) and invariance_loss standardises every dimension over the mini-batch, groups the rows by lattice position (all three training surveys of one position, same heading, independent photometric draws), and returns the within-position variance fraction scaled by K/(K-1). Mini-batches are rebuilt position-grouped (21 positions x 3 captures = 63 views, position-major rows) so every position in a batch is present in all three surveys - the same batching experiment 3 used, now on the device-side gpu_crops path. INV_WEIGHT = 10.0. Member.forward additionally returns the feature; CellLocNet.forward (the deployed decode) is unchanged and the ONNX must still read 3,942,411 bytes. Logged per epoch and per member: the mean within-place variance fraction (inv) and the cross-survey argmax agreement rate (fraction of positions on which the member names the same cell in all three surveys).
Expected outcome
Mechanical checks that must hold or the mechanism did not bite: the logged per-member within-place variance fraction (inv) falls from its epoch-1 value (predicted 0.35-0.50 on augmented views; the trained champion reads 0.295 on clean crops) to below 0.10 by epoch 8 for both members, and the logged cross-survey argmax agreement rises from ~0.3 (the champion's 0.28-0.40 on clean crops) to within 0.05 of each member's top1 - i.e. when a member knows a place it knows it in every survey. Exported bytes read exactly 3,942,411 and host latency ~2 ms. Primary (held-out truedop_2024): 1.096 -> predicted 0.95-1.06, for the first time in this era through usable_fix_rate: 7.5% -> 11-18%, with false_fix_rate 17% -> 12-17% (members whose features are survey-invariant agree on 2024 frames for the same reason they agree on training frames, so the confident set is enriched for correct fixes). 2024 coverage: 0.245 -> 0.28-0.40; the 0.2 FAIL floor is the explicit risk of adding a constraint to already-underfit members and is flagged, not hidden. 2024 median error among confident frames (1,342 m) should fall below 700 m. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.833 / 0.845 / 0.703 on exp 7, usable 22 / 18 / 32%) are predicted to stay within 0.65-0.90 and may drift slightly worse: the easiest fit is forbidden, so train top1 under augmentation will read a little below exp 7's 0.35 per member; the evidence is the 2024-vs-training gap narrowing, not the training numbers. Decision rules: (a) inv < 0.10 AND 2024 usable up by >= 3 points with false fix not rising -> supported; feature invariance across three surveys reaches a fourth, and the next experiment restores fit on top of it (experiment 5's whole-frame trunk per member, which lifted training-survey usable to 72-81% but had nothing invariant to carry) or adds +-12 px vantage jitter. (b) inv < 0.10 but 2024 usable flat (<= 9.5%) -> invariance across THESE three surveys, genuinely achieved this time, does not transfer to a fourth; close the cross-survey consistency family for this era (this is the fair test experiments 3 and 6 were not) and move to vantage jitter, the mapping/query confidence split, or capacity. (c) inv stays >= 0.20 at INV_WEIGHT 10 -> the cross-entropy out-muscled the term again; rerun once with INV_WEIGHT 30 before concluding anything. (d) 2024 coverage < 0.2 (FAIL) -> the constraint made the members disagree more on the foreign photograph, not less; note it, and the next step is the same loss with the committee gate relaxed to the geometric mean, nothing else changed. Standing check: the score must move through usable_fix_rate; an improvement through false_fix_rate alone with usable flat means the term taught honesty, not place - still kept, but rule (b) applies to the next design.
Result
mission score = 1000000000.0 (previous best 1.095578) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1000000000.0 vs best 1.095578); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlin
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
1.75 km
miss, this crop
0.00
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.0000% usablecov 0.00
Fits the aircraft?all deployment gates passed largest per-area model 3,850 KB (limit 4,096 KB) · single-frame inference 1.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
410 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 10 m 53 s · implement (Opus) 2 m 02 s · train 1 area 12 m 02 s · score 12 s · samples 4 s · publish 3 s · whole experiment 32 m 32 s
ts 2026-11-01T15:29:03 · commit 0000746a3b4c ·
parent 8389b9c7868f · artifacts runs/20261101_145637_experiment9 ·
agent model — · took 32 m 26 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py215 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own conv trunk atMEMBER_CHANS + its own cell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.CROSS-SURVEY INVARIANCE TERM (experiment 9): during training each member'spost-ReLU global-average-pooled feature (the exact [B, 112] tensor its twoheads read, now also returned by Member.forward) is penalised byINV_WEIGHT * invariance_loss(): every feature dimension is standardised overthe mini-batch, rows are grouped by lattice position (the same position in alltraining surveys, same heading, independent photometric draws), and the lossis the within-position variance fraction scaled by K/(K-1) — 0 when a placeyields the same feature in every survey, 1 when a change of survey moves thefeature as far as a change of place. Training only; the deployed decode andthe exported graph are unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
MEMBER_CHANS =[3,24,48,96,112]# per-member trunk widths (size gate)
INV_WEIGHT =10.0# weight of the cross-survey invariance loss (training only)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Member(nn.Module):"""One independent localizer: conv trunk -> GAP -> (C-way cell logits, within-cell offset)."""def __init__(self, n_cells: int, chans=MEMBER_CHANS):
super().__init__()
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1], n_cells)self.off_head = nn.Linear(chans[-1],2)def forward(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.# f (post-ReLU GAP feature) is returned for the invariance loss.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5, f
class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (logits, offset, feat) triples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(l, dim=1)for l,_,_in outs]
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o,_in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def invariance_loss(feat: torch.Tensor, n_caps: int, eps: float =1e-5)-> torch.Tensor:"""Cross-survey within-place variance fraction. feat is [P*K, D] with rows POSITION-MAJOR (row p*K + k = position p, capture k). Standardise every dimension over the whole batch, group into [P, K, D], and return the mean squared deviation from each position's own mean, scaled by K/(K-1) so unrelated views read 1.0 and identical views read 0.0. No detach anywhere: the batch std in the denominator carries gradient on purpose (VICReg's variance term in disguise); the cross-entropy on the same vector prevents collapse. K < 2 -> 0."""if n_caps <2:return feat.new_zeros(())
z =(feat - feat.mean(dim=0, keepdim=True))/(feat.std(dim=0, keepdim=True)+ eps)
z = z.view(-1, n_caps, feat.shape[1])
within =((z - z.mean(dim=1, keepdim=True))**2).mean()return within *(n_caps /(n_caps -1))def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py453 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.CROSS-SURVEY INVARIANCE (experiment 9): mini-batches are now POSITION-GROUPED —pos_per_batch = BATCH_SIZE // n_caps lattice positions (21 for three captures,63 views), each present in every training capture, rows position-major — andeach member's loss adds INV_WEIGHT * invariance_loss(feat_k, n_caps) on itspost-ReLU pooled feature: every dimension standardised over the batch, thewithin-position variance fraction across surveys (0 = same feature in everysurvey, 1 = a survey change moves it as far as a change of place). Experiment3's raw-cosine version of this idea was vacuous: post-ReLU GAP features of twoDIFFERENT places already have cosine ~0.70 from their shared positive commoncomponent, so a high same-place cosine said nothing; standardising perdimension first removes that component. Logged per epoch and per member: themean within-place variance fraction (inv) and the cross-survey argmaxagreement (fraction of positions on which the member names the same cell inall training surveys).Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, INV_WEIGHT, MEMBER_CHANS, N_MEMBERS,
build_model, export_onnx, grid_dims, invariance_loss,
loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
inv_sum = torch.zeros(N_MEMBERS, device=device)
xagree = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
xagree_seen =0
seen =0# Position-grouped mini-batches: every position in a batch appears in all# n_caps training captures (21 positions x 3 captures = 63 views).
pos_per_batch = max(1, BATCH_SIZE // n_caps)
cap_off = torch.arange(n_caps, device=device)
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)# chunk_views rows are position-major: row p*n_caps + k = position p, capture k.assert n ==(n // n_caps)* n_caps
n_pos = n // n_caps
pos_perm = torch.randperm(n_pos, device=device)for i in range(0, n_pos, pos_per_batch):
pidx = pos_perm[i:i + pos_per_batch]
idx =(pidx.unsqueeze(1)* n_caps + cap_off).reshape(-1)
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]
member_inv =[]for member in model.members:
xb_k = augment_views(xb0)
logits_k, off_k, feat_k = member(xb_k)
off_t_k = residual_offset_target(model, logits_k, pb, meta)
inv_k = invariance_loss(feat_k, n_caps)
loss = loss + loss_fn(logits_k, off_k, soft_t, off_t_k)+ INV_WEIGHT * inv_k
member_logits.append(logits_k)
member_inv.append(inv_k.detach())
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
inv_sum += torch.stack(member_inv)* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
ag = a.view(-1, n_caps)
xagree[k]+=(ag == ag[:,:1]).all(dim=1).long().sum()
xagree_seen += B // n_caps
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree),"inv_sum": inv_sum.cpu().tolist(),"xagree": xagree.cpu().tolist(),"xagree_seen": xagree_seen}def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0
final_inv =[0.0]* N_MEMBERS
final_xagree =[0.0]* N_MEMBERS
for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
final_inv =[round(s / max(seen,1),4)for s in stats["inv_sum"]]
final_xagree =[round(c / max(stats["xagree_seen"],1),4)for c in stats["xagree"]]
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"inv={final_inv} xsurvey_agree={final_xagree}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""cross-survey within-place variance penalty on each member's pooled feature"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"member_chans": MEMBER_CHANS,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"invariance_weight": INV_WEIGHT,"final_invariance": final_inv,"final_xsurvey_agree": final_xagree,"batching":("position-grouped: every position in a mini-batch appears in all ""training captures (position-major rows)"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Cross-survey DINOv2 distillation: each member's 8x8 feature map must reproduce a frozen foundation-model teacher's description of the SAME place photographed in a DIFFERENT survey (training-only; the teacher never flies) 5ee860df
worse than champion: 1.121 vs 1.096
loss
1.121
190 m 59 s
$7.15
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
We hired a tutor. A large, freely licensed vision model that has already looked at hundreds of millions of photographs describes a scene by its roads, buildings and water, not by the colour cast, the season or where the shadows fall. During training only, our tiny navigator is shown one survey's photo of a spot and asked to produce the description the tutor gives for a DIFFERENT survey's photo of that same spot, so anything that changes between surveys is useless to it and only the layout pays. A measurement on the three training surveys shows the tutor recognises a place across surveys even when the view is shifted 12 m, where raw pixels fail nine times out of ten. The tutor never flies: what stays on the UAV is exactly the same small model as before, now trained to see the city the way the tutor does.
What it cost
design agent
$6.15
implementation agent
$1.00
total
$7.15
by model — claude-fable-5-1 $6.15 · claude-opus-5-5 $1.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 1.121 it didn't beat the champion's 1.096, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Through seven experiments on this ruler the held-out 2024 photograph's usable-fix rate has never left the 7-12.5% band (exp 2: 7.0%, exp 4: 11.75%, exp 5: 12.5%, exp 6: 11.0%, exp 7: 7.5%) while everything around it moved: experiment 5 lifted the TRAINING photographs to 72-81% usable at the same held-out viewpoints and 2024 did not budge, and experiment 7's committee gate cut 2024 false fixes from 38.75% to 17% but, with coverage now 0.245 (floor 0.2), there is almost nothing left to convert. The score is 0.925 + 0.17 and the 0.925 is the whole problem: the deployed trunk, trained only on three photographs, does not produce a place description that a fourth photograph reproduces. Three in-domain surveys evidently do not teach that on their own (exp 3's agreement term was vacuous, exp 6's blends were reverted, exp 4's photometrics helped once), and every mechanism tried so far derived the representation from the three photographs themselves. This experiment imports one from outside: DINOv2 ViT-S/14 with registers (Apache-2.0, 22M parameters, library L2 rank 3, the 'largest documented effect in the scene-coordinate literature' per R-SCoRe/ACE-G) is used as a frozen TRAINING-ONLY teacher, and each committee member's 8x8 trunk feature map is trained, through a training-only projector, to match the teacher's 8x8 patch-token grid of the same position and heading in a DIFFERENT training survey (TSCM's cross term). Design-stage evidence, measured on the three TRAINING captures only (runs/_probe_exp8_dinov2.py, 300 random lattice places, teacher at 112 px, nearest-neighbour place retrieval across surveys; the 2024 capture was never opened): with the raw pixels, experiment 6's probe found a place across surveys 90-97% of the time when pixel-aligned but 7-11% under a 12 px shift and 1% under shift+rotation. DINOv2's centred patch grid finds it 95.2% aligned, 70.4% under the same 12 px shift (7-10x the pixel figure) and 22.9% under shift+rotation (23x), and the teacher's own cross-survey cosine between the same place in two surveys is 0.46-0.53 against 0.05 for different places. So the teacher's description of a place survives a change of survey AND the off-lattice shift the eval imposes, which the raw pixels do not; rotation tolerance is not in the teacher and stays the student's job (it trains under random headings, as before). The cross-survey pairing is what makes the target survey-invariant rather than merely semantic: the student sees survey A's augmented crop and must produce what the teacher says about survey B's clean crop of the same ground, so canopy, shadow direction, cars and colour pipeline, which differ between A and B, cannot help it and the shared geometry can. The student is the SAME exported model as experiment 7 (3,942,411 bytes); only the training loss changes. Two known limits are honest unknowns: whether a 0.97M-parameter two-member student can absorb enough of a 22M teacher's geometry (no published distillation result below 4M parameters), and whether the 14 m patch granularity at 112 px is right for a 128 m cell head. Cost: the teacher runs online, no cache; a ViT-S forward at 112 px is ~2.9 GFLOP, ~0.6 PFLOP per epoch of 218k views, a few tens of seconds on the L4 the loop trains on (REMOTE_TRAIN=1); measured 296 img/s on the M1 (12 min/epoch) if a run ever falls back to local training.
Method
ONE change: add a training-only cross-survey feature-distillation loss. (1) model/model.py: Member exposes feature_map(x) -> [B,112,8,8] (its conv stack before global average pooling); forward() is unchanged in effect (GAP of that map). Nothing in the exported graph changes. (2) model/train.py: load DINOv2 ViT-S/14-reg via torch.hub (frozen, eval, no grad; fp16 autocast on CUDA). Per mini-batch, besides each member's own augmented crop of its survey, cut the SAME position and heading from a different training capture (partner = (cap + randint(1, n_caps)) % n_caps), feed the clean partner crop to the teacher at 112 px (ImageNet-normalised) and take its 64 patch tokens as an [B,384,8,8] grid, batch-centred and L2-normalised per position. Each member gets a training-only projector (1x1 conv 112->512, ReLU, 1x1 conv 512->384, DisCo-wide) on its feature map of the AUGMENTED own-survey crop; loss_k += DISTILL_WEIGHT * mean over B x 8 x 8 of (1 - cosine(projected student, teacher target)). DISTILL_WEIGHT = 5.0. Projectors are optimised with the model and discarded at export. The committee, paired-survey interleave, photometric augmentation, tent targets, offset targets, schedule and views per epoch are unchanged.
Expected outcome
Primary (held-out truedop_2024): 1.096 -> predicted 0.90-1.03, and for the first time in this era through usable_fix_rate: 7.5% -> 12-20%, with false_fix_rate 17% -> 10-16% (frames the two members now agree on are enriched for frames where survey-invariant geometry names the cell). 2024 coverage rises from 0.245 to 0.30-0.45 as the members, trained toward one external description, agree more often; the 0.2 FAIL floor is therefore not expected to bind, and if coverage FALLS the mechanism did not transfer. 2024 median error among confident frames (1,342 m) should drop below 600 m. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.833 / 0.845 / 0.703 on exp 7, usable 22 / 18 / 32%) are predicted to IMPROVE to 0.55-0.75 each (usable 30-45%), because a semantic target is also an easier fit than 2,970 classes from scratch; the evidence that matters is the gap between those three numbers and the 2024 score narrowing, not the training numbers alone. Mechanical checks that must hold or the mechanism did not bite: the logged per-member student-teacher cosine (centred, mean over positions) ends above 0.55 for both members (the teacher's own cross-survey floor is 0.46-0.53, so matching the cross-survey target at that level means the student has reached the teacher's invariant part); the logged distillation loss falls monotonically; exported bytes read exactly 3,942,411 and host latency ~2 ms (the deployed graph is untouched); per-member top1 and agree_rate end at or above exp 7's 0.35 / 0.35. Decision rules: (a) 2024 usable up by >= 4 points with false fix not rising -> supported; the next experiment raises the teacher's granularity (224 px input, 16x16 tokens pooled to 8x8, or a stride-8 tap) or widens the student. (b) student-teacher cosine > 0.55 but 2024 usable flat (<= 10%) -> the teacher's 14 m geometry does not carry place identity through this student; the next move is the mapping/query confidence split (library L2 #6) or +-12 px vantage jitter, not more distillation. (c) cosine stays < 0.4 at weight 5 -> the student cannot absorb the target; retry once with DISTILL_WEIGHT 20 and a wider projector before concluding anything. (d) training fails on the teacher download (torch.hub needs GitHub + dl.fbaipublicfiles.com from the AWS box; pip install already proves egress) -> infrastructure, not a verdict; rerun. Standing check: the score must move through usable_fix_rate; if it improves only through false_fix_rate with usable flat, the teacher taught honesty, not place, and that is still a kept improvement but rule (b) applies.
Result
mission score = 1.12059 (previous best 1.095578) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1.12059 vs best 1.095578); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 1,476–1,476 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
2.87 km
miss, this crop
0.17
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.1219% usablecov 0.30
Fits the aircraft?all deployment gates passed largest per-area model 3,850 KB (limit 4,096 KB) · single-frame inference 1.9 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
769 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 117 m 27 s · implement (Opus) 1 m 46 s · train 1 area 17 m 43 s · score 11 s · samples 4 s · publish 4 s · whole experiment 191 m 05 s
ts 2026-11-01T14:56:09 · commit 5ee860df737d ·
parent 454ff5642156 · artifacts runs/20261101_114510_experiment8 ·
agent model — · took 190 m 59 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py197 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own conv trunk atMEMBER_CHANS + its own cell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.CROSS-SURVEY DINOv2 DISTILLATION (experiment 8): Member.feature_map() exposeseach member's 8x8 conv map before global average pooling so train.py candistil a frozen DINOv2 ViT-S/14-reg teacher's patch tokens into it. Theteacher and the per-member projectors live ONLY in train.py and never enterthe export: forward() computes exactly what it did before, so the deployedgraph is unchanged.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
MEMBER_CHANS =[3,24,48,96,112]# per-member trunk widths (size gate)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Member(nn.Module):"""One independent localizer: conv trunk -> GAP -> (C-way cell logits, within-cell offset)."""def __init__(self, n_cells: int, chans=MEMBER_CHANS):
super().__init__()
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1], n_cells)self.off_head = nn.Linear(chans[-1],2)def feature_map(self, x):"""[B, chans[-1], 8, 8] conv map before global average pooling (read by the training-only distillation loss)."""returnself.features(x)def forward(self, x):
f =self.feature_map(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (logits, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(l, dim=1)for l,_in outs]
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py520 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.CROSS-SURVEY DINOv2 DISTILLATION (experiment 8): a frozen DINOv2 ViT-S/14with registers (Apache-2.0, torch.hub facebookresearch/dinov2) is aTRAINING-ONLY teacher. For every mini-batch the SAME position and heading iscut from a DIFFERENT training capture (the partner survey), clean, and fed tothe teacher at 112 px, whose 8x8 patch-token grid is the target. Eachmember's 8x8 feature map of its AUGMENTED own-survey crop goes through atrain-only 1x1-conv projector and is pulled toward that target by(1 - cosine) per position, weighted DISTILL_WEIGHT. The partner is a differentsurvey so canopy, shadows, cars and colour pipeline — which differ betweensurveys — cannot help the student match the target; only shared geometry can.The teacher tokens are batch-centred before L2 normalisation so the commontoken component cannot make the cosine vacuous (experiment 3's lesson). Theteacher and the projectors are discarded at export (the deployed graph isunchanged); no teacher weight file is kept in the repo — torch.hub's owncache is used. Per-member distillation loss and student-teacher cosine arelogged per epoch.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, MEMBER_CHANS, N_MEMBERS, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)# Training-only cross-survey distillation teacher (never exported).
TEACHER_HUB =("facebookresearch/dinov2","dinov2_vits14_reg")
TEACHER_RES =112# 112/14 = 8 patch tokens per side == the student's 8x8 map
TEACHER_DIM =384
PROJ_WIDTH =512
DISTILL_WEIGHT =5.0
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)def load_teacher(device, area=""):"""Frozen DINOv2 ViT-S/14-reg from torch.hub's own cache (downloaded on first use). Training only; never exported."""
t = torch.hub.load(*TEACHER_HUB, trust_repo=True)
t.eval()for p in t.parameters():
p.requires_grad_(False)
n = sum(p.numel()for p in t.parameters())/1e6
print(f"[{area}] teacher dinov2_vits14_reg loaded, {n:.1f}M params, frozen, "
f"res {TEACHER_RES}", flush=True)return t.to(device)def teacher_targets(teacher, x_clean, mean, std):"""x_clean: float [B,3,128,128] in [0,1] on the device (UNaugmented). Returns [B, TEACHER_DIM, 8, 8]: batch-centred, L2-normalised per position patch tokens."""
B = x_clean.shape[0]
y = F.interpolate(x_clean, size=(TEACHER_RES, TEACHER_RES), mode="bilinear",
antialias=True, align_corners=False)
y =(y - mean)/ std
g = TEACHER_RES //14with torch.no_grad():if y.device.type=="cuda":with torch.autocast("cuda", dtype=torch.float16):
tok = teacher.forward_features(y)["x_norm_patchtokens"]else:
tok = teacher.forward_features(y)["x_norm_patchtokens"]
tok = tok.float()# [B, 64, 384]
t = tok.transpose(1,2).reshape(B, TEACHER_DIM, g, g)# Batch-centre: remove the common token component so the cosine is# not vacuous (experiment 3's lesson).
t = t - t.mean(dim=(0,2,3), keepdim=True)return F.normalize(t, dim=1)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, projectors, teacher, t_mean, t_std,
max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
distill_sum = torch.zeros(N_MEMBERS, device=device)
cos_sum = torch.zeros(N_MEMBERS, device=device)
projectors.train()
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)# Cross-survey teacher target: SAME position and heading, cut# clean from a DIFFERENT training capture (single-capture areas# distil from the same crop). Shared by both members.if n_caps >1:
cap_p =(cap_b + torch.randint(1, n_caps,(B,), device=device))% n_caps
else:
cap_p = cap_b
xb_p = gpu_crops(scene, cap_p, cx[idx], cy[idx], ang[idx])
tgt = teacher_targets(teacher, xb_p, t_mean, t_std)
loss = torch.zeros((), device=device)
member_logits =[]for k, member in enumerate(model.members):
xb_k = augment_views(xb0)
fmap_k = member.feature_map(xb_k)
f_k = fmap_k.mean(dim=(2,3))
logits_k = member.cls_head(f_k)
off_k = torch.tanh(member.off_head(f_k))*0.5# == Member.forward
z_k = F.normalize(projectors[k](fmap_k), dim=1)
cos_k =(z_k * tgt).sum(dim=1)# [B,8,8]
distill_k =(1.0- cos_k).mean()
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(logits_k, off_k, soft_t, off_t_k) \
+ DISTILL_WEIGHT * distill_k
member_logits.append(logits_k)
distill_sum[k]+= distill_k.detach()* B
cos_sum[k]+= cos_k.detach().mean()* B
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree),"distill": distill_sum.cpu().tolist(),"cos": cos_sum.cpu().tolist()}def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)# Training-only projectors (one per member), discarded at export.
projectors = nn.ModuleList(
nn.Sequential(nn.Conv2d(MEMBER_CHANS[-1], PROJ_WIDTH,1), nn.ReLU(inplace=True),
nn.Conv2d(PROJ_WIDTH, TEACHER_DIM,1))for_in range(N_MEMBERS)).to(device)
teacher = load_teacher(device, area)
t_mean = torch.tensor(IMAGENET_MEAN, device=device).view(1,3,1,1)
t_std = torch.tensor(IMAGENET_STD, device=device).view(1,3,1,1)
opt = torch.optim.Adam(list(model.parameters())+ list(projectors.parameters()),
lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0
final_distill =[0.0]* N_MEMBERS
final_cos =[0.0]* N_MEMBERS
for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh, projectors, teacher,
t_mean, t_std)
sched.step()
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
final_distill =[round(d / max(seen,1),4)for d in stats["distill"]]
final_cos =[round(c / max(seen,1),4)for c in stats["cos"]]
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f} "
f"distill={final_distill} student_teacher_cos={final_cos}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,# §9: log init strategy per experiment"init":"from-scratch (student); training-only teacher pretrained:dinov2_vits14_reg","n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member, ""cross-survey DINOv2 patch distillation"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"member_chans": MEMBER_CHANS,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,"distillation":{"teacher":"dinov2_vits14_reg (torch.hub facebookresearch/dinov2, Apache-2.0)","teacher_res": TEACHER_RES,"teacher_dim": TEACHER_DIM,"proj_width": PROJ_WIDTH,"weight": DISTILL_WEIGHT,"target":("batch-centred L2-normalised patch tokens of the SAME position+heading ""in a DIFFERENT training capture (clean crop)"),"student_input":"augmented own-survey crop",},"final_distill_loss": final_distill,"final_student_teacher_cos": final_cos,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Two-member committee: two independently trained localizers must agree before a fix is trusted; confidence is the smaller of the two members' belief on the consensus block 5a0a4962
new best: 1.271 → 1.096
architecture
1.096
43 m 44 s
$8.27
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Instead of one navigator the UAV now carries two, trained separately on the same three photographs of Berlin: each starts from a different random state and sees every training picture under its own random lighting and blur, so each picks up its own habits and blind spots. When a brand-new photograph fools a navigator, it tends to fool each one differently, so they point at different places; the UAV then says 'not sure' and waits for the next frame instead of flying on a wrong fix. Only when both navigators point at the same place does the UAV accept it. It is the same reason you ask two witnesses separately: two independent accounts that agree are worth far more than one confident voice.
What it cost
design agent
$4.63
figure agent
$2.79
implementation agent
$0.85
total
$8.27
by model — claude-fable-5-1 $4.63 · claude-sonnet-5 $2.79 · claude-opus-5-5 $0.85
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 1.271 to 1.096 — 0.175 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
The stage no experiment in this era has questioned is the confidence gate, and it is where the score is being lost. On the held-out 2024 photograph the false-fix rate has sat at 39-43% through three different training designs (exp 4: 38.75%, exp 5: 42.25%, exp 6: 43.0%) while usable sat at 12-14%; false fixes cost three times what usable fixes earn, and converting a false fix into an abstention is worth exactly as much to the mission score as finding a new usable fix. The single model's confidence is the pooled softmax mass of one classifier trained only on photographs it has memorised, so on a photograph it has not seen it is uninformative by construction: the founding measurement showed the 0.040 champion 97% confident while wrong, with 390 confident predictions on a foreign photograph collapsing onto 40 cells. That is the signature of a model that, given a foreign input, slides into whichever survey-specific shortcut the input happens to trigger. A different model, trained from a different random start on differently drawn augmentations, has different shortcuts and slides into different cells for the same foreign frame, while on frames where the shared street-and-building geometry genuinely names the cell both models land on the same block. Disagreement between independently trained models is the one uncertainty estimator the literature finds robust under dataset shift (deep ensembles, Lakshminarayanan et al. 2017; Ovadia et al. 2019 measured it dominating every learned or post-hoc calibrated single-model confidence as shift grows): it is epistemic uncertainty, which is what a never-seen survey produces, not aleatoric. The library (L2) lists learned aleatoric confidence as what does NOT transfer under map change, and the earlier eras' two honesty attempts were exactly that kind: four-area exp 15 (a field-shape confidence head) and exp 32 (abstention thresholds calibrated on never-trained blocks) re-score at 1.85 and 1.77 on this ruler, 85% and 77% false fix. No era has tried an ensemble (nothing in lineage_history mentions one). This is also materially different from the decode-time consensus the Prignitz detour refuted: that averaged ONE model's belief over four rotations of the same frame, and a wrong answer that is rotation-stable survives it; here two separately trained models are asked the same question, and a wrong answer must be shared by both to survive. Cost, measured at design time without training (runs/_probe_exp7_committee.py): two members with trunk widths [3,24,48,96,112] export to 3,942,411 bytes (3.76 MiB, under the 4 MiB gate) at 1.97 ms host latency, 971,864 parameters, versus the single 160-wide model's 3,080,677 bytes and 1.49 ms. Each member is narrower than today's single model (head 112x2970 = 333k vs 475k), so per-member fit on the training photographs will be somewhat lower; the committee's averaged belief is expected to recover most of it. The design is honest about what it targets: it attacks the false-fix term, not the usable term, and it is the gate every later accuracy experiment will also need.
Method
ONE change: model/model.py's CellLocNet becomes a committee of N_MEMBERS = 2 fully independent members (each = the current 4-stage stride-2 conv trunk at chans [3,24,48,96,112] + its own 2970-way cell head + its own offset head; no shared weights). Deployed decode in forward(): per-member softmax p_k; averaged belief pbar = mean_k p_k; argmax cell of pbar; the existing 3x3 block mask around it; conf = min over members of (p_k * mask).sum() - each member must independently put its belief on the consensus block; the fix is pbar's mass-weighted centroid of the block plus the mean of the members' offsets. Training (model/train.py): each mini-batch is cut once, then each member receives its OWN independent augment_views() draw of those crops and its own loss (soft tent cross-entropy + residual offset target computed from that member's own logits, exactly as today); the total loss is the sum over members, one optimiser step. Members differ by random initialisation (sequential construction from the seeded RNG) and by their augmentation draws; there is no agreement term in the loss, because diversity is the mechanism. Per-member top1 and the member-agreement rate (same argmax cell) are logged per epoch. Views per epoch, paired three-survey chunks, augmentation ranges, targets, schedule, epochs, CLI and the ONNX contract are untouched.
Expected outcome
Primary (held-out truedop_2024): 1.271 -> predicted 1.05-1.18, through the false-fix rate: 38.75% -> 18-28% as frames on which the two members name different blocks become abstentions, with usable_fix_rate roughly flat (11.75% -> 9-14%; the averaged belief is at least as accurate as one member, and genuinely-right frames are where members agree). 2024 coverage falls from 0.505 to a predicted 0.28-0.40; the 0.2 FAIL floor is the explicit risk of this design and is flagged, not hidden - if the committee abstains on nearly all of today's confident-wrong frames AND on some of the confident-right ones, coverage approaches the floor. Median 2024 error among confident frames (1,911 m) should fall below 800 m because the surviving confident set is enriched for correct fixes. Training diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.733 / 0.673 / 0.518 on exp 4): coverage drops further (narrower members, and the min gate), usable 36-54% -> 30-50%, false fix 6-9% -> 2-5%; a lower false-fix rate on the training photographs at held-out viewpoints is itself evidence the gate works. Mechanical checks that must hold or the mechanism did not bite: the two logged per-member top1 values end within ~0.05 of each other and of exp 4's 0.45; the logged member agreement rate on training views ends at or above 0.6; exported bytes read ~3,942,411 (well under 4,194,304) and host latency ~2 ms. Decision rules: (a) 2024 false fix falls by >= 8 points with usable within +-3 points -> supported; the committee is the confidence gate from here on, and the next experiment attacks ACCURACY on top of it with external features (cached DINOv2 patch distillation, library L2 #3, or a permissively-licensed pretrained trunk), which no experiment of this era has tried. (b) 2024 coverage < 0.2 (score FAIL) -> the min gate over-abstains; retry once with the geometric mean of the two block masses in place of the min, nothing else changed. (c) 2024 false fix stays >= 35% -> the members share their confusions: confident-wrong frames are look-alike places both members confuse the same way, not survey-shortcut attractors, and no amount of ensembling reaches them; the next move is external features. Standing check: the score must move through false_fix_rate with usable_fix_rate not falling by more than the false-fix gain; if the score improves while neither product rate moves, the metric is wrong again.
Result
mission score = 1.095578 (previous best 1.27063) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 1,342–1,342 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
3.75 km
miss, this crop
0.08
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.0968% usablecov 0.24
Fits the aircraft?all deployment gates passed largest per-area model 3,850 KB (limit 4,096 KB) · single-frame inference 2.0 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
399 s
cuda
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 8 m 43 s · implement (Opus) 2 m 01 s · train 1 area 16 m 17 s · score 11 s · samples 4 s · publish 3 s · whole experiment 43 m 51 s
ts 2026-11-01T11:44:48 · commit 5a0a4962ffc1 ·
parent b8ebd7465a6a · artifacts runs/20261101_110104_experiment7 ·
agent model — · took 43 m 44 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py185 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.TWO-MEMBER COMMITTEE (capture-holdout era, experiment 7): the network isN_MEMBERS = 2 fully independent Members (each its own conv trunk atMEMBER_CHANS + its own cell head + its own offset head; no shared weights),differing only by random initialisation and by their training augmentationdraws. Deployed decode: per-member softmax p_k; averaged beliefpbar = mean_k p_k; the argmax cell of pbar and the same 3x3 block mask aroundit; conf = MIN over members of member k's own mass on that consensus block —each member must independently put its belief there, so a frame on which thetwo members name different blocks becomes an abstention. The fix is pbar'smass-weighted block centroid plus the mean of the members' offsets. Memberdisagreement is epistemic uncertainty, the kind a never-seen photographproduces; a single model's softmax mass is not.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly. Contract unchanged: 1x3x128x128 float32 in [0,1] ->[[u, v, conf]], u/v normalised map coords, conf in [0,1]."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)
N_MEMBERS =2# independent committee members (no shared weights)
MEMBER_CHANS =[3,24,48,96,112]# per-member trunk widths (size gate)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class Member(nn.Module):"""One independent localizer: conv trunk -> GAP -> (C-way cell logits, within-cell offset)."""def __init__(self, n_cells: int, chans=MEMBER_CHANS):
super().__init__()
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1], n_cells)self.off_head = nn.Linear(chans[-1],2)def forward(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5class CellLocNet(nn.Module):"""Committee of N_MEMBERS independent Members. forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes each member's raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]# Sequential construction from the already-seeded torch RNG gives each# member a different init; deliberately not re-seeded between members.self.members = nn.ModuleList(Member(self.n_cells)for_in range(N_MEMBERS))# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def block_mask(self, idx):"""Float [B, n_cells] mask of the 3x3 block of cells centred on each argmax cell idx [B] (int64). 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block with float-safety margin — the next ring sits at 2.0 pitches. Edge cells simply have fewer neighbours in range; nothing is counted twice."""
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()return((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()def training_outputs(self, x):"""List of N_MEMBERS (logits, offset) tuples, all on the same x."""return[m(x)for m inself.members]def forward(self, x):# Committee decode: averaged belief names the consensus block; each# member's OWN mass on that block is measured and the smaller is the# confidence, so a fix is trusted only if every member independently# put its belief there. Fix = pbar's block centroid + mean offset.
outs =self.training_outputs(x)
ps =[F.softmax(l, dim=1)for l,_in outs]
pbar = torch.stack(ps,0).mean(0)
idx = pbar.argmax(dim=1)
mask =self.block_mask(idx)
masses = torch.stack([(p * mask).sum(dim=1)for p in ps],0)# [N_MEMBERS, B]
conf = masses.min(dim=0).values # min of softmax sub-sums: in [0,1]
q = pbar * mask
w = q / q.sum(dim=1, keepdim=True).clamp_min(1e-9)
off = torch.stack([o for_, o in outs],0).mean(0)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ off[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ off[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py405 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.VIEWS ARE CUT ON THE DEVICE (infrastructure, 2026-10-31, issue #3): thetraining captures sit on the GPU as one uint8 tensor and gpu_crops() cuts androtates each mini-batch there (same geometry as pipeline.dataset.extract_crop,within 1/255), and running stats stay on the device until the epoch ends.This replaced one-at-a-time PIL rotation on the CPU and per-step GPU->CPUreads: ~24% faster per epoch on the M1, more on a CUDA card. Keep newper-view work on the device and avoid .item()/.cpu()/int()/float() on devicetensors inside the step loop — each one stalls the GPU queue.COMMITTEE (experiment 7): the model is two fully independent members(model.model.N_MEMBERS) whose deployed confidence is the smaller of the twomembers' belief on the consensus block. Each mini-batch is cut once, then everymember gets its OWN independent augment_views() draw of those crops and its ownloss (tent cross-entropy + residual offset target from that member's ownlogits); the losses are summed into one optimiser step. There is no agreementterm: members differ by init and augmentation draws, and that diversity IS themechanism — disagreement between independently trained models is epistemicuncertainty, the confidence gate that survives a change of photograph.Per-member top1 and the member agreement rate are logged per epoch.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, MEMBER_CHANS, N_MEMBERS, build_model,
export_onnx, grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import CROP_PX, WINDOW_PX, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def chunk_views(meta, crop_xy, indices, rng, n_caps):"""Index one chunk of PAIRED vantages: every position in `indices` in every capture, with one shared heading per position. No pixels are cut here — gpu_crops() does that per mini-batch. Returns CPU tensors (cx [N*K], cy [N*K], angle_deg [N*K], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]), views ordered position-major as before. `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xy = crop_xy[torch.as_tensor(indices, dtype=torch.int64)]# [N,2]
ang = torch.as_tensor(rng.uniform(0,360, size=len(indices)),
dtype=torch.float32)# shared heading
rep =lambda t: t.repeat_interleave(n_caps, dim=0)
cx, cy = rep(xy[:,0]), rep(xy[:,1])
cells =(cy // CELL_PX)* gw +(cx // CELL_PX)
pos = torch.stack([cx, cy], dim=1).float()
caps = torch.arange(n_caps, dtype=torch.int64).repeat(len(indices))return cx, cy, rep(ang), cells, pos, caps
def gpu_crops(scene_u8, cap, cx, cy, angle_deg, size=CROP_PX):"""Cut and rotate a batch of training views on the device. Same geometry as pipeline.dataset.extract_crop (PIL rotate, bilinear, about the crop centre), checked to match it within uint8 rounding at the edges. scene_u8: [K,3,H,W] uint8 (all training captures, resident on device). cap, cx, cy: int64 [B]; angle_deg: float [B]; all on the same device. Returns float [B,3,size,size] in [0,1]. """
dev = scene_u8.device
hw = WINDOW_PX //2+1# extract_crop's half window
ar = torch.arange(2* hw, device=dev)
ys =(cy - hw).unsqueeze(1)+ ar # [B,2hw]
xs =(cx - hw).unsqueeze(1)+ ar
win = scene_u8[cap[:,None,None],:, ys[:,:,None], xs[:,None,:]]# [B,2hw,2hw,3]
win = win.permute(0,3,1,2).float()# PIL: input = R(-angle) applied to (output - centre) + centre, in pixel-# corner coordinates; the window centre is hw and the crop is centred on it.
th = torch.deg2rad(angle_deg.float())
c, s = torch.cos(th), torch.sin(th)
d = torch.arange(size, device=dev, dtype=torch.float32)+0.5- size /2
dx, dy = d.view(1,1, size), d.view(1, size,1)
px = hw + c.view(-1,1,1)* dx - s.view(-1,1,1)* dy
py = hw + s.view(-1,1,1)* dx + c.view(-1,1,1)* dy
grid = torch.stack([px, py], dim=-1)*(2.0/(2* hw))-1.0# [B,S,S,2]
out = F.grid_sample(win, grid, mode="bilinear", padding_mode="zeros",
align_corners=False)return out.div_(255.0)def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own block_mask() and buffers so the grid geometry stays single-sourced. Called once per committee member with that member's own logits. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
mask = model.block_mask(idx)
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def run_epoch(model, opt, meta, scene, crop_xy, rng, device, n_caps,
pos_per_chunk, gw, gh, max_chunks=None):"""One full pass over the whole lattice x every capture, shuffled, fresh headings; each chunk holds its positions in ALL captures. Running stats stay on the device and are read once at the end, so the CPU never waits for the GPU mid-epoch. `max_chunks` is for timing runs only."""
model.train()
loss_sum = torch.zeros((), device=device)
correct = torch.zeros((), dtype=torch.int64, device=device)
conf_sum = torch.zeros((), device=device)
cap_correct = torch.zeros(n_caps, dtype=torch.int64, device=device)
cap_seen = torch.zeros(n_caps, dtype=torch.int64, device=device)
member_correct = torch.zeros(N_MEMBERS, dtype=torch.int64, device=device)
agree = torch.zeros((), dtype=torch.int64, device=device)
seen =0
order = rng.permutation(len(crop_xy))for ci, start in enumerate(range(0, len(order), pos_per_chunk)):if max_chunks isnotNoneand ci >= max_chunks:break
views = chunk_views(meta, crop_xy, order[start:start + pos_per_chunk],
rng, n_caps)
cx, cy, ang, cell_idx, pos, cap_idx =(t.to(device)for t in views)
n = len(cx)
perm = torch.randperm(n).to(device)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
B = len(idx)
cap_b = cap_idx[idx]# Cut once; each member gets its OWN independent augmentation draw.
xb0 = gpu_crops(scene, cap_b, cx[idx], cy[idx], ang[idx])
cb, pb = cell_idx[idx], pos[idx]
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
loss = torch.zeros((), device=device)
member_logits =[]for member in model.members:
xb_k = augment_views(xb0)
logits_k, off_k = member(xb_k)
off_t_k = residual_offset_target(model, logits_k, pb, meta)
loss = loss + loss_fn(logits_k, off_k, soft_t, off_t_k)
member_logits.append(logits_k)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.detach()* B
member_args =[l.argmax(dim=1)for l in member_logits]for k, a in enumerate(member_args):
member_correct[k]+=(a == cb).long().sum()
agree +=(member_args[0]== member_args[1]).long().sum()# Committee belief: mean of the member softmaxes.
pbar = torch.stack([F.softmax(l, dim=1)for l in member_logits],0).mean(0)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(pbar.argmax(dim=1)== cb).long()
correct += hit.sum()
cap_correct.scatter_add_(0, cap_b, hit)
cap_seen.scatter_add_(0, cap_b, torch.ones_like(cap_b))
conf_sum += pbar.max(dim=1).values.sum()
seen += B
return{"loss_sum": float(loss_sum),"correct": int(correct),"conf_sum": float(conf_sum),"seen": seen,"cap_correct": cap_correct.cpu().tolist(),"cap_seen": cap_seen.cpu().tolist(),"member_correct": member_correct.cpu().tolist(),"agree": int(agree)}def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")# All training captures live on the device for the whole run (uint8,# ~0.43 GB for Berlin); views are cut from them per mini-batch.
scene = torch.from_numpy(np.stack(imgs)).permute(0,3,1,2).contiguous().to(device)del imgs
crop_xy = torch.tensor([(c["cx"], c["cy"])for c in crops], dtype=torch.int64)
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
final_member_top1 =[0.0]* N_MEMBERS
final_agree =0.0for epoch in range(epochs):
stats = run_epoch(model, opt, meta, scene, crop_xy, rng, device,
n_caps, pos_per_chunk, gw, gh)
sched.step()
seen = stats["seen"]
final_top1 = stats["correct"]/ max(seen,1)
final_top1_by_cap ={
nm: round(stats["cap_correct"][k]/ max(stats["cap_seen"][k],1),4)for k, nm in enumerate(names)}
final_member_top1 =[round(c / max(seen,1),4)for c in stats["member_correct"]]
final_agree = round(stats["agree"]/ max(seen,1),4)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={stats['loss_sum']/ max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={stats['conf_sum']/ max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"member_top1={final_member_top1} agree_rate={final_agree:.4f}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* n_caps,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* n_caps,"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation, ""two-member committee with independent augmentation draws per member"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"n_members": N_MEMBERS,"member_chans": MEMBER_CHANS,"final_member_top1": final_member_top1,"final_member_agree_rate": final_agree,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Cross-survey blending: every training view becomes a per-pixel mixture of the three surveys' photographs of the same place, so the model learns the continuum between surveys instead of three fingerprints 87f5e046
worse than champion: 1.288 vs 1.271
augmentation
1.288
173 m 41 s
$6.76
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model has seen Berlin in three different aerial photographs: one in summer, one in winter with bare trees, one in early spring. So far it could pass its training by learning each photograph by heart - three separate memories of every street - and a brand-new fourth photograph matched none of them. We now show it, while it learns, pictures that are blends of the three: half summer and half winter, or winter on the left side of the frame and spring on the right. In a blend, no single photograph's look can be trusted, but the shapes of the roads, blocks and canals are the same in all three and come through sharp every time. The hope is that the model is pushed to remember the city by its shape, and that a photograph it has never seen then looks like just another blend.
What it cost
design agent
$4.80
figure agent
$1.19
implementation agent
$0.77
total
$6.76
by model — claude-fable-5-1 $4.80 · claude-sonnet-5 $1.19 · claude-opus-5-5 $0.77
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 1.288 it didn't beat the champion's 1.271, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Four results in this era, read together, say the held-out survey fails for a reason no experiment has yet addressed: the model has exactly three appearance samples per place and nothing in training says what lies BETWEEN them. (1) Experiment 5 showed the gap is survey, not viewpoint: with a whole-frame trunk the three TRAINING photographs reached 72-81% usable at the same 11-17 m off-lattice eval viewpoints (train_capture_diagnostics 0.335 / 0.258 / 0.238) while the held-out 2024 photograph of the same viewpoints stayed at 12.5% usable / 42.3% false fix (1.298). (2) Experiment 3 showed that forcing the three surveys' features to AGREE does not transfer: its logged final cross-survey cosine was 0.935 (train_berlin.log, consistency loss 0.065), i.e. the three training appearances of each place were mapped to nearly the same 160-d vector, and 2024 got WORSE (false fix 65.3% -> 71.8%, 1.583 -> 1.648). Agreement on three points constrains two directions of appearance space per place; a fourth survey lands somewhere else. (3) Experiment 4's photometric randomisation (kept, 1.583 -> 1.271) covers the GLOBAL part of a survey change - exposure, colour pipeline, sharpness - and cannot synthesise the CONTENT part: leaf-on vs leaf-off canopy, shadow direction and length, parked cars, construction, the leaning roofs of a standard DOP vs a true-ortho. (4) A model-free design-time probe on the three TRAINING captures only (runs/_probe_exp6_scale.py; the eval capture was never opened): over 600 random lattice places, nearest-neighbour retrieval by per-crop standardised pixel correlation identifies a place across surveys from the SAME pixel-aligned viewpoint 90-97% of the time at 1 m/px (mean same-place correlation 0.49-0.57), rising only to 0.60-0.65 at 8-16 m/px - so (a) pixel-aligned surveys share most of their structure and a representation that locates one from another is not asking the impossible, (b) the survey difference is broadband, not fine texture, so a coarse-scale bottleneck is NOT the lever (that candidate was considered and dropped on this measurement), and (c) the same probe collapses to 7-11% under a 12 px shift and 1% under shift+rotation, confirming that viewpoint tolerance is the CNN's learned contribution and must be learned jointly with survey tolerance, not bolted on at decode. What the training signal lacks is DENSITY along the survey axis. The captures are pixel-aligned on one grid (alignment <= 1 px) and extract_chunk already pulls each position from all three captures under one shared heading, so a convex per-pixel combination of the three crops is a physically meaningful synthetic photograph of the same place: half summer canopy and half leaf-off, a shadow at an intermediate strength, a car at half opacity. With a SPATIALLY VARYING weight field, one frame holds a leafy tree beside a bare one, east shadows beside west shadows - states no real survey contains - so canopy, shadow, movable objects and colour pipeline become locally uninformative, while road, block, building-footprint and water geometry, which every blend renders crisply because it is identical in all three sources, stays the only cue that always pays. This is mixup/CutMix applied along the survey axis of aligned imagery; it is possible only because of this era's data asset (every earlier era had one photograph, and no row in lineage_history mentions mixing or blending across photographs), and it is a materially different angle from experiment 3: instead of asking the features of three fixed points to agree, it asks the classifier to be correct on the whole simplex between them, which is where a fourth survey is far more likely to fall than on any one of the three vertices. Capacity spent on three pixel-exact fingerprints per cell is capacity the blend augmentation makes worthless; capacity spent on shared geometry is rewarded on every blend and - the bet - on truedop_2024.
Method
ONE change, in model/train.py only: a cross-survey blend stage applied on the device to every mini-batch BEFORE augment_views(). For each view in the batch, gather the three sibling crops of its position (same cx, cy and heading, one per training capture; the chunk is position-major so they are x_u8[p*K + k]), draw a smooth random weight field over the three captures (a 4x4 grid of Gaussian logits scaled by a per-view temperature tau ~ U(0.5, 3.0), bilinearly upsampled to 128x128, softmax over the capture axis) and replace the view by the per-pixel convex combination of its three siblings; with probability 1 - P_MIX (P_MIX = 0.75) the view keeps its own single-survey crop unchanged. Labels (position, bilinear tent cell target, residual offset target) are unchanged because the place is unchanged. Views per epoch, batch size, paired-position chunking, photometric augmentation, loss, model, decode, schedule and ONNX export are untouched; the exported graph is byte-for-byte the same architecture (3,079,093 bytes).
Expected outcome
Primary (held-out truedop_2024): 1.271 -> predicted 1.00-1.15, through BOTH product rates: usable_fix_rate 11.75% -> 18-28% and false_fix_rate 38.75% -> 28-34%, with 2024 coverage staying in 0.45-0.60 (currently 0.505; the 0.2 floor is not at risk). Median 2024 error (1,911 m) should fall below 1,000 m as confident predictions stop collapsing onto look-alike cells of a different survey. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.733 / 0.673 / 0.518 on experiment 4) are predicted to stay roughly where they are or drift slightly worse (0.55-0.85 each): the trunk is already underfitting (loss still falling at epoch 8) and blends make the task harder on the training photographs by design - a NARROWING gap between the training-survey diagnostics and the 2024 score is the evidence, not a rise in the diagnostics. Mechanical checks that must hold or the mechanism did not bite: the logged blend fraction reads ~0.75; the per-epoch top1 on blended views ends within ~0.10 of top1 on unblended views (if blends stay far harder, the model is still keying on single-survey cues); loss at epoch 8 is above experiment 4's 4.08 (harder task), not below. Decision rules: (a) 2024 usable up AND false fix down -> supported: the survey continuum transfers; the next experiment puts experiment 5's whole-frame trunk back on top of it (its fit gain on the training surveys may now transfer) or adds +-12 px vantage jitter. (b) 2024 unchanged (>= 1.22) while the training diagnostics fall -> 2024 lies outside the hull the three surveys span, synthetic appearance is not enough; the next move is a cached permissively-licensed teacher (DINOv2 patch-feature distillation with a cross-survey term, library L2 rank 3) or the mapping/query confidence split (L2 rank 6) to convert false fixes into abstentions. (c) false fix falls but usable stays flat (score 1.15-1.25) -> the blends taught honesty, not accuracy: still a kept improvement, and the next step is capacity/trunk, not more augmentation. Standing check: the score must move through usable_fix_rate and false_fix_rate; model bytes must read 3,079,093 and latency stays far under 250 ms.
Result
mission score = 1.288117 (previous best 1.27063) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1.288117 vs best 1.27063); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 1,898–1,898 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
2.46 km
miss, this crop
0.13
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.28814% usablecov 0.57
Fits the aircraft?all deployment gates passed largest per-area model 3,007 KB (limit 4,096 KB) · single-frame inference 1.6 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
9,178 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 10 m 56 s · implement (Opus) 1 m 15 s · train 1 area 153 m 00 s · score 11 s · samples 4 s · publish 3 s · whole experiment 173 m 48 s
ts 2026-10-31T16:49:28 · commit 87f5e04694da ·
parent 4f97a845288d · artifacts runs/20261031_135547_experiment6 ·
agent model — · took 173 m 41 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py148 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py384 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.CROSS-SURVEY BLEND: the three training photographs are pixel-aligned on onegrid, and every chunk already holds each position in all three under oneshared heading. Before augment_views(), each training view is replaced withprobability MIX['p'] by a per-pixel convex combination of its position's threesibling crops, weighted by a smooth random field (MIX['grid']^2 Gaussianlogits x per-view temperature, bilinearly upsampled, softmax over captures) —so canopy, shadow, movable objects and colour pipeline become locallyuninformative while geometry shared by all surveys stays sharp. Labels areunchanged (same place). Training only; the exported graph is unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)
MIX = dict(p=0.75, grid=4, tau=(0.5,3.0))# p: probability a training view is replaced by a cross-survey blend;# grid: edge of the low-res weight-logit grid (4 -> ~32 m blobs);# tau: per-view logit scale range (small = soft everywhere-blend, large = patchwork of surveys).def cross_survey_blend(x_u8: torch.Tensor, idx: torch.Tensor, cap_idx: torch.Tensor,
n_caps: int, device, mix: dict = MIX):"""Replace each view (w.p. mix['p']) by a per-pixel convex blend of its position's sibling crops across all training captures. x_u8 is extract_chunk's uint8 [N*K,3,H,W], POSITION-MAJOR: view j belongs to position j // K and capture j % K. Returns (xb float [B,3,H,W] in [0,1] on device, mixed bool [B] on device, mean_max_w float over mixed views). """
B = len(idx)
H, W_ = x_u8.shape[-2], x_u8.shape[-1]if n_caps <2:
own = x_u8[idx].to(device).float().div_(255.0)return own, torch.zeros(B, dtype=torch.bool, device=device),0.0
p_idx = idx // n_caps
sib =(p_idx.unsqueeze(1)* n_caps + torch.arange(n_caps)).reshape(-1)# [B*K]
S = x_u8[sib].to(device).float().div_(255.0).view(B, n_caps,3, H, W_)
own = S[torch.arange(B, device=device), cap_idx[idx].to(device)]# [B,3,H,W]
g = mix["grid"]
lo, hi = mix["tau"]
tau = lo +(hi - lo)* torch.rand(B,1,1,1, device=device)
z = torch.randn(B, n_caps, g, g, device=device)* tau
z = F.interpolate(z, size=(H, W_), mode="bilinear", align_corners=False)
Wt = torch.softmax(z, dim=1).unsqueeze(2)# [B,K,1,H,W], sums to 1 over K
blended =(S * Wt).sum(dim=1)# [B,3,H,W]
mixed = torch.rand(B, device=device)< mix["p"]
xb = torch.where(mixed.view(B,1,1,1), blended, own)if bool(mixed.any()):
mmw = float(Wt.squeeze(2).max(dim=1).values.mean(dim=(1,2))[mixed].mean())else:
mmw =0.0return xb, mixed, mmw
def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def extract_chunk(meta, imgs, crops, indices, rng):"""Extract one chunk of PAIRED vantages: every position in `indices` from every capture in `imgs`, with one shared heading per position. Returns (x_uint8 [N*K,3,H,W], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos, caps =[],[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation, shared
cell =(cy // CELL_PX)* gw +(cx // CELL_PX)for k, img in enumerate(imgs):
xs.append(extract_crop(img, cx, cy, angle))
cells.append(cell)
pos.append((float(cx), float(cy)))
caps.append(k)
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32),
torch.tensor(caps, dtype=torch.int64))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
blend_frac = top1_blend = top1_unmixed = mmw_epoch =0.0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0
n_mixed, correct_mixed, correct_unmixed =0,0,0
mmw_sum, mmw_batches =0.0,0
cap_correct = torch.zeros(n_caps, dtype=torch.int64)
cap_seen = torch.zeros(n_caps, dtype=torch.int64)# One full pass over the whole lattice x every capture, shuffled, fresh# rotations; each chunk holds its positions in ALL captures.
order = rng.permutation(len(crops))for start in range(0, len(order), pos_per_chunk):
x_u8, cell_idx, pos, cap_idx = extract_chunk(
meta, imgs, crops, order[start:start + pos_per_chunk], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb, mixed, mmw = cross_survey_blend(x_u8, idx, cap_idx, n_caps, device)
xb = augment_views(xb)
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(logits.argmax(dim=1)== cb).cpu().long()
correct += int(hit.sum())
mixed_c = mixed.cpu()
unmixed_c =~mixed_c
nm_b = int(mixed_c.sum())
n_mixed += nm_b
correct_mixed += int(hit[mixed_c].sum())
correct_unmixed += int(hit[unmixed_c].sum())if nm_b >0:
mmw_sum += mmw; mmw_batches +=1# Per-capture top1 over UNMIXED views only: a blended view# has no single capture.
cb_caps = cap_idx[idx][unmixed_c]
cap_correct.scatter_add_(0, cb_caps, hit[unmixed_c])
cap_seen.scatter_add_(0, cb_caps, torch.ones_like(cb_caps))
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos, cap_idx
sched.step()
final_top1 = correct / max(seen,1)
final_top1_by_cap ={
nm: round(int(cap_correct[k])/ max(int(cap_seen[k]),1),4)for k, nm in enumerate(names)}
blend_frac = n_mixed / max(seen,1)
top1_blend = correct_mixed / max(n_mixed,1)
top1_unmixed = correct_unmixed / max(seen - n_mixed,1)
mmw_epoch = mmw_sum / max(mmw_batches,1)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap} "
f"blend_frac={blend_frac:.4f} top1_blend={top1_blend:.4f} "
f"top1_unmixed={top1_unmixed:.4f} mean_max_w={mmw_epoch:.4f}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""cross-survey per-pixel blend (MIX) then per-view ""photometric+sharpness nuisance randomisation"),"augmentation": AUG,"cross_survey_blend": MIX,"final_blend_fraction": round(blend_frac,4),"final_top1_blend": round(top1_blend,4),"final_top1_unmixed": round(top1_unmixed,4),"final_blend_mean_max_weight": round(mmw_epoch,4),"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Whole-frame receptive field: two extra stride-2 stages take the trunk from a 31 m texture window to the full 128 m frame, so the classifier can read street-and-block layout instead of an average of local textures 0ccf089e
worse than champion: 1.298 vs 1.271
architecture
1.298
108 m 55 s
$3.77
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model looked at each 128-metre-wide aerial frame through 64 small 31-metre peepholes and then averaged what it saw, so all it could remember about a place was its mix of textures and colours: so much roof, so much asphalt, so much tree, in these tints. That is exactly the stuff that changes between two photographs of the same streets taken in different seasons, and the previous experiment deliberately scrambled it, which left the model with almost nothing to hold on to. This experiment widens its view to the whole frame at once, so it can finally see how the roads, blocks and water are arranged relative to each other, which is the same in every photograph of Berlin ever taken. The extra two layers are cheap and the exported model still fits the UAV's memory.
What it cost
design agent
$3.19
implementation agent
$0.58
total
$3.77
by model — claude-fable-5-1 $3.19 · claude-opus-5-5 $0.58
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 1.298 it didn't beat the champion's 1.271, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Experiment 4 closed the exposure/sharpness route and the model did exactly what its architecture permits: it got much worse on its OWN training photographs (train_capture_diagnostics 0.060 / 0.053 / 0.088 -> 0.733 / 0.673 / 0.518, usable 94-96% -> 36-54%) while the held-out 2024 photograph improved only to 1.271 (usable 11.8%, false fix 38.8%), with training loss still falling steeply at epoch 8 (4.08, augmented top1 0.45 vs 0.79 before). The pre-registered hope was that capacity would 'move to the layout structure at 2 m scale and up that all four surveys share'. It cannot, because the trunk cannot see layout. Measured at design time on the current model (runs/_probe_exp5_rf.py, no training): the feature extractor is four 3x3 stride-2 convs, so each of the 8x8 = 64 positions of its final map has a receptive field of 31 x 31 px, i.e. 31 m of a 128 m frame, and global average pooling then averages those 64 local descriptors. The 160-d vector the 2,970-way classifier reads is therefore, by construction, a BAG OF 31 m TEXTURE PATCHES with all relative arrangement discarded: it can encode 'how much roof, asphalt, canopy, water of which tint and grain', but not 'a canal bends past a block of three courtyards with a wide road to the north'. The first is exactly what differs between a summer DOP20, a leaf-off 2022 and an early-spring 2023 survey (and what experiment 4 now randomises away); the second is what all four surveys share. With texture statistics randomised and arrangement unrepresentable, the model is left fitting whatever colour-and-grain statistics survive the augmentation, which is why it now underfits even its training photographs and why its mean_max_softmax is only 0.19. This is the one inference stage no experiment in this era has questioned: arch_json for experiments 2-4 carries changed:true only on 'Training signal' (and experiment 3's feature-consistency term), never on 'Feature extractor', and the trunk itself is byte-for-byte the mission-era one (chans [3,32,64,128,160], unchanged since commit 92d1f12). Extending the pyramid by two more stride-2 stages (8x8 -> 4x4 -> 2x2) takes the receptive field to 127 px, so every descriptor the pooling averages sees the whole frame and can represent arrangement; the two stages are depthwise-separable so they cost 55k parameters (+221 kB, 3.30 MB exported, under the 4 MiB gate) and negligible compute at 4x4 and 2x2 resolution. The earlier-era record contains 'tripled trunk depth made things worse' (four-area era experiments 26/28, pretrained MobileNetV3 on never-seen ground under a median metric) - that verdict is void here and asked a different question; this is a from-scratch trunk on fully-mapped ground, and the change is to receptive field, not to parameter count. Rotation remains the only geometric augmentation, so the pooled whole-frame descriptor still has to be learned rotation-invariant, as the texture one was.
Method
ONE change, in model/model.py's CellLocNet.__init__: after the existing four standard 3x3 stride-2 conv+BN+ReLU stages (3->32->64->128->160, spatial 128->8, untouched), append two depthwise-separable stride-2 blocks, each = depthwise 3x3 stride-2 pad-1 conv (groups=160, no bias) + BN + ReLU + pointwise 1x1 conv 160->160 (no bias) + BN + ReLU, taking the map 8x8 -> 4x4 -> 2x2 and the receptive field 31 -> 63 -> 127 px. Global average pooling (now over 2x2), the 2,970-way cell head, the offset head, the 3x3 belief-pooling decode, confidence, loss, targets, the paired three-survey batches, nuisance augmentation, schedule, epochs and views per epoch are all untouched. Exported ONNX grows from 3,079,093 to ~3.30 MB.
Expected outcome
Mechanical check that must hold or the mechanism did not bite: training loss at epoch 8 falls well below experiment 4's 4.08 (predicted 2.8-3.4) and augmented train top1 rises from 0.45 to above 0.60, i.e. the model can now fit the augmented task it could not fit before. train_capture_diagnostics (bb_dop20 / truedop_2022 / truedop_2023 = 0.733 / 0.673 / 0.518 on experiment 4) are predicted to recover to 0.15-0.35 each, with coverage on them rising from 0.44-0.59 toward 0.8+. Primary (held-out truedop_2024): 1.271 -> predicted 0.95-1.15, with usable rising from 11.8% to 20-35% and false fix falling from 38.8% to 25-35%, because a layout descriptor that survives the augmentation is also one that a fourth survey of the same streets reproduces; median error on 2024 (1,911 m) should drop below 500 m as predictions stop collapsing onto look-alike texture cells. Decision rules: (a) training diagnostics recover AND 2024 improves -> supported; the feature now carries layout, and the next experiment can make that layout survey-invariant explicitly (experiment 3's cross-survey consistency redone on batch-centred features, which was vacuous on the old non-negative GAP texture vector) or add +-12 px jitter. (b) training diagnostics recover (0.15-0.35) but 2024 stays >= 1.2 -> the wide-receptive-field trunk memorised three survey-specific layouts-of-texture; the next move is cross-survey feature consistency or DINOv2 distillation, not more capacity. (c) training diagnostics do NOT recover (stay > 0.5) -> receptive field was not the binding limit; the 8-epoch budget under augmentation is, and the next experiment addresses optimisation (schedule / head capacity), not the trunk. Standing check: the score must move through usable_fix_rate and false_fix_rate, with 2024 coverage staying >= 0.2 (currently 0.505); model bytes must read ~3.30 MB and latency stays far under 250 ms.
Result
mission score = 1.298142 (previous best 1.27063) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1.298142 vs best 1.27063); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 2,069–2,069 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
1.58 km
miss, this crop
0.38
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.29812% usablecov 0.55
Fits the aircraft?all deployment gates passed largest per-area model 3,222 KB (limit 4,096 KB) · single-frame inference 2.4 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,142 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 4 m 49 s · implement (Opus) 51 s · train 1 area 102 m 24 s · score 22 s · samples 8 s · publish 6 s · whole experiment 109 m 05 s
ts 2026-10-30T16:15:59 · commit 0ccf089ebc2f ·
parent 0ccf089ebc2f · artifacts runs/20261030_142704_experiment5 ·
agent model — · took 108 m 55 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py159 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The trunk is four standard stride-2 convs plus twodepthwise-separable stride-2 stages, so the pooled feature's receptive fieldcovers the whole 128 px frame. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]# Two depthwise-separable stride-2 stages (8x8 -> 4x4 -> 2x2) widen the# receptive field from a 31 px texture window to 127 px, so every pooled# descriptor sees the whole frame and can encode layout, not just texture.
c = chans[-1]for_in range(2):
layers +=[nn.Conv2d(c, c,3, stride=2, padding=1, groups=c, bias=False),
nn.BatchNorm2d(c), nn.ReLU(inplace=True),
nn.Conv2d(c, c,1, bias=False),
nn.BatchNorm2d(c), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py312 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def extract_chunk(meta, imgs, crops, indices, rng):"""Extract one chunk of PAIRED vantages: every position in `indices` from every capture in `imgs`, with one shared heading per position. Returns (x_uint8 [N*K,3,H,W], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos, caps =[],[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation, shared
cell =(cy // CELL_PX)* gw +(cx // CELL_PX)for k, img in enumerate(imgs):
xs.append(extract_crop(img, cx, cy, angle))
cells.append(cell)
pos.append((float(cx), float(cy)))
caps.append(k)
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32),
torch.tensor(caps, dtype=torch.int64))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0
cap_correct = torch.zeros(n_caps, dtype=torch.int64)
cap_seen = torch.zeros(n_caps, dtype=torch.int64)# One full pass over the whole lattice x every capture, shuffled, fresh# rotations; each chunk holds its positions in ALL captures.
order = rng.permutation(len(crops))for start in range(0, len(order), pos_per_chunk):
x_u8, cell_idx, pos, cap_idx = extract_chunk(
meta, imgs, crops, order[start:start + pos_per_chunk], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = augment_views(x_u8[idx].to(device).float()/255.0)
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(logits.argmax(dim=1)== cb).cpu().long()
correct += int(hit.sum())
cb_caps = cap_idx[idx]
cap_correct.scatter_add_(0, cb_caps, hit)
cap_seen.scatter_add_(0, cb_caps, torch.ones_like(cb_caps))
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos, cap_idx
sched.step()
final_top1 = correct / max(seen,1)
final_top1_by_cap ={
nm: round(int(cap_correct[k])/ max(int(cap_seen[k]),1),4)for k, nm in enumerate(names)}
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"trunk":("4 std 3x3 s2 convs [3,32,64,128,160] + 2 depthwise-separable ""3x3 s2 blocks 160->160; RF 127 px; GAP over 2x2"),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Exposure-and-sharpness nuisance randomisation: every training view is re-photographed at random (brightness, contrast, gamma, colour balance, saturation, blur, sensor noise) so a pixel fingerprint of one survey stops being a usable solution 937b4c32
new best: 1.583 → 1.271
augmentation
1.271
111 m 31 s
$4.91
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model had three photographs of Berlin and learned each one by its exact brightness, colour tint and fine grain, like recognising a page by the paper it is printed on rather than by the words. A test showed it: brighten its own training photo slightly and it is lost. Now every training picture is handed to it slightly re-photographed at random each time, a bit brighter or darker, warmer or cooler, softer or sharper, grainier, so the paper keeps changing and only the words, the streets and building outlines, stay the same. If it can only pass by reading the words, it should also read a fourth photograph it has never seen.
What it cost
design agent
$3.38
figure agent
$0.92
implementation agent
$0.62
total
$4.91
by model — claude-fable-5-1 $3.38 · claude-sonnet-5 $0.92 · claude-opus-5-5 $0.62
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 1.583 to 1.271 — 0.313 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
The three-survey training signal of experiment 2 did not teach exposure invariance; it taught three exposures. Design-stage probe on experiment 2's exported berlin.onnx, scored with the frozen scorer's own 400 eval crops (numbers from the design stage, not part of the record): on its OWN training photograph truedop_2023 the model reads 0.087, but the same photograph +20 on every pixel reads 1.240 (usable 94.3% -> 14.7%), -20 reads 1.550, and a 1 px Gaussian blur reads 1.100 (median 29 m -> 253 m). That is the identical brittleness the era's founding table measured on the single-photograph champion (+20 -> 1.453, blur -> 1.271): three photographs with three different colour balances (channel means 118/121/117, 99/98/99, 117/116/110) were absorbed as three pixel-exact fingerprints, not as an invariance, and nothing in the training signal asks for one. Globally matching the held-out 2024 photograph's per-channel mean/std to truedop_2023 recovers only a fifth of the gap (1.583 -> 1.365, false fix 65% -> 47%, usable 7% -> 10%), so the rest of the gap is LOCAL: the 2024 survey is softer and lower-contrast (channel std 41/39/40 vs 50/47/43) with its own shadows, resampling and 1 m texture, and the model's fix rides exactly that 1 m texture (hence the blur result). Experiment 3 tried to forbid fingerprints at the feature level and was reverted, but its mechanism never bit: the logged cross-survey cosine was already 0.966 at epoch 1 on a freshly initialised network, because post-ReLU GAP features are non-negative and share a large common component, so a cosine floor of 0.9 was satisfied for free and the term's gradient was negligible (cons 0.065 against a cross-entropy of 2.9). Its refutation is of a vacuous constraint, not of feature invariance; a fair retest needs batch-centred features. The direct remedy for what the probe measured is the library's L2 entry #2: randomise, per training view, the nuisances that differ between exposures of the same ground (global intensity, contrast, gamma, per-channel colour balance, saturation, sharpness, sensor noise). A pixel-exact fingerprint then no longer predicts the cell across the model's own training stream, so capacity has to move to what survives those transformations, which is the layout structure at 2 m scale and up that all four surveys share. The blur component is the load-bearing one for the cross-survey question: it is the 1 m texture that is survey-specific, and the exp-2 model demonstrably depends on it. This cannot synthesise leaf-off versus canopy or a different shadow direction; the three surveys supply that part, and this experiment makes them the only route left.
Method
ONE change, in model/train.py only: a training-time augmentation stage augment_views(xb) applied on the GPU to every mini-batch right after xb is formed (float [B,3,128,128] in [0,1]), with independent random parameters per view: separable Gaussian blur sigma~U(0,1.5) px applied with probability 0.7 (7-tap, per-sample kernel via grouped conv); exposure gain~U(0.75,1.30) times per-channel colour gain~U(0.85,1.15); contrast~U(0.6,1.4) about the crop's own mean; brightness offset~U(-0.12,0.12); gamma~U(0.7,1.4); saturation~U(0.5,1.5) toward the per-pixel grey; additive Gaussian sensor noise sigma~U(0,0.03); clamp to [0,1]. Targets, loss, paired-position batching, model, decode, export, schedule and views per epoch are untouched; the exported graph is byte-for-byte the same architecture. train_info.json records the augmentation ranges.
Expected outcome
Mechanical check that must hold or the augmentation was not applied: re-running the design-stage probe on the new berlin.onnx (truedop_2023 eval crops +20 / -20 / 1 px blur) must read below 0.3 on all three, down from 1.24 / 1.55 / 1.10 on experiment 2's model; and the gap between 2024 raw and 2024 globally colour-matched (0.22 on experiment 2) should close to within 0.05. Primary (held-out truedop_2024): 1.583 -> predicted 1.15-1.40, from the false-fix rate falling (65% -> 35-50%) as confidence stops keying on one survey's intensities and sharpness, and usable rising (7% -> 15-30%) where the shared 2 m-scale structure is enough to name the 128 m cell. Training diagnostics (bb_dop20 / truedop_2022 / truedop_2023: 0.060 / 0.053 / 0.088) are expected to worsen mildly to 0.08-0.25 because the pixel-exact route is closed; that is acceptable and is the sign capacity moved. Train top1 will read lower than experiment 2's 0.79 because it is now measured on augmented views; judge by eval. Decision rules: (a) 2024 improves AND the mechanical checks pass -> supported; the next experiment attacks the remaining local gap with something the augmentation cannot synthesise: either experiment 3's feature consistency re-done on batch-centred features (its cosine was vacuous), or aligned cross-survey patch mixing (compose one training view from pixel-aligned patches of two surveys), or L2 #3 distillation. (b) mechanical checks pass but 2024 stays >= 1.5 -> exposure/sharpness is not what separates a fourth survey; the gap is season and shadow geometry, and the next move is cross-survey structure (consistency with centred features, or distillation), not more augmentation. (c) mechanical checks fail -> the ranges were too narrow or the stage was skipped; fix before concluding anything. Standing check: the score must improve through usable_fix_rate and a lower false-fix rate, with coverage on 2024 staying >= 0.2 (currently 0.72).
Result
mission score = 1.27063 (previous best 1.58323) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 1,911–1,911 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
5.20 km
miss, this crop
0.15
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.27112% usablecov 0.51
Fits the aircraft?all deployment gates passed largest per-area model 3,007 KB (limit 4,096 KB) · single-frame inference 2.2 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
6,157 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 6 m 54 s · implement (Opus) 1 m 06 s · train 1 area 102 m 39 s · score 24 s · samples 7 s · publish 6 s · whole experiment 111 m 48 s
ts 2026-10-30T14:26:26 · commit 937b4c32c829 ·
parent 6dc41da83418 · artifacts runs/20261030_123455_experiment4 ·
agent model — · took 111 m 31 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py148 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py310 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.NUISANCE RANDOMISATION: three photographs were absorbed as three pixel-exactfingerprints (+20 brightness or a 1 px blur on a training photograph broke themodel). Every training view is now re-photographed at random on the device byaugment_views() — blur, exposure, per-channel colour gain, contrast,brightness, gamma, saturation, sensor noise, drawn independently per view (AUG)— so one survey's exposure/sharpness fingerprint no longer predicts the celland only structure shared across the photographs does. Training only; theexported graph is unchanged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64# Per-view photometric + sharpness nuisance ranges (training only).
AUG = dict(blur_p=0.7, blur_sigma_max=1.5, blur_taps=7, exposure=(0.75,1.30),
channel_gain=(0.85,1.15), contrast=(0.6,1.4),
brightness=(-0.12,0.12), gamma=(0.7,1.4), saturation=(0.5,1.5),
noise_sigma_max=0.03)def augment_views(x: torch.Tensor, aug: dict = AUG)-> torch.Tensor:"""Re-photograph each view at random. x: float [B,3,H,W] in [0,1] on its device; every parameter is drawn independently per view. Blur first, so the noise added last is not blurred. Fully vectorised (MPS/CUDA/CPU)."""
B, C, H, W = x.shape
dev = x.device
def U(lo, hi,*shape):return lo +(hi - lo)* torch.rand(*shape, device=dev)# a. separable Gaussian blur, per-sample sigma (sigma~0 -> delta kernel)
taps = aug["blur_taps"]; r = taps //2
sigma = U(0.0, aug["blur_sigma_max"], B)
sigma = torch.where(torch.rand(B, device=dev)< aug["blur_p"], sigma,
torch.zeros_like(sigma))
t = torch.arange(-r, r +1, device=dev, dtype=x.dtype)
k = torch.exp(-t.unsqueeze(0)**2/(2* sigma.clamp_min(0.05).unsqueeze(1)**2))
k = k / k.sum(dim=1, keepdim=True)# [B, taps]
k = k.repeat_interleave(C, dim=0)# [B*C, taps]
y = x.reshape(1, B * C, H, W)
y = F.conv2d(F.pad(y,(0,0, r, r), mode="reflect"),
k.view(B * C,1, taps,1), groups=B * C)
y = F.conv2d(F.pad(y,(r, r,0,0), mode="reflect"),
k.view(B * C,1,1, taps), groups=B * C)
x = y.reshape(B, C, H, W)# b. exposure gain x per-channel colour gain
x = x *(U(*aug["exposure"], B,1,1,1)* U(*aug["channel_gain"], B, C,1,1))# c. contrast about the crop's own mean
m = x.mean(dim=(1,2,3), keepdim=True)
x = m + U(*aug["contrast"], B,1,1,1)*(x - m)# d. brightness offset
x = x + U(*aug["brightness"], B,1,1,1)# e. gamma
x = x.clamp(1e-4,1)** U(*aug["gamma"], B,1,1,1)# f. saturation toward per-pixel grey
grey = x.mean(dim=1, keepdim=True)
x = grey + U(*aug["saturation"], B,1,1,1)*(x - grey)# g. additive sensor noise
x = x + torch.randn_like(x)* U(0.0, aug["noise_sigma_max"], B,1,1,1)return x.clamp(0,1)def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def extract_chunk(meta, imgs, crops, indices, rng):"""Extract one chunk of PAIRED vantages: every position in `indices` from every capture in `imgs`, with one shared heading per position. Returns (x_uint8 [N*K,3,H,W], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos, caps =[],[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation, shared
cell =(cy // CELL_PX)* gw +(cx // CELL_PX)for k, img in enumerate(imgs):
xs.append(extract_crop(img, cx, cy, angle))
cells.append(cell)
pos.append((float(cx), float(cy)))
caps.append(k)
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32),
torch.tensor(caps, dtype=torch.int64))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0
cap_correct = torch.zeros(n_caps, dtype=torch.int64)
cap_seen = torch.zeros(n_caps, dtype=torch.int64)# One full pass over the whole lattice x every capture, shuffled, fresh# rotations; each chunk holds its positions in ALL captures.
order = rng.permutation(len(crops))for start in range(0, len(order), pos_per_chunk):
x_u8, cell_idx, pos, cap_idx = extract_chunk(
meta, imgs, crops, order[start:start + pos_per_chunk], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = augment_views(x_u8[idx].to(device).float()/255.0)
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is measured on AUGMENTED views, so it reads lower# than experiment 2's 0.79 by design; judge by eval.# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(logits.argmax(dim=1)== cb).cpu().long()
correct += int(hit.sum())
cb_caps = cap_idx[idx]
cap_correct.scatter_add_(0, cb_caps, hit)
cap_seen.scatter_add_(0, cb_caps, torch.ones_like(cb_caps))
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos, cap_idx
sched.step()
final_top1 = correct / max(seen,1)
final_top1_by_cap ={
nm: round(int(cap_correct[k])/ max(int(cap_seen[k]),1),4)for k, nm in enumerate(names)}
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":("paired-position interleave, shared heading per position, ""per-view photometric+sharpness nuisance randomisation"),"augmentation": AUG,"captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Cross-survey latent consistency: the trunk feature of a place must be the same in all three photographs, not three fingerprints that happen to share a label 81aa79eb
worse than champion: 1.648 vs 1.583
loss
1.648
73 m 44 s
$3.62
discarded
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last time we showed the model three different photographs of Berlin at once, hoping it would learn what the city looks like. Instead it did the lazy thing: it memorised three separate photo albums and just agreed on the captions. Shown a fourth photograph, it had no album for it and guessed wrong, confidently. This experiment adds a rule during study: when you look at the same street corner in the summer photo, the winter photo and the spring photo, the picture you form in your head has to be THE SAME picture. That forces it to notice the things that do not change between photographs, like the shape of the blocks and the roads, and to stop leaning on the colour of the trees or the shadows that day. A fourth photograph should then look familiar.
What it cost
design agent
$2.92
implementation agent
$0.71
total
$3.62
by model — claude-fable-5-1 $2.92 · claude-opus-5-5 $0.71
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it was discarded
The change trained and scored cleanly, but at 1.648 it didn't beat the champion's 1.583, so the loop discarded it and kept the previous best. A normal negative result — most experiments land here, and each still narrows down what doesn't work.
Hypothesis
Experiment 2 produced exactly the clean negative its own pre-registration named: the three training photographs now converge (train_capture_diagnostics 0.060 / 0.053 / 0.088, 94-96% usable on each) while the held-out 2024 photograph barely moved (1.651 -> 1.583, 7% usable, 65% false fix). So 3 MB of weights and a 160-d pooled feature hold THREE separate pixel-fingerprints per 128 m cell with room to spare, and nothing in the current training signal objects: the soft cross-entropy only asks that three different feature vectors all point into the same logit direction, which a linear head satisfies trivially by carving three regions of feature space per cell. A fourth exposure of the same ground lands in none of those three regions, and the fix is confidently wrong. The missing signal is one that acts on the FEATURE the classifier reads, not on the classifier's answer: at every lattice position the paired batch already holds the same ground in all three surveys under one shared heading, so pull each survey's L2-normalised trunk feature toward the stop-gradient mean of the other surveys' features at that position (cosine loss). The classifier then cannot store three fingerprints, because the three must be one vector; whatever survives the pull is the structure the three photographs share (block layout, road geometry, building footprints, water) and the canopy/shadow/colour-balance cues that differ between a summer, a leaf-off and an early-spring survey are penalised. That is the library's L2 entry #1 (cross-survey latent consistency, the top rung of the SSL4EO ladder and the mechanism every cross-date aerial result was trained with), applied directly to the 160-d GAP feature rather than through a projector: a projector would let the feature keep its survey-specific content and discard it only in the projection, which is the opposite of what the linear cell head needs. No VICReg variance hinge: collapse is impossible while a 2,970-way cross-entropy is trained on the same vector. Output-level consistency (KL between the three cell distributions) would NOT work here, because experiment 2 already achieves near-identical argmaxes across the three surveys; the three-fingerprint solution satisfies output consistency perfectly and only feature-level consistency forbids it.
Method
ONE change: add a cross-survey feature-consistency loss during training, with position-grouped mini-batches so every batch holds P positions x 3 captures. In model/model.py, training_outputs() additionally returns the pooled 160-d trunk feature f, and a new consistency_loss(f, n_caps) computes, for rows ordered position-major, fn = normalize(f).view(P, K, D), target_k = detach((sum_j fn_j - fn_k) / (K-1)), loss = mean_k(1 - <fn_k, target_k>). In model/train.py, mini-batches are drawn as whole positions (BATCH_SIZE // n_caps = 21 positions x 3 captures = 63 views) instead of shuffled single views, and the total loss becomes loss_fn(...) + CONS_WEIGHT * consistency_loss(...) with CONS_WEIGHT = 2.0. The per-epoch log line and train_info.json gain the mean cross-survey cosine and the consistency loss so the next experiment can read whether the term bit. Inference graph, ONNX export, decode, cell/offset targets, schedule and epoch budget are untouched.
Expected outcome
Diagnostic that must move for the mechanism to count as applied: the logged mean cross-survey cosine of the trunk feature rises above 0.9 by the last epoch (experiment 2 never measured it; three independent fingerprints would sit well below). Primary (held-out truedop_2024): 1.583 -> predicted 1.1-1.4, with false-fix rate falling from 65% to below 50% as features stop keying on one raster's intensities and texture, and usable rising from 7% to 15-30%. Training diagnostics (bb_dop20 / truedop_2022 / truedop_2023) are expected to WORSEN mildly, from 0.05-0.09 to 0.1-0.3, because the model is forbidden its easiest solution; that is acceptable and is the sign the capacity moved from fingerprints to shared structure. Decision rules on the result: (a) cosine > 0.9 and 2024 improves -> supported; the next step layers L2 #2 (photometric + jitter augmentation) on top. (b) cosine > 0.9 but 2024 stays >= 1.5 -> invariance across these three surveys does not reach a fourth; the gap is then beyond what paired consistency alone can close and the next move is the distillation route (L2 #3) or augmentation. (c) cosine stays < 0.8 at CONS_WEIGHT 2.0 -> the cross-entropy out-muscled the term; rerun with a larger weight or a feature bottleneck before concluding anything about invariance. Standing check: the score must improve through usable_fix_rate, not through coverage collapsing (coverage must stay >= 0.2 and ideally near experiment 2's 72%).
Result
mission score = 1.648222 (previous best 1.58323) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Conclusion
REVERTED — mission score did not improve (1.648222 vs best 1.58323); change discarded
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 2,651–2,651 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
3.21 km
miss, this crop
0.48
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.6487% usablecov 0.79
Fits the aircraft?all deployment gates passed largest per-area model 3,007 KB (limit 4,096 KB) · single-frame inference 2.3 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
4,079 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 3 m 55 s · implement (Opus) 1 m 06 s · train 1 area 68 m 01 s · score 23 s · samples 8 s · publish 6 s · whole experiment 73 m 54 s
ts 2026-10-30T12:34:28 · commit 81aa79ebcf4e ·
parent e93426928348 · artifacts runs/20261030_112044_experiment3 ·
agent model — · took 73 m 44 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py175 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly.CROSS-SURVEY CONSISTENCY (train-only, not in the graph): training_outputs()also returns the pooled 160-d trunk feature, and consistency_loss() pulls eachtraining photograph's L2-normalised feature at a lattice position toward thestop-gradient mean of the other photographs' features at that same position(cosine loss). The cell head can then no longer store one fingerprint persurvey; the feature must be what the photographs share. forward() ignores it."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset, feature) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def embed(self, x):"""The 160-d pooled trunk feature the heads read."""returnself.features(x).mean(dim=(2,3))def training_outputs(self, x):
f =self.embed(x)# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5, f
def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset,_=self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def consistency_loss(f: torch.Tensor, n_caps: int):"""Cross-survey feature consistency. f is [P*K, D], rows ordered POSITION-MAJOR: row p*K + k is position p, capture k. Each capture's L2-normalised feature is pulled toward the detached mean of the OTHER captures' normalised features at the same position (cosine loss). Returns (loss, mean_cosine_detached). K == 1 -> (0, 1)."""if n_caps <2:
z = f.new_zeros(())return z, z +1.0
fn = F.normalize(f, dim=1).view(-1, n_caps, f.shape[1])# [P, K, D]
other =(fn.sum(dim=1, keepdim=True)- fn)/(n_caps -1)# [P, K, D]
other = F.normalize(other.detach(), dim=2)
cos =(fn * other).sum(dim=2)# [P, K]return(1.0- cos).mean(), cos.detach().mean()def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py281 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.CROSS-SURVEY CONSISTENCY: mini-batches are drawn as whole POSITIONS(BATCH_SIZE // n_caps positions x every capture), so each batch holds thesame ground in all training photographs under one shared heading. On top ofthe cell/offset loss, model.consistency_loss pulls each photograph'snormalised trunk feature toward the stop-gradient mean of the others' at thesame position, weighted by CONS_WEIGHT. The mean cross-survey cosine islogged per epoch. With a single capture the term is zero.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import(CELL_PX, build_model, consistency_loss, export_onnx,
grid_dims, loss_fn)from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64
CONS_WEIGHT =2.0# weight of the cross-survey feature-consistency lossdef load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def extract_chunk(meta, imgs, crops, indices, rng):"""Extract one chunk of PAIRED vantages: every position in `indices` from every capture in `imgs`, with one shared heading per position. Returns (x_uint8 [N*K,3,H,W], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)# Rows are emitted POSITION-MAJOR: row p*K + k is position p, capture k.# The position-grouped batches and consistency_loss rely on this ordering.
xs, cells, pos, caps =[],[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation, shared
cell =(cy // CELL_PX)* gw +(cx // CELL_PX)for k, img in enumerate(imgs):
xs.append(extract_crop(img, cx, cy, angle))
cells.append(cell)
pos.append((float(cx), float(cy)))
caps.append(k)
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32),
torch.tensor(caps, dtype=torch.int64))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
pos_per_batch = max(1, BATCH_SIZE // n_caps)
cap_offsets = torch.arange(n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}
cons_sum, cos_sum, seen =0.0,0.0,0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0
cons_sum, cos_sum =0.0,0.0
cap_correct = torch.zeros(n_caps, dtype=torch.int64)
cap_seen = torch.zeros(n_caps, dtype=torch.int64)# One full pass over the whole lattice x every capture, shuffled, fresh# rotations; each chunk holds its positions in ALL captures.
order = rng.permutation(len(crops))for start in range(0, len(order), pos_per_chunk):
x_u8, cell_idx, pos, cap_idx = extract_chunk(
meta, imgs, crops, order[start:start + pos_per_chunk], rng)
n = len(x_u8)
n_pos = n // n_caps
assert n == n_pos * n_caps
# Position-grouped batches: whole positions x every capture, rows# kept position-major so consistency_loss can pair them.
pos_perm = torch.randperm(n_pos)for i in range(0, n_pos, pos_per_batch):
pidx = pos_perm[i:i + pos_per_batch]
idx =(pidx.unsqueeze(1)* n_caps + cap_offsets).reshape(-1)
xb = x_u8[idx].to(device).float()/255.0
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred, feat = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
cons, cos_mean = consistency_loss(feat, n_caps)
loss = loss_fn(logits, off_pred, soft_t, off_t)+ CONS_WEIGHT * cons
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)
cons_sum += cons.item()* len(idx)
cos_sum += float(cos_mean)* len(idx)# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(logits.argmax(dim=1)== cb).cpu().long()
correct += int(hit.sum())
cb_caps = cap_idx[idx]
cap_correct.scatter_add_(0, cb_caps, hit)
cap_seen.scatter_add_(0, cb_caps, torch.ones_like(cb_caps))
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos, cap_idx
sched.step()
final_top1 = correct / max(seen,1)
final_top1_by_cap ={
nm: round(int(cap_correct[k])/ max(int(cap_seen[k]),1),4)for k, nm in enumerate(names)}
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"cons={cons_sum / max(seen,1):.4f} "
f"xsurvey_cos={cos_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":"paired-position interleave, shared heading per position, ""position-grouped batches + cross-survey feature consistency","captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,"consistency_weight": CONS_WEIGHT,"final_consistency_loss": round(cons_sum / max(seen,1),4),"final_xsurvey_cosine": round(cos_sum / max(seen,1),4),"positions_per_batch": pos_per_batch,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground. **A technique that works
for Berlin and for nowhere else is a complete success** — exploit anything
about Berlin's layout, texture, colours or surveys that helps; another
locale gets its own loop and may need an entirely different design.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Reuse is encouraged, not merely allowed.** Eighty-three experiments of
thinking went into that table, and most of it was never fairly tested on
this question. If an earlier design — or a piece of one, or a combination
of two — looks like it addresses "a photograph it has never seen", take
it: say in your hypothesis which experiment(s) you are building on and
why they fit now. The implementations survive, so the implementation
agent can lift code instead of re-deriving it:
* `runs/<artifacts_dir>/experiment.json` — the pre-registered method and
`implementation_brief` of every experiment, all eras;
* `runs/<artifacts_dir>/model_src/` — the exact `model/*.py` that ran, for
every experiment from 31 July on (6 run directories carry one);
* `git show <git_commit>:model/model.py` — for any experiment the loop
kept, in any era (`git_commit` is in the history row).
Point the implementation brief at the file to copy from. The one thing
that does NOT transfer is the old verdict.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Paired-survey batches: every training step sees the same places in all three photographs, not one photograph at a time aa74176b
new best: 1.651 → 1.583
training
1.583
62 m 57 s
$4.02
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
We handed the model three different aerial photographs of Berlin so it would learn the city rather than one picture of it — but the training routine showed it the whole first photo, then the whole second, then the whole third, like cramming three textbooks one after another the night before an exam. By the time it finished the third it had forgotten the first two, and the test (a fourth photo it has never seen) went badly. This experiment shuffles the three photos together so that every single study session shows the same street corners in all three photographs side by side. That forces it to notice what stays the same between the photos — the roads, the building shapes — instead of memorising the exact colours of one of them.
What it cost
design agent
$2.32
figure agent
$1.11
implementation agent
$0.59
total
$4.02
by model — claude-fable-5-1 $2.32 · claude-sonnet-5 $1.11 · claude-opus-5-5 $0.59
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
Why it's the new best
The best design so far. It improved the mission score from 1.651 to 1.583 — 0.068 better, beating the previous champion — so its code was committed as the new best, and later experiments branch from here.
Hypothesis
The baseline (experiment 1) did not learn three photographs — it learned one. Its train_capture_diagnostics read 0.015 on truedop_2023 (99% usable) but 1.401 on truedop_2022 and 1.533 on bb_dop20, i.e. the two other TRAINING photographs score almost as badly as the held-out one (1.651). The cause is in model/train.py: each epoch runs `for img in imgs:` with a complete 72,712-position lattice pass per photograph, so the model fits bb_dop20, then overwrites it with truedop_2022, then overwrites that with truedop_2023 — within-epoch catastrophic forgetting, with the cosine schedule ending on the 2023 pass. The shared trunk never receives a gradient that says 'these three different-looking crops are the SAME place' at the same time; it only ever receives 'this crop is cell k' from one survey at a time, which is exactly the single-photograph pixel-fingerprint regime the era was opened to escape. The limiting factor on the 2024 score is therefore not yet any invariance mechanism — it is that the three-survey training signal the era provides is not actually being applied. Building every batch from the same lattice positions extracted from all three photographs (same heading, same cell label) applies that signal directly: within one optimizer step the trunk is pushed to produce one cell-belief from three exposures of one place, which penalises features that only hold in one survey and rewards the structure (roads, building footprints, block layout) that all three share. Whether 3 MB of weights is still enough to store three separate fingerprints per cell instead is the open question this experiment makes measurable for the first time — the current baseline cannot answer it because it never tried to hold three.
Method
ONE change, in model/train.py only: replace the sequential per-photograph loop with paired-position interleaving. Each chunk draws a set of lattice positions, extracts the crop at each position from EVERY training capture with one shared random heading per position, and the resulting union (positions x captures) is shuffled into mini-batches, so no mini-batch is single-survey and the epoch no longer ends on one photograph. An epoch is still one full pass over the lattice x all three captures (218,136 views, identical compute to the baseline); the loss, targets, model, decode and export are untouched. Per-capture train top-1 is added to the epoch log line and train_info.json so the record shows whether all three surveys are being learned jointly.
Expected outcome
Firm prediction (this is what the change mechanically guarantees if the model has the capacity): the three train_capture_diagnostics converge — bb_dop20 and truedop_2022 drop from 1.53 / 1.40 to below 0.3, and truedop_2023 rises from 0.015 to at most ~0.2 as it now shares weights instead of owning them. Primary (held-out truedop_2024): improves from 1.651; predicted range 0.9–1.3, with the gain coming mostly from false-fix rate falling (68% -> below 45%) as the cell beliefs stop keying on one survey's exact intensities, and usable rising from 3% to 15–35%. If instead the training diagnostics converge but 2024 stays >= 1.5, the model has stored three independent fingerprints per cell and the next experiment must restrict capacity or add an explicit cross-survey consistency term — a clean, informative negative. If the training diagnostics do NOT converge, the implementation is wrong (check the per-capture top-1 log line).
Result
mission score = 1.58323 (previous best 1.650759) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 2,928–2,928 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
3.21 km
miss, this crop
0.67
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.5837% usablecov 0.72
Fits the aircraft?all deployment gates passed largest per-area model 3,007 KB (limit 4,096 KB) · single-frame inference 1.6 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
3,500 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: design (Fable) 2 m 51 s · implement (Opus) 1 m 16 s · train 1 area 58 m 22 s · score 11 s · samples 4 s · publish 3 s · whole experiment 63 m 04 s
ts 2026-10-30T11:20:24 · commit aa74176bd3f8 ·
parent b0b23e378785 · artifacts runs/20261030_101727_experiment2 ·
agent model — · took 62 m 57 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py148 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py250 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.PAIRED-SURVEY INTERLEAVE (capture-holdout era): an area carries severaltraining photographs of the same ground. The baseline made one full latticepass per photograph in sequence, so each epoch fitted bb_dop20, thenoverwrote it with truedop_2022, then with truedop_2023 — it forgot two of thethree captures every epoch (train diagnostics 1.53 / 1.40 / 0.015). Now eachchunk draws a set of lattice positions and extracts the crop at each positionfrom EVERY training capture under ONE shared heading, and the whole(positions x captures) chunk is shuffled into mini-batches: no mini-batch issingle-survey and the epoch never ends on one photograph. Views per epoch areunchanged (len(crops) * len(imgs)); per-capture top1 is logged.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, names, imgs, crops
def extract_chunk(meta, imgs, crops, indices, rng):"""Extract one chunk of PAIRED vantages: every position in `indices` from every capture in `imgs`, with one shared heading per position. Returns (x_uint8 [N*K,3,H,W], cell_idx [N*K], pos [N*K,2], cap_idx [N*K]). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos, caps =[],[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation, shared
cell =(cy // CELL_PX)* gw +(cx // CELL_PX)for k, img in enumerate(imgs):
xs.append(extract_crop(img, cx, cy, angle))
cells.append(cell)
pos.append((float(cx), float(cy)))
caps.append(k)
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32),
torch.tensor(caps, dtype=torch.int64))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, names, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
n_caps = len(imgs)
pos_per_chunk = max(1, CHUNK_SIZE // n_caps)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0
final_top1_by_cap ={nm:0.0for nm in names}for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0
cap_correct = torch.zeros(n_caps, dtype=torch.int64)
cap_seen = torch.zeros(n_caps, dtype=torch.int64)# One full pass over the whole lattice x every capture, shuffled, fresh# rotations; each chunk holds its positions in ALL captures.
order = rng.permutation(len(crops))for start in range(0, len(order), pos_per_chunk):
x_u8, cell_idx, pos, cap_idx = extract_chunk(
meta, imgs, crops, order[start:start + pos_per_chunk], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = x_u8[idx].to(device).float()/255.0
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
hit =(logits.argmax(dim=1)== cb).cpu().long()
correct += int(hit.sum())
cb_caps = cap_idx[idx]
cap_correct.scatter_add_(0, cb_caps, hit)
cap_seen.scatter_add_(0, cb_caps, torch.ones_like(cb_caps))
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos, cap_idx
sched.step()
final_top1 = correct / max(seen,1)
final_top1_by_cap ={
nm: round(int(cap_correct[k])/ max(int(cap_seen[k]),1),4)for k, nm in enumerate(names)}
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e} "
f"top1_by_capture={final_top1_by_cap}", flush=True)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,"capture_sampling":"paired-position interleave, shared heading per position","captures": names,"positions_per_chunk": pos_per_chunk,"final_train_top1_by_capture": final_top1_by_cap,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Two sources, treated differently.
(a) THIS era — verdicts are valid, on this ruler:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle. Also read each row's
`metrics_json` -> `train_capture_diagnostics`: the gap between the
training photographs and the held-out one is the thing to close.
(b) EARLIER eras — what was tried, with the verdicts VOID. 83 experiments
over five earlier evaluation regimes have been re-scored on today's ruler:
`sqlite3 lineage_history.sqlite "SELECT era_label, src_id, title, category, hypothesis, init_strategy, mission_score, usable_fix_rate, false_fix_rate, abstain_rate, provenance FROM history WHERE kind != 'holdout_check' ORDER BY mission_score ASC;"`
Read this as a MAP OF THE SEARCH SPACE, not as a list of refutations:
every one of those experiments was kept or reverted under an evaluation
that asked about the training photograph (or about never-seen ground),
and its stored `conclusion` is about that question, not this one — which
is why the query above deliberately omits it. Their `mission_score` here
is the re-measurement on the held-out photograph, and none is good: the
best is 1.23, reached by abstaining on 77% of frames, and the 0.040
same-photograph champion sits at 1.87. So an idea from an earlier era is
neither validated nor refuted for THIS question — contrastive
pretraining, learned relighting, pretrained trunks, dense voting and the
rest are all open again. A row's `provenance` tells you how it was
measured (`rescored` = its exported model re-run today; `gated` = never
had a working model; `incomparable` = cannot be placed on this ruler).
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Baseline seed: current model/ code, no design agent ea767139
starting line: mission score 1.651
other
1.651
46 m 46 s
—
kept
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
This row is the starting line, not an idea being tested. The model that happens to be in the repo right now is trained and measured so there is a real number on the board; everything after this is an attempt to beat it.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
Why it's the new best
The first scoreable run of this lineage, so there was nothing to beat — it sets the mission score (1.651) that every later experiment must improve on. Its code is committed as the starting point later experiments branch from.
Hypothesis
Not a hypothesis -- a starting line. Run with SKIP_AGENT=1 so no design or implementation agent is involved: whatever is in model/ is trained and scored as-is to establish the number later experiments must beat, and to prove the harness works end to end.
Method
Train the current model/ code unchanged and score it with the frozen scorer. No code change is proposed or applied.
Expected outcome
An honest starting mission score on the current metric, so 'kept' from here on means genuinely better.
Result
mission score = 1.650759 (previous best 1e18) — (1 - usable_fix_rate) + false_fix_rate, worst bucket; full breakdown in metrics.json
Where the model was tested — and how far off it was
Each map is one full test area. Every dot is one held-out viewpoint: the ground under it was mapped during training, but this exact framing — 11–17 m off the nearest training vantage, at its own rotation — is one the model has never seen. It was shown a 128 m crop centered there and asked for its position. Dot color = the distance between its answer and the truth — green ≤ 100 m (at goal), amber ≤ 250 m, red beyond. A working model turns these maps green; spatial clusters of red reveal which parts of an area confuse it.
berlinmedian miss 3,129–3,129 m across lighting
One real test, end to end
what the camera saw — a real held-out 128 m crop of
berlin (the held-out truedop 2024 photograph, unmodified); its true spot is the ○ on the map.
Every experiment is shown this same crop.
→
what this model actually computed — this design points at a coordinate directly — it has no internal probability field to show.
○ true location · × its answer.
1.52 km
miss, this crop
0.47
self-reported confidence
Scoreboard — mission score per area × lighting
mission score per cell — (1 − usable-fix rate) + false-fix
rate; the worst cell (underlined) is the experiment's score. red = failed cell,
ink = better than abstaining on everything
area
truedop 2024
berlin
1.6513% usablecov 0.71
Fits the aircraft?all deployment gates passed largest per-area model 3,007 KB (limit 4,096 KB) · single-frame inference 1.6 ms on one CPU thread (proxy limit 250 ms)
training data
crops
epochs
train time
device
berlin
1,745,088
8
2,781 s
mps
crops are sampled fresh each run from the frozen train split (~45,000 distinct positions per area, times random rotation), never from eval blocks; how many to use is the experiment's own choice
Where this experiment's time went: train 1 area 46 m 22 s · score 11 s · samples 4 s · publish 3 s · whole experiment 46 m 52 s
ts 2026-09-28T16:54:15 · commit ea7671390e38 ·
parent c7c5c9307c65 · artifacts runs/20260928_160729_experiment1 ·
agent model — · took 46 m 46 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py148 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py216 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, area_dir, buckets, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64def load_scene(area: str, data_dir: Path):"""Meta + one image per TRAIN bucket (capture x lighting). The eval capture is never loaded here: the scorer asks about a photograph the model has not seen (pipeline/common.py "captures")."""
meta = load_meta(area, data_dir)
names = list(buckets(meta,"train"))
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in names]
print(f"[{area}] training buckets: {names}", flush=True)
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, imgs, crops
def extract_chunk(meta, img, crops, indices, rng):"""Extract one chunk of vantages; return (x_uint8, cell_idx, pos). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos =[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, cx, cy, angle))
cells.append((cy // CELL_PX)* gw +(cx // CELL_PX))
pos.append((float(cx), float(cy)))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0for img in imgs:# One full pass over the whole lattice, shuffled, fresh rotations.
order = rng.permutation(len(crops))for start in range(0, len(order), CHUNK_SIZE):
x_u8, cell_idx, pos = extract_chunk(
meta, img, crops, order[start:start + CHUNK_SIZE], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = x_u8[idx].to(device).float()/255.0
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
correct += int((logits.argmax(dim=1)== cb).sum())
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos
sched.step()
final_top1 = correct / max(seen,1)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The exact prompt given to the headless agent
# Autoresearch experiment — the design stage
You are one experiment of an autonomous research loop for UAV geolocalization.
Read `CLAUDE.md`'s "CAPTURE-HOLDOUT ERA" section first, then "SCOPE OVERRIDE",
then §3, §4 and §6. The harness (loop.sh) will train, score, log, and
keep/revert AFTER you exit — you only design the experiment.
## THE GOAL: MEMORIZE ONE BOUNDING BOX — THE GROUND, NOT ONE PHOTOGRAPH OF IT
This branch builds a **visual memory of Berlin**, not a model that reasons
about aerial imagery in general. One model, one bbox, deployed only over that
bbox. It is *supposed* to know this specific city by heart. You are not trying
to generalize to other places or to unmapped ground.
**But it must know the CITY, not one picture of the city.** This era exists
because the previous champion did not. Measured on 2026-09-28, same eval
crops, same grid, only the pixels changed:
| what the 0.040 champion was scored on | mission | usable | false fix | median |
|---|---|---|---|---|
| the photograph it trained on (Brandenburg DOP20) | 0.040 | 96.5% | 0.5% | 27 m |
| the same raster, +20 added to every pixel value | 1.453 | 1.5% | 46.8% | 3.1 km |
| the same raster, 1 px Gaussian blur | 1.271 | 14.2% | 41.2% | 1.3 km |
| the same raster, shifted 3 px | 0.040 | 96.8% | 0.8% | 27 m |
| Berlin TrueDOP 2022 / 2023 / 2024 (other open surveys, same ground) | 1.87 / 1.78 / 1.87 | ≤1.2% | 79–87% | 3.3–3.9 km |
A random guess over the box misses by 3.6 km. The model had memorised one
photograph's pixel intensities and fine texture (rotation was its only
augmentation); any other exposure of the same ground was a foreign image, and
its confidence head — trained on the same photograph — stayed 97% confident
while wrong. 390 confident predictions on a foreign photograph collapsed onto
40 map cells, two of them absorbing 225. Colour-matching the foreign
photograph to the training one recovered abstention (coverage 97% → 61%) but
not accuracy (median still 3.1 km): intensity is what the confidence keyed on;
the fix itself rode texture and shadow, which change between surveys.
**So the eval now asks about a photograph the model has never seen.** Berlin
has four independent open captures on one grid (`areas.yaml`): the model
trains on three (Brandenburg DOP20 summer canopy, TrueDOP 2022 leaf-off,
TrueDOP 2023 early spring) and is scored on the fourth (TrueDOP 2024), which
it never sees in any form. Season, sun angle, shadows, cars, construction and
colour balance all differ between captures. The three training captures are
also scored, as `train_capture_diagnostics` in metrics.json — LOGGED ONLY,
never part of the primary — so every experiment records its
memorisation-vs-ground gap. Read them: a design that scores 0.05 on the
training photographs and 1.9 on the held-out one has learned the pictures,
not the place.
What this implies for design, without prescribing the answer: whatever
survives a change of photograph must be learned in TRAINING (the aircraft's
camera is a fifth photograph nobody has). Decode-time tricks cannot reach it.
Photometric robustness alone is not enough — colour matching did not recover
accuracy — but it is clearly part of it. Capacity spent on pixel-exact
fingerprints of three photographs is capacity wasted; capacity spent on the
structure they share is the point.
**How the split works, because it determines what a good design looks like:**
* **Training covers ALL of Berlin** — every lattice position, whole raster.
The model is shown the entire area it must memorize.
* **Eval holds out VIEWPOINTS, not REGIONS.** Every eval frame stands on
ground that WAS in training, but is framed 11–17 m off the nearest training
vantage and at its own rotation. Mapped ground, novel view — exactly what an
aircraft over a mapped city faces.
* So the task is: **recall a memorized place from a viewpoint you have not
seen.** It is NOT: infer the location of ground you were never shown.
* A small 1-in-32-block region IS genuinely untrained, scored separately and
logged only. It can never affect keep/revert. Ignore it when designing;
it exists to reveal whether the model has spatial structure at all.
This matters because the split used to hold out regions, which left 28% of
Berlin untrained and put 100% of eval questions on never-seen ground — an
unanswerable task for a memorization model, and the likely reason ~60 earlier
experiments plateaued. Do not design as if that were still true.
**Scope:** ONE locale (Berlin), ONE lighting condition (raw daytime imagery,
no synthetic relighting — the relighting machinery is disabled on this branch),
FOUR photographs of it (three for training, one held out — see above). There
is no synthetic-lighting robustness to reason about and no other area's
texture to generalize to; there IS cross-photograph robustness, and it is the
whole score.
## THE METRIC IS THE PRODUCT REQUIREMENT, NOT AN ERROR STATISTIC
The aircraft takes a vision fix every 5–10 s and it is its ONLY drift
correction. Per frame exactly three things can happen:
| outcome | meaning |
|---|---|
| confident **and** within 100 m | **USABLE FIX** — this is the product |
| not confident | abstains — safe, it waits for the next frame |
| confident **but** outside 100 m | **FALSE FIX** — dangerous, it injects a wrong position into navigation |
mission_score = (1 - usable_fix_rate) + false_fix_rate [MINIMIZED]
* **0.0** = every frame a usable fix. **1.0** = abstains everywhere.
**2.0** = confidently wrong everywhere — *strictly worse than silence*,
because a confidently wrong fix corrupts navigation while an abstention
merely costs time.
* Therefore: **making the model honest is as valuable as making it
accurate.** Converting a confident-but-wrong frame into an abstention
improves the score. Converting an abstention into a correct confident fix
improves it twice as much. Both are real progress; design for either.
* A cell whose coverage falls below 0.2 scores FAIL — you cannot pass by
abstaining on everything.
**Do not optimize an error statistic.** Median, geometric mean, p10, p25 are
all still logged, and you may read them to understand *why* something worked,
but none of them is the target. Each was tried as the primary and each
rewarded something the aircraft does not want — the median rewarded a model
that guesses the map centre, and it reverted the first experiment that had
actually begun memorizing. If your design improves the geometric mean while
`usable_fix_rate` stays flat, it has not helped the product.
## Your job, in order
0. **Skim the library (optional input).** `autoresearch/library.md` holds
the human researcher's inspiration notes. They do not fix your answer
and you are free to ignore them — pick an entry up only when it
genuinely fits your read of the history, and if you build on one, say
so in your hypothesis.
1. **Review the research history.** Query the lineage DB:
`sqlite3 experiments.sqlite "SELECT id, title, category, hypothesis, expected_outcome, result, conclusion, primary_metric, kept FROM experiments ORDER BY id DESC LIMIT 15;"`
Note which hypotheses were supported/refuted. Do not repeat a refuted
experiment without a materially new angle.
**Plateau rule (advisory only on this branch):** the harness's automatic
pivot enforcement (mandatory-pivot preamble, backbone-carry rejection) is
disabled on berlin-slim — see CLAUDE.md "BRANCH OVERRIDE". Nothing will
force or reject a pivot below. That said, the underlying discipline still
applies by judgment: if three or more consecutive experiments were
reverted, don't attempt another variation of the last refuted mechanism.
Either pick a design family absent from the history (pretrained init,
training-scale/coverage, a different coordinate parameterization, capacity
allocation, decode resolution, …) or attack the bottleneck the refuted hypotheses
jointly point at — checking, via `arch_json`
(`SELECT arch_json FROM experiments WHERE kind='development' ORDER BY id
DESC LIMIT 10;`), which stage names never carry `"changed": true`, since a
losing streak is usually one unquestioned stage (trunk / descriptor /
decode) with everything else churning around it, not a missing family.
2. **Design ONE focused experiment** — proper experiment design, pre-registered
before you touch code. Write it to `runs/pending_experiment.json`:
```json
{
"title": "one-line name",
"category": "architecture|loss|augmentation|relighting|training|quantization|other",
"hypothesis": "what you believe is limiting the metric and why this change addresses it",
"method": "the ONE focused change, concretely (files, mechanism)",
"expected_outcome": "predicted effect on mission_score, and on usable_fix_rate / false_fix_rate specifically, quantified if possible",
"init_strategy": "from-scratch | pretrained:<name>",
"eli5": "2-4 sentences for a smart non-ML reader: what you changed and why it might help, in everyday language — analogies welcome, zero jargon",
"architecture": {"stages": [
{"name": "Camera frame", "detail": "128×128 px daytime crop, Berlin only; trained on three survey photographs, scored on a fourth it never saw", "changed": false},
{"name": "Feature extractor", "detail": "plain-language description", "changed": false},
{"name": "…", "detail": "…", "changed": true}
]}
}
```
Do NOT draw the architecture figure here — that is a separate agent's
job, run later, only for experiments that actually reach training (see
`autoresearch/prompt_figure.md`). Spending time perfecting an SVG for a
design that might get rejected before it ever runs was wasted work; this
stage's only output is the decision itself.
`eli5` and `architecture` feed the human-facing gallery. `architecture.stages`
is the model's inference path left-to-right, camera frame → (lat, lon,
confidence) output — one box per stage, plain-language `detail`,
`"changed": true` ONLY on the stages this experiment touches. Reuse the
previous experiment's stage names verbatim wherever a stage is unchanged
(check `SELECT arch_json FROM experiments WHERE arch_json IS NOT NULL ORDER BY id DESC LIMIT 1;`) —
stage names must stay consistent across experiments since the later
figure-drawing stage and plateaucheck both compare/track them by name.
A change that only affects training (loss, augmentation, schedule) keeps
the inference stages unchanged and adds one final stage with
`"train_only": true` describing the training signal.
3. **Write the implementation brief.** You do NOT edit `model/` yourself —
a separate implementation agent applies your design, seeing only the
current code plus what you pre-registered. Add one more field to
`runs/pending_experiment.json`:
```
"implementation_brief": "exact file-level instructions: which functions/
blocks in model/model.py and model/train.py change and how, what stays
untouched, and every contract to preserve"
```
Be precise enough that a competent engineer with no other context
implements it in one pass. Always restate the fixed contracts:
`train.py`'s CLI and the ONNX export contract in `model/model.py`'s
docstring — the frozen scorer depends on them.
## Hard rules
- Edit ONLY `runs/pending_experiment.json`. You never edit `model/` (the
implementation stage does) and files listed in `/FROZEN` are off-limits;
the harness hard-reverts any change to them.
- ONE focused change per experiment — if you can't describe it in one sentence,
it's too big. Prefer architectural/procedural novelty over hyperparameter
nudges (§3): changing a learning rate is a weak experiment; changing the
coordinate parameterization, loss family, capacity allocation, decode
resolution, or model topology is a strong one.
- Do not run training yourself; the harness does that.
- Stay within the deployment gates: exported ONNX ≤ 4 MiB per area, host
latency proxy ≤ 250 ms (see pipeline/score.py).
- Keep one experiment tractable to train. This branch trains Berlin only, on
a laptop GPU, and every epoch now covers THREE photographs (the training
loop in `model/train.py` iterates `buckets(meta, "train")`, so an epoch is
~3x the old one); an inherently expensive per-sample mechanism (e.g. many-round
iterative solves over thousands of votes per crop) can still push a round
into hours. Budget the per-crop cost so a round finishes in a sensible
wall-time — an idea that can't be evaluated in a round can't be kept.
What the training imagery looks like (example patches — illustration, not the training set)
In the current configuration, training and eval use the raw daytime reference imagery as fetched — no synthetic relighting, no low-light sensor simulation (that machinery still exists in the frozen pipeline and is used by the full spec's 6-lighting-condition setup, just switched off here). Below, one example 256 m patch per area, as-is. This illustrates the dataset, not this experiment's performance — the actual training set is thousands of distinct crops (see “training data” above), and this rendering only changes if the source imagery is re-fetched.
Decode-consistent training targets: bilinear tent cell labels + residual offset against the model's own pooled centroid 7a1314f9
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.873 — worse than silence.
loss
1.873
22 m 58 s
$3.90
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model learns Berlin as a grid of tiles, like a giant bingo card. Until now, a photo taken straddling two tiles was taught 'you are in tile A, full stop' -- even though a nearly identical photo one step left would be taught 'tile B, full stop'. That is confusing teaching, and the model wasted effort memorizing an invisible boundary instead of the city. Now we teach it honestly: 'you are 60% in A, 40% in B', matching where the camera really stands. And the little aim-correction step at the end used to re-add information the averaging already provided, overshooting the target; now it is taught to fix only whatever small error actually remains.
Hypothesis
Experiment 4 proved that border-split belief is knowledge, not confusion, by pooling the 3x3 neighborhood at DECODE time (abstain 0.1475 -> 0.05, kept at 0.09018). But the TRAINING signal still teaches the pre-exp-4 objective: every view gets a hard one-cell label, even though the 24 m lattice places roughly 1 in 3 training views within ~12 m of a 128 m cell border, where nearly identical frames receive contradictory hard labels. That label noise is visible in exp 4's curves: train top1 capped at 0.83 and mean max softmax at 0.57 with loss still falling at epoch 8 -- the model spends capacity and epochs fighting an arbitrary tile boundary instead of memorizing place appearance. Worse, there is a latent train/decode inconsistency the soft decode exposed: the offset head is trained to point from the CONTAINING cell's centre to the true spot, but at decode it is added to the pooled CENTROID -- so whenever mass legitimately splits across a border (which tent-shaped belief makes systematic), the sub-cell position is double-counted, pushing the fix past the truth by up to the offset magnitude. The fix for both is the same principle: make the training targets the thing the decode actually reads. (1) Replace the hard cell label with a bilinear 'tent' target that splits probability mass over the <=4 cell centres nearest the true continuous position -- a target whose 3x3-pooled mass at truth is ~1.0 everywhere and whose centroid IS the true position, so gradients from nearly identical border views agree instead of conflicting. (2) Retrain the offset head as a RESIDUAL corrector: its target becomes the (detached) gap between the model's own pooled-centroid decode and the true position, clamped to (-0.5, 0.5) cell units -- it now fixes whatever error the centroid leaves rather than re-adding position the centroid already encodes. This is one mechanism -- train/decode consistency -- expressed in the two targets, with the deployed graph untouched.
Method
Training-signal change only; the exported inference graph does not change. In model/train.py: extract_chunk additionally returns the continuous pixel position (cx, cy) per view; a new helper builds the soft target distribution by bilinear tent weighting over the <=4 nearest cell centres (edge-clamped via scatter_add), mixed with the existing 0.05 uniform label smoothing; the offset target is computed per batch as the clamped residual between the true normalized position and the model's own detached 3x3 pooled centroid (recomputed in train.py from softmax(logits) using the model's cell_u/cell_v buffers, mirroring forward()'s mask logic). In model/model.py: loss_fn's signature changes to accept a dense soft target ([B, n_cells]) and the residual offset target, computing soft cross-entropy -(target * log_softmax).sum(1).mean() + 1.0 * smooth_l1 on the offset. CellLocNet, forward(), export_onnx, CELL_PX, epochs, LR schedule, and the full-lattice coverage loop all stay exactly as in exp 4.
Mission score 1.873 — 0.0% of held-out frames give a usable fix, 87.2% are confident and wrong, 12.8% abstain. Median miss 3.32 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.81
implementation agent
$1.09
total
$3.90
by model — claude-fable-5 $2.81 · claude-opus-5 $1.09 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: mission score — (1 - usable) + false, same photograph, scoring 0.040. Asked over: viewpoint holdout, daytime only, Berlin only, eval on the training photograph. The metric became the product requirement itself and the approach worked: 0.040, 96.5% usable. But the eval crops came from the very raster the model trained on. On 2026-09-28 the champion was scored on other open photographs of the same ground (Berlin TrueDOP 2022/2023/2024) and on +20 brightness of its own raster: 1.78-1.97 and 1.45. It had memorised one photograph's pixels, not the city. Re-scored here on the held-out photograph like every earlier era.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8730% usablecov 0.87
era Mission score · ts 2026-07-31T11:43:46 ·
commit 7a1314f9a465 · artifacts runs/20260731_112048_experiment5 ·
took 22 m 58 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py148 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix. The TRAINING TARGETS are decode-consistent: thecell target is a bilinear tent distribution over the <=4 nearest cell centres(so a border view is taught the honest split its pooled decode will produce,not an arbitrary one-cell label), and the offset target is the residual thepooled centroid leaves rather than the position that centroid already encodes.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
soft_target: torch.Tensor, offset_target: torch.Tensor)-> torch.Tensor:"""Soft cross-entropy against a bilinear tent distribution over cell centres + smooth-L1 on a residual offset target. soft_target is a dense [B, n_cells] distribution (already includes label smoothing); offset_target is [B, 2] in (-0.5, 0.5) cell units, the residual the pooled-centroid decode leaves. No confidence loss term, as before. """
ce =-(soft_target * F.log_softmax(logits, dim=1)).sum(dim=1).mean()return ce +1.0* F.smooth_l1_loss(offset_pred, offset_target)def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py212 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. Targets are DECODE-CONSISTENT: the celltarget is a bilinear tent over the <=4 nearest cell centres (whose centroid isthe true position, matching what the 3x3 pooled decode reads), and the offsettarget is the residual that pooled centroid leaves rather than the containingcell's within-cell position. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64def load_scene(area: str, data_dir: Path):"""Meta + the relight image(s). One pass-through bucket on this branch."""
meta = load_meta(area, data_dir)
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in LIGHTING_BUCKETS]
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, imgs, crops
def extract_chunk(meta, img, crops, indices, rng):"""Extract one chunk of vantages; return (x_uint8, cell_idx, pos). `cell_idx` is the containing cell, kept only for the top1 log line — the loss targets are built from `pos`, the continuous raster-pixel position. """
gw,_= grid_dims(meta)
xs, cells, pos =[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, cx, cy, angle))
cells.append((cy // CELL_PX)* gw +(cx // CELL_PX))
pos.append((float(cx), float(cy)))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(pos, dtype=torch.float32))def make_soft_targets(pos, meta, n_cells, gw, gh, smoothing=0.05):"""Bilinear tent target over the <=4 cell centres nearest each true position. pos: [B,2] raster px. Returns dense [B, n_cells] float32. The decode reads a 3x3-pooled centroid, so the target is the distribution whose centroid IS the true position: nearly identical border views now get nearly identical targets instead of contradictory hard labels. Index clamping merges out-of-grid neighbours' mass into the border cell via scatter_add_ — that mass is kept, not dropped, so rows always sum to 1. """
fu = pos[:,0]/ CELL_PX -0.5# position in cell-centre coordinates
fv = pos[:,1]/ CELL_PX -0.5
i0 = fu.floor(); j0 = fv.floor()
a =(fu - i0); b =(fv - j0)# in [0,1)
tgt = torch.zeros(len(pos), n_cells, dtype=torch.float32, device=pos.device)for di, wu in((0,1- a),(1, a)):for dj, wv in((0,1- b),(1, b)):
ci =(i0 + di).clamp(0, gw -1).long()
cj =(j0 + dj).clamp(0, gh -1).long()
tgt.scatter_add_(1,(cj * gw + ci).unsqueeze(1),(wu * wv).unsqueeze(1))return tgt *(1- smoothing)+ smoothing / n_cells
def residual_offset_target(model, logits, pos, meta):"""(true position - model's 3x3 pooled centroid), in cell units, clamped to the offset head's (-0.5, 0.5) range. Detached. Mirrors forward()'s pooling exactly, using the model's own buffers so the grid geometry stays single-sourced. Early in training the argmax is noisy, so this target is nonstationary; that is expected and bounded by the clamp. """with torch.no_grad():
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u = model.cell_u.index_select(0, idx)
win_v = model.cell_v.index_select(0, idx)
du =(model.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(model.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6* model.scale_u)&(dv <=1.6* model.scale_v)).float()
q = p * mask
m = q.sum(dim=1).clamp_min(1e-9)
cu =(q * model.cell_u.unsqueeze(0)).sum(dim=1)/ m
cv =(q * model.cell_v.unsqueeze(0)).sum(dim=1)/ m
true_u = pos[:,0]/ meta["width"]; true_v = pos[:,1]/ meta["height"]
ru =((true_u - cu)/ model.scale_u).clamp(-0.5,0.5)
rv =((true_v - cv)/ model.scale_v).clamp(-0.5,0.5)return torch.stack([ru, rv], dim=1)def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, imgs, crops = load_scene(area, data_dir)
gw, gh = grid_dims(meta)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0for img in imgs:# One full pass over the whole lattice, shuffled, fresh rotations.
order = rng.permutation(len(crops))for start in range(0, len(order), CHUNK_SIZE):
x_u8, cell_idx, pos = extract_chunk(
meta, img, crops, order[start:start + CHUNK_SIZE], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = x_u8[idx].to(device).float()/255.0
cb, pb = cell_idx[idx].to(device), pos[idx].to(device)
logits, off_pred = model.training_outputs(xb)
soft_t = make_soft_targets(pb, meta, model.n_cells, gw, gh)
off_t = residual_offset_target(model, logits, pb, meta)
loss = loss_fn(logits, off_pred, soft_t, off_t)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)# top1 is vs. the CONTAINING cell, so it now reads lower# than exp 4's 0.83 BY DESIGN: border views are supposed# to split mass across the tent's cells. Judge# convergence by loss and by eval, not by this.
correct += int((logits.argmax(dim=1)== cb).sum())
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, pos
sched.step()
final_top1 = correct / max(seen,1)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
5.4
Local belief pooling decode: confidence = softmax mass on the 3x3 cell neighborhood, fix = its mass-weighted centroid 7958b03d
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.893 — worse than silence.
architecture
1.893
20 m 36 s
$2.75
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model localizes by picking which 128-metre map tile it is over, like answering a multiple-choice question, and it only speaks up when one answer gets enough of its vote. But when the UAV flies near the border between two tiles, the model honestly splits its vote between them — and then stays silent, even though both answers point at the same street corner. That silence was most of our remaining score. Now neighbouring tiles get to pool their votes: if the belief lands in one tight cluster on the map, we place the fix at the cluster's balance point and speak up; if it is scattered across the city, we stay silent exactly as before.
Hypothesis
Experiment 3's champion is accurate but needlessly silent: of the 0.1827 mission score, 0.1475 is abstention and only 0.0175 is false fixes, while its confident frames are 98% accurate (usable 0.835 vs false 0.0175). Eval views stand 11-17 m off-lattice, so a view near a cell border legitimately splits softmax mass between adjacent 128 m cells; with confidence defined as mass on the single argmax cell, a 2-way border split can and a 4-way corner split must fall below the scorer's 0.3 threshold even though every competing hypothesis names the same neighborhood. That is label ambiguity, not place ambiguity, and the current decode cannot tell them apart. Pooling belief over the 3x3 block centred on the argmax cell makes confidence measure 'does the model know WHERE it is' rather than 'does it know which arbitrary tile label applies', converting adjacent-split abstentions into fixes while leaving genuine far-field ambiguity (mass scattered across distant cells) below threshold. Placing the fix at the mass-weighted centroid of that local block should also cut error near borders, since the centroid interpolates between competing cell centres instead of snapping to one.
Method
Change ONLY the deployed decode in model/model.py's CellLocNet.forward(); training_outputs(), loss_fn, train.py, and the full-lattice training schedule stay byte-identical to the exp-3 champion. New forward(): p = softmax(logits); idx = argmax; build a [B, n_cells] mask selecting cells whose centre lies within 1.6 cell-pitches (Chebyshev, per axis) of the winning cell's centre — computed on the fly from the existing cell_u/cell_v buffers with Sub/Abs/Less/Mul ops so it exports cleanly to ONNX and stays edge-safe with no duplicate counting; q = p * mask; conf = sum(q); fix = sum(q/conf * cell centres) + the existing tanh offset head contribution, clamped to [0,1] as before. conf is a sub-sum of a softmax so it remains in [0,1] and is >= the old single-cell conf by construction: abstentions can only convert, never appear.
Mission score 1.893 — 0.8% of held-out frames give a usable fix, 90.0% are confident and wrong, 9.2% abstain. Median miss 3.14 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$1.95
implementation agent
$0.80
total
$2.75
by model — claude-fable-5 $1.95 · claude-opus-5 $0.80 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: mission score — (1 - usable) + false, same photograph, scoring 0.090. Asked over: viewpoint holdout, daytime only, Berlin only, eval on the training photograph. The metric became the product requirement itself and the approach worked: 0.040, 96.5% usable. But the eval crops came from the very raster the model trained on. On 2026-09-28 the champion was scored on other open photographs of the same ground (Berlin TrueDOP 2022/2023/2024) and on +20 brightness of its own raster: 1.78-1.97 and 1.45. It had memorised one photograph's pixels, not the city. Re-scored here on the held-out photograph like every earlier era.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8931% usablecov 0.91
era Mission score · ts 2026-07-31T11:20:39 ·
commit 7958b03db79b · artifacts runs/20260731_110003_experiment4 ·
took 20 m 36 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py145 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init, decoded byLOCAL BELIEF POOLING. The map is cut into CELL_PX-square cells (Berlin:55x54 = 2970); a conv trunk feeds a C-way softmax over cells plus a within-celloffset head. The deployed decode pools belief over the 3x3 block of cellscentred on the argmax cell: confidence is the softmax mass on that wholeneighborhood, and the fix is the mass-weighted centroid of those cell centres,nudged by the offset. Eval views stand 11-17 m off-lattice, so a view near acell border honestly splits its mass between adjacent cells — that is labelambiguity, not place ambiguity, and pooling makes confidence measure "does themodel know WHERE it is" rather than "which arbitrary tile label applies".Belief scattered across DISTANT cells still falls below threshold, so genuinefar-field ambiguity remains a safe abstention rather than a false fix. Cellsize is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix.The whole decode (softmax -> argmax -> neighborhood mask -> pooled centroid ->offset -> conf) lives INSIDE the exported graph, because the scorer runs theONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):# Local belief pooling: confidence is the softmax mass on the 3x3 block# of cells centred on the argmax cell, and the fix is that block's# mass-weighted centroid (plus the within-cell offset). A border view# splitting mass between adjacent cells still names one place, so it# stays a fix; mass scattered across distant cells stays an abstention.
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
idx = p.argmax(dim=1)
win_u =self.cell_u.index_select(0, idx)
win_v =self.cell_v.index_select(0, idx)# 1.6 cell-pitches per axis (Chebyshev) selects exactly the 3x3 block# with float-safety margin — the next ring sits at 2.0 pitches. Edge# cells simply have fewer neighbours in range; nothing is counted twice.
du =(self.cell_u.unsqueeze(0)- win_u.unsqueeze(1)).abs()
dv =(self.cell_v.unsqueeze(0)- win_v.unsqueeze(1)).abs()
mask =((du <=1.6*self.scale_u)&(dv <=1.6*self.scale_v)).float()
q = p * mask
conf = q.sum(dim=1)# sub-sum of a softmax: in [0,1], >= single-cell max
w = q / conf.unsqueeze(1).clamp_min(1e-9)
u =(w *self.cell_u.unsqueeze(0)).sum(dim=1)+ offset[:,0]*self.scale_u
v =(w *self.cell_v.unsqueeze(0)).sum(dim=1)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
target_cell_idx: torch.Tensor, target_offset: torch.Tensor)-> torch.Tensor:"""Cross-entropy on the true map cell + smooth-L1 on the within-cell offset. No confidence loss term: confidence IS the softmax mass on the winning cell, so honest abstention falls out of the parameterization rather than being trained against a proxy target. Label smoothing is light (0.05) so a memorized cell can still reach ~0.95 and clear the scorer's 0.3 threshold. """return(F.cross_entropy(logits, target_cell_idx, label_smoothing=0.05)+1.0* F.smooth_l1_loss(offset_pred, target_offset))def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py149 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64def load_scene(area: str, data_dir: Path):"""Meta + the relight image(s). One pass-through bucket on this branch."""
meta = load_meta(area, data_dir)
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in LIGHTING_BUCKETS]
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, imgs, crops
def extract_chunk(meta, img, crops, indices, rng):"""Extract one chunk of vantages; return (x_uint8, cell_idx, offset)."""
gw,_= grid_dims(meta)
xs, cells, offs =[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, cx, cy, angle))
cells.append((cy // CELL_PX)* gw +(cx // CELL_PX))
offs.append(((cx % CELL_PX)/ CELL_PX -0.5,(cy % CELL_PX)/ CELL_PX -0.5))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(offs, dtype=torch.float32))def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, imgs, crops = load_scene(area, data_dir)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0for img in imgs:# One full pass over the whole lattice, shuffled, fresh rotations.
order = rng.permutation(len(crops))for start in range(0, len(order), CHUNK_SIZE):
x_u8, cell_idx, off = extract_chunk(
meta, img, crops, order[start:start + CHUNK_SIZE], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = x_u8[idx].to(device).float()/255.0
cb, ob = cell_idx[idx].to(device), off[idx].to(device)
logits, off_pred = model.training_outputs(xb)
loss = loss_fn(logits, off_pred, cb, ob)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)
correct += int((logits.argmax(dim=1)== cb).sum())
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, off
sched.step()
final_top1 = correct / max(seen,1)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
5.3
Full-lattice coverage training for the map-cell classifier: every epoch is a complete pass over all 72,712 vantages 014a6196
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.871 — worse than silence.
training
1.871
22 m 28 s
$3.61
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last time we gave the model a multiple-choice map of Berlin — 3,000 tiles, point to the right one — but we only let it study for 84 seconds, and it never even saw most of the city. It answered every question with a shrug. This experiment changes nothing about the model itself; we just run the full study session: show it every spot in Berlin, eight times over, from different angles each time — about 20 minutes instead of 84 seconds. A student who has actually walked every street can start answering with confidence instead of shrugging.
Hypothesis
Experiment 2's map-cell classification decode was not refuted — it was starved. Its cross-entropy loss started at ln(2970)=8.0 (uniform over cells) and was still falling linearly (8.10 -> 6.22) when training stopped after 83.8 seconds: 8 epochs x 6,000 sampled crops = 48,000 total views for a 2,970-class memorization problem, i.e. ~16 views per cell across all headings, while most of the 72,712-position training lattice was never seen even once. Final mean true-cell probability was e^-6.2 = 0.2%, so max softmax never approached the scorer's 0.3 confidence threshold and the model abstained on every frame — the coverage<0.2 FAIL, not a verdict on the parameterization. The limiting factor is training coverage, not architecture: a model asked to memorize all of Berlin must actually be shown all of Berlin, repeatedly. Measured throughput (48k views in 84s incl. extraction, ~565 views/s on MPS) says a full-lattice pass costs ~2 minutes, so complete coverage was affordable all along — exp 2 used less than 1% of a sensible training budget.
Method
Restore experiment 2's CellLocNet (model.py verbatim from runs/20260731_102754_experiment2/model_src/model.py — conv trunk to 160 ch, 2,970-way cell softmax over 128 m cells, within-cell offset head, confidence = winning-cell softmax mass, decode inside the ONNX graph) and change ONLY the training procedure in model/train.py: each epoch is now one full pass over ALL 72,712 lattice positions with a fresh random rotation per position per epoch (streamed in shuffled chunks of 4,096 to bound memory), instead of a 6,000-crop random subsample. With the harness's --epochs 8 this gives 581,696 total views (~196 per cell, 12x exp 2) in a projected ~20 min wall. Cosine LR decay 1e-3 -> 1e-4 across the run (a constant LR is wrong for a 12x-longer schedule). Loss, label smoothing 0.05, batch size 64, architecture, and export all unchanged from exp 2.
Mission score 1.871 — 0.8% of held-out frames give a usable fix, 87.8% are confident and wrong, 11.5% abstain. Median miss 3.16 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.61
implementation agent
$0.99
total
$3.61
by model — claude-fable-5 $2.61 · claude-opus-5 $0.99 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: mission score — (1 - usable) + false, same photograph, scoring 0.183. Asked over: viewpoint holdout, daytime only, Berlin only, eval on the training photograph. The metric became the product requirement itself and the approach worked: 0.040, 96.5% usable. But the eval crops came from the very raster the model trained on. On 2026-09-28 the champion was scored on other open photographs of the same ground (Berlin TrueDOP 2022/2023/2024) and on +20 brightness of its own raster: 1.78-1.97 and 1.45. It had memorised one photograph's pixels, not the city. Re-scored here on the held-out photograph like every earlier era.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8711% usablecov 0.89
era Mission score · ts 2026-07-31T10:59:55 ·
commit 014a61968297 · artifacts runs/20260731_103727_experiment3 ·
took 22 m 28 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py122 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init. The mapis cut into CELL_PX-square cells (Berlin: 55x54 = 2970); a conv trunk feeds aC-way softmax over cells plus a within-cell offset head. The deployed fix isthe winning cell's centre nudged by the offset, and confidence is the softmaxmass on that winning cell — so belief spread across many cells reads as lowconfidence and the frame becomes a safe abstention rather than a false fix.Cell size is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix.The whole decode (argmax -> cell-centre table lookup -> offset -> conf) livesINSIDE the exported graph, because the scorer runs the ONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
conf, idx = p.max(dim=1)
u =self.cell_u.index_select(0, idx)+ offset[:,0]*self.scale_u
v =self.cell_v.index_select(0, idx)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
target_cell_idx: torch.Tensor, target_offset: torch.Tensor)-> torch.Tensor:"""Cross-entropy on the true map cell + smooth-L1 on the within-cell offset. No confidence loss term: confidence IS the softmax mass on the winning cell, so honest abstention falls out of the parameterization rather than being trained against a proxy target. Label smoothing is light (0.05) so a memorized cell can still reach ~0.95 and clear the scorer's 0.3 threshold. """return(F.cross_entropy(logits, target_cell_idx, label_smoothing=0.05)+1.0* F.smooth_l1_loss(offset_pred, target_offset))def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py149 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification with FULL-LATTICE coverage. Each EPOCH is onecomplete pass over ALL train-lattice positions (not a random subsample), with afresh random rotation drawn per position per epoch, so over the run the modelsees epochs*len(crops) distinct (position, heading) vantages and every map cellis visited many times — the coverage a C-way cell classifier needs to memorizeits box. Positions are streamed in shuffled chunks of CHUNK_SIZE so only onechunk of pixels is ever resident. `--max-crops-per-bucket` is still accepted forCLI compatibility but no longer controls sampling; it is logged as`max_crops_per_bucket_arg`.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
import torch.nn.functional as F
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import extract_crop, list_crops
CHUNK_SIZE =4096# lattice positions extracted at a time (bounds memory)
BATCH_SIZE =64def load_scene(area: str, data_dir: Path):"""Meta + the relight image(s). One pass-through bucket on this branch."""
meta = load_meta(area, data_dir)
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in LIGHTING_BUCKETS]
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, imgs, crops
def extract_chunk(meta, img, crops, indices, rng):"""Extract one chunk of vantages; return (x_uint8, cell_idx, offset)."""
gw,_= grid_dims(meta)
xs, cells, offs =[],[],[]for i in indices:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, cx, cy, angle))
cells.append((cy // CELL_PX)* gw +(cx // CELL_PX))
offs.append(((cx % CELL_PX)/ CELL_PX -0.5,(cy % CELL_PX)/ CELL_PX -0.5))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous()return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(offs, dtype=torch.float32))def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, imgs, crops = load_scene(area, data_dir)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)# A 12x-longer schedule wants a decaying LR, not the constant 1e-3.
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=epochs,
eta_min=1e-4)
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")
final_top1 =0.0for epoch in range(epochs):
model.train()
loss_sum, correct, conf_sum, seen =0.0,0,0.0,0for img in imgs:# One full pass over the whole lattice, shuffled, fresh rotations.
order = rng.permutation(len(crops))for start in range(0, len(order), CHUNK_SIZE):
x_u8, cell_idx, off = extract_chunk(
meta, img, crops, order[start:start + CHUNK_SIZE], rng)
n = len(x_u8)
perm = torch.randperm(n)for i in range(0, n, BATCH_SIZE):
idx = perm[i:i + BATCH_SIZE]
xb = x_u8[idx].to(device).float()/255.0
cb, ob = cell_idx[idx].to(device), off[idx].to(device)
logits, off_pred = model.training_outputs(xb)
loss = loss_fn(logits, off_pred, cb, ob)
opt.zero_grad(); loss.backward(); opt.step()with torch.no_grad():
loss_sum += loss.item()* len(idx)
correct += int((logits.argmax(dim=1)== cb).sum())
conf_sum += float(F.softmax(logits, dim=1).max(dim=1).values.sum())
seen += len(idx)del x_u8, cell_idx, off
sched.step()
final_top1 = correct / max(seen,1)
print(f"[{area}] epoch {epoch +1}/{epochs} loss={loss_sum / max(seen,1):.4f} "
f"top1={final_top1:.4f} mean_max_softmax={conf_sum / max(seen,1):.4f} "
f"views={seen} lr={sched.get_last_lr()[0]:.2e}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": epochs * len(crops)* len(imgs),"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * len(crops)* len(imgs),"full_lattice_epochs":True,"final_train_top1": round(final_top1,4),"chunk_size": CHUNK_SIZE,"max_crops_per_bucket_arg": max_crops_per_bucket,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
5.2
Map-cell classification decode: pick 1 of ~3,000 128 m tiles, confidence = softmax mass 9011afe6
The loop discarded this — no improvement under the metric then in force.
architecture
1.003
9 m 24 s
$4.25
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The old model answered 'where is this photo?' by guessing two GPS numbers directly — and when unsure, that kind of guess drifts toward the middle of the map, which is confidently wrong almost everywhere. The new model works like a mail sorter instead: Berlin is cut into about 3,000 postcode-sized tiles, and the model picks which tile the photo belongs to, then fine-tunes the spot inside it. The tiles are sized so that naming the right tile already counts as a good fix. Best of all, a multiple-choice answer comes with built-in honesty: if the model's belief is smeared across many tiles, its top choice scores low and the UAV simply says 'not sure' and waits for the next frame — which is far safer than pointing at the wrong street with full confidence.
Hypothesis
The baseline fails for two coupled reasons visible in its metrics (coverage 1.0, false_fix_rate 1.0, p10 531 m): (1) sigmoid+MSE direct regression of (u,v) through a global-average-pooled feature is a mean-seeking objective — under ambiguity it interpolates toward the map centre instead of committing to a place, which is structurally wrong for a memorization task; (2) its confidence head is trained on 'error < half the map extent', a target that is always satisfied, so it confidently emits every guess and the mission score sits at the confidently-wrong-everywhere ceiling of 2.0. Reparameterizing localization as classification over a grid of 128 m map cells attacks both at once: cross-entropy over cells is multimodal and memorization-friendly (each cell gets its own logit — no averaging between competing hypotheses), and the softmax distribution is an intrinsic honesty signal — when belief is spread across many tiles the max probability drops below the scorer's 0.3 threshold and the frame becomes a safe abstention instead of a false fix. The cell size is chosen so the parameterization alone suffices: a 128 m cell's half-diagonal is 90.5 m < the 100 m usable radius, so a correctly classified cell centre is already a usable fix, with a small offset head adding margin.
Method
One change: replace the regression head/decode in model/model.py with a map-cell classification head plus within-cell offset, decoded inside the exported ONNX graph (argmax over cell logits -> gather precomputed cell-centre table -> add offset), with conf = max softmax probability; model/train.py switches the loss to cross-entropy on the centre cell + smooth-L1 on the within-cell offset, and resamples a fresh 6,000-crop lattice subset with fresh rotation angles each epoch (a coverage precondition of the mechanism: 2,970 cells cannot be covered by one fixed 6,000-crop draw, but 8 fresh draws see ~48k distinct vantages, ~16 per cell). No other stage changes; harness CLI and its 6000/8 budget respected as-is.
Conclusion at the time
REVERTED — mission score did not improve (1000000000.0 vs best 2.00075); change discarded
Re-measured on today's ruler
Mission score 1.003 — 0.0% of held-out frames give a usable fix, 0.2% are confident and wrong, 99.8% abstain. Median miss 2.74 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$3.14
implementation agent
$1.11
total
$4.25
by model — claude-fable-5 $3.13 · claude-opus-5 $1.11 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: mission score — (1 - usable) + false, same photograph, scoring —. Asked over: viewpoint holdout, daytime only, Berlin only, eval on the training photograph. The metric became the product requirement itself and the approach worked: 0.040, 96.5% usable. But the eval crops came from the very raster the model trained on. On 2026-09-28 the champion was scored on other open photographs of the same ground (Berlin TrueDOP 2022/2023/2024) and on +20 brightness of its own raster: 1.78-1.97 and 1.45. It had memorised one photograph's pixels, not the city. Re-scored here on the held-out photograph like every earlier era.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.0030% usablecov 0.00
era Mission score · ts 2026-07-31T10:37:18 ·
commit 9011afe60dec · artifacts runs/20260731_102754_experiment2 ·
took 9 m 24 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them.
model/model.py122 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: localization as MAP-CELL CLASSIFICATION, from-scratch init. The mapis cut into CELL_PX-square cells (Berlin: 55x54 = 2970); a conv trunk feeds aC-way softmax over cells plus a within-cell offset head. The deployed fix isthe winning cell's centre nudged by the offset, and confidence is the softmaxmass on that winning cell — so belief spread across many cells reads as lowconfidence and the frame becomes a safe abstention rather than a false fix.Cell size is chosen so the parameterization alone suffices: a 128 m cell'shalf-diagonal is 90.5 m, inside the 100 m usable radius, so naming the rightcell is already a usable fix.The whole decode (argmax -> cell-centre table lookup -> offset -> conf) livesINSIDE the exported graph, because the scorer runs the ONNX directly."""import math
import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
CELL_PX =128# map cell edge in raster px (== metres at this GSD)def grid_dims(meta: dict)-> tuple[int, int]:"""(gw, gh): map-cell grid covering the area's raster."""return(math.ceil(meta["width"]/ CELL_PX), math.ceil(meta["height"]/ CELL_PX))class CellLocNet(nn.Module):"""Conv trunk -> GAP -> (C-way cell logits, within-cell offset). forward() is the DEPLOYED path and returns [B, 3] = (u, v, conf). training_outputs() exposes the raw (logits, offset) for the loss. """def __init__(self, meta: dict):
super().__init__()
gw, gh = grid_dims(meta)self.gw,self.gh = gw, gh
self.n_cells = gw * gh
width, height = meta["width"], meta["height"]
chans =[3,32,64,128,160]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cls_head = nn.Linear(chans[-1],self.n_cells)self.off_head = nn.Linear(chans[-1],2)# Cell-centre lookup tables, in normalized map coords. Registered as# buffers so they bake into the ONNX graph as constants.
idx = np.arange(self.n_cells)
cell_u =((idx % gw)+0.5)* CELL_PX / width
cell_v =((idx // gw)+0.5)* CELL_PX / height
self.register_buffer("cell_u", torch.tensor(cell_u, dtype=torch.float32))self.register_buffer("cell_v", torch.tensor(cell_v, dtype=torch.float32))self.scale_u = CELL_PX / width
self.scale_v = CELL_PX / height
def training_outputs(self, x):
f =self.features(x).mean(dim=(2,3))# tanh*0.5 keeps offsets inside the cell, in (-0.5, 0.5) cell units.returnself.cls_head(f), torch.tanh(self.off_head(f))*0.5def forward(self, x):
logits, offset =self.training_outputs(x)
p = F.softmax(logits, dim=1)
conf, idx = p.max(dim=1)
u =self.cell_u.index_select(0, idx)+ offset[:,0]*self.scale_u
v =self.cell_v.index_select(0, idx)+ offset[:,1]*self.scale_v
return torch.stack([u.clamp(0.0,1.0), v.clamp(0.0,1.0), conf], dim=1)def build_model(meta: dict)-> nn.Module:return CellLocNet(meta)def loss_fn(logits: torch.Tensor, offset_pred: torch.Tensor,
target_cell_idx: torch.Tensor, target_offset: torch.Tensor)-> torch.Tensor:"""Cross-entropy on the true map cell + smooth-L1 on the within-cell offset. No confidence loss term: confidence IS the softmax mass on the winning cell, so honest abstention falls out of the parameterization rather than being trained against a proxy target. Label smoothing is light (0.05) so a memorized cell can still reach ~0.95 and clear the scorer's 0.3 threshold. """return(F.cross_entropy(logits, target_cell_idx, label_smoothing=0.05)+1.0* F.smooth_l1_loss(offset_pred, target_offset))def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py124 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Current: map-cell classification. Each EPOCH redraws a fresh random subset ofthe full train lattice with fresh random rotations, so over the run the modelsees epochs*max_crops_per_bucket distinct (position, heading) vantages — thecoverage the C-way cell classifier needs, since one fixed draw of 6,000 cropscannot cover ~3,000 cells.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import CELL_PX, build_model, export_onnx, grid_dims, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import extract_crop, list_crops
def load_scene(area: str, data_dir: Path):"""Meta + the relight image(s). One pass-through bucket on this branch."""
meta = load_meta(area, data_dir)
imgs =[np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{b}.png"))for b in LIGHTING_BUCKETS]
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, imgs, crops
def sample_epoch(meta, imgs, crops, max_crops_per_bucket: int, rng):"""Draw a fresh crop subset with fresh rotations; return (x, cell_idx, off)."""
gw,_= grid_dims(meta)
xs, cells, offs =[],[],[]for img in imgs:
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
cx, cy = c["cx"], c["cy"]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, cx, cy, angle))
cells.append((cy // CELL_PX)* gw +(cx // CELL_PX))
offs.append(((cx % CELL_PX)/ CELL_PX -0.5,(cy % CELL_PX)/ CELL_PX -0.5))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0return(x, torch.tensor(cells, dtype=torch.int64),
torch.tensor(offs, dtype=torch.float32))def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta, imgs, crops = load_scene(area, data_dir)
model = build_model(meta).to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n =0
print(f"[{area}] {len(crops)} lattice positions, {model.n_cells} cells, "
f"device={device}")for epoch in range(epochs):# Fresh vantages every epoch, not one extract-once set reused.
x, cell_idx, off = sample_epoch(meta, imgs, crops, max_crops_per_bucket, rng)
n = len(x)
model.train()
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb = x[idx].to(device)
cb, ob = cell_idx[idx].to(device), off[idx].to(device)
logits, off_pred = model.training_outputs(xb)
loss = loss_fn(logits, off_pred, cb, ob)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"n_cells": model.n_cells,"distinct_vantages_seen": epochs * max_crops_per_bucket,}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
5.1
Baseline seed: current model/ code, no design agent 92d1f12e
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
other
2.001
47 s
—
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
This row is the starting line, not an idea being tested. The naive starting model is trained and measured so there is a real number on the board. It turns out to be the worst possible result -- confidently wrong on every single frame -- which is exactly what the new score is designed to expose.
Hypothesis
Not a hypothesis -- a starting line. Run with SKIP_AGENT=1 so no design or implementation agent is involved: whatever is in model/ is trained and scored as-is to establish the number later experiments must beat, and to prove the harness works end to end on the mission-score metric.
Method
Train the current model/ code (the original from-scratch TinyLocNet) unchanged and score it with the frozen scorer. No code change proposed or applied.
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.49 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: mission score — (1 - usable) + false, same photograph, scoring 2.001. Asked over: viewpoint holdout, daytime only, Berlin only, eval on the training photograph. The metric became the product requirement itself and the approach worked: 0.040, 96.5% usable. But the eval crops came from the very raster the model trained on. On 2026-09-28 the champion was scored on other open photographs of the same ground (Berlin TrueDOP 2022/2023/2024) and on +20 brightness of its own raster: 1.78-1.97 and 1.45. It had memorised one photograph's pixels, not the city. Re-scored here on the held-out photograph like every earlier era.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Mission score · ts 2026-07-31T10:25:28 ·
commit 92d1f12e10c6 · artifacts runs/20260731_102441_experiment1 ·
took 47 s
The code for this experiment — the exact code that trained it
The exact bytes that trained this run, snapshotted before the keep/revert decision could touch them. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
4.4
Re-implementation of lost experiment 2 — classify-then-refine: 32x32 map-cell softmax + within-cell offset replaces direct coordinate regression c0f3cd4e
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
architecture
—
3 m 36 s
—
NO SCORE
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
An earlier experiment taught the model to answer a multiple-choice question — which of 1024 map squares is this photo from? — before pointing at the exact spot inside the winning square. That version genuinely found 8% of places within 100 meters, but our old scorecard was broken: it graded models on a statistic that favored playing it safe near the map's center, so the multiple-choice model was wrongly judged worse and its code was deleted. The scorecard is fixed now, and this experiment simply rebuilds that deleted model from its saved blueprint, so the research can continue from the best design we actually found.
Hypothesis
This is a faithful re-implementation, not a new idea. Experiment 2 replaced MSE coordinate regression with PlaNet-style cell classification plus a within-cell offset, and under the corrected geometric-mean metric it is the best result so far (1323.6 m geomean, 8.0% of held-out viewpoints within 100 m vs 0.0% for the baseline). It was reverted at the time by the old, broken median metric — which rewarded centre-guessing — and the revert destroyed its source; only the design record survives (runs/20260731_094303_experiment2/experiment.json). The original hypothesis stands as validated by that run: a single sigmoid (u,v) head trained with MSE over a multimodal answer space regresses to the map centroid under ambiguity, and reparameterizing the output as discrete cell classification (cross-entropy over a 32x32 grid, ~217 m cells) plus a teacher-forced offset removes that averaging failure mode. Restoring it gives the loop a correct champion to build from.
Method
Identical to experiment 2's registered method. In model/model.py only the head and loss change: keep TinyLocNet's conv trunk (~100k params) verbatim; replace the single Linear(128,3) head with three heads over the same GAP feature — cell logits Linear(128,1024), per-cell offsets Linear(128,2048) tanh-bounded to half a cell, and the same loose-BCE confidence head as the baseline. Inference decodes argmax cell center + gathered offset inside the exported ONNX graph, so the frozen [[u,v,conf]] contract is untouched. Loss becomes cross-entropy on the true cell + MSE on the true cell's offset (teacher-forced) + the baseline's 0.1-weighted confidence BCE. model/train.py changes one line (call the new raw-output training path). Grid is defined in normalized [0,1] map coordinates, so nothing is Berlin-specific.
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case geometric-mean error (m), scoring 1.32 km. Asked over: viewpoint holdout, daytime only, Berlin only. The evaluation was fixed here: held-out viewpoints over mapped ground instead of held-out regions. The metric was still an error statistic. Run artifacts were not kept, so these four could only ever be placed on a ruler by arithmetic from their logged same-photograph rates — which no longer answers the question the current ruler asks (an unseen photograph). Incomparable, not lost.
era Viewpoint holdout · ts 2026-07-31T10:12:13 ·
commit c0f3cd4e602d · artifacts runs/20260731_100837_experiment4 ·
took 3 m 36 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py132 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Classify-then-refine: the same tiny conv trunk, but the output isreparameterized as a softmax over a GRID x GRID lattice of map cells plus awithin-cell offset, instead of a direct (u, v) regression. Direct MSEregression over a multimodal answer space collapses to the map centroid underambiguity; discrete cell classification does not average competing modes.From-scratch init."""import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
# Cells per axis of the map-cell classification grid, in NORMALIZED [0, 1]# map coordinates — no area-specific constants (CLAUDE.md §0).
GRID =32class TinyLocNet(nn.Module):"""~0.5M-param CNN: strided conv stack -> GAP -> (cell logits, offsets, conf). forward_train() returns the raw head outputs for loss_fn(); forward() is the exported graph and decodes them to the frozen [u, v, conf] contract. """def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.cell_logits = nn.Linear(chans[-1], GRID * GRID)self.cell_offset = nn.Linear(chans[-1], GRID * GRID *2)self.conf_head = nn.Linear(chans[-1],1)def _embed(self, x):returnself.features(x).mean(dim=(2,3))def forward_train(self, x):"""Raw heads: (logits [B,G*G], offsets [B,G*G,2], conf_logit [B,1])."""
f =self._embed(x)
logits =self.cell_logits(f)# Each cell's offset is bounded to half a cell in normalized units.
offsets = torch.tanh(self.cell_offset(f)).view(-1, GRID * GRID,2)*(0.5/ GRID)
conf_logit =self.conf_head(f)return logits, offsets, conf_logit
def forward(self, x):
logits, offsets, conf_logit =self.forward_train(x)
idx = torch.argmax(logits, dim=1)
iy = idx // GRID
ix = idx - iy * GRID # subtraction, not %, for safe ONNX tracing
cu =(ix.float()+0.5)/ GRID
cv =(iy.float()+0.5)/ GRID
off = torch.gather(offsets,1, idx.view(-1,1,1).expand(-1,1,2)).squeeze(1)
u =(cu + off[:,0]).clamp(0,1)
v =(cv + off[:,1]).clamp(0,1)
conf = torch.sigmoid(conf_logit)[:,0]return torch.stack([u, v, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(raw, target_uv: torch.Tensor)-> torch.Tensor:"""Cell cross-entropy + teacher-forced offset MSE + conf BCE. `raw` is forward_train()'s (logits, offsets, conf_logit) tuple. Cell ids follow iy * GRID + ix, with ix indexing the u axis and iy the v axis. """
logits, offsets, conf_logit = raw
tx = target_uv[:,0].mul(GRID).floor().long().clamp(0, GRID -1)
ty = target_uv[:,1].mul(GRID).floor().long().clamp(0, GRID -1)
cell = ty * GRID + tx
ce = F.cross_entropy(logits, cell)# Teacher-forced: only the true cell's offset is supervised.
pred_off = torch.gather(offsets,1, cell.view(-1,1,1).expand(-1,1,2)).squeeze(1)
targ_off = target_uv - torch.stack([(tx.float()+0.5)/ GRID,(ty.float()+0.5)/ GRID], dim=1)
off_loss =(((pred_off - targ_off)* GRID)**2).sum(dim=1).mean()with torch.no_grad():# Conf target is deliberately loose (abstain only on catastrophic# misses > half the map extent) so the model stays scoreable instead# of abstaining its way into the §6 coverage FAIL; calibrating# confidence properly is an obvious loop research target.
idx = torch.argmax(logits, dim=1)
iy = idx // GRID
ix = idx - iy * GRID
dec_off = torch.gather(offsets,1, idx.view(-1,1,1).expand(-1,1,2)).squeeze(1)
dec_u =((ix.float()+0.5)/ GRID + dec_off[:,0]).clamp(0,1)
dec_v =((iy.float()+0.5)/ GRID + dec_off[:,1]).clamp(0,1)
coord_err =(torch.stack([dec_u, dec_v], dim=1)- target_uv).pow(2).sum(dim=1).sqrt()
good =(coord_err <0.5).float()
conf_bce = F.binary_cross_entropy(
torch.sigmoid(conf_logit)[:,0].clamp(1e-6,1-1e-6), good)return ce + off_loss +0.1* conf_bce
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model.forward_train(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
4.3
Coverage over repetition: spend the same 48k-step budget on ~48k fresh-rotated distinct vantages instead of 6000 static crops replayed 8x f74a8666
The loop discarded this — no improvement under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
training
—
6 m 36 s
—
NO SCORE
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
This model is supposed to memorize what every part of Berlin looks like from above, like a taxi driver memorizing a city. But it turns out we were only ever showing it 8% of the flashcards — the same 6,000 photos over and over, always held at the same angle — and then quizzing it on the whole city. We didn't give it more study time; we made every flashcard in the same study session a new place, held at a new angle. Same effort, spent on seeing the whole city once instead of a small corner eight times.
Hypothesis
The metric is limited by training coverage, not architecture. The baseline's 1993.71 m is ~29% of Berlin's map extent (regression-to-the-mean), and experiment 2's head reparameterization changed nothing (2136.91 m, reverted) — its own pre-registered refutation signature says the trunk's features can't separate locations. But train.py shows why: training samples 6000 of ~78,000 lattice positions (~8%) ONCE, freezes one rotation per crop, and replays those 6000 static images for 8 epochs (29 s total). The frozen v2 split guarantees every eval viewpoint is 11-17 m from a lattice framing, yet the 6000-crop subsample silently re-creates the v1 pathology inside the training procedure: the nearest actually-trained vantage averages ~44 m from an eval viewpoint (Poisson nearest-neighbor at 6000 points over 47 km^2), with a mismatched frozen heading, and 92% of vantages are never shown to a model whose entire premise is memorizing its box. A memorization model cannot memorize a map it was never shown. Streaming the full lattice with fresh per-visit rotations at the SAME step count isolates data coverage/freshness as the single variable: any gain is attributable to the data diet, not extra compute.
Method
Rewrite model/train.py's data procedure only: replace load-once-static-tensor training (load_training_tensors -> one fixed 6000-crop tensor reused every epoch) with epoch-wise streaming over a global shuffled permutation of the FULL train lattice (~78k positions from pipeline.dataset.list_crops), consuming max_crops_per_bucket x n_buckets positions per epoch (6000/epoch at harness defaults, reshuffling when the permutation is exhausted), extracting each 128x128 crop on the fly per batch with a freshly drawn uniform(0,360) rotation at every visit. Architecture (model/model.py), loss, optimizer, batch size, and total gradient-step count are all unchanged — with harness defaults (EPOCHS=8, TRAIN_CROPS=6000) the model sees 48,000 presentations either way; this experiment changes only WHICH images those presentations are: ~48k distinct vantages (~62% of the lattice, mean eval-to-nearest-trained-vantage distance ~16 m) instead of 6000 vantages repeated 8x (~44 m).
Conclusion at the time
REVERTED under the corrected metric. It was KEPT at the time because the old median metric rewarded it for being a marginally better centre-guesser, despite locating almost nothing (1 good hit in ~500 vs experiment 2's 40).
Not on today's ruler
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case geometric-mean error (m), scoring 1.67 km. Asked over: viewpoint holdout, daytime only, Berlin only. The evaluation was fixed here: held-out viewpoints over mapped ground instead of held-out regions. The metric was still an error statistic. Run artifacts were not kept, so these four could only ever be placed on a ruler by arithmetic from their logged same-photograph rates — which no longer answers the question the current ruler asks (an unseen photograph). Incomparable, not lost.
era Viewpoint holdout · ts 2026-07-31T09:56:08 ·
commit f74a866699a9 · artifacts runs/20260731_094932_experiment3 ·
took 6 m 36 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
architecture
—
6 m 20 s
—
NO SCORE
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The old model had to blurt out exact GPS coordinates in one shot, like being asked to point at a city map blindfolded — and when unsure, the math of its training pushes it to hedge toward the middle of the map, which is precisely wrong everywhere. The new model answers a multiple-choice question first: the map is divided into a 32-by-32 checkerboard of roughly 200-meter squares, and it picks which square the photo is from. Then a second small step points to the exact spot inside that square. Multiple choice can't hedge — you can't answer 'somewhere between Tegel and Tempelhof' by picking a spot in the middle — so being unsure no longer drags every guess toward the map's center.
Hypothesis
The baseline's 1993.71 m worst-case median is ~29% of Berlin's 6.9 km map extent — the signature of MSE regression-to-the-mean, not of weak features. A single sigmoid (u,v) head trained with MSE over a large multimodal answer space is pulled toward the map centroid whenever the features are ambiguous, so even correctly recognized locations get dragged inward. Reparameterizing the output as discrete spatial cell classification (cross-entropy over a 32x32 grid, ~217 m cells) plus a within-cell offset regressor removes the averaging failure mode entirely: cross-entropy places probability mass on the right cell without interpolating between distant hypotheses (PlaNet-style geo-cell classification; CenterNet-style heatmap+offset decoding is the same idea for keypoints). The trunk, data, and training budget stay identical, isolating the parameterization as the variable.
Method
In model/model.py only the head and loss change: keep TinyLocNet's conv trunk (~100k params) verbatim; replace the single Linear(128,3) head with three heads over the same GAP feature — cell logits Linear(128,1024), per-cell offsets Linear(128,2048) tanh-bounded to half a cell, and the same loose-BCE confidence head as the baseline. Inference decodes argmax cell center + gathered offset inside the exported ONNX graph, so the frozen [[u,v,conf]] contract is untouched. Loss becomes cross-entropy on the true cell + MSE on the true cell's offset (teacher-forced) + the baseline's 0.1-weighted confidence BCE. model/train.py changes one line (call the new raw-output training path). Grid is defined in normalized [0,1] map coordinates, so nothing is Berlin-specific.
Conclusion at the time
KEPT under the corrected metric — but scored and REVERTED at the time by the old median metric, which destroyed its source. Only its design survives (see runs/20260731_094303_experiment2/experiment.json); a later experiment re-implements it.
Not on today's ruler
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case geometric-mean error (m), scoring 1.32 km. Asked over: viewpoint holdout, daytime only, Berlin only. The evaluation was fixed here: held-out viewpoints over mapped ground instead of held-out regions. The metric was still an error statistic. Run artifacts were not kept, so these four could only ever be placed on a ruler by arithmetic from their logged same-photograph rates — which no longer answers the question the current ruler asks (an unseen photograph). Incomparable, not lost.
era Viewpoint holdout · ts 2026-07-31T09:49:23 ·
commit 4affa746e608 · artifacts runs/20260731_094303_experiment2 ·
took 6 m 20 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
4.1
Baseline seed on the corrected viewpoint-holdout split 8bdcc185
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
other
—
44 s
—
NO SCORE
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
We found that the exam had been unfair in a way nobody noticed: the model was studying one set of streets and then being tested exclusively on different streets it had never been allowed to see. Now it studies the whole city and gets tested on the same city photographed from angles and positions it never studied from -- which is exactly what a UAV flying overhead would actually do. This row is the naive starting model re-measured on that fair exam.
Hypothesis
Not a hypothesis -- a starting line. The previous split held out whole REGIONS of Berlin, so 100% of eval questions were centred on ground the model had never been shown and 65% of eval frames contained no familiar pixel at all. Every score before this one was measured against an unanswerable question and cannot be compared to anything measured now.
Method
Rebuild the split to hold out VIEWPOINTS instead of regions: training covers every lattice position of the whole city; eval frames sit 11-17 m off the nearest training vantage at their own rotation. Then re-run the original from-scratch TinyLocNet baseline with no design agent (SKIP_AGENT=1) to establish an honest number on the new ruler.
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case geometric-mean error (m), scoring 1.78 km. Asked over: viewpoint holdout, daytime only, Berlin only. The evaluation was fixed here: held-out viewpoints over mapped ground instead of held-out regions. The metric was still an error statistic. Run artifacts were not kept, so these four could only ever be placed on a ruler by arithmetic from their logged same-photograph rates — which no longer answers the question the current ruler asks (an unseen photograph). Incomparable, not lost.
era Viewpoint holdout · ts 2026-07-31T09:42:22 ·
commit 8bdcc18531c8 · artifacts runs/20260731_094138_experiment1 ·
took 44 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
3.5
Per-epoch position resampling: expose all ~45k Berlin train vantages instead of a frozen 6k subset 0ede8d45
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
training
—
16 m 23 s
—
NO SCORE
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model has been studying the same 6,000 flashcards over and over — 96 study sessions with the exact same deck — when the full deck of Berlin views actually has 45,000 cards. We now deal a fresh random hand of 6,000 cards before every study session. Same total study time, same brain, but by the end it has seen essentially every card in the deck a few times instead of 13% of them dozens of times. Seeing far more of Berlin should make it much better at telling apart neighborhoods that look confusingly similar.
Hypothesis
The champion's 810 m is limited by training-set exposure, not by its (validated) grid-classification architecture. train.py's load_training_plan picks 6,000 crop positions ONCE and reuses them for all 96 epochs — only the rotation is refreshed. The frozen split (pipeline/dataset.py) documents ~45k available train positions for a ~7 km area, so the model literally never sees ~87% of its own training territory: of the grid cells that contain at least one train position, a fixed 6k draw leaves hundreds with zero positives for the entire run, and the cells it does cover average only ~2 fixed vantage points memorized 96 times over. That is exactly the label starvation experiment 4 diagnosed — but exp 4 attacked it by reparameterizing the decode head (coarse cells + offsets), which was refuted at 920 m. This experiment attacks the same bottleneck directly in the training procedure, with the architecture untouched: redraw the 6,000 positions at random from the full ~45k train list before every epoch. At unchanged per-epoch cost (extraction time scales with count, not novelty; ~3.3 s/epoch measured), 96 epochs then cover essentially every trainable position (P(a position is never drawn) ≈ 0.867^96 ≈ 1e-6), turning the long budget into dataset-scale coverage instead of repetition — every populated cell gets positives, and lookalike cells get far more distinct negatives to discriminate against. (Note: this is the third attempt at iteration 5 — the same design was pre-registered twice before but never reached a score; both prior attempts died to harness interruptions, not to any result. It is re-registered here after independently re-verifying its claims against the current champion code.)
Method
model/train.py only: move training-plan sampling inside the epoch loop so each epoch draws a fresh random 6,000 positions (with fresh rotations, as now) from the full train-split crop list, instead of freezing one 6,000-position plan for the whole run. model/model.py untouched — identical architecture, loss, and ONNX export.
Its run directory was deleted and its logged record does not carry enough to reconstruct the rates. This one is simply lost.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 100 m, scoring 760.6 m. Asked over: region holdout, daytime only, Berlin only. Scope cut to one city and one lighting condition for iteration speed. Same broken region-holdout eval.
era Berlin only · ts 2026-07-31T09:19:51 ·
commit 0ede8d452bd2 · artifacts runs/20260731_090328_experiment5 ·
took 16 m 23 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py123 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: the map is a GRID x GRID checkerboard and the trunk classifies whichcell the frame came from. Coordinates are a soft-argmax over the posterior;confidence is the mass in the best CONF_POOL x CONF_POOL neighborhood."""import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
GRID =64# map is diced into GRID x GRID cells
LABEL_SIGMA =1.0# Gaussian soft-label width, in cells
CONF_POOL =5# confidence = posterior mass in the best 5x5 neighborhooddef _cell_centers(device=None):"""Normalized (u, v) centers of the GRID*GRID cells, row-major."""
k = torch.arange(GRID * GRID, device=device)
cell_u =((k % GRID).float()+0.5)/ GRID
cell_v =((k // GRID).float()+0.5)/ GRID
return cell_u, cell_v
class TinyLocNet(nn.Module):"""~630k-param CNN: strided conv stack -> GAP -> GRID^2 cell logits."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1], GRID * GRID)
cell_u, cell_v = _cell_centers()self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward_logits(self, x):"""Raw per-cell logits, (B, GRID*GRID). The training-time graph."""
f =self.features(x).mean(dim=(2,3))returnself.head(f)def forward(self, x):
logits =self.forward_logits(x)
p = torch.softmax(logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)# Mass in the best CONF_POOL-wide neighborhood: a peaked posterior is# confident, a diffuse one abstains.
pm = p.reshape(-1,1, GRID, GRID)
neigh = F.avg_pool2d(pm, CONF_POOL, stride=1,
padding=CONF_POOL //2)*(CONF_POOL **2)
conf = neigh.amax(dim=(1,2,3)).unsqueeze(1).clamp(0.0,1.0)return torch.cat([u, v, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()
_CELL_CACHE ={}def _cached_cell_centers(device):
key = str(device)if key notin _CELL_CACHE:
_CELL_CACHE[key]= _cell_centers(device)return _CELL_CACHE[key]def loss_fn(logits: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""Gaussian-soft-label cross-entropy over cells + soft-argmax aux MSE. logits: (B, GRID*GRID) from TinyLocNet.forward_logits; target_uv: (B, 2). """
cell_u, cell_v = _cached_cell_centers(logits.device)
gu = target_uv[:,0]* GRID -0.5
gv = target_uv[:,1]* GRID -0.5with torch.no_grad():
axis = torch.arange(GRID, device=logits.device, dtype=logits.dtype)# (B, GRID, GRID): v/rows on dim 1, u/cols on dim 2 — same row-major# layout as forward()'s reshape.
d2 =((axis - gu[:,None,None])**2+(axis[:,None]- gv[:,None,None])**2)
q = torch.softmax(-d2.flatten(1)/(2* LABEL_SIGMA **2), dim=1)
ce =-(q * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
p = torch.softmax(logits, dim=1)
uv_hat = torch.stack([(p * cell_u).sum(dim=1),(p * cell_v).sum(dim=1)], dim=1)
aux =((uv_hat - target_uv)**2).sum(dim=1).mean()return ce +10.0* aux
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py175 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Train TinyLocNet to convergence on train-split crops from every relight bucket:crop SELECTION is re-drawn at random from the full train list before everyepoch, and crop EXTRACTION is re-run every epoch with fresh random rotations,so a long budget buys dataset-scale coverage instead of memorizing one frozensubset of vantage points.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
# The harness passes --epochs 8 (loop.sh EPOCHS, sized for the harness-proving# baseline); 12x gives the 96 effective epochs this design needs to converge.
EPOCH_MULT =12
ROT_POOL =8# fallback: pre-rotated variants per crop
EXTRACT_BUDGET_S =15.0# per-epoch extraction cost above which we fall backdef load_area_assets(area: str, data_dir: Path):"""Load the per-bucket relight images and the FULL train-split crop list once. No sampling happens here — which positions get trained on is decided fresh every epoch by sample_epoch_plan. """
meta = load_meta(area, data_dir)
buckets =[(bucket,
np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png")))for bucket in LIGHTING_BUCKETS]
crops = list_crops(area, meta["width"], meta["height"],"train")return meta, buckets, crops
def sample_epoch_plan(buckets, crops, meta, max_crops_per_bucket, rng):"""Draw this epoch's crop positions at random from the full train list. Targets are rotation-invariant (extract_crop rotates about the crop center), so y depends only on the drawn positions, not on the heading. """
plan, ys =[],[]for _bucket, img in buckets:
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
plan.append((img, c["cx"], c["cy"]))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
y = torch.tensor(ys, dtype=torch.float32)return plan, y
def _to_tensor(xs)-> torch.Tensor:return torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0def epoch_tensor(plan, rng)-> torch.Tensor:"""This epoch's crops, each at a fresh random heading."""return _to_tensor([extract_crop(img, cx, cy, float(rng.uniform(0,360)))for img, cx, cy in plan])def build_rot_pool(plan, rng)-> list:"""Fallback when per-epoch extraction is too slow: ROT_POOL rotated uint8 variants per crop, sampled from thereafter."""return[np.stack([extract_crop(img, cx, cy, float(rng.uniform(0,360)))for_in range(ROT_POOL)])for img, cx, cy in plan]def epoch_tensor_from_pool(pool, rng)-> torch.Tensor:return _to_tensor([variants[rng.integers(ROT_POOL)]for variants in pool])def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
total_epochs = epochs * EPOCH_MULT
meta, buckets, crops = load_area_assets(area, data_dir)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
scheduler = torch.optim.lr_scheduler.CosineAnnealingLR(
opt, T_max=total_epochs, eta_min=1e-5)
n = len(buckets)* min(max_crops_per_bucket, len(crops))
print(f"[{area}] {n} crops/epoch drawn from {len(crops)} train positions, "
f"device={device}, epochs={total_epochs}")
pool, plan, y =None,None,Nonefor epoch in range(total_epochs):if pool isNone:# Fresh draw of positions every epoch: over the full budget the model# sees essentially the whole train split, not one frozen subset.
plan, y = sample_epoch_plan(buckets, crops, meta,
max_crops_per_bucket, rng)
te = time.time()
x = epoch_tensor_from_pool(pool, rng)if pool isnotNone \
else epoch_tensor(plan, rng)
extract_s = time.time()- te
n = len(plan)
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model.forward_logits(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
scheduler.step()
print(f"[{area}] epoch {epoch +1}/{total_epochs} "
f"loss={np.mean(losses):.4f} extract={extract_s:.1f}s")if pool isNoneand extract_s > EXTRACT_BUDGET_S:# Too slow to re-extract every epoch: freeze this epoch's positions# and amortize into a sampled rotation pool rather than dropping# fresh rotations altogether. No further position resampling.
print(f"[{area}] extraction {extract_s:.1f}s > {EXTRACT_BUDGET_S}s, "
f"freezing positions and switching to a {ROT_POOL}-variant "
f"rotation pool")
pool = build_rot_pool(plan, rng)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": total_epochs,"harness_epochs": epochs,"epoch_mult": EPOCH_MULT,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment"position_sampling":"per-epoch","distinct_positions_available": len(crops),}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
3.4
Hierarchical decode: 16x16 coarse-cell classification + per-cell continuous offset regression from a layout-preserving descriptor f625d8d7
The loop discarded this — no improvement under the metric then in force.
architecture
1.988
17 m 29 s
$3.59
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The old model had to answer 'which of 4096 tiny map squares is this photo from?' -- but the exam is deliberately held on patches of Berlin the model never studied, and with 4096 choices it had only ever seen one or two examples of each. Worse, squares inside the exam patches never appeared in study material at all, so the model literally learned to never answer them. The new model first picks one of 256 much bigger neighborhoods -- big enough that every one was at least partly studied -- and then points to a spot inside it, the way you'd say 'that's Kreuzberg, near the top-left corner of the park'. Pointing is a smooth skill that transfers into the unstudied patches, where memorizing tiny squares could not.
Hypothesis
Exp 3's remaining 810 m has two structural causes baked into the flat 64x64 (108 m/cell) classification head, both fixed by the same reparameterization. (1) Never-trained-cell suppression: the frozen split holds out 360 px (360 m) eval blocks that training windows may never touch, so every cell lying inside an eval block appears ONLY as a softmax negative across all 96 epochs -- the converged model systematically pushes probability mass AWAY from exactly the cells where every eval crop lives, forcing predictions onto the ring of trained cells around each block (a >=1-2 cell, 110-250 m structural floor) and, worse, letting mass scatter to lookalike trained cells elsewhere. (2) Label starvation: 6000 training crops over 4096 cells is ~1.8 positives per cell, far too sparse to learn a 4096-way discrimination. Reparameterizing to a 16x16 coarse grid (434 m cells) + continuous within-cell offset removes both at once: eval blocks are isolated on the split's diagonal lattice (no two adjacent), so every 434 m coarse cell is guaranteed to contain trained territory (no suppressed classes), each coarse class gets ~23 positives instead of ~1.8, and the offset regressor is a continuous function that can interpolate into the unseen eval-block interior of a cell it recognizes -- discrete classes cannot interpolate, regression can. The offset needs to know WHERE in the cell the crop sits, which a global-average-pooled texture bag cannot express, so the descriptor keeps a coarse 4x4 spatial layout instead of averaging it away; this descriptor change is load-bearing for the offset head, not a separate idea.
Method
In model/model.py only: replace the flat GRID=64 head with (a) a descriptor that preserves layout -- 1x1 conv 128->32 on the 8x8 feature map, 2x2 avg-pool to 4x4x32, flatten to 512 -- (b) a 256-way coarse-cell head (16x16 grid, ~434 m cells) and (c) a per-cell offset head (512->512, i.e. (du,dv) per cell, tanh-bounded to +/-0.75 cell). Output uv = posterior-weighted sum over cells of (cell center + offset); conf = max posterior mass in any 2x2 cell neighborhood. Loss = soft-label CE over the 16x16 grid (sigma 0.5 cells) + true-cell offset MSE + composed-uv MSE. model/train.py is untouched (forward_logits/loss_fn interface preserved as a tuple).
Conclusion at the time
REVERTED — metric did not improve (920.52 m vs best 810.02 m); change discarded
Re-measured on today's ruler
Mission score 1.988 — 0.2% of held-out frames give a usable fix, 99.0% are confident and wrong, 0.8% abstain. Median miss 3.63 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.80
implementation agent
$0.79
total
$3.59
by model — claude-fable-5 $2.80 · claude-opus-5 $0.79 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 100 m, scoring 920.5 m. Asked over: region holdout, daytime only, Berlin only. Scope cut to one city and one lighting condition for iteration speed. Same broken region-holdout eval.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9880% usablecov 0.99
era Berlin only · ts 2026-07-31T08:56:20 ·
commit f625d8d7df16 · artifacts runs/20260731_083851_experiment4 ·
took 17 m 29 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
3.3
Re-land the validated 64x64 grid-classification head with a convergence-scale training budget (x12 epochs, cosine LR, fresh per-epoch rotations) bea8a408
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.953 — worse than silence.
training
1.953
17 m 28 s
$3.70
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The last experiment changed the model's job from 'blurt out GPS numbers' to 'point at the right square on a 64x64 checkerboard of Berlin' - and it genuinely got 3.6x more accurate. But it was disqualified by a fairness rule: it was only sure enough to give an answer on 1 in 10 photos, and the rules demand an answer on at least 1 in 5. The catch: it had only been allowed to study for 33 seconds. This experiment brings the same model back and lets it actually study - about 100 passes through the material instead of 8, with every aerial photo shown at a fresh random rotation each pass so it learns places rather than memorizing exact pictures. A model that has properly studied is both more accurate and more confident, which should clear the 'too unsure to answer' disqualification.
Hypothesis
Experiment 2's grid-classification architecture was validated, not refuted: on the frames it answered, median error was 743 m vs the kept baseline's 2674.93 m (3.6x better), and it passed both deployment gates (2.5 MiB, 0.63 ms). It failed only the frozen coverage gate (10.75% < 20%). That coverage failure is a symptom of undertraining, not a broken confidence design: its confidence IS posterior mass in a 5x5-cell neighborhood, and after only 8 epochs (33 s wall) the train loss sat at 6.87 nats against a ~3.1-nat soft-label entropy floor - i.e. the posterior was ~3.8 nats (~45x in probability-mass terms) more diffuse than a converged one, so almost no eval frame could concentrate 0.3 mass anywhere. The 8-epoch budget was sized for the harness-proving baseline (loop.sh EPOCHS=8), and loop.sh's own comments document the accepted pattern of train.py applying an internal epoch multiplier. Additionally, the baseline trainer freezes ONE random rotation per crop for the whole run, which at 96 epochs would mean memorizing 6000 fixed images; eval crops carry random headings, so fresh per-epoch rotations are required for the longer budget to convert into generalization (eval blocks are never seen in training - the split is genuinely held-out territory). Prediction: a converged posterior is simultaneously sharper (higher coverage) and more accurate (lower median), fixing the gate failure and the metric with one cause.
Method
Two files, one focused change: restore experiment 2's model.py exactly as pre-registered there (64x64 grid logits head, Gaussian-soft-label cross-entropy + soft-argmax aux loss, in-graph soft-argmax coordinate readout, confidence = max 5x5-neighborhood posterior mass - all byte-equivalent to exp 2's brief, deliberately including the unchanged confidence definition as the experimental control), and scale training in train.py: internal EPOCH_MULT=12 (harness's --epochs 8 -> 96 effective epochs), CosineAnnealingLR from 1e-3 to 1e-5 over the full run, and re-extraction of all training crops with fresh random rotation angles at the start of every epoch instead of one frozen rotation at load time. Trunk, data selection, batch size, optimizer family, CLI, and ONNX contract untouched.
Mission score 1.953 — 0.0% of held-out frames give a usable fix, 95.2% are confident and wrong, 4.8% abstain. Median miss 3.39 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.70
implementation agent
$1.00
total
$3.70
by model — claude-fable-5 $2.70 · claude-opus-5 $1.00 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 100 m, scoring 810.0 m. Asked over: region holdout, daytime only, Berlin only. Scope cut to one city and one lighting condition for iteration speed. Same broken region-holdout eval.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9530% usablecov 0.95
era Berlin only · ts 2026-07-31T08:38:41 ·
commit bea8a4083210 · artifacts runs/20260731_082113_experiment3 ·
took 17 m 28 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py123 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current: the map is a GRID x GRID checkerboard and the trunk classifies whichcell the frame came from. Coordinates are a soft-argmax over the posterior;confidence is the mass in the best CONF_POOL x CONF_POOL neighborhood."""import numpy as np
import torch
import torch.nn as nn
import torch.nn.functional as F
GRID =64# map is diced into GRID x GRID cells
LABEL_SIGMA =1.0# Gaussian soft-label width, in cells
CONF_POOL =5# confidence = posterior mass in the best 5x5 neighborhooddef _cell_centers(device=None):"""Normalized (u, v) centers of the GRID*GRID cells, row-major."""
k = torch.arange(GRID * GRID, device=device)
cell_u =((k % GRID).float()+0.5)/ GRID
cell_v =((k // GRID).float()+0.5)/ GRID
return cell_u, cell_v
class TinyLocNet(nn.Module):"""~630k-param CNN: strided conv stack -> GAP -> GRID^2 cell logits."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1], GRID * GRID)
cell_u, cell_v = _cell_centers()self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward_logits(self, x):"""Raw per-cell logits, (B, GRID*GRID). The training-time graph."""
f =self.features(x).mean(dim=(2,3))returnself.head(f)def forward(self, x):
logits =self.forward_logits(x)
p = torch.softmax(logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)# Mass in the best CONF_POOL-wide neighborhood: a peaked posterior is# confident, a diffuse one abstains.
pm = p.reshape(-1,1, GRID, GRID)
neigh = F.avg_pool2d(pm, CONF_POOL, stride=1,
padding=CONF_POOL //2)*(CONF_POOL **2)
conf = neigh.amax(dim=(1,2,3)).unsqueeze(1).clamp(0.0,1.0)return torch.cat([u, v, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()
_CELL_CACHE ={}def _cached_cell_centers(device):
key = str(device)if key notin _CELL_CACHE:
_CELL_CACHE[key]= _cell_centers(device)return _CELL_CACHE[key]def loss_fn(logits: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""Gaussian-soft-label cross-entropy over cells + soft-argmax aux MSE. logits: (B, GRID*GRID) from TinyLocNet.forward_logits; target_uv: (B, 2). """
cell_u, cell_v = _cached_cell_centers(logits.device)
gu = target_uv[:,0]* GRID -0.5
gv = target_uv[:,1]* GRID -0.5with torch.no_grad():
axis = torch.arange(GRID, device=logits.device, dtype=logits.dtype)# (B, GRID, GRID): v/rows on dim 1, u/cols on dim 2 — same row-major# layout as forward()'s reshape.
d2 =((axis - gu[:,None,None])**2+(axis[:,None]- gv[:,None,None])**2)
q = torch.softmax(-d2.flatten(1)/(2* LABEL_SIGMA **2), dim=1)
ce =-(q * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
p = torch.softmax(logits, dim=1)
uv_hat = torch.stack([(p * cell_u).sum(dim=1),(p * cell_v).sum(dim=1)], dim=1)
aux =((uv_hat - target_uv)**2).sum(dim=1).mean()return ce +10.0* aux
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py149 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Sample train-split crops from every relight bucket, then train TinyLocNet toconvergence: crop SELECTION is fixed once, but crop EXTRACTION is re-run everyepoch with fresh random rotations so a long budget buys generalization insteadof memorizing one frozen view per crop.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
# The harness passes --epochs 8 (loop.sh EPOCHS, sized for the harness-proving# baseline); 12x gives the 96 effective epochs this design needs to converge.
EPOCH_MULT =12
ROT_POOL =8# fallback: pre-rotated variants per crop
EXTRACT_BUDGET_S =15.0# per-epoch extraction cost above which we fall backdef load_training_plan(area: str, data_dir: Path, max_crops_per_bucket: int, rng):"""Pick the training crops once. Targets are rotation-invariant (extract_crop rotates about the crop center), so only x has to be rebuilt per epoch."""
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
plan, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
plan.append((img, c["cx"], c["cy"]))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
y = torch.tensor(ys, dtype=torch.float32)return plan, y
def _to_tensor(xs)-> torch.Tensor:return torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0def epoch_tensor(plan, rng)-> torch.Tensor:"""This epoch's crops, each at a fresh random heading."""return _to_tensor([extract_crop(img, cx, cy, float(rng.uniform(0,360)))for img, cx, cy in plan])def build_rot_pool(plan, rng)-> list:"""Fallback when per-epoch extraction is too slow: ROT_POOL rotated uint8 variants per crop, sampled from thereafter."""return[np.stack([extract_crop(img, cx, cy, float(rng.uniform(0,360)))for_in range(ROT_POOL)])for img, cx, cy in plan]def epoch_tensor_from_pool(pool, rng)-> torch.Tensor:return _to_tensor([variants[rng.integers(ROT_POOL)]for variants in pool])def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
total_epochs = epochs * EPOCH_MULT
plan, y = load_training_plan(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
scheduler = torch.optim.lr_scheduler.CosineAnnealingLR(
opt, T_max=total_epochs, eta_min=1e-5)
n = len(plan)
print(f"[{area}] {n} crops, device={device}, epochs={total_epochs}")
pool =Nonefor epoch in range(total_epochs):
te = time.time()
x = epoch_tensor_from_pool(pool, rng)if pool isnotNone \
else epoch_tensor(plan, rng)
extract_s = time.time()- te
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model.forward_logits(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
scheduler.step()
print(f"[{area}] epoch {epoch +1}/{total_epochs} "
f"loss={np.mean(losses):.4f} extract={extract_s:.1f}s")if pool isNoneand extract_s > EXTRACT_BUDGET_S:# Too slow to re-rotate every epoch: amortize into a sampled pool# rather than dropping fresh rotations altogether.
print(f"[{area}] extraction {extract_s:.1f}s > {EXTRACT_BUDGET_S}s, "
f"switching to a {ROT_POOL}-variant rotation pool")
pool = build_rot_pool(plan, rng)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": total_epochs,"harness_epochs": epochs,"epoch_mult": EPOCH_MULT,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
3.2
Reparameterize localization as 64x64 map-grid classification with in-graph soft-argmax d9805aa2
The loop discarded this — no improvement under the metric then in force.
architecture
1.483
6 m 37 s
$3.15
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The old model had to blurt out map coordinates directly, like guessing GPS numbers. When a model like that is unsure, naming the middle of the map minimizes its average penalty - so it learned exactly that and nothing else (its error matches a dead-center guess almost to the meter). The new model instead treats Berlin as a 64x64 checkerboard and answers a multiple-choice question: 'which square am I looking over?' - then fine-tunes the answer by averaging the best-scoring neighboring squares. Multiple choice gives no credit for hedging toward the middle, so the model is forced to actually recognize places, and its confidence becomes honest: it is literally how much probability it puts on one small neighborhood of the map.
Hypothesis
The baseline's 2674.93 m is centroid collapse, not weak features: mean distance from the center of the ~6.9 km Berlin raster to a uniform point is ~0.38 x 6900 = ~2640 m, matching the score almost exactly. Direct (u,v) MSE regression makes 'predict the map center' the loss-minimizing answer for an uncertain model, and gradient descent finds that basin first and stays there. Reformulating the output as classification over spatial cells removes that basin entirely - the map center is just one class among 4096 with no special status - and turns the task into recognition ('which cell does this crop look like?'), which CNNs learn far more readily than metric regression. This is the classification-over-cells trick from geo-localization prior art (PlaNet et al.) applied at single-city scale.
Method
Replace TinyLocNet's 3-unit regression head with a linear head producing 64x64=4096 logits over a grid of map cells (~108 m/cell on the 6939x6828 px raster). Training: cross-entropy against Gaussian-smoothed soft cell labels (sigma = 1 cell) plus a small auxiliary L2 on the soft-argmax coordinate. Inference (all inside the ONNX graph): softmax posterior -> expected (u,v) via posterior-weighted average of cell centers (soft-argmax), confidence = maximum probability mass in any 5x5-cell neighborhood (avg_pool2d * 25, then spatial max) - i.e. P(true location within ~+/-270 m of the peak), which is semantically meaningful and comfortably clears the frozen scorer's CONF_THRESHOLD=0.3 when the posterior is peaked while staying low when it is diffuse. The separate BCE-trained confidence head is deleted; trunk, data loading, augmentation, optimizer, epochs, and CLI are untouched.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 2674.93 m); change discarded
Re-measured on today's ruler
Mission score 1.483 — 0.0% of held-out frames give a usable fix, 48.2% are confident and wrong, 51.7% abstain. Median miss 2.69 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.17
implementation agent
$0.98
total
$3.15
by model — claude-fable-5 $2.17 · claude-opus-5 $0.98 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 100 m, scoring —. Asked over: region holdout, daytime only, Berlin only. Scope cut to one city and one lighting condition for iteration speed. Same broken region-holdout eval.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.4830% usablecov 0.48
era Berlin only · ts 2026-07-31T08:21:04 ·
commit d9805aa27bfc · artifacts runs/20260731_081427_experiment2 ·
took 6 m 37 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
3.1
Baseline seed: original TinyLocNet, fresh berlin-slim lineage 28f2ebe1
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.996 — worse than silence.
other
1.996
16 s
—
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
This row isn't a new idea being tested -- it's the starting line. The original, deliberately naive tiny CNN from the project's very first bootstrap gets retrained from scratch on Berlin's daytime-only imagery, with no design agent involved, just to prove the pipeline still works end-to-end after today's changes and to get a real number on the board. Everything after this row is a genuine attempt to beat it.
Hypothesis
Not a research hypothesis -- this is a deliberate reset, not an experiment testing an idea. After pivoting to the berlin-slim branch (single locale, no synthetic relighting, 100 m milestone), the old champion architecture was tuned for a different problem (4 areas x 6 lighting buckets) and the old experiment lineage no longer meant anything under the new scoring, so both were reset by request.
Method
Restore the original from-scratch bootstrap baseline (TinyLocNet, model/model.py + model/train.py from commit c0a1bdf) as the starting point, wipe experiments.sqlite so this branch's lineage starts at experiment 1 (old history archived, not deleted), and run the harness with SKIP_AGENT=1 -- no design/implementation agent, train+score+log only -- to prove the fixed harness end-to-end and establish a real number for the next experiment to actually beat.
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 2.68 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 100 m, scoring 2.67 km. Asked over: region holdout, daytime only, Berlin only. Scope cut to one city and one lighting condition for iteration speed. Same broken region-holdout eval.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Berlin only · ts 2026-07-31T08:13:58 ·
commit 28f2ebe186f8 · artifacts runs/20260731_081342_experiment1 ·
took 16 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The loop discarded this — no improvement under the metric then in force.
other
1.738
28 s
—
DISCARDED
Method
Not a research experiment. Second SKIP_AGENT=1 harness run, three minutes after the first. No design or implementation agent ran (both 0 s); 200 crops, 1 epoch, ~12 s of training. Its score reflects the training budget, not a hypothesis — there was no hypothesis.
Conclusion at the time
REVERTED — metric did not improve (2706.81 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.738 — 0.0% of held-out frames give a usable fix, 73.8% are confident and wrong, 26.2% abstain. Median miss 2.53 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.71 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.7380% usablecov 0.74
era Four areas, six lighting buckets · ts 2026-07-31T07:40:05 ·
commit 5e9419c3bd39 · artifacts runs/20260731_073937_experiment65 ·
took 28 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
other
1.738
34 s
—
DISCARDED
Method
Not a research experiment. The loop was run with SKIP_AGENT=1 to exercise the harness end-to-end on the morning of 31 July, before the berlin-slim branch was cut. No design agent and no implementation agent ran (both recorded 0 s); training used 200 crops for 1 epoch, ~19 s, against a real experiment's 36,000 crops over 8 epochs. The model it produced failed a deployment gate, which is what a 19-second model does.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.738 — 0.0% of held-out frames give a usable fix, 73.8% are confident and wrong, 26.2% abstain. Median miss 2.53 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.7380% usablecov 0.74
era Four areas, six lighting buckets · ts 2026-07-31T07:37:17 ·
commit 1365713063fa · artifacts runs/20260731_073643_experiment64 ·
took 34 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
architecture
1.811
64 m 52 s
$9.41
DISCARDED
In plain words
The last 27 attempts to beat the champion split into two piles: ones that changed HOW the model reads out its final answer from its internal map of guesses (all of them made things worse, sometimes much worse), and ones that changed WHAT the model's 'eyes' actually notice about the photo (the two best results in the whole project's history both came from this second pile). This round combines, for the first time, the two best 'better eyes' ideas that were only ever tried separately: first, the eyes get a two-part warm-up where they practice matching the SAME spot photographed under two different lighting conditions before they ever try to guess coordinates, so they learn to see past lighting changes on their own; second, every photo also gets a extra 'brightness contrast' sketch layered on top that stays roughly the same for a given spot regardless of what time of day it is, handing the eyes a shortcut to the same lesson. On top of that, since this round isn't allowed to reuse the champion's borrowed eyes at all, the two rival 'day expert / night expert' sub-brains are replaced with one brain that just gently retunes itself based on brightness, the model now also checks the mirror image of each rotated view (aerial photos really do look the same flipped), and instead of scanning its whole 1,024-cell guess-map when committing to an answer, it first throws out everything except its top 64 most-likely guesses so far-off lookalike spots can't quietly tug the final answer toward them.
Hypothesis
27 rounds since champion (exp-35, 743.07 m) have tried two disjoint kinds of change: reparameterizing the DECISION mechanism (VQ codebook exp-51 2751.73m, continuous GMM exp-52 2140.32m, three dense-per-patch-consensus variants exp-47/48/49 up to 2655.65m, IRLS robust consensus exp-55 2360.39m, spatial MoE exp-50 1109.13m, retrieve-then-rerank exp-45 1213.14m, factorized row/col axes exp-46 1e9, coordinate-generated field exp-39 1103.28m, coarse-to-fine exp-40 1011.58m) and reparameterizing the TRUNK/descriptor while leaving the decision mechanism alone or nearly alone. Every single decision-mechanism alternative to plain grid-classification-field-plus-soft-argmax has landed 1.5-3.7x worse than champion -- eight-plus independent measurements is enough to treat that family as refuted, not a shape still worth reaching into. Trunk-side changes tell a different story: exp-42 (domain-native contrastive self-supervised pretraining of a from-scratch trunk, decode/gate/field left completely untouched) reached 846.42 m, the single closest result in the entire post-champion history -- and exp-60 (a fixed, non-learned illumination-invariant retinex input channel + from-scratch trunk + cross-lighting consistency loss, gate deleted, decode otherwise untouched) reached 963.42 m, the best result of any FULLY pivot-compliant design (every non-frozen stage genuinely changed) measured so far. These are the two best post-champion results in the whole history and they attack the same thing from two different, non-overlapping angles -- what the trunk represents -- rather than how the field commits to an answer. They have never been combined, and neither has ever been tested inside a design that also legitimately rebuilds gate/ensemble/decode/confidence, which this round's compliance rule requires. Two more recent attempts at trunk swaps (exp-61 int8-quantization-freed from-scratch trunk, exp-62 SqueezeNet1.1 Fire trunk + FiLM + D4 + adaptive-beta decode) never actually trained -- both crashed on the GPU across all four areas identically before a single epoch completed, an infrastructure failure, not a measurement -- so they neither support nor refute anything, and this design deliberately keeps memory/compute modest (narrow from-scratch trunk, D4 without a wide pretrained trunk stacked under it, no learned per-example adaptive-beta MLP) specifically to avoid repeating whatever tipped those two rounds over an edge. Dispatcher/specialist-split designs (exp-30, 46, 59) have also uniformly lost, one catastrophically (exp-59, 2134.12 m) -- that family is not revisited here.
Method
model/model.py: delete `from torchvision.models import mobilenet_v3_small`, `PRETRAINED_TRUNK_PATH`, `_build_pretrained_trunk`, `IMAGENET_MEAN`/`IMAGENET_STD` buffers, `dark_logits`, and `gate`. Replace the trunk with a small from-scratch conv stack (~150-200k params, stride 16, 48 output channels at 8x8 -- deliberately matched to champion's own 48ch/8x8 shape rather than widened, since exp-61's capacity analysis and the original pre-exp-11 from-scratch baseline (128ch, still lost to the pretrained trunk) both show raw width was never champion's advantage -- pretraining quality was) taking a 4-channel input: the raw 3-channel RGB crop plus one new fixed, non-learned illumination-invariant channel computed in forward() every pass (log-luminance minus its own large-radius fixed Gaussian blur, via a non-trainable depthwise Conv2d buffer -- no new trainable parameters, reused from CLAUDE.md SS4's ambient-vs-active-light framing and exp-60's validated approach). Extend `_c4_stack` to `_d4_stack`: the existing 4 rotations plus each one's horizontal mirror (`.flip(3)`), 8 exact-pixel views total, pure index ops, no interpolation -- keep the trunk narrow specifically so this 2x view-count increase over champion's C4 does not repeat exp-62's likely memory-driven crash (that round paired D4 with an 8x-wider 384-channel trunk; this round does not widen the trunk at all). Delete the two-expert gate/blend entirely; replace with ONE unified field head (GAP + 1x1 layout-squeeze, same shape as champion's layout-aware head) modulated by a single lightweight brightness-conditioned per-channel gain: `film_gain = nn.Linear(1, feat_ch)` (no hidden layer, ~50 params) applied as `fmap_mod = fmap * (1 + torch.tanh(film_gain(lum)).view(-1, feat_ch, 1, 1))` before the layout-squeeze and GAP -- a genuine but minimal-risk replacement for the deleted gate, not a full FiLM MLP. Change Decode: instead of sharpen-then-soft-argmax over all 1024 cells, mask to a fixed top-K=64 subset BEFORE sharpening (`topv, topi = torch.topk(logits, 64, dim=1)`; scatter into a full-size tensor filled with -inf; softmax(DECODE_BETA * masked_logits) so cells outside the top-64 get exactly zero probability) -- this directly targets the champion-failure-mode-probes diagnosis (true cell in the raw field's own top-20 of 1024 on 33-58% of crops, but top-1 only ~2%) by structurally excluding the long low-probability tail of distant lookalikes from ever contributing weighted mass to the soft-argmax centroid, rather than merely turning up the sharpening temperature on top of them. The unsharpened, UNMASKED full-field softmax is still used for the CE training loss (matching champion's exp-14 separation of 'field training signal' from 'commit decode') and for one confidence feature (top-64 raw mass fraction, a diagnostic of how concentrated the raw field already was before masking). Rebuild the confidence head over [averaged GAP descriptor, sharpened-masked peak mass, sharpened-masked entropy over 64 cells, gap between masked and unmasked decode, top-64 raw mass fraction] -- the old gate-derived inputs no longer exist. Add a self-supervised domain-contrastive pretraining routine (module-level function, called from train.py before fine-tuning): for a batch of sampled locations, load the SAME crop under two different randomly chosen lighting buckets (both already available via train.py's `_load_bucket_img` cache), run both through the trunk + GAP only (no field head), and apply a standard InfoNCE/SimCLR loss pulling the two lighting-views' GAP descriptors of the SAME location together and different locations' descriptors apart within the batch -- this is the exact recipe that produced exp-42's 846.42 m result, now applied to the new 4-channel (RGB+retinex) input. model/train.py: add a `pretrain_contrastive(model, area, meta, crops, renders_dir, data_dir, rng, device, steps=600)` function using the InfoNCE loss above, called once before the existing epoch loop in `train_area` (modest step count so four areas still finish in reasonable wall-time -- this phase only runs the trunk+GAP, not the full D4 ensemble or field head, so it is cheap per step). The existing fine-tuning loop (confusability-weighted sampler, cosine LR schedule, two-tier trunk/head LR split via `model.features.parameters()`, `calibrate_conf_shift`) is otherwise unchanged and must keep working against the new model unmodified -- only the `info['init']` string changes to describe the new strategy. `export_onnx` and `estimate_position`'s ONNX input/output contract (1x3x128x128 float32 in, [[u,v,conf]] out -- the retinex channel is computed INSIDE forward() from the 3-channel input, never added to the external contract) are unchanged.
Conclusion at the time
REVERTED — metric did not improve (1074.76 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.811 — 0.5% of held-out frames give a usable fix, 81.5% are confident and wrong, 18.0% abstain. Median miss 2.42 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
figure agent
$4.85
design agent
$2.58
implementation agent
$1.98
total
$9.41
by model — claude-sonnet-5 $9.41 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.07 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8110% usablecov 0.82
era Four areas, six lighting buckets · ts 2026-07-30T20:58:48 ·
commit c46162512d6d · artifacts runs/20260730_195356_experiment63 ·
took 64 m 52 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.62
Fire-module SqueezeNet1.1 trunk + FiLM-conditioned single field + D4 symmetry + adaptive-sharpening decode (forced pivot, mobilenet_v3_small banned) 0041192d
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
26 m 11 s
$6.86
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model's 'eyes' have been the same borrowed eyes for 35 rounds, and the last 25 experiments all tried rearranging what happens AFTER the eyes without touching them -- none of it worked. This round we're not allowed to reuse those eyes at all, so we swap in a different pretrained set that sees the world through wider, richer 'glances' (8x more detail per glance) instead of trying to build new eyes from scratch, which has failed every single time it's been tried. Everything downstream is rebuilt to match: instead of two separate 'day expert' and 'night expert' sub-brains voting on the answer, there's now one brain that just retunes itself based on how bright the photo is; instead of checking the view from 4 rotated angles, we now also check its mirror image, since aerial photos really do look the same flipped left-right; and instead of always squinting at the guess-map by the same fixed amount before committing to an answer, the model now decides per-photo how hard to squint based on how confusing that particular map looks.
Hypothesis
25 straight reverts since champion (exp-35, 743.07 m) have swept nearly every decode/output family (VQ codebook, GMM, dense per-patch consensus, spatial MoE, retrieve-rerank, factorized axes, coarse-to-fine, coordinate-generated field) and nearly every from-scratch-trunk-plus-objective family (contrastive, reconstruction/canonicalization, five from-scratch backbones, exp-61's 4x-wider from-scratch trunk which failed the deployment gate outright) while leaving champion's exact pretrained trunk (mobilenet_v3_small features[:9], 190k params, 48ch@8x8 GAP) and its two-expert gate untouched or barely touched. The single closest post-champion result in the whole history, exp-42 (846.42 m), is the ONE experiment that changed only the trunk's pretraining objective while leaving champion's full field/decode/gate/C4-ensemble shape completely intact -- jointly with exp-61's own capacity analysis, this points at trunk richness (channel width / feature vocabulary), not decode shape, as the binding constraint every decode-family pivot has failed to move. This round bans champion's exact backbone outright, so instead of falling back to a from-scratch trunk (a family already tried 10+ times and consistently starved at ~130k params, per exp-61's own count), it swaps in a genuinely different pretrained family: SqueezeNet1.1's squeeze-then-expand 'fire module' trunk (torchvision, BSD-3, ImageNet-pretrained), truncated to its first 11 layers -- structurally unlike MobileNetV3's depthwise-separable inverted-residual-plus-SE-plus-hardswish blocks, and critically ~8x wider per spatial position (384ch vs 48ch) at a comparable total trunk parameter count (~336k vs 190k), so the field head finally reads a richer descriptor instead of a wider from-scratch stack no prior experiment could make work. Around that new trunk, every downstream stage is rebuilt rather than carried over: the two-expert gate/blend (an unexamined mixture-of-experts mechanism kept unchanged since exp-12, itself ~570k params of duplicated capacity) is replaced by a single FiLM-conditioned head, so the freed duplication budget pays for the wider trunk's field head instead of a second expert; the C4 rotation ensemble becomes full D4 (rotations plus mirror reflections -- aerial views are genuinely left-right symmetric, unlike the handwriting-style tasks C4/D4 usually get used for, and reflection invariance has never been tried); and the fixed-temperature decode sharpening (DECODE_BETA=3.0 constant since exp-14) becomes a per-example learned function of the raw field's own entropy, so confusable (high-entropy) fields get sharpened harder before commit -- attacking the same lookalike-cell problem exp-35's training-side sampling improved, now also from the decode side.
Method
model/model.py: delete the mobilenet_v3_small import, PRETRAINED_TRUNK_PATH/mnv3s_features8.pt load, dark_logits/gate mixture, and fixed DECODE_BETA. Build the trunk from torchvision.models.squeezenet1_1's features[:11] (stem conv + 4 Fire blocks through the third maxpool, ~336k params, ImageNet-pretrained, BSD-3), loading a new checked-in weights slice model/pretrained/squeezenet1_1_features11.pt (same strict-load convention as the file it replaces). Replace the C4 rotation stack with a D4 stack (4 rotations x mirror flip = 8 exact pixel views). Replace the layout-squeeze+GAP+gated-dual-head with ONE FiLM-conditioned head: a tiny brightness-to-(scale,shift) MLP modulates the trunk's ~7x7x384 feature map per-channel before a slim layout squeeze (1 channel) + GAP(384) feed a single Linear to the 32x32 cell logits. Replace fixed DECODE_BETA with a tiny 2-input MLP (raw field entropy + raw field peak mass, both detached) producing a per-example adaptive beta that scales the logits before the softmax soft-argmax commit; the unsharpened field (beta-independent) is still used for CE training and for the confidence head's shape features, mirroring exp-14's separation of 'well-calibrated field' from 'sharpened commit'. Recompute the confidence head over the new descriptor plus the adaptive beta value itself. model/train.py: no structural changes needed -- keep the trunk submodule named self.features so the existing two-tier LR split (trunk 1e-4 / head 1e-3), the confusability-weighted sampler, and the conf_shift calibration all keep working unmodified; only update the one-line init string logged in train_area()'s info dict to name the new pretrained family. ONNX export / estimate_position contracts, GRID_K=32, TARGET_SIGMA_CELLS, and the overall loss_fn shape (Gaussian-CE + coord L2 + conf BCE) are unchanged.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
figure agent
$3.22
design agent
$2.01
implementation agent
$1.63
total
$6.86
by model — claude-sonnet-5 $6.85 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-30T19:53:50 ·
commit 0041192d9e77 · artifacts runs/20260730_192739_experiment62 ·
took 26 m 11 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
45 m 05 s
$7.88
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Every recent attempt to swap out the one part of the model we're now required to remove made things worse, and the pattern points at a simple reason: the replacement parts were always smaller and cheaper than the piece they replaced, because the model has to fit in a fixed 4-megabyte file. This experiment tries a trick borrowed from how phones shrink apps: train the model's numbers to already sit on a coarse, round grid (like rounding every price to the nearest dollar instead of the nearest cent), so that when we later squeeze those numbers down to take a quarter of the storage space each, almost nothing is lost. That squeeze buys back enough room to build a genuinely bigger, single-focus model instead of the small or split-up replacements that kept losing.
Hypothesis
20+ rounds since champion (exp-35, 743.07 m) have swept nearly every decode/output family (VQ codebook, GMM, dense per-patch consensus, spatial MoE, retrieve-rerank, factorized axes, coarse-to-fine, coordinate-generated field) and nearly every trunk-objective family (contrastive, reconstruction/canonicalization translators, ShuffleNetV2-pretrained, five from-scratch variants) on top of or in place of champion's field+soft-argmax decode, and all of them lost. The single closest post-champion result in the whole history is exp-42 (846.42 m, contrastive-pretrained from-scratch trunk) -- the ONE experiment that changed only the trunk's training objective while leaving the champion's full-capacity field/decode/C4-ensemble shape completely untouched. Every from-scratch trunk ever tried (exp 41-55) was a small plain conv stack (~130k params) next to champion's 190k-param pretrained trunk feeding a ~570k-param single field head; every experiment that also SPLIT capacity across two or more heads (the exp-12 gate kept in several designs, and explicitly the three independent dispatcher/specialist attempts exp-30/46/59) lost, exp-59 catastrophically (2134 m) despite a coherent gradient-interference hypothesis -- its own pre-registered risk note said capacity-per-regime could dominate over gradient interference, and the result supports exactly that: capacity, not decode shape or gradient crosstalk, is what this design has been starved of every time a from-scratch trunk or a split-capacity design has been tried. This round bans the champion's exact pretrained trunk outright, which finally forces the one lever no prior round has pulled: instead of accepting whatever capacity a from-scratch trunk happens to have at float32 byte cost, train every trunk/field/confidence weight tensor to tolerate int8 rounding (a fixed, non-learned round-to-grid transform with a straight-through gradient, applied every forward pass) and export the deployed artifact through real int8 weight quantization (onnxruntime dynamic quantization, not a training-time simulation left un-exported) -- turning the 4-byte-per-weight cost that has capped every from-scratch trunk's width so far into a 1-byte-per-weight cost, and spending the freed budget on both a wider trunk AND a single larger unified field (deleting the exp-12 gate/dark-expert split entirely, since the evidence above says specialization has been costing capacity, not buying it).
Method
In model/model.py: delete the mobilenet_v3_small import, _build_pretrained_trunk, PRETRAINED_TRUNK_PATH, and the ImageNet mean/std buffers entirely -- no torchvision import anywhere in the file. Replace with a from-scratch, never-pretrained depthwise-separable conv trunk (a stem 3->64 regular 3x3 conv stride 2, then three depthwise-separable stride-2 blocks 64->128->224->320, BatchNorm2d+ReLU6 after every conv, 128x128 input -> 8x8x320 output -- 4x wider than every from-scratch trunk tried in exps 41-55 because depthwise-separable convs buy width per byte far more cheaply than the plain conv stacks those experiments used). Delete self.dark_logits and self.gate entirely (the exp-12 two-expert blend) -- one unified loc_logits Linear head reads the new trunk's [320-d GAP + 8-channel/64-cell layout-squeeze code] descriptor, same layout-squeeze mechanism as today just re-widthed. Raise GRID_K from 32 to 40 (1024 -> 1600 cells, ~175 m cells instead of ~220 m) since the freed byte budget affords a finer field; DECODE_BETA, the Gaussian-smoothed-CE target, and the sharpened-soft-argmax decode formula are otherwise byte-identical, just operating over the new grid size. The C4 rotation-vote (4x forward pass, average field logits over the crop's 90-degree rotations) is kept -- it is a previously-validated, causally distinct mechanism (exp 16, +33%) this experiment is not testing -- but its code necessarily changes because there is no longer a gated blend to average before the vote: logits4 = self.loc_logits(...) directly, then the same reshape(4,n,-1).mean(dim=0). Confidence head is rebuilt with re-dimensioned Linear layers reading the new (320-d GAP + peak + entropy + sharp/unsharp gap) descriptor -- same three shape-derived features as today, same detached-gradient contract, just resized for the new GAP width. Add a QATConv2d/QATLinear module pair (thin nn.Conv2d/nn.Linear subclasses) that fake-quantize self.weight every forward call via a symmetric per-tensor 8-bit round-to-grid straight-through estimator (scale = weight.detach().abs().max()/127, quantized = round(weight/scale).clamp(-127,127)*scale, gradient passes straight through the round) before calling the normal functional conv/linear op -- used for every weighted layer in the trunk, layout_squeeze, loc_logits, and conf_head (NOT the tiny confidence-head bias-only ops or the fixed grid-center buffers). In model/train.py: replace the two-LR-group optimizer (trunk_params at 1e-4, head_params at 1e-3 -- a fine-tuning schedule that only makes sense for a pretrained trunk) with a single param group at 1e-3 for the whole from-scratch model, since there are no pretrained features to protect from early large gradients; update the `info["init"]` string to reflect from-scratch init with weight fake-quantization. After the existing epoch loop, calibration, and float32 export_onnx call (kept as an intermediate sanity artifact), add one final step: onnxruntime.quantization.quantize_dynamic(model_input=<float32 onnx path>, model_output=<same models/<area>.onnx path>, weight_type=QuantType.QInt8) with default (per-tensor, no reduce_range) settings, overwriting the scored artifact with the real int8-weight ONNX -- input/output tensor names, shapes, and the float32-in/float32-out contract are unchanged by dynamic quantization (only Conv/Gemm/MatMul weight tensors become int8; activations stay float32 end to end), so pipeline/score.py needs no changes. Confusability-weighted sampling (exp 35), TRAIN_REALIZATIONS, EPOCH_MULT, per-epoch resampling, and the calibration procedure are all left exactly as today -- this experiment's ONE hypothesis is capacity, not data strategy, and mixing in a sampler change would confound attribution.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
figure agent
$4.09
implementation agent
$2.22
design agent
$1.56
total
$7.88
by model — claude-sonnet-5 $7.87 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-30T19:27:34 ·
commit 9421cc39c20e · artifacts runs/20260730_184229_experiment61 ·
took 45 m 05 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
architecture
1.991
86 m 54 s
$6.23
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Every recent experiment has tried a different way for the model to guess a location, or a different pretrained starting brain for it, and all of them lost to the current champion. This time we try something the project noticed early but never actually got to test properly: give the model a second, cleaned-up version of the photo, computed by simple non-learned math, that strips out roughly how bright the whole scene is and keeps mostly the sharp edges and shapes -- like handing it a rough charcoal sketch alongside the color photo. Buildings and roads look the same in that sketch whether it's noon or midnight; only the color photo changes drastically. We also add a training rule that nudges the model's internal summary of 'what this place looks like' to stay the same whether the photo was rendered as daytime or nighttime, since it's the same physical spot either way.
Hypothesis
20 straight rounds since champion (exp-35, 743.07 m) have swept nearly every decode/aggregation family (VQ codebook, continuous GMM, dense per-patch consensus under 3 different aggregators, spatial MoE, retrieve-rerank, factorized axes, coarse-to-fine) and every plausible trunk-objective swap (contrastive, joint/sequential reconstruction, ShuffleNetV2-pretrained, from-scratch x5) on top of the champion's field+soft-argmax decode, and all of them lost -- several catastrophically. The single closest post-champion result in the entire history is exp-42 (846.42 m, +14%), which is the ONE experiment that changed only the trunk's pretraining objective (contrastive) while leaving the champion's field/decode/rotation-ensemble shape untouched; every experiment that also rewrote the decode landed at 1100-2655 m or worse. That pattern says the decode family is not the wall -- the trunk's descriptor content is. But no trunk-objective swap tried so far has attacked the specific, previously-diagnosed nuisance in that descriptor: iter-12 probes (project memory champion-failure-mode-probes; also cited by exp-33/38) found the champion's descriptor rides low-level resampling-blur statistics that carry zero location information (removing rotation-resample blur nearly doubles error, 983->1668 m on a matched crop), and CLAUDE.md SS4 itself names the fix at the data-generation level: separate reflected AMBIENT light (dims with time-of-day) from ACTIVE artificial lighting (streetlamps/windows, lighting-invariant). Exp 38 proposed giving the trunk a fixed, non-learned Retinex-style illumination-invariant channel (log-luminance minus its own large-radius Gaussian blur) precisely to hand the network that decomposition explicitly instead of hoping fine-tuning discovers it -- but it was REJECTED BEFORE IMPLEMENTATION, correctly, for leaving the lighting gate/field/confidence/training-signal stages self-reported unchanged under the pivot rule. The retinex idea itself was never trained or measured, unlike every learned-canonicalization alternative already tried and refuted (exp 43/44's reconstruction translators, exp 54's memory-safe corrected retry) -- this is a categorically different mechanism (a fixed geometric transform, not a learned translator with its own capacity/loss to fail), so it is not a repeat of those three refutations. This design is exp-38's corrected, fully-compliant re-attempt: every stage it touches actually changes in the code, and the fixed retinex channel is paired with a genuinely new training-signal addition (a cross-lighting descriptor-consistency loss) that gives the invariance hypothesis a second, independent lever rather than resting on the input channel alone. The champion's mobilenet_v3_small/mnv3s_features8.pt trunk is banned this round regardless, which forces a from-scratch trunk -- used here as the occasion to also delete the two-expert bright/dark gate (exp 12), since the retinex channel is meant to supply architecturally the invariance the gate was patching statistically.
Method
In model/model.py: (1) delete the mobilenet_v3_small import and _build_pretrained_trunk/PRETRAINED_TRUNK_PATH/IMAGENET_MEAN/IMAGENET_STD -- replace with a new from-scratch compact conv trunk (~4-5 conv blocks reaching an 8x8 spatial output, channel count sized to keep the exported ONNX comfortably under the 4 MiB gate) whose first conv accepts 4 input channels. (2) Add a fixed, non-learned Retinex-style preprocessing step computed inside forward() from the raw [0,1] RGB input: luminance -> log1p -> large-radius Gaussian blur (fixed depthwise-conv buffer, no gradient, sigma on the order of ~16 px on the 128x128 crop) -> retinex = log-luminance minus its own blur, clamped/rescaled to roughly [0,1] -- concatenated as a 4th channel before the first learned conv layer. This is computed from the existing ONNX input, so the (1x3x128x128 float32 [0,1]) export contract is unchanged. (3) Delete the dark_logits/gate branch entirely -- a single loc_logits head reads the unified layout+GAP descriptor (same field/decode math: Gaussian-smoothed-CE-trained 32x32 grid, DECODE_BETA-sharpened soft-argmax, unchanged) built from the new trunk's output. (4) Confidence head is rebuilt to read the new (non-gated) field's shape statistics (peak mass, entropy, sharpened-vs-unsharpened gap) -- same mechanism as champion, wired to the new descriptor since the old gate-derived inputs no longer exist. (5) Add a `return_descriptor: bool` option to TinyLocNet.forward so train.py can retrieve the pooled post-rotation-average GAP descriptor for the consistency loss (mirrors the existing return_logits pattern). In model/train.py: (6) sample_epoch additionally draws, for each per-bucket batch, one 'lighting partner' crop per location at the identical (cx, cy, heading) but from one other uniformly-random bucket (reusing the already-cached per-bucket renders/realizations -- no new rendering cost), returned alongside the primary batch. (7) train_area's step loop forwards both the primary and partner crop batches (return_descriptor=True) and adds a new CONSISTENCY_WEIGHT-scaled L2 term between their pooled descriptors to the existing loss_fn output, backpropagated jointly. (8) Keep EPOCH_MULT, TRAIN_REALIZATIONS, CONFUSABILITY_ALPHA, and the calibration procedure exactly as champion -- do not also scale up training length, since the partner-view forward pass already roughly doubles per-step compute and four areas must still finish in sensible wall time.
Conclusion at the time
REVERTED — metric did not improve (963.42 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.991 — 0.0% of held-out frames give a usable fix, 99.0% are confident and wrong, 1.0% abstain. Median miss 3.07 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
figure agent
$3.07
design agent
$1.80
implementation agent
$1.36
total
$6.23
by model — claude-sonnet-5 $6.22 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 963.4 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9910% usablecov 0.99
era Four areas, six lighting buckets · ts 2026-07-30T18:42:21 ·
commit 4add08608d95 · artifacts runs/20260730_171527_experiment60 ·
took 86 m 54 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.59
Independently-trained day/night specialist twins with a trunk-free brightness dispatcher efa8f69b
The loop discarded this — no improvement under the metric then in force.
architecture
1.953
80 m 09 s
$6.15
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Instead of one brain trying to memorize the city in both daylight and pitch darkness at once, we build two smaller, separate brains -- one that only ever studies daytime photos, one that only ever studies night photos -- trained completely apart so neither one's lessons get diluted by the other's. A tiny doorman glances at how bright the incoming photo is and decides which brain should answer. We're testing whether the old one-brain-does-everything setup was quietly making both jobs a little worse than they could be on their own.
Hypothesis
20 straight reverted rounds have exhaustively swept decode/output parameterizations (dense field, per-patch voting + attention pooling, per-patch voting + IRLS robust consensus, VQ codebook, continuous GMM, coarse-to-fine, retrieve-then-rerank, spatial MoE, canonicalization translators) on top of trunks that were EITHER the banned pretrained MobileNetV3-Small OR a from-scratch conv stack -- and every single one lost to champion (exp-35, 743.07m). The three prior 'dispatcher' rounds in this history (exp-30, exp-46, exp-50) all share one thing none of the decode sweeps questioned: the dispatcher blends two or more expert HEADS that read off a SINGLE SHARED trunk/backbone, trained jointly end to end every step -- so gradients from night crops still shape the features a day crop's expert reads, and vice versa. That is soft task-blending inside one optimization, not specialization. This round's forced pivot bans the champion's shared trunk outright, which finally makes the untested version of the dispatcher idea cheap to build correctly: TWO fully independent from-scratch trunks, each trained in its OWN optimization run on only its own half of the lighting buckets, so a night crop's gradient never touches a single day-specialist weight and vice versa -- true task decomposition, not joint multi-task blending. If the champion's ~743m worst-case has been capped by one shared representation being pulled in two directions (day's rich-texture regime vs. night's near-featureless regime), removing that shared-gradient interference by training two small purpose-built specialists in isolation, then only calibrating a tiny trunk-free dispatcher on top, should relax that cap -- at the cost of each specialist getting a smaller capacity budget than champion's single trunk, since both must fit the same 4 MiB envelope together.
Method
Replace the single shared-trunk model with two independent from-scratch specialist networks -- Day (morning/midday/afternoon) and Night (early_evening/evening/night) -- each its own small conv trunk + coarse classification field + sharpened soft-argmax decode + confidence head, no weights shared between them and no pretrained init anywhere (mobilenet_v3_small / mnv3s_features8.pt banned this round). A third, tiny, trunk-free dispatcher (3 raw-pixel brightness statistics -> 2-layer MLP -> sigmoid gate g) blends the two specialists' (u, v, conf) outputs for the final export. Training is staged, not joint: Phase 1 trains only the Day specialist on its 3 buckets; Phase 2 trains only the Night specialist on its 3 buckets, from a fresh optimizer with zero gradient crossover into Phase 1's weights; Phase 3 freezes both specialists completely and trains only the ~40-parameter gate across all 6 buckets on the frozen specialists' blended output. One ONNX graph is exported at the end (both specialists always run; the gate blend, not graph branching, does the routing), preserving the single-file single-forward-pass export contract.
Conclusion at the time
REVERTED — metric did not improve (2134.12 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.953 — 0.0% of held-out frames give a usable fix, 95.2% are confident and wrong, 4.8% abstain. Median miss 2.74 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
implementation agent
$2.38
figure agent
$2.25
design agent
$1.52
total
$6.15
by model — claude-sonnet-5 $6.14 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.13 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9530% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-23T21:50:49 ·
commit efa8f69bd1f7 · artifacts runs/20260723_203040_experiment56 ·
took 80 m 09 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.55
Dense scene-coordinate voting with a differentiable IRLS robust consensus (from-scratch trunk) c998b079
The loop discarded this — no improvement under the metric then in force.
architecture
1.826
21 m 51 s
$3.41
DISCARDED
In plain words
Instead of one all-knowing guess about where the photo was taken, we now let roughly a thousand tiny local patches of the same photo each make their own small, independent guess -- like asking a thousand people who each only glimpsed one corner of a map to point at where they think you are. Two earlier attempts at this already failed because they combined all those guesses in one single pass -- either just averaging them all equally, or letting one learned 'attention' pass decide the weights once and stick with it -- so a handful of confused, wrong guesses could still drag the final answer off course. This time the combining step runs several rounds: after each round it checks which guesses agree with the group and which ones look like outliers, and quietly turns down the volume on the outliers before averaging again -- the same trick a surveyor uses when throwing out one wildly-off measurement before re-averaging the rest. If a photo is genuinely confusing (say, featureless forest or open water), the votes never converge and the model honestly says 'not sure' instead of reporting a guess nobody actually agreed on.
Hypothesis
20 straight rounds since champion exp-35 (743.07 m) have failed, and this round's forced direction pre-assigns the ACE/DSAC family: dense per-cell coordinate regression aggregated by a robust consensus, not a global classification field. This exact family (one global descriptor replaced by many local location votes, over the same single-crop-center supervision this project actually has) has been measured twice before, and both measurements point at the AGGREGATOR, not the per-cell voting idea, as the failure point: exp-4 (2563.37 m, reverted) used a plain unweighted mean over per-patch coordinate guesses, and exp-49 (2655.65 m, reverted, ~3.6x worse than champion) used a single learned softmax-attention-weighted mean. Both are one-shot, non-iterative pooling: a single set of weights (uniform, or one attention pass) is computed once and applied once, so an outlier vote that the attention head fails to suppress on its first and only pass drags the final answer proportionally to how much weight it received -- there is no mechanism to notice, after seeing the emerging consensus, that a given vote disagrees with it and correct course. This design tests the one aggregator in this family that has never been measured: iteratively reweighted least squares (IRLS) with a redescending kernel, which recomputes vote weights against the CURRENT consensus estimate over several rounds, so a vote that looked plausible in isolation but disagrees with where the other ~1,023 votes are converging gets progressively down-weighted rather than fixed at its first-pass score. This is mechanically closer to what ACE/DSAC actually do at inference (RANSAC re-scores hypotheses against an evolving consensus) than either prior attempt was, and it is a materially different bet from 'per-patch consensus is refuted' -- it is a bet that per-patch consensus was never fairly tested because both prior attempts used a pooling mechanism with no self-correction.
Method
Replace the champion's global-descriptor + 1024-way map-cell classification field entirely with: (1) a from-scratch, no-pretrained conv trunk producing a 16x16 spatial grid of local features (banned identifiers mnv3s_features8.pt / mobilenet_v3_small do not appear anywhere); (2) a per-cell head that independently regresses an absolute (u, v) coordinate guess plus a log-variance (confidence) from each cell's own local feature vector only -- no global pooling anywhere in the forward path; (3) the crop's four 90-degree C4 rotations each get their own independent trunk pass and their own 16x16 grid of votes, pooled together as 4x16x16 = 1,024 total independent votes (previously the four rotations' full field maps were averaged BEFORE any decision; now every rotation's every cell is one independent vote into the consensus stage); (4) a 3-round differentiable IRLS solve: start from a confidence-weighted mean of all 1,024 votes, then for each of 3 rounds recompute each vote's residual distance to the current estimate, apply a fixed-scale Geman-McClure redescending re-weighting (soft-inlier down-weighting of votes far from the emerging consensus), renormalize, and recompute the weighted mean -- fully differentiable, no argmax/hard threshold/data-dependent control flow anywhere, so it is both trainable end-to-end and ONNX-exportable as a fixed 3-iteration unroll; (5) overall confidence derived from the final iteration's effective weight concentration (inverse of the summed squared normalized weights, i.e. how few votes the answer actually rests on) and the final weighted residual spread, fed through a small calibrated head trained the same way as the champion's hit-predictor (BCE against a within-GOOD_ERR_UV label, detached inputs, post-hoc per-bucket conf_shift calibration). The confusability-weighted training sampler (exp-35) is rebuilt at the level of individual training locations (nearest-distant-location descriptor match, same exclusion radius idea) instead of via the now-deleted GRID_K classification grid, since there is no classifier grid left to bucket by. Loss = final-consensus-estimate L2 + 0.5x mean per-vote heteroscedastic NLL (trains each cell's own sigma to track its own actual error) + 0.3x confidence BCE, mirroring the champion's loss-term weighting shape but built for the new decode.
Conclusion at the time
REVERTED — metric did not improve (2360.39 m vs best 1176.5 m); change discarded
Re-measured on today's ruler
Mission score 1.826 — 0.0% of held-out frames give a usable fix, 82.5% are confident and wrong, 17.5% abstain. Median miss 2.41 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
implementation agent
$1.75
design agent
$1.65
total
$3.41
by model — claude-sonnet-5 $3.40 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.36 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8260% usablecov 0.82
era Four areas, six lighting buckets · ts 2026-07-23T17:03:59 ·
commit c998b0796247 · artifacts runs/20260723_164208_experiment55 ·
took 21 m 51 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
relighting
1.926
19 m 42 s
$2.88
DISCARDED
In plain words
Two earlier attempts tried teaching the model to first 'clean up' a dark, noisy night photo into something that looks like a clear daytime picture before trying to figure out where it was taken -- like adjusting brightness and contrast before reading a blurry street sign. Both attempts crashed partway through training for a boring technical reason (the computer ran out of memory), so we never actually found out if the idea works. This round redesigns that cleanup step to be much smaller and lighter -- it works on a shrunk-down, thumbnail version of the picture instead of the full-size one -- so it can't run out of memory the same way, and we finally get to test the idea for real. Everything downstream is also rebuilt to match: a fresh, untrained map-reading network (since the old borrowed one is off-limits this round), with the old 'two separate experts, one for day, one for night' trick removed entirely, because the cleanup step should make that split unnecessary.
Hypothesis
18 straight rounds (36-53) have failed to beat champion exp-35's 743.07 m. Splitting them by what they actually changed gives a clean signal: every one of the 11 rounds that swapped or reparameterized the DECISION mechanism while the descriptor-producing trunk was either untouched or forcibly swapped (36-40, 45, 46, 48-53 -- margin losses, coordinate-generated fields, coarse-to-fine, retrieve-rerank, factorized axes, dispatcher+MoE, per-patch consensus, residual VQ, Gaussian-mixture regression, a ShuffleNetV2 trunk paired with FiLM+top-K decode) landed clearly worse than champion, several catastrophically (1e9 x5, 1552-2752 m x6). The ONE round that instead kept the champion's exact field+soft-argmax decode shape and only changed what the trunk was trained to represent (exp 42, domain-native contrastive from-scratch pretraining) came closest of all 17 post-champion rounds at 846.42 m (+14%) -- the tightest gap in the entire losing streak, and the only result inside 1000 m. That single data point argues descriptor/appearance-canonicalization quality, not decision-mechanism shape, is the real remaining lever: champion's ImageNet-MobileNetV3 trunk (now banned) was never taught to discard lighting as a nuisance variable, and no downstream decode rewrite has ever fixed that by construction. CLAUDE.md SS4 explicitly names learned relighting as one of the areas most open to genuine improvement, and library L1 proposes exactly this ('canonicalize the night: denoise toward the clean render') -- but this exact family was tried twice (exp 43 joint reconstruction, exp 44 sequential flying translator) and BOTH were never actually measured: their train logs show a clean 0-byte crash on 2 of 4 areas each round (different area-pairs each time, ruling out an area-specific cause) diagnosed as an OOM/ENOSPC race from loop.sh's 4-way concurrent GPU launch colliding with a full-resolution (128x128) encoder-decoder's large intermediate activations. That is an infra artifact, not a refutation -- the canonicalization bet itself remains untested at the design level, exactly like exp 47/48's per-patch-consensus idea was before its own corrected re-attempt (exp 49) finally measured it (and refuted it, cleanly, this time). This design is that same kind of corrected re-attempt, not a repeat of 43 or 44: the translator is redesigned from scratch to make the OOM/ENOSPC failure structurally impossible (bottlenecked at 32x32 with narrow channels, one pass per crop instead of one pass per C4-rotation-copy) rather than hoping the same shape gets luckier concurrency timing, and the reconstruction loss is computed at a downsampled 32x32 target instead of full 128x128 pixels -- directly following exp 44's own pre-registered falsification fork (c), which predicted that a full-resolution L1 term risks oversmoothing genuine layout detail (building edges) while chasing pixel fidelity, and recommended exactly this fix ('weight the L1 term lower or restrict it to a coarser scale') for the next attempt.
Method
Insert a tiny from-scratch delighting translator ahead of the trunk in model/model.py: Conv2d(3,16,k=4,s=4) -> 32x32x16, two 3x3 GroupNorm+ReLU convs at 32x32x24, Conv2d(24,3,k=3) -> a 32x32x3 raw correction. The correction is bilinearly upsampled (parameter-free) to 128x128 and added residually to the input crop (clamped to [0,1]) to produce the 'cleaned' image the rest of the network sees; peak activation size never exceeds 32x32x24, and the crop is translated ONCE (not once per C4 rotation copy, unlike exp 44's ordering) -- both changes directly shrink the per-example memory footprint that the OOM/ENOSPC crashes were traced to. Replace the ImageNet-pretrained MobileNetV3-Small trunk (banned this round) with a from-scratch 4-stage plain conv stack (32/64/96/128 channels, stride 2 each, GroupNorm+ReLU), 128x128 -> 8x8x128, reading the CLEANED image's four C4 rotations. Delete the dual-expert lighting-gate blend (loc_logits/dark_logits/gate) entirely -- one unified field (GAP + 1x1-squeezed layout code -> GRID_K x GRID_K logits), matching the only structural choice (42/43/44) that removed the gate without itself causing a measured regression. Keep the existing sharpened-softmax soft-argmax decode exactly (DECODE_BETA mechanism unchanged in form; it is 'changed' only in that it now reads a single field instead of a gated blend, forced by the gate's removal). Confidence head gains one new detached input: the translator's own mean |correction| magnitude (how much repair the crop needed), alongside the existing peak/entropy/sharpened-vs-unsharpened-decode-gap features. Training: sample_epoch also extracts the pixel-aligned clean daytime reference crop (same cx/cy/angle, from reference.tif, already loaded for compute_cell_weights) for every drawn training location -- a free supervision pair per library L1. loss_fn gains a reconstruction term: L1 between (avg_pool2d(input,4) + raw_correction).clamp(0,1) and avg_pool2d(reference_crop,4), weight 0.3 (down from exp 43/44's implicit 1.0, per the falsification-fork-(c) fix). Training schedule: single LR group for all parameters (translator + trunk + head), since nothing is pretrained -- the old 10x trunk/head split existed only to protect transferred ImageNet features, which no longer exist.
Conclusion at the time
REVERTED — metric did not improve (1929.57 m vs best 1176.5 m); change discarded
Re-measured on today's ruler
Mission score 1.926 — 0.0% of held-out frames give a usable fix, 92.5% are confident and wrong, 7.5% abstain. Median miss 2.97 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
implementation agent
$1.46
design agent
$1.42
total
$2.88
by model — claude-sonnet-5 $2.88 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.93 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9260% usablecov 0.93
era Four areas, six lighting buckets · ts 2026-07-23T16:21:10 ·
commit d06f7d8de53f · artifacts runs/20260723_160127_experiment54 ·
took 19 m 42 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.53
ShuffleNetV2 trunk with FiLM-conditioned single field and top-K decode replaces the two-expert MobileNet blend 01ab7892
The loop discarded this — no improvement under the metric then in force.
architecture
1.836
21 m 36 s
$2.96
DISCARDED
In plain words
Every one of the last 16 tries kept the same borrowed off-the-shelf 'photo recognition' brain and only changed how the model turns its guesses into a final answer -- and none of them won. The one time someone swapped the brain itself instead came closest to beating the champion. So this time we swap in a differently-built starter brain (ShuffleNet instead of MobileNet -- same idea of starting from a brain pretrained on ordinary photos, but organized in a structurally different way, like hiring someone with a different training background rather than re-coaching the same specialist). We also replace the old on/off 'is this a night photo?' light switch -- which forced two separate day-expert and night-expert opinions to be blended -- with a dial that continuously reads how dark the shot is. And when the model commits to an answer, it now only lets its 48 most-likely spots (out of 1024 possible) compete for the final vote, instead of letting one confident-looking but wrong far-away lookalike quietly drag the answer toward it.
Hypothesis
16 straight reverted rounds (36-52) all churned the location-decision mechanism (softmax reparameterizations, attention consensus, spatial MoE, hard VQ coding, continuous Gaussian mixture) while leaving champion's ImageNet-MobileNetV3-Small trunk untouched, and every one of them landed well below champion (743.07 m) -- several catastrophically (1000000000.0 m x6, 2140-2751 m x3). The ONE round that instead changed the trunk and kept the field-decode family (exp 42, domain-native contrastive from-scratch trunk) came closest of all 17 post-champion rounds at 846.42 m (+14%), the tightest gap in the entire losing streak. That single data point, plus the uniform failure of every decode-family alternative, points at descriptor information content -- not the decision mechanism -- as the real wall: champion's two hard-gated experts (a layout-aware head and a GAP-only 'dark' head, blended by a sigmoid trained on raw brightness) are a coarse patch over a trunk whose SE-gated inverted-residual features were learned for natural photographs, not confusable low-resolution aerial texture, and whose lighting handling is a binary switch rather than a continuous read of illumination. With that backbone banned this round regardless, the experiment worth running is: does a structurally different pretrained feature family (grouped convolutions + channel shuffle, no depthwise-separable/SE blocks), combined with continuous rather than discrete lighting conditioning, close more of the gap than any of the 11 decode rewrites did -- while also fixing the one real mismatch the champion's own field never addressed: the frozen scorer's soft-argmax reads across all 1024 cells even though only a handful are ever genuinely competitive, letting a confident-looking distant lookalike quietly pull the answer toward it.
Method
Four coupled changes, one coherent design: (1) model/model.py's trunk is replaced with an ImageNet-pretrained ShuffleNetV2 x0.5 (torchvision, BSD-3) truncated to stem+stage2+stage3 (stride 16, ~96ch @ 8x8 for a 128x128 input) -- a structurally different backbone family from MobileNetV3, loaded from a new local weights asset model/pretrained/shufflenetv2_x0_5_stage3.pt. (2) The two hard-gated field experts (bright head + dark head + sigmoid blend) are deleted; one field FC reads a single descriptor built from GAP + the existing 1x1 spatial-layout squeeze, continuously modulated via FiLM (scale/shift from a tiny MLP over the crop's own mean luminance) instead of a binary day/night gate. (3) The four C4 rotation views are fused at the feature level (element-wise max over the 4 views' FiLM-modulated descriptors) before the single field FC runs once per crop, replacing the old late fusion of two already-blended heatmaps. (4) Decode is restricted to a top-48-of-1024 masked soft-argmax after sharpening (was: full 1024-way soft-argmax), and confidence is recomputed directly from that shortlist's normalized entropy through a 2-parameter calibrated score, replacing the old 4-feature learned confidence MLP. Training (model/train.py) gets three matching changes: confusability-weighted sampling (exp 35) is computed per (cell, lighting bucket) using each bucket's own rendered texture instead of one global reference-image weighting; loss_fn gains one new term, a margin penalty when the true location's cell is not already inside the model's own top-48 shortlist, so the training signal explicitly targets what the new decode reads; and the LR schedule adds a 500-step linear warmup before cosine decay, with the pretrained-trunk LR ratio dropped from 10x to 20x below the head LR.
Conclusion at the time
REVERTED — metric did not improve (1552.08 m vs best 1176.5 m); change discarded
Re-measured on today's ruler
Mission score 1.836 — 0.2% of held-out frames give a usable fix, 83.8% are confident and wrong, 16.0% abstain. Median miss 2.14 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$1.86
implementation agent
$1.09
total
$2.96
by model — claude-sonnet-5 $2.95 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.55 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8360% usablecov 0.84
era Four areas, six lighting buckets · ts 2026-07-23T16:01:06 ·
commit 01ab78924253 · artifacts runs/20260723_153930_experiment53 ·
took 21 m 36 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.52
Continuous Gaussian-mixture location regression replaces the shared map-cell classification field 5361f941
The loop discarded this — no improvement under the metric then in force.
architecture
1.971
21 m 32 s
$3.90
DISCARDED
In plain words
For 16 rounds straight, every fix has tried to make one master scoreboard -- ranking up to 1,024 possible neighborhoods against each other -- work a little better, whether that scoreboard was one big table, a filing-cabinet lookup, or a panel of votes. This round throws the scoreboard out completely. Instead, the model gets to say 'I think it's one of these 6 specific spots' (times 4, once per compass direction it double-checks itself from) and picks whichever single guess it's most sure about, the same way a person narrows down a place to a handful of candidates rather than ranking every neighborhood in the city against each other. Because the backbone network powering last round's champion is banned this round, we also had to retire the old sampling trick that leaned on a classroom-style grid of neighborhoods, and replace it with one that works location-by-location instead.
Hypothesis
16 straight rounds since champion exp-35 (743.07 m) have failed, and every one of them left one thing structurally intact even when it looked abandoned: SOME shared, jointly-normalized comparison across many location candidates decides the answer -- a flat 1024-way softmax (36-40, 45, 46), a per-region softmax repeated 64 times (50), an attention-weighted mean over 256 votes (47-49), or a hard-argmin residual-VQ codebook lookup (51, which explicitly abandoned softmax for exclusive nearest-neighbor coding and still scored 2751.73 m, 3.7x worse than champion). champion-failure-mode-probes diagnosed the wall precisely: the true cell is the classifier's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops -- confusable lookalikes stay comparable under one shared scale no matter how that scale is reparameterized, factorized, shortlisted, or replaced with hard coding. This design tests the one parameterization family absent from all 51 rounds: a small, fully continuous, per-crop Gaussian mixture over (u,v), with each component's mean a FREE regression output (not a fixed grid center, not a codebook entry, not a spatially-partitioned expert), trained by exact mixture negative-log-likelihood (proper probabilistic multimodal regression, Bishop-style MDN) instead of cross-entropy-over-candidates, hard nearest-neighbor coding, or attention-averaged consensus. A K=6-component mixture per rotation view, pooled across the 4 C4 views into one 24-component mixture, gives the model just enough hypotheses to represent genuine ambiguity between a handful of lookalike districts -- without ever forcing 1024, 256, or 2304 candidates into one comparison at once, and without exp 37's winner-take-all-L2 failure mode (dead/uninitialized hypotheses starved of any gradient): every component gets a soft NLL-weighted gradient in proportion to its own likelihood under the true target, every step. The mnv3s_features8.pt / mobilenet_v3_small backbone is banned this round, which forces the trunk to become from-scratch anyway -- rather than treat that as a tax paid while leaving the decision mechanism alone (the exact failure the patience rule calls out), the forced trunk change is the occasion to also delete the GRID_K cell abstraction entirely: with no classification grid anywhere in the model, the champion's training-data mechanism (exp 35's confusability-weighted sampling, computed over 32x32 GRID_K classifier cells) has no cells left to attach to, so it is rebuilt at the level the new architecture actually operates on: individual training locations. This is a genuine whole-pipeline pivot (trunk, decode, loss, confidence, and the sampler all change together because the grid they shared is gone), not a decode swap bolted onto an unexamined trunk.
Method
Replace TinyLocNet's ImageNet-pretrained MobileNetV3-Small trunk + GAP/layout head + gated dark-expert + GRID_K x GRID_K classification field + beta-sharpened soft-argmax decode + field-shape confidence, in model/model.py, with: (1) a from-scratch conv trunk (~4 stride-2 blocks, 128x128 -> 8x8, ~300-400k params, no pretrained weights, no torchvision import); (2) a shared small head that reads {GAP descriptor, 1x1-squeezed spatial layout code} and outputs, per rotation view, K=6 mixture components (mean_u, mean_v via sigmoid to stay in [0,1], a scalar log_sigma, and a mixing logit); (3) the 4 C4 rotation views' components are pooled into one 24-component mixture (concatenate, renormalize mixing weights by softmax jointly over all 24 logits) instead of averaging field logits; (4) decode = the mean of the single highest-weight component (hard mode-commit, matching the project's established peak-commit lesson from exp 14 rather than a soft blended mean, which would reintroduce centroid shrinkage); (5) loss_fn becomes exact 2D-Gaussian mixture NLL over the pooled 24 components (isotropic covariance per component, log_sigma floored for numerical stability) plus the existing conf BCE term, recomputed on new features; (6) confidence is now {winning component's own mixing weight (post-hoc renormalized among the 24), winning component's own sigma, and the mixture weight distribution's entropy over all 24 components} in place of the deleted field's peak-mass/entropy/sharpened-vs-unsharpened-gap features -- same conf_head MLP shape and the same conf_shift calibration mechanism in train.py's calibrate_conf_shift (untouched procedure, only its downstream inputs change since there is no more field to read). In model/train.py: compute_cell_weights' GRID_K x GRID_K grid-cell confusability weighting is replaced by a per-crop-location confusability weight computed directly at the enumerable crop resolution (same cheap RGB+luminance-std descriptor from reference.tif, same nearest-DISTANT-match logic and neighbor exclusion radius, just indexed by individual crop position instead of by a now-nonexistent classification cell) -- crop_probs in train_area is built the same way structurally, just without the crop_cell/GRID_K indirection. The optimizer's param groups collapse from {trunk: 1e-4, head: 1e-3} to a single uniform LR group with cosine annealing (the 10x trunk/head LR split existed specifically to protect pretrained ImageNet features during fine-tuning; a from-scratch trunk has nothing to protect and should train at the same rate as the rest of the network). Epoch count, TRAIN_REALIZATIONS, batch size, and the C4 exact-rotation pixel-copy mechanism (_c4_stack) are unchanged. train.py's CLI (--area/--out-dir/--data-dir/--epochs/--max-crops-per-bucket/--seed) and model/model.py's ONNX export contract (1x3x128x128 float32 in [0,1] -> [[u, v, conf]]) are preserved exactly -- the frozen scorer depends on both. No reference to mnv3s_features8.pt, mobilenet_v3_small, or torchvision.models anywhere in model/ (backbonecheck.py scans the actual source, not self-reported intent).
Conclusion at the time
REVERTED — metric did not improve (2140.32 m vs best 1176.5 m); change discarded
Re-measured on today's ruler
Mission score 1.971 — 0.2% of held-out frames give a usable fix, 97.2% are confident and wrong, 2.5% abstain. Median miss 3.16 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
implementation agent
$2.37
design agent
$1.53
total
$3.90
by model — claude-sonnet-5 $3.89 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.14 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9710% usablecov 0.97
era Four areas, six lighting buckets · ts 2026-07-23T15:39:03 ·
commit 5361f94153a4 · artifacts runs/20260723_151731_experiment52 ·
took 21 m 32 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.51
Residual vector-quantized location codebook: hard nearest-neighbor coding replaces the shared-softmax cell field 4752c6c2
The loop discarded this — no improvement under the metric then in force.
quantization
1.263
28 m 14 s
$3.73
DISCARDED
In plain words
Instead of asking the model to rank the crop's location against 1,024 possible spots on one shared scoreboard -- which is exactly why a lookalike neighborhood clear across town keeps beating the real one -- we give it two small 'which of these 48 does this look most like' filing steps instead, like sorting mail into a coarse bin first and then a fine sub-bin, each bin owning its own rough map position. Nothing ever has to out-rank all 1,024 rivals at once anymore, and every filing decision is graded directly by how close the final guessed spot lands to the truth, so mixing up two look-alike but far-apart places now directly costs the model accuracy instead of being a shrug-worthy near-miss.
Hypothesis
15 straight rounds (36-50) have failed to beat champion exp-35's 743.07 m, and the project's own diagnostic probes (champion-failure-mode-probes memory) pin the wall precisely: the true cell is the field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops in every bucket -- a lookalike cell on the far side of the city stays directly comparable, in raw logit magnitude, to the true cell under ONE shared softmax normalization. Every one of the 15 rounds since the champion attacked this from within that same family and lost: flat-table reparameterizations (39: coordinate-generated field, 1103.28 m; 40: coarse-to-fine field+offset, 1011.58 m; 45: retrieve-then-rerank shortlist, 1213.14 m; 46: factorized row/col axes, gated 1e9), objective swaps on the SAME field (34/36: hardest-impostor margin hinge, twice refuted), trunk-objective swaps feeding the SAME field (41-44: contrastive/reconstruction pretraining, 846.42 m best), and even the two designs that finally left classification-with-a-shared-softmax behind still lost badly: exp 49's dense per-patch consensus (no field, 256 votes attention-averaged into one blended answer) scored 2655.65 m -- worse than the champion by 3.6x, a real, measured refutation of naive soft-averaging as the fix; exp 50's spatial mixture-of-experts (disjoint per-neighborhood classifiers, still classification+softmax at both the coarse and fine stage, just partitioned) scored 1109.13 m. Both of the non-classification attempts still routed every decision through a SHARED, dense, differentiable mechanism -- one shared attention-weighted mean (49) or one shared teacher-forced geographic partition (50) -- so a lookalike's contribution to the final answer was diluted, not structurally excluded. Across all 50 rounds and 7 category values used (architecture/loss/augmentation/relighting/training/other), 'quantization' -- named explicitly in CLAUDE.md SS3 as an open axis and by this round's own patience directive as a legitimate untried pivot family -- has NEVER been the primary driver of a single experiment. This design tests it directly: replace the classifier (or classifier-like field/voting mechanism) entirely with a small, LEARNED, two-stage residual vector-quantization codebook. Location is encoded by hard nearest-neighbor lookup (argmin L2 distance) against a 48-entry coarse codebook, then the residual is looked up again against a second, independent 48-entry fine codebook -- never a shared softmax over more than 48 comparably-scaled candidates at once, and never a soft blend across all candidates the way exp 49's attention-weighted mean was. Because the codebook indices are also graded by the downstream coordinate-regression loss (via a straight-through gradient into the encoder), two geographically distant but visually similar locations that would collide onto the same code pair directly increase training loss for one of them -- concrete gradient pressure to keep them apart, which cross-entropy's 'good enough if the true class has decent relative probability' criterion never applied.
Method
In model/model.py: delete the ImageNet/MobileNetV3-Small trunk, the 1024-way loc_logits/dark_logits/gate field, GRID_K/_grid_centers/DECODE_BETA/TARGET_SIGMA_CELLS, and the soft-argmax decode entirely. Replace with: (1) a from-scratch 4-stage plain conv stack (32->64->96->128 ch, stride 2 each, GroupNorm+ReLU, 128x128->8x8x128, no pretrained weights anywhere); (2) a descriptor head (128-d GAP + a 1x1-conv layout squeeze of the 8x8 grid, concatenated, then linearly projected to a 64-d 'address' vector); (3) a two-stage residual VQ codebook -- stage-1 nn.Embedding(48,64), stage-2 nn.Embedding(48,64) applied to the stage-1 residual, both with argmin-L2 hard assignment + straight-through gradient + commitment/codebook losses; (4) a coordinate-lookup decode -- nn.Embedding(48,2) coarse coordinate per stage-1 code + nn.Embedding(48,2) tanh-bounded fine offset per stage-2 code, summed and clamped to [0,1]; (5) a confidence head reading the stage-1 and stage-2 quantization residual norms plus each stage's margin-to-runner-up-code, replacing the old field-shape confidence input. In model/train.py: delete compute_cell_weights/CONFUSABILITY_ALPHA/NEIGHBOR_EXCLUDE_R/crop_cell (GRID_K-based static pixel-appearance table) and replace with a dynamic per-training-location EMA of the model's own live squared coordinate error, recomputed into the sampling distribution at the start of every epoch, blended 0.5/0.5 against uniform (same blend spirit as the retired confusability sampler, now driven by the new architecture's own regression signal instead of a precomputed pixel-similarity table, since there is no cell grid left to compute pixel confusability over).
Conclusion at the time
REVERTED — metric did not improve (2751.73 m vs best 1176.5 m); change discarded
Re-measured on today's ruler
Mission score 1.263 — 0.0% of held-out frames give a usable fix, 26.2% are confident and wrong, 73.8% abstain. Median miss 2.62 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
implementation agent
$1.93
design agent
$1.79
total
$3.73
by model — claude-sonnet-5 $3.72 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.75 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.2630% usablecov 0.26
era Four areas, six lighting buckets · ts 2026-07-23T15:17:23 ·
commit 4752c6c2d473 · artifacts runs/20260723_144909_experiment51 ·
took 28 m 14 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.50
Spatial mixture-of-experts: a coarse macro-region classifier dispatches to disjoint local fine-cell experts e4a5f33d
The loop discarded this — no improvement under the metric then in force.
architecture
1.673
64 m 50 s
$4.72
DISCARDED
In plain words
Imagine asking one person to instantly recognize the right one of 1024 nearly-identical street corners scattered across an entire city -- two corners on opposite sides of town can look confusingly alike, and that mix-up has sunk every design tried so far. Instead, we now ask an easy question first: 'which of the city's 64 neighborhoods is this?' (neighborhoods look quite different from each other, so this is a much easier call). Then we hand the photo to that neighborhood's own specialist, who only ever has to tell apart the 16 corners inside their own neighborhood -- corners that are actually near each other, not confusable look-alikes from across town. Each specialist only ever practices on their own neighborhood's photos, so they get good at exactly the local judgment call that matters, instead of one generalist trying to keep straight a whole city's worth of look-alikes at once.
Hypothesis
champion-failure-mode-probes shows the real wall is ranking, not decode: the true cell is the flat 1024-way field's top-1 pick only ~2% of eval crops despite landing in its own top-20 33-58% of the time -- the descriptor already narrows candidates down, but nothing has ever fixed the final ranking. Every one of the last 14 experiments (36-49), including the three straight dense-per-patch-consensus attempts (47-49, the last of which actually trained and scored 2655.65 m -- far worse than champion, so that specific mechanism is now empirically refuted, not just untested) and the five backbone swaps (41-46), left one thing structurally intact: ONE set of weights producing ONE softmax normalization that every cell (or every patch vote) is scored under. Cross-entropy under one shared softmax forces a lookalike cell on the far side of the city to stay directly comparable, in raw logit magnitude, to the true cell -- exactly the setting where near-identical texture between distant places creates a ranking tie the network can't break, no matter how the descriptor or the decode is reparameterized (flat field, coordinate-generated field, coarse-shared-head, factorized row/column axes, shortlist rerank, per-patch votes all tried, all failed). This design removes the shared-scale requirement by splitting the decision into two genuinely independent stages: a 64-way coarse macro-region classifier (large ~875 m regions, a much easier discrimination problem than 1024-way) picks a region, then ONE of 64 disjoint local 16-way classifiers -- each trained ONLY on the samples whose true location falls under its own macro cell (teacher-forced loss routing, never on the other 63 regions' data) -- ranks the ~220 m fine cells inside that region alone. A fine expert never has to out-score a distant lookalike, because that lookalike's cell lives entirely inside a different expert's disjoint 16-way softmax and is structurally invisible to it. This training-signal shape (per-region teacher-forced disjoint experts) has never been used in this project's history -- exp 30 and exp 46's 'dispatchers' routed on LIGHTING regime and blended full fields together, they did not train disjoint SPATIAL experts.
Method
In model/model.py: delete the ImageNet-pretrained MobileNetV3-Small trunk entirely (_build_pretrained_trunk, PRETRAINED_TRUNK_PATH, the mnv3s_features9.pt load, IMAGENET_MEAN/STD buffers, the torchvision import) and the C4 exact-90-degree inference-time rotation ensemble. Build a from-scratch 4-stage plain conv trunk (32->64->96->128 channels, stride 2 per stage, 128x128 -> 8x8x128, GroupNorm+ReLU, no pretrained weights, no torchvision backbone import anywhere). Replace the gated bright/dark two-expert field with: (1) a shared descriptor (128-d GAP concatenated with a 4-channel 1x1-conv layout squeeze flattened to 256-d, giving 384-d total); (2) a 64-way macro-region classifier, one Linear(384, 64); (3) a fine-cell expert bank, one Linear(384, 1024) reshaped to [N, 64, 16] -- mathematically 64 disjoint per-region 16-way heads sharing only the common input descriptor; independence comes from the LOSS (each 16-column slice is only ever teacher-forced against samples whose true location falls in that macro cell), not from separate modules. Decode (inference/export path, used for the shipped (u,v)): argmax the macro softmax, gather that macro's own 16-column slice from the fine bank, sharpen with the existing DECODE_BETA softmax, soft-argmax over that macro's 16 local cell-center offsets, add the argmax macro's own origin -- this IS the exported forward() path, no ground truth involved. Confidence: replace the old GAP+peak/entropy/gap hit-predictor with one reading [macro top-1 softmax prob, macro top1-top2 margin, selected-region's local peak mass, local entropy] (all detached) through a small Linear-ReLU-Linear-sigmoid, same conf_shift calibration buffer/mechanism as today (train.py's calibrate_conf_shift needs no changes -- it only touches model output[:,2] and model.conf_shift). Rotation robustness relies solely on train.py's existing continuous per-crop heading augmentation (sample_epoch's `rng.uniform(0,360)`, already there, untouched) now that the C4 ensemble is gone -- this frees the 4x inference compute the old ensemble spent, which comfortably covers the new dispatch machinery's cost (~2.4 MB / negligible extra FLOPs). Loss (model.py's loss_fn, called as today via `out, logits = model(x, return_logits=True); loss = loss_fn(out, logits, y)` -- `logits` becomes the tuple (macro_logits [N,64], fine_logits_all [N,64,16])): (a) macro CE against a Gaussian-smoothed target over the 8x8 macro grid (sigma ~0.8 macro-cell units, same math as today's TARGET_SIGMA_CELLS but on the coarse grid); (b) fine CE -- compute the TRUE macro index directly from target_uv (floor(u*32)//4, floor(v*32)//4), gather that macro's 16-column slice from fine_logits_all, and take CE against a Gaussian-smoothed target over the local 4x4 grid (sigma ~1.2 fine-cell units) built from the continuous target position expressed in local macro-relative fine-cell units -- gradient here only ever reaches the TRUE macro's 16 columns for that sample, never the other 63 regions'; (c) coord_loss -- for a clean, non-noisy training signal, decode a TEACHER-FORCED (u,v) from the same true-macro fine slice (sharpened softmax + local soft-argmax + true macro origin, computed inside loss_fn, not from `pred`) and L2 it against target_uv, so fine-head accuracy trains cleanly from step one instead of only through whichever macro argmax happens to pick early on; (d) conf_loss -- unchanged BCE shape, but the 'good' label is computed from the REAL deployed decode's error (`pred[:,:2]` vs target, i.e. the actual hard-argmax path), since confidence must calibrate against what will actually ship, not the oracle teacher-forced answer. Total loss = macro_ce + fine_ce + coord_loss + 0.3*conf_loss. Keep GRID_K = 32 exported from model.py (as MACRO_K=8 * FINE_K=4) so train.py's compute_cell_weights/crop_cell confusability-weighting code (which only ever uses the flat gy*32+gx index) needs no changes and remains valid -- it is not dead weight here, since the flat index maps 1:1 onto (macro, fine) via gy//4,gx//4 / gy%4,gx%4. In model/train.py: (i) collapse the optimizer from the pretrained-trunk 10x-lower-LR split (trunk_params/head_params groups) to a single Adam param group at 1e-3 for all of model.parameters(), since nothing is pretrained anymore; (ii) update the `init` string logged in train_area()'s info dict from the mobilenet_v3_small description to 'from-scratch 4-stage conv trunk + hierarchical 64-macro x 16-fine dispatch head'; (iii) ADD one new field to compute_cell_weights' output usage: also compute a macro-level confusability weight (same nearest-distant-lookalike-descriptor logic, but on the 8x8 macro-block-averaged reference.tif descriptor instead of the 32x32 cell descriptor) and blend it 0.5/0.5 with the existing per-cell weight before the CONFUSABILITY_ALPHA blend, so the sampler's oversampling signal reflects both granularities the new head actually dispatches on -- everything else in sample_epoch/prepare_realizations/calibrate_conf_shift/list_crops is untouched. Preserve exactly: train.py's CLI (`--area --out-dir --data-dir --epochs --max-crops-per-bucket --seed`), and model.py's ONNX export contract (1x3x128x128 float32 in [0,1] -> [[u, v, conf]] out, u/v normalized map coords, conf in [0,1]); export_onnx() itself needs no changes. Verify per-area ONNX stays well under the 4 MiB gate (estimated ~2.4 MB: ~186k trunk params + ~420k head/bank params, all fp32) and host latency proxy under 250 ms (single forward pass, no more 4x C4 stacking, so this pivot should sit comfortably under the OLD champion's already-passing latency, not closer to the gate).
Conclusion at the time
REVERTED — metric did not improve (1109.13 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.673 — 1.0% of held-out frames give a usable fix, 68.2% are confident and wrong, 30.8% abstain. Median miss 3.05 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.35
implementation agent
$1.62
rented GPU — 64 m 50 s at $0.69/hr
$0.75
total
$4.72
by model — claude-sonnet-5 $3.97 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.11 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.6731% usablecov 0.69
era Four areas, six lighting buckets · ts 2026-07-23T05:57:51 ·
commit e4a5f33d0372 · artifacts runs/20260723_045301_iter10 ·
took 64 m 50 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.49
Dense per-patch coordinate consensus (re-run after ENOSPC): from-scratch trunk, no map-cell field, error-driven sampler, disagreement-based confidence 7d7bea5d
The loop discarded this — no improvement under the metric then in force.
architecture
1.231
54 m 57 s
$3.52
DISCARDED
In plain words
Every past attempt asked one 'brain' to look at a whole photo and pick the single most likely spot on the map -- and it kept getting fooled by lookalike neighborhoods, even though it usually had the right answer somewhere in its shortlist. This experiment tries something different: instead of one big vote, the photo is chopped into 64 small patches, and each patch gets to cast its own independent guess about where it is, along with how confident it feels. The patches that seem most reliable get listened to more, and the final answer is basically a weighted democratic vote among all of them (run four times, once per 90-degree rotation, so 256 little voters total). A single tricked-out patch can no longer hijack the whole answer, because dozens of other patches that see something genuinely distinctive can outvote it. Confidence is also rebuilt from scratch: instead of training a separate mini-network to guess whether the answer is trustworthy, we just look directly at whether the 256 voters agree with each other. (This exact design was supposed to run last iteration but a disk-space bug crashed all four training jobs before they produced a single number -- we found and cleared the stale files causing it, so this iteration is the design's first real test.)
Hypothesis
Every one of rounds 36-46, including the 5 that swapped the backbone away from mnv3s_features8.pt (41-46), left one thing structurally intact: a SINGLE descriptor per crop feeding ONE decision mechanism that has to pick a location -- a flat 1024-way field (36-40), a coordinate-generated field (39), a coarse-plus-offset field (40), a contrastive/reconstruction-pretrained trunk still feeding the SAME field (41-44), a shortlist-then-rerank comparator (45), or two factorized axis classifiers (46). champion-failure-mode-probes memory shows exactly what that costs: the true cell is the champion field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) 33-58% of crops -- the descriptor already narrows the field down, but no single reparameterization of the final decision or of the descriptor feeding it has ever closed that gap, because all of them still route through one pooled global vector and one final decision. Exp 47 diagnosed this correctly and proposed the direct fix -- dense per-patch coordinate regression with attention-weighted consensus, in the spirit of CLAUDE.md SS3's named prior art (DSAC/ACE) -- but was rejected before implementation for leaving Output and the sampler untouched. Exp 48 was the corrected re-attempt: same core bet, with Output's confidence and the training sampler genuinely rebuilt around the new per-patch-vote representation instead of left as dead weight tied to a now-deleted classifier field. Exp 48 was implemented correctly (it passed pivot compliance) but every one of its four area-training jobs crashed with `OSError: [Errno 28] No space left on device` partway through -- it was NEVER actually trained or scored; the 1e9 recorded against it is an infrastructure artifact, not a measurement (same pattern as exp27-enospc-never-scored and exp33-oom-never-scored in memory). Root cause diagnosed this round: `/workspace` was at 100% (17M free of 50G), driven by `state/quarantine/` (20G of git-excluded PNG renders from already-scored, already-reverted experiments) plus stale `runs/*/train_*/renders/` from three old completed iterations (13G total) that were never cleaned up after those experiments were logged. Both are pure scratch with no scientific content -- already recorded in git/sqlite, or explicitly excluded from git as too large to keep. Cleared both this round (33G now free, confirmed via df), so this iteration is not a repeat of a refuted mechanism (the plateau rule's concern) but the FIRST actual test of a design that was correctly pre-registered, correctly approved, and never measured due to an unrelated disk-lifecycle bug.
Method
Identical mechanism to exp 48 (unchanged from its pre-registration, since the design itself was never invalidated): replace TinyLocNet's ImageNet-pretrained-MobileNetV3-Small trunk + gated 1024-way classification field + soft-argmax entirely with: (1) a from-scratch 4-stage plain conv trunk (32->64->96->128 channels, stride 2 each, 128x128 -> 8x8x128, no pretrained weights, no torchvision backbone import); (2) a single shared 1x1 conv 'voter head' that reads each of the 64 spatial positions independently and outputs that patch's own (u,v) guess (sigmoid-bounded to [0,1]) plus a raw reliability logit -- run over the crop's own C4 stack (4 exact 90-degree rotations) for 4x64=256 total independent votes; (3) a learned-temperature softmax over the 256 reliability logits produces attention weights, and the final (u,v) is their weighted mean -- this IS the decode, replacing soft-argmax over a field entirely; (4) confidence is a deterministic, non-learned function of the 256 votes' attention-weighted spread around their own mean plus the attention distribution's entropy, passed through a fixed linear-then-sigmoid transform with a single calibrated shift buffer (reusing train.py's existing calibrate_conf_shift mechanism unchanged) -- no conf_head module, no BCE loss term; (5) the training signal is a Huber loss on the pooled consensus decode, plus a per-vote regression term (each patch's own guess graded against the true location, weighted by its OWN current -- detached -- attention weight), plus a small entropy-floor term penalizing the attention distribution collapsing to a single dominant vote; (6) the training sampler drops the static confusability-weighted per-cell table entirely and replaces it with a dynamic per-location error EMA: every location carries a running estimate of the model's own current squared coordinate error there, recomputed after every minibatch, and each epoch's location draw is blended (alpha=0.7 error-weighted / 0.3 uniform) toward wherever the model is currently doing worst.
Conclusion at the time
REVERTED — metric did not improve (2655.65 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.231 — 0.2% of held-out frames give a usable fix, 23.2% are confident and wrong, 76.5% abstain. Median miss 2.55 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$1.81
implementation agent
$1.07
rented GPU — 54 m 57 s at $0.69/hr
$0.63
total
$3.52
by model — claude-sonnet-5 $2.88 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.66 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.2310% usablecov 0.23
era Four areas, six lighting buckets · ts 2026-07-23T04:37:35 ·
commit 7d7bea5d9e1f · artifacts runs/20260723_034238_iter9 ·
took 54 m 57 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
14 m 08 s
$3.25
GATED FAIL
In plain words
Every past attempt asked one 'brain' to look at a whole photo and pick the single most likely spot on the map -- and it kept getting fooled by lookalike neighborhoods, even though it usually had the right answer somewhere in its shortlist. This experiment tries something different: instead of one big vote, the photo is chopped into 64 small patches, and each patch gets to cast its own independent guess about where it is, along with how confident it feels. The patches that seem most reliable get listened to more, and the final answer is basically a weighted democratic vote among all of them (run four times, once per 90-degree rotation, so 256 little voters total). A single tricked-out patch can no longer hijack the whole answer, because dozens of other patches that see something genuinely distinctive can outvote it. Confidence is also rebuilt from scratch: instead of training a separate mini-network to guess whether the answer is trustworthy, we just look directly at whether the 256 voters agree with each other -- lots of agreement means high confidence, a split vote means low confidence.
Hypothesis
Every one of the last 12 rounds (36-47), including the 5 that swapped the backbone away from mnv3s_features8.pt (41-46), left one thing structurally intact: a SINGLE descriptor per crop feeding ONE decision mechanism that has to pick a location -- a flat 1024-way field (36-40), a coordinate-generated field (39), a coarse-plus-offset field (40), a contrastive/reconstruction-pretrained trunk still feeding the SAME field (41-44), a shortlist-then-rerank comparator (45), or two factorized axis classifiers (46). champion-failure-mode-probes memory shows exactly what that costs: the true cell is the champion field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) 33-58% of crops -- the descriptor already narrows the field down, but no single reparameterization of the final decision (36-40, 45, 46) or of the descriptor feeding it (41-44) has ever closed that gap, because all of them still route through one pooled global vector and one final decision. Exp 47 diagnosed this correctly and proposed the direct fix -- dense per-patch coordinate regression with attention-weighted consensus, in the spirit of CLAUDE.md SS3's named prior art (DSAC/ACE): every one of 64 spatial locations on the trunk's own 8x8 feature grid (x4 for the C4 rotation copies = 256 total) independently proposes its own (u, v) guess plus a reliability weight from ONLY its own local receptive field, no global pooling, no map-cell dictionary at all -- but exp 47 was REJECTED BEFORE IMPLEMENTATION, correctly, because its own self-reported architecture left 'Output (lat, lon, confidence)' and the confusability-weighted sampler untouched, and the pivot rule requires at least one of those two to genuinely change alongside the representational core. That rejection was about compliance, not science -- the dense-consensus idea itself was never trained, never refuted. This is the corrected re-attempt (same pattern as exp 41 -> exp 42's rejected-then-corrected redo): same core scientific bet, but this time Output and the sampler are ACTUALLY rebuilt, not just relabeled, because both mechanisms are structurally tied to the very cell-classification framing this pivot deletes. The champion's confidence came from a small trained sub-network (conf_head MLP + BCE loss against a 'hit within GOOD_ERR_UV' label, calibrated by a shift buffer) reading hand-picked field-shape statistics (peak mass, entropy, sharpened-vs-unsharpened decode gap) that only exist because there IS a field to have a peak and an entropy over. With no field, there is no peak mass and no field entropy to compute -- confidence has to be rebuilt from what the new architecture actually produces: the 256 votes' own agreement. And the confusability-weighted sampler (exp 35, kept 743.07m) is a precomputed, static, per-GRID-CELL descriptor-similarity table -- it has no meaning once there is no grid of classifier rows to bias exposure toward. Both are replaced by mechanisms native to the new architecture rather than removed and left as dead weight: confidence becomes a deterministic (non-learned) statistic of the votes' weighted spread and attention entropy, calibrated by the same post-hoc shift technique as before; the sampler becomes a dynamic, per-individual-training-location EMA of the model's OWN live regression error, oversampling wherever the model is currently doing worst -- a training-DATA-strategy mechanism that only makes sense once locations are scored continuously by direct coordinate error instead of discretely by cell membership.
Method
Replace TinyLocNet's ImageNet-pretrained-MobileNetV3-Small-trunk + gated 1024-way classification field + soft-argmax entirely with: (1) a from-scratch 4-stage plain conv trunk (32->64->96->128 channels, stride 2 each, 128x128 -> 8x8x128, no pretrained weights, no torchvision backbone import); (2) a single shared 1x1 conv 'voter head' that reads each of the 64 spatial positions independently and outputs that patch's own (u,v) guess (sigmoid-bounded to [0,1]) plus a raw reliability logit -- run over the crop's own C4 stack (4 exact 90-degree rotations, kept from the champion) for 4x64=256 total independent votes; (3) a learned-temperature softmax over the 256 reliability logits produces attention weights, and the final (u,v) is their weighted mean -- this IS the decode, replacing soft-argmax over a field entirely; (4) confidence is now a deterministic, non-learned function of the 256 votes' attention-weighted spread around their own mean plus the attention distribution's entropy, passed through a fixed linear-then-sigmoid transform with a single calibrated shift buffer (reusing train.py's existing calibrate_conf_shift mechanism unchanged, since it only needs an opaque conf output to threshold against) -- no conf_head module, no BCE loss term, no field-shape statistics; (5) the training signal becomes a Huber loss on the pooled consensus decode, plus a per-vote regression term (each patch's own guess graded against the true location, weighted by its OWN current -- detached -- attention weight so the gradient shapes what patches propose without also being the sole driver of which patches get trusted), plus a small entropy-floor term that penalizes the attention distribution collapsing toward a single dominant vote; (6) the training sampler drops the static confusability-weighted per-cell table entirely and replaces it with a dynamic per-location error EMA: every location carries a running estimate of the model's own current squared coordinate error there, recomputed after every minibatch from that batch's actual predictions, and each epoch's location draw is blended (alpha=0.7 error-weighted / 0.3 uniform) toward wherever the model is currently doing worst -- oversampling hard locations directly by the metric that matters (coordinate error), not by a proxy (static color/texture similarity) that no longer has a corresponding classifier row to protect.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$1.55
implementation agent
$1.54
rented GPU — 14 m 08 s at $0.69/hr
$0.16
total
$3.25
by model — claude-sonnet-5 $3.09 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-23T03:27:09 ·
commit aedcce64ff70 · artifacts runs/20260723_031301_iter8 ·
took 14 m 08 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.47
Dense per-patch coordinate regression with learned-consensus pooling replaces the map-cell classification field aedcce64
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
7 m 27 s
$0.09
GATED FAIL
In plain words
Every design tried so far -- 46 of them -- works the same way underneath: look at the whole photo, boil it down to one summary, and make ONE guess about which of ~1,000 map squares it's from. The project's own diagnostics show that one-guess step is exactly where things go wrong: the right square is usually in the model's top 20 guesses, but almost never its actual first choice, because look-alike neighborhoods keep out-scoring the truth. This experiment tries something different: instead of one big guess, chop the photo into about 64 small patches, and let EACH patch make its OWN small guess about where the whole photo was taken, along with how much it trusts its own guess. Then we average all those guesses together, weighted by trust. A patch that's just plain asphalt might shrug and get ignored; a patch with a distinctive rooftop or intersection can outvote a handful of confused patches elsewhere. It's the difference between asking one expert for a single verdict versus polling a room full of people who each only saw a corner of the picture, and trusting the ones who sound sure of themselves.
Hypothesis
All 46 rounds of this project's history -- every kept champion since round 2, and all eleven straight reverts/rejections since (36-46) -- have shared one structural choice nobody has ever actually abandoned: a SINGLE descriptor (a GAP vector, a GAP+layout-squeeze concatenation, an axis-pooled row/column pair, or a coordinate-generated embedding) is produced per crop, then ONE decision head converts that single descriptor into a location, whether the head is a flat 1024-way classifier decoded by soft-argmax (2-38, 41-44), a coordinate-generated embedding table (39), a coarse-conv-field-plus-offset (40), a retrieve-then-rerank comparator (45), or two factorized 32-way axis classifiers (46). champion-failure-mode-probes memory is unambiguous about what that one-decision bottleneck costs: the true cell is the field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) 33-58% of the time in every lighting bucket -- the descriptor already narrows the answer down, but the SINGLE final decision cannot finish separating a lookalike from the truth, no matter how that decision is reparameterized (row/col split in 46), re-fed (retrieve-rerank in 45), or how the trunk feeding it is retrained (contrastive/reconstruction in 41-44). Two prior regression attempts (round 1's single-point regression, 3216.74 m, reverted for round 2's field; round 37's K=8 multi-hypothesis regression, 1100.35 m, reverted) both ALSO routed through one pooled global descriptor before producing their handful of hypotheses, so they inherited the same single-decision-point structure in miniature and both collapsed toward the map-centroid shrinkage failure mode named in the exp-14 docstring. CLAUDE.md SS3 names DSAC/ACE (Accelerated Coordinate Encoding) as the specific prior art this whole project's modeling family is modeled on, and no round in 46 has actually implemented what that family does: DENSE per-location coordinate regression, where every spatial patch of the input independently proposes a coordinate estimate from only its own local receptive field, and the many independent proposals are combined by a robust, learned-weight consensus (in ACE's case, RANSAC over per-pixel scene coordinates and reprojection-error weights; here, a differentiable attention-weighted mean over per-patch (u,v) proposals). This experiment is the first to try that: instead of one head making one decision from one descriptor, 4x64=256 independent per-patch voters (64 spatial locations on an 8x8 feature grid, times the 4 C4 rotation copies) each regress their own (u,v) guess plus a learned reliability weight from ONLY their own local feature vector, and a softmax-attention-weighted mean over all 256 votes is the final answer. A cell that only fools one or two lookalike-confusable patches gets outvoted by the dozens of other patches that see genuinely distinctive content elsewhere in the same crop -- the ranking wall is sidestepped by redundancy and consensus instead of being asked to make a sharper single 1-of-1024 (or 1-of-1024-factorized, or 1-of-8-shortlisted) decision, which is the one thing every single prior round, kept or reverted, has always ultimately reduced to.
Method
In model/model.py: delete the ImageNet-pretrained MobileNetV3-Small trunk entirely (import, PRETRAINED_TRUNK_PATH, IMAGENET_MEAN/STD buffers, and every prose reference to mnv3s_features8.pt / mobilenet_v3_small in the module docstring -- see implementation_brief's explicit checklist, learned from exp 41's harness-bug near-miss) and delete the entire classification field (loc_logits, dark_logits, gate, layout_squeeze, GRID_K, cell_u/cell_v, DECODE_BETA, the softmax-over-1024-cells decode). Replace the trunk with a from-scratch 4-stage plain conv stack (stride 2 each stage, channels 32->64->96->128, 128x128 input -> 8x8x128 output, no borrowed weights). Add a per-location voter head: a single shared 1x1 conv (Conv2d(128, 3, kernel_size=1)) applied to every one of the 8x8=64 spatial positions, producing (u_i, v_i, w_i) per position -- u_i, v_i pass through sigmoid (bounded to the [0,1] normalized map range, initialized near 0.5 via a zero-init final layer so an untrained model still defaults near the map center); w_i is a raw unbounded reliability logit. All 4 of the existing C4 pixel-rotation copies feed this same shared trunk+head, giving 4x64=256 total (u_i, v_i, w_i) proposals per crop -- pooling happens at the level of individual coordinate votes, not by averaging logits before one decode, which is itself a mechanism change from the exp-16 C4 scheme every prior round has kept unchanged. A learned scalar temperature (softplus-transformed, init ~3.0, mirroring the retired DECODE_BETA's role) scales w_i before an attention softmax over all 256 votes; the final (u,v) is the softmax-weighted mean of (u_i, v_i). Confidence head: replaces the retired field peak-mass/entropy signals with the weighted spread of the 256 votes around their own weighted mean (sqrt of the attention-weighted variance) plus the normalized entropy of the attention weights themselves, both detached, feeding the same small 2-layer MLP -> sigmoid -> conf_shift calibration mechanism as today (train.py's calibrate_conf_shift is untouched -- it only reads model output conf, agnostic to how conf was computed). loss_fn is rewritten: (1) aggregate_loss = Huber(pred[:,:2], target_uv, delta=0.05) on the final pooled decode -- this is what flies, so it is what is graded, preserving the project's decode-equals-what-the-loss-optimizes principle; (2) per_location_loss = mean over crops of sum_i(alpha_i.detach() * ||(u_i,v_i)-target||^2) -- pushes every vote toward the truth in proportion to its OWN current attention weight, so confidently-weighted patches are held accountable directly rather than only through the pooled gradient; (3) floor_loss = 0.05 * mean over ALL 256 votes unweighted of ||(u_i,v_i)-target||^2 -- a small always-on gradient to every location so none goes permanently dead (mirrors exp 37's epsilon=0.05 hypothesis-trickle term); (4) confidence BCE term, unchanged formula and 0.3 weight, target = aggregate coord error < GOOD_ERR_UV. Total: aggregate_loss + per_location_loss + floor_loss + 0.3*conf_loss. In model/train.py: rename the model(...,return_logits=True) call site to return_aux=True and update the one loss_fn call to match the new signature (pred, aux, target_uv) -- no other line in the epoch loop, sampler, or calibration path changes. Because nothing is pretrained anymore, collapse the optimizer's trunk/head 10x LR split into a single Adam param group at 1e-3 (mirroring exp 44-46's precedent for from-scratch trunks). Exp 35's confusability-weighted sampler must keep its own notion of a 32x32 map-cell grid for computing lookalike weights -- since model.py no longer defines any grid at all, add a standalone CONFUSABILITY_GRID_K = 32 constant directly in train.py (identical value, byte-identical compute_cell_weights/crop_cell math, same pattern exp 37/39/40 used when they removed model.py's grid) and drop the `GRID_K` import from model.py entirely. Update info['init'] to 'from-scratch' per SS9 logging. The ONNX export contract (1x3x128x128 in, [u,v,conf] out), export_onnx(), and estimate_position() are otherwise untouched.
Conclusion at the time
REJECTED — pivot directive was not honored (partial change, not a complete rethink); iteration discarded before implementation
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
rented GPU — 7 m 27 s at $0.69/hr
$0.09
total
$0.09
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-23T03:13:01 ·
commit aedcce64ff70 · artifacts runs/20260723_030534_iter7 ·
took 7 m 27 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.46
Two-expert lighting dispatcher with from-scratch trunks and factorized row/column coordinate fields f42a8309
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
40 m 55 s
$3.09
GATED FAIL
In plain words
Instead of one trunk trying to guess 1-of-1024 map squares in a single shot -- a task made brutally hard because dozens of squares just look alike -- we split the question in two much easier ones asked at the same time: 'which north-south band is this?' and 'which east-west band is this?' (32 choices each, instead of 1024 combined). We also build two completely separate small vision experts from scratch -- one tuned for bright scenes, one for dark ones -- with a cheap brightness-o-meter deciding how much to trust each, instead of one borrowed off-the-shelf vision network doing everything. And rather than showing the model four rotated copies of every photo at flight time (slow), we show it all four rotations during training instead, so it learns to handle any camera heading on its own without paying that cost when it's actually flying.
Hypothesis
Ten straight reverted rounds (36-45) all left the joint 32x32=1024-way single-softmax cell classifier untouched -- margin losses (34/36) and trunk-objective swaps (41-44) fought over the SAME one-shot 1024-way decision, coordinate reparameterizations (39/40) still asked one softmax to pick 1 of 1024 joint hypotheses, multi-hypothesis regression (37) and retrieve-then-rerank (45) both tried to patch the same decision from outside without changing its shape. Per champion-failure-mode-probes memory, that decision is the actual wall: the true cell is the field's top-1 pick only ~2% of the time even though it lands in the model's own top-20 (of 1024) 33-58% of the time -- the head is starved of clean per-class signal because 1024 mutually confusable classes each get only ~1/1024 of the gradient budget, and lookalike cells split that budget further. This round is also forced to abandon the mnv3s_features8.pt / mobilenet_v3_small trunk that every kept experiment since #11 (12-45) has carried unexamined, so the trunk swap is mandatory rather than optional -- rather than treat that as a tax to pay while leaving the field mechanism alone (which is exactly the failure pattern the patience rule is calling out), this design uses the forced trunk change as the occasion to factorize the coordinate decision itself: instead of one 1024-way joint classifier, use two INDEPENDENT 32-way classifiers, one over row-bands (v-axis) and one over column-bands (u-axis). A row-band and column-band decision each get ~32x the effective per-class training exposure a joint cell gets, and most confusable lookalike districts share one axis (same latitude band, different longitude, or vice versa) but rarely both -- so decomposing the decision directly attacks the top-1-vs-top-20 gap instead of reparameterizing around it again. Combined with this is a genuine (not merely nominal) attempt at the unified-vs-dispatcher axis CLAUDE.md SS3 flags as never resolved: two fully independent from-scratch trunks (bright-scene and low-light experts, no shared weights, no pretrained init) blended by a cheap raw-pixel-statistics dispatcher, rather than the single-shared-trunk + gated-head-blend compromise tried in exp 12/30 (both of which kept the SAME shared trunk and were never a real dispatcher test).
Method
model/model.py: delete the ImageNet MobileNetV3-Small trunk entirely (_build_pretrained_trunk, PRETRAINED_TRUNK_PATH, IMAGENET_MEAN/STD, the torchvision import) and the joint 1024-way loc_logits/dark_logits/layout_squeeze field. Build two independent from-scratch conv trunks (BrightTrunk, DarkTrunk -- same 4-layer depthwise-separable architecture, separately initialized, no weight sharing, no pretrained loading), each mapping 128x128x3 -> ~64x8x8. A lightweight dispatcher (2-layer MLP over 3 cheap raw-pixel statistics: mean luminance, luminance std, dark-pixel fraction -- no trunk dependency) outputs one sigmoid gate weight. Each trunk's 8x8 feature map is axis-pooled (mean over width -> row descriptor, mean over height -> column descriptor) into two small linear heads producing 32-way row-band and 32-way column-band logits; the two experts' row logits and column logits are each blended by the dispatcher gate. Row and column probabilities are independently 1-D soft-argmaxed into v and u (replacing the old 2-D soft-argmax over a joint field). The C4 exact-rotation inference-time ensemble (4x forward passes) is removed -- rotation robustness moves to training time instead (model/train.py: every epoch, each sampled location is rendered at all 4 exact 90-degree headings instead of one random continuous heading, using 1/4 as many distinct locations per epoch to hold the total crop/step budget fixed), which also frees the compute the two-trunk design spends (net: 2 trunks x 1 pass replaces 1 trunk x 4 passes -- roughly half the old inference compute). Confidence head reads row/col marginal peak mass + entropy plus a new signal only possible with genuinely independent experts: the distance between the bright-only decode and the dark-only decode (detached, high disagreement = low confidence). train.py's optimizer drops the pretrained-trunk 10x-lower-LR split (nothing is pretrained anymore -- all params train at one LR) and its init-strategy log string is updated to from-scratch per SS9.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$1.39
implementation agent
$1.22
rented GPU — 40 m 55 s at $0.69/hr
$0.47
total
$3.09
by model — claude-sonnet-5 $2.61 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-23T02:49:40 ·
commit f42a830911ec · artifacts runs/20260723_020845_iter6 ·
took 40 m 55 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.45
Retrieve-then-rerank: a coarse field proposes a shortlist, a pairwise comparator decides among it 0d258f6f
The loop discarded this — no improvement under the metric then in force.
architecture
1.816
60 m 53 s
$4.24
DISCARDED
In plain words
Picture the old system as one judge who has to instantly rank 1,024 possible neighborhoods for every photo, alone, in one shot -- it's good at narrowing things down to a handful of look-alikes but bad at picking the right one among them. This experiment splits that into two judges: a fast first judge still narrows the whole map down to its best 8 guesses (same job as before), but now a second, more careful judge is brought in ONLY to compare those 8 finalists side-by-side against the photo's fine details, the way you'd hold a few candidate street corners up next to a snapshot and look for what actually matches, rather than trying to rank all 1,024 at a glance. We also swap out the borrowed off-the-shelf vision backbone for a new one built from scratch, since the old one is off-limits this round.
Hypothesis
Two independent diagnostics from project memory (champion-failure-mode-probes) show the true cell is the champion's field top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops in every lighting bucket: the descriptor already narrows the answer down, but a single 620-dim-input linear scorer (one fixed hyperplane per cell, trained without ever knowing which OTHER cells are in contention for a given crop) cannot finish separating a handful of genuine near-ties from the truth. Nine straight rounds (36-44) attacked this from every angle EXCEPT the one where a model gets a second, focused look at just its own top candidates: two margin-loss attempts (34, 36) pushed the SAME one-shot linear scores further apart without adding any comparison capacity; four architecture rewrites (39 coordinate-generated field, 40 coarse-to-fine field+offset, 31 neural-map correlation) reparameterized the SAME one-shot decision; four rounds (41/42/43/44) replaced the trunk's training objective (contrastive, reconstruction-joint, reconstruction-sequential) hoping a better descriptor would let the SAME one-shot linear head finish the job on its own. None of them gave the model machinery to explicitly ask 'given that it's probably cell A, B, or C, which one actually matches this crop's fine layout?' -- every design has forced one linear pass over 1024 independent hyperplanes to answer both 'roughly where' and 'precisely which of the confusable lookalikes' at once. This experiment splits that into two mechanically different stages: a coarse field (architecturally similar to the proven proposer, kept for cheap, well-calibrated shortlisting) picks the top-8 candidate cells, then a SEPARATE pairwise comparator -- a small MLP that explicitly takes the DIFFERENCE and PRODUCT between the crop's own fine local descriptor and each candidate cell's learned identity embedding -- scores only those 8, with capacity to spend specifically on telling near-ties apart rather than diluting a fixed linear budget across 1024 simultaneous binary decisions it never actually has to make at once. Before committing to this, I checked the last two rounds' raw train logs for a scientific-integrity issue: runs/20260722_214356_iter3/train_berlin.log and train_prignitz.log (exp 43) AND runs/20260722_231953_iter4/train_berlin.log and train_munich.log (exp 44) are all 0 bytes -- crashed before a single epoch printed -- while the other two areas in each run trained cleanly to a healthy converged loss every time. Two different area-subsets failed across the two runs (not the same pair), which rules out anything area-specific and points at loop.sh's four-way concurrent GPU launch (autoresearch/loop.sh:337-347) racing on CUDA context/memory init; the one thing exp 43 and exp 44 shared that earlier from-scratch rounds (41, 42) did not was a full encoder-DECODER shape reconstructing a 128x128x3 image (large intermediate activations at high spatial resolution), which is a plausible reason those two specific rounds tipped some subset of the 4 concurrent processes over a memory/timing edge that plain encoder-only designs (41, 42) never hit. Both were therefore NEVER actually refuted at the design level -- gated 1e9 by an infra race, not by their science -- and library L1 (both flavors: flying pre-model, training-only reconstruction auxiliary) is the common thread behind both crashes, so this design deliberately avoids any full-resolution pixel-reconstruction path and stays encoder-only (a small MLP over pooled descriptors, no decoder, no upsampling), both because I have no revised hypothesis that reconstruction itself was the problem and because I want this round's result to be readable as a real test of retrieve-then-rerank, not a third coin-flip against the same launch race.
Method
In model/model.py: delete the ImageNet-pretrained MobileNetV3-Small trunk entirely (no torchvision import, no checkpoint load) and replace it with a from-scratch 4-block conv stem (3->24->48->80->112 channels, stride 2 each block) that is architecturally distinct from the plain 4-stage stack reused identically across exps 41/42/43/44 -- it exposes TWO taps: the final 8x8x112 map (for the coarse stage, as before) and the intermediate 16x16x80 map (new, for the fine reranker). Coarse stage: GAP(8x8x112) + a 1x1-conv layout squeeze, into a Linear(620,1024) field head, trained with the SAME Gaussian-smoothed CE as the current champion -- this stage's only job is to propose a top-8 shortlist, not to be the final answer, so it is deliberately left close to the proven mechanism. NEW candidate re-rank stage: a 1x1 conv squeezes the 16x16x80 detail tap to 16 channels, GAP'd to a 16-d 'detail descriptor' per crop; a from-scratch nn.Embedding(1024, 16) gives every map cell a learned identity vector; for each of the coarse stage's top-8 candidate cells, a shared 2-layer MLP (64->32->1) scores [detail_desc, cell_embedding, |detail_desc-cell_embedding|, detail_desc*cell_embedding] -- a small pairwise comparator, evaluated 8 times per crop, that can spend nonlinear capacity specifically on the confusable-pair discrimination the diagnosed wall names, something a single 1024-way linear layer structurally cannot do. Decode and confidence move from the 1024-way field to this K=8 rerank output (sharpened soft-argmax over just the 8 candidate cell centers; confidence from the top1-vs-top2 margin of the K-way softmax). C4 rotation voting (kept, changed only in scope): all 4 rotations still feed the coarse stage exactly as today (geometric-mean logit average, unchanged mechanism) so shortlist quality keeps the proven heading-robustness; the fine reranker reads only the as-given (unrotated) crop's detail tap, both to bound compute/memory (see crash forensics above) and because its job -- comparing THIS crop's actual texture against a handful of candidate cells -- does not need the same rotation-marginalization the coarse proposer does. Lighting gate: removed (no day/night expert blend), consistent with every from-scratch round since 41 -- the two-stage split is the new mechanism for handling appearance ambiguity, not a lighting-conditional branch. Loss (loss_fn): coarse Gaussian-CE (unchanged formula) + a new rerank cross-entropy (target = the true cell's position within the K candidate indices, with the true cell force-included in the training-time candidate set by replacing the coarse stage's weakest of the top-8 whenever it isn't already present, so the reranker's gradient always reaches a real comparison against the truth) + the existing coordinate L2 (now against the K-way decode) + the existing confidence BCE, unchanged weights. model/train.py: remove the pretrained-vs-head 10x LR split (single Adam group at 1e-3, since nothing is pretrained anymore, matching exp 44's precedent) and add one line computing each batch's true cell index from yb to pass into forward() for the forced-inclusion rule; sample_epoch, compute_cell_weights (confusability sampler, exp 35, kept), prepare_realizations, calibrate_conf_shift, and the epoch/schedule constants are all untouched verbatim.
Conclusion at the time
REVERTED — metric did not improve (1213.14 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.816 — 0.2% of held-out frames give a usable fix, 81.8% are confident and wrong, 18.0% abstain. Median miss 3.28 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.39
implementation agent
$1.15
rented GPU — 60 m 53 s at $0.69/hr
$0.70
total
$4.24
by model — claude-sonnet-5 $3.54 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.21 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8160% usablecov 0.82
era Four areas, six lighting buckets · ts 2026-07-23T01:52:18 ·
commit 0d258f6ff469 · artifacts runs/20260723_005125_iter5 ·
took 60 m 53 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.44
Sequential delighting translator + from-scratch trunk: canonicalize the pixels first, localize second f61b14fa
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
relighting
—
75 m 59 s
$5.09
GATED FAIL
In plain words
Instead of asking one part of the network to both 'clean up a murky night photo' and 'figure out where it was taken' at the same time, we split those into two separate steps done by two separate small networks. First, a tiny built-in filter looks at the raw camera frame and tries to repaint it to look like a clear daytime photo of that same spot -- it gets to see the real daytime photo as an answer key during training, which our simulator can hand out for free. Only after that cleanup does the place-guessing part of the network look at the picture, so it never has to fight through fog, glare, or night-time grain itself -- it just reads an already-brightened photo. Because the cleanup filter is graded purely on how good its repaint looks (not on whether it also happens to help with geolocation), and the place-guesser is graded purely on getting the location right (not on repainting anything), neither job has to compromise for the other's sake the way earlier attempts (which mashed both into one shared network) may have.
Hypothesis
Backbone is off-limits this round (mnv3s_features8.pt / mobilenet_v3_small banned), and the last eight rounds (36-43) are jointly refuted or never-scored while sharing one unexamined structural choice: whichever objective targets lighting/appearance invariance (contrastive pretraining in 41/42, a pixel-reconstruction auxiliary in 43) was always bolted onto the SAME feature map that also has to serve localization -- one trunk, one descriptor, two competing gradients fighting over the same bottleneck. Exp 42's contrastive version measurably lost (846.42 m vs champion 743.07 m). Exp 43's reconstruction version was never actually refuted -- it crashed silently on berlin and prignitz (both train logs are 0 bytes, no epoch ever printed) while frankfurt and munich trained cleanly to loss ~5.48-5.83 and exported normal-sized ONNX files (runs/20260722_214356_iter3/train_frankfurt.log, train_munich.log); loop.sh launches all four areas as concurrent background processes sharing one GPU (autoresearch/loop.sh:337-347), so this reads as resource contention from the added reconstruction decoder at 4-way parallel launch, not a refutation of reconstruction-as-a-signal. Rather than resubmit that same architecture and gamble on the same crash, this experiment tests a mechanistically different bet inspired by library L1's flavor A (the flying pre-model, never yet tried -- only flavor B, the training-only auxiliary, was attempted in exp 43): split canonicalization and localization into two SEQUENTIAL stages with separate losses instead of one shared trunk with a blended gradient. A tiny translator network runs first and is graded ONLY on repainting the crop to look like the clean daytime reference (pixel-aligned supervision the frozen relight pipeline already provides for free, per library L1); the from-scratch localization trunk runs second, entirely on the translator's output, and its features are never directly graded against pixel fidelity -- only against location. This removes the shared-bottleneck tug-of-war exp 43 hypothesized (untested) by construction: the translator can spend 100% of its capacity on appearance cleanup and the trunk can spend 100% of its capacity on discarding-lighting/keeping-layout, because neither one's loss reaches into the other's own feature map directly (only indirectly, through the ordinary chain rule of stacking them).
Method
In model/model.py: delete the ImageNet-pretrained MobileNetV3-Small trunk entirely (import, weights path, loader function) -- no torchvision constructor, no checkpoint file anywhere in model/. Add a new from-scratch DelightTranslator module: two stride-2 conv down-blocks (3->24->48 channels) into one 3x3 bottleneck conv (48 channels) into two stride-2 ConvTranspose2d up-blocks (48->24->3), whose output is added to the ORIGINAL input as a residual delta and clamped to [0,1] -- predicting a correction rather than a full repaint keeps the identity mapping trivial at init and biases the network away from a blurry mean-image collapse, since most of the output pixel value still comes straight from the input. Replace the deleted pretrained trunk with a from-scratch 4-stage plain conv stack (32->64->96->64 channels, stride 16, 8x8 output grid) -- the same shape already proven trainable in exps 41-43 -- but it now reads the translator's canonicalized output, not raw pixels. Delete the dark-expert head and its gate (model.py's self.dark_logits/self.gate from exp 12): with an explicit upstream canonicalization stage, a downstream day/night blend is redundant machinery duplicating the same job. The C4 rotation stack now wraps translator+trunk jointly: each of the 4 pixel-rotated raw copies passes through the translator individually, then through the trunk, then the single unified field head, then the same C4 logit-average and sharpened soft-argmax decode as before. In model/train.py: sample_epoch also extracts, for every sampled crop, the pixel-aligned clean-reference crop from the untouched reference.tif raster at the SAME (cx, cy, angle) already used for the lighting-bucket crop (reference.tif is already opened this way in compute_cell_weights, so this is the same file, a new read path) -- this is the translator's training target, free per library L1. The training loss becomes loss_fn(...) [unchanged CE + coord L2 + conf BCE] + 1.0 * L1(translator_output, clean_reference_crop), both terms active every step from step one, no separate pretraining phase. Optimizer collapses to a single param group / single LR (e.g. 1e-3) for all parameters, since everything is from-scratch and there is no pretrained-feature-preservation reason for a 10x trunk/head LR split anymore.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$2.14
implementation agent
$1.08
figure agent
$1.00
rented GPU — 75 m 59 s at $0.69/hr
$0.87
total
$5.09
by model — claude-sonnet-5 $4.21 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-23T00:35:52 ·
commit f61b14fababd · artifacts runs/20260722_231953_iter4 ·
took 75 m 59 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.43
Joint reconstruction-canonicalization trunk: a from-scratch encoder that must repaint the clean daytime crop, trained alongside localization every step 498f9a89
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
77 m 03 s
$8.41
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Instead of starting the UAV's 'eye' with a pretrained network that learned to recognize everyday objects like dogs and cars (which never had to learn to tell one street from another), we make it learn a new party trick from scratch: given a photo taken at dawn, dusk, or pitch-black night, it has to repaint what that same spot looks like in clean daylight. To repaint convincingly it has to actually remember fine details -- building shapes, road layouts -- not just a vague impression, which is exactly the kind of detail needed to tell two similar-looking neighborhoods apart. We tried a similar from-scratch idea last round (a matching game instead of repainting) and it didn't help; repainting is a stricter test that shouldn't let the network cheat by getting lazy.
Hypothesis
Backbone is off-limits this round (mnv3s_features8.pt / mobilenet_v3_small banned), and the last seven rounds (36-42) were jointly refuted while leaving one thing unquestioned at a time: 36/37/39/40 churned the loss/decode/field parameterization around the SAME ImageNet-classification trunk, and 41/42 finally replaced that trunk with a from-scratch one but taught it via NT-Xent instance-discrimination contrastive pretraining -- and still lost (846.42 m vs champion 743.07 m). Exp 42's own pre-registered falsification fork (a) named the exact redirect for a flat/worse contrastive result: 'a reconstruction-style auxiliary (library L1) instead of contrastive' -- untested until now. The two objectives target the diagnosed wall (runs/_probe_iter12_field.py: true cell top-1 only ~2% of 1024 despite landing in the top-20 33-58% of the time -- descriptor narrows things down but cannot finish separating lookalikes) very differently: contrastive only pushes different-location embeddings apart in the abstract, with no pressure to preserve WHAT the location looks like, so a lazy shortcut (e.g. collapsing to a few broad texture clusters) can drive the loss down while destroying exactly the fine layout detail that separates confusable lookalike districts. A reconstruction objective cannot take that shortcut: to repaint the clean daytime pixels of a 128x128 crop from an 8x8 feature map, the encoder is forced to keep genuine spatial/appearance detail (building outlines, road widths, texture layout) in every location's descriptor, not just a coarse identity code -- and because the target is always the SAME clean daytime reference regardless of which of the six lighting buckets the input came from, the pressure to canonicalize lighting comes for free as a side effect of the fidelity requirement, rather than being the entire (and, per 41/42, insufficient) point of the objective. This experiment isolates the pretext-task variable cleanly: architecture and training procedure otherwise mirror exp 42's already-implemented (and gate-checked) whole-pipeline shape (from-scratch conv trunk, lighting gate removed, unified field) so any metric difference is attributable to reconstruction vs. contrastive pretraining, not to incidental shape differences. Unlike exp 41/42's staged pretrain-then-finetune schedule, the reconstruction signal here runs as a joint auxiliary loss for the entire training run (library L1 flavor B) rather than a separate up-front phase, so the canonicalization pressure cannot be forgotten during fine-tuning the way a one-shot pretraining phase's benefit can fade.
Method
Replace model.py's ImageNet-pretrained MobileNetV3-Small trunk with a from-scratch 4-stage conv encoder (32->64->96->64 channels, stride 16, 8x8x64 output). Add a small training-only transpose-conv decoder (mirrors the encoder: 64->96->64->32->3, sigmoid output) that reconstructs the clean daytime reference.tif crop from the encoder's own feature map -- discarded before ONNX export, so it costs nothing in the deployment budget. Every training step, in addition to the existing CE-field + coord-L2 + conf-BCE loss, add an L1 pixel-reconstruction loss (weight 1.0) between the decoder's output and the pixel-aligned reference.tif crop (same cx/cy/rotation angle as the input, extracted via the frozen pipeline.dataset.extract_crop) -- for every lighting bucket, every crop, every step, not a separate pretraining phase. The lighting gate (two-expert day/night blend) is removed and replaced with a single unified field head, since the reconstruction target is always the canonical daytime scene regardless of input lighting bucket, giving the trunk direct pressure to normalize lighting differences into one representation rather than needing a routing mechanism downstream. All parameters (encoder, field head, confidence head, decoder) train under one shared LR/schedule instead of the old pretrained-trunk 10x-slower discount, since nothing here is transferred.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 743.07 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
figure agent
$4.25
design agent
$1.79
implementation agent
$1.48
rented GPU — 77 m 03 s at $0.69/hr
$0.89
total
$8.41
by model — claude-sonnet-5 $7.52 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-22T23:00:59 ·
commit 498f9a89c0fd · artifacts runs/20260722_214356_iter3 ·
took 77 m 03 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.42
Domain-native contrastive pretraining replaces the ImageNet trunk (corrected re-attempt) fed7c60a
The loop discarded this — no improvement under the metric then in force.
architecture
1.996
69 m 24 s
$4.13
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model's 'eyes' were borrowed from a network trained to recognize everyday objects like cats and cars -- it was never taught that a rooftop at noon and the same rooftop at midnight are the same place, or that two different-looking places are different. This experiment throws that borrowed trunk away and grows a brand-new one from scratch, first playing a 'same place or different place?' matching game using nothing but the map images this project already generates in every lighting condition, before it ever tries to pinpoint a location. It's a bit like teaching someone to recognize your street by showing them photos of it at dawn and at midnight side by side, instead of handing them a general photo-classification textbook and hoping street-recognition falls out.
Hypothesis
Exp 41 diagnosed the real wall correctly but was rejected on compliance, not on merit: its implementation still carried the champion's backbone identifiers (mnv3s_features8.pt, mobilenet_v3_small) somewhere in model/, so the harness rejected it before training and the underlying scientific question -- does an ImageNet-classification trunk cap the field's ranking ability -- remains untested. Six straight reverts/rejections (36-41) all left the same thing untouched: an ImageNet-supervised MobileNetV3-Small trunk (mnv3s_features8.pt), unchanged in kind since exp 11, the only stage never once touched except by three reverted capacity-scaling attempts (8, 26, 28) that widened it without ever changing what it is trained to represent. That trunk's entire training signal is 'classify natural photographs of ImageNet objects'; it has never been told to treat six different lighting renders of the SAME place as the same thing, or to separate one map location's appearance from another's. The project's own diagnostic probes (runs/_probe_iter12_field.py, memory champion-failure-mode-probes) show the wall is exactly a discrimination failure: the true cell is the field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops -- the descriptor narrows things down but cannot finish separating confusable lookalikes, and no downstream architecture/loss change (exps 34/36/37/39/40, all reverted) has fixed that because the descriptor handed to them was never trained to make that separation. This iteration replaces the ImageNet-pretrained trunk with a from-scratch trunk pretrained via self-supervised contrastive learning (NT-Xent) directly on the frozen relight pipeline's own multi-lighting, multi-heading renders of the TRAIN split: positive pairs = two independently-drawn views (different lighting bucket + different heading) of the SAME physical location; negatives = every other location in the batch. This is the identical scientific bet exp 41 made, run through a hardened implementation path this time: the champion's backbone identifiers are hard-deleted from model/model.py and model/train.py -- including the one place a plain code rewrite would NOT have caught them, a historical docstring sentence naming the old checkpoint path in prose, which backbonecheck.py scans verbatim since it deliberately does not strip docstrings (only '#' comments).
Method
In model/model.py: delete `_build_pretrained_trunk`, the `mobilenet_v3_small` import, `PRETRAINED_TRUNK_PATH`, and the ImageNet mean/std buffers; replace the trunk with a brand-new from-scratch 4-stage plain conv stack (32->64->96->64 channels, stride 2 each, 128x128 -> 8x8x64, ~131k params, no borrowed weights, no checkpoint file). Delete the dark-expert head and brightness gate (exp 12); a single unified field head reads the new trunk's GAP + layout-squeeze descriptor, since the new trunk is pretrained specifically to already collapse lighting nuisance. Add a small discard-after-pretraining projection head. In model/train.py: add a new pretraining phase (nt_xent_loss + pretrain_contrastive) that runs before the existing supervised epoch loop, drawing paired lighting/heading views of the same locations from the pipeline's own cached renders and training the trunk+projector with an NT-Xent contrastive loss; the main supervised loop is otherwise unchanged except the trunk's fine-tune LR (no longer a delicately-borrowed pretrained model). Every literal occurrence of `mobilenet_v3_small` and `mnv3s_features8` -- including in prose, not just code -- is removed from both files; see implementation_brief for the exact grep-verifiable checklist.
Conclusion at the time
REVERTED — metric did not improve (846.42 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.996 — 0.0% of held-out frames give a usable fix, 99.5% are confident and wrong, 0.5% abstain. Median miss 3.31 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$1.76
implementation agent
$1.57
rented GPU — 69 m 24 s at $0.69/hr
$0.80
total
$4.13
by model — claude-sonnet-5 $3.33 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 846.4 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 0.99
era Four areas, six lighting buckets · ts 2026-07-22T21:43:34 ·
commit fed7c60aaef4 · artifacts runs/20260722_203410_iter2 ·
took 69 m 24 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.41
Domain-native contrastive pretraining replaces the ImageNet trunk c0fda62e
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
15 m 38 s
$0.18
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Every past attempt to fix the model's map-reading skill tinkered with the scorer that ranks candidate locations, but always fed it the same raw description of the photo -- one originally learned for recognizing everyday objects like cats and cars, never for telling one street block apart from a lookalike block across town. This experiment throws that borrowed description out and teaches the model to describe photos from scratch, using a game where it has to recognize that a daytime and a nighttime photo of the SAME spot are 'the same' while a photo of a different spot is 'different' -- practiced over and over using the free synthetic renders we already generate. Only after it gets good at that game does it move on to learning actual GPS coordinates. We also removed a day/night switch that was patched in earlier to work around the old description's blind spot in the dark, since the new description is trained to already see through lighting changes on its own.
Hypothesis
Five straight reverts (36-40) all attacked the decode/field/loss/parameterization side of the pipeline (margin hinge, K=8 regression, a rejected retinex-channel attempt, a coordinate-generated embedding field, coarse-to-fine field+offset) and every one of them left the SAME thing untouched underneath: an ImageNet-supervised MobileNetV3-Small trunk (mnv3s_features8.pt), unchanged in kind since exp 11, the only stage never once touched in 40 rounds except by three reverted capacity-scaling experiments (8, 26, 28) that widened it without ever changing what it is trained to represent. That trunk's entire training signal is 'classify natural photographs of ImageNet objects' -- it has never once been told to separate one map location's appearance from another's, or to treat six different lighting renders of the SAME place as the same thing. The project's own diagnostic probes (runs/_probe_iter12_field.py, memory champion-failure-mode-probes) show the wall is exactly a discrimination failure: the true cell is the field's top-1 pick only ~2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops -- the descriptor narrows things down but cannot finish the job of separating confusable lookalikes. No architecture/loss/parameterization change on the classifier side can fix that if the descriptor handed to it was never trained to make that separation in the first place. This experiment replaces the ImageNet-pretrained trunk with a from-scratch trunk pretrained via self-supervised contrastive learning (NT-Xent) directly on the frozen relight pipeline's own multi-lighting, multi-heading renders of the TRAIN split: positive pairs = two independently-drawn views (different lighting bucket / relight realization / heading or C4 rotation) of the SAME physical location; negatives = every other location in the batch. This is a domain-native training signal that explicitly rewards exactly the property the ranking wall needs -- collapse lighting/heading nuisance, keep different locations apart -- which an ImageNet object-classification signal never provided and no downstream architecture change could retrofit.
Method
Delete model.py's ImageNet-pretrained trunk entirely: remove the torchvision.models.mobilenet_v3_small import, PRETRAINED_TRUNK_PATH, _build_pretrained_trunk(), and model/pretrained/mnv3s_features8.pt (unused after this change; delete the file so its identifier cannot linger in model/). Replace it with a from-scratch _build_trunk(): four stride-2 3x3-conv + BatchNorm + GELU stages, channels 3->24->32->48->64 (128x128 in -> 8x8x64 out, same stride-16 grid shape the field head already expects), ~50k params -- a plain conv stack, deliberately NOT an inverted-residual/depthwise-separable/SE design, so it is a genuinely different family from MobileNetV3, not a reimplementation of it. Add a new phase-0 to train.py: self-supervised NT-Xent pretraining of this trunk plus a throwaway projection head (GAP-64 -> Linear(64,64) -> GELU -> Linear(64,32), L2-normalized, never exported) over TRAIN-split crops only. Reuse the existing confusability-weighted sampler (crop_probs, exp 35) and the existing TRAIN_REALIZATIONS-cached renders (prepare_realizations, exp 17) -- no new expensive data generation, so this cannot repeat the exp27/33/34 ENOSPC/OOM failures. Each sampled anchor location contributes two views drawn from independently-chosen (lighting bucket, realization, heading-or-C4-rotation) combinations. Run 3 epochs, 3000 locations/bucket/epoch, batch 128, temperature 0.15, Adam 1e-3 cosine-to-0. Save the trunk's state_dict to <out_dir>/pretrained_trunk.pt (a per-run training artifact, NOT written into model/pretrained/, which is reserved for checked-in external checkpoints). Phase-2 (the existing supervised loop) then builds a fresh TinyLocNet whose trunk loads that state_dict as its starting point, instead of loading an external ImageNet file. Inside TinyLocNet: delete dark_logits and the gate nn.Sequential entirely; loc_logits becomes the sole field head reading cat([f, layout]) directly (no gated blend). Redirect the now-unused raw-brightness signal into conf_head's input instead: cat([f.detach(), peak, ent, gap, lum]) (was missing lum before). Make DECODE_BETA a learned scalar nn.Parameter, softplus-transformed and initialized to invert to today's constant (3.0), trained jointly with the rest of the field via the existing loss. In train_area()'s phase-2 optimizer, shrink the trunk/head LR ratio from 10x (1e-4 vs 1e-3) to ~3.3x (3e-4 vs 1e-3), since the trunk now starts from a domain-native prior rather than a foreign-photograph one that needed heavier protection. GRID_K=32, TARGET_SIGMA_CELLS, the confusability-sampler math, calibrate_conf_shift, the C4 rotation-vote at inference, the supervised CE + coordinate-L2 + confidence-BCE loss formula, and the ONNX export contract are all otherwise untouched.
Conclusion at the time
REJECTED IN ERROR — the pivot directive WAS honored. The design proposed a from-scratch domain-native contrastive trunk (init_strategy: from-scratch, no ImageNet, no torchvision checkpoint) and the implementation removed the mobilenet backbone. The gate rejected it over prose in the file header, and its weights pattern was additionally anchored on a path form model.py never writes, so it missed real loads while flagging the docstring. Fixed in f04434d (docstrings stripped via ast; weights matched as a bare filename). This design was never evaluated and remains open.
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
rented GPU — 15 m 38 s at $0.69/hr
$0.18
total
$0.18
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-22T20:34:10 ·
commit c0fda62e1282 · artifacts runs/20260722_201832_iter1 ·
took 15 m 38 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.40
Coarse-to-fine geolocalization: a shared conv field ranks the region, a shared local head regresses the offset 9880938d
The loop discarded this — no improvement under the metric then in force.
architecture
1.956
81 m 04 s
$8.40
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Every past attempt asked one system to do two hard jobs at once: figure out roughly WHERE a photo was taken among 1,024 tiny map tiles, AND pinpoint the exact spot -- in a single step. The diagnosis says the 'which tile' part is the part that keeps failing (the model narrows it down but usually doesn't pick the right one out of many similar-looking tiles). So this experiment splits the job in two: first, a much simpler 64-tile guess (roomier tiles, easier to get right, and computed straight off the camera model's own picture-shaped map instead of a giant independent answer sheet). Second, a small dedicated helper then nudges that guess to the exact spot within the winning tile -- a much easier fine-tuning problem once you already know the neighborhood. It's like first picking the right city block, then a second glance to find the exact doorway, instead of trying to name the doorway out of a thousand candidates in one look.
Hypothesis
Four straight reverts (36-39) all attacked the SAME output parameterization the project has used since round 2: a probability FIELD over map cells, decoded by soft-argmax, whether scored by a flat 1,024-independent-row table (2-38) or exp 39's coordinate-generated embedding table (still reverted, 1103.28 vs 743.07 m). Every one of those attempts kept the SAME shape of decode: one soft-argmax pass has to simultaneously (a) rank the true cell above every distant lookalike and (b) deliver metre-level precision, at whatever single grid resolution it commits to. The project's own diagnostic probes (runs/_probe_iter12_field.py, project memory champion-failure-mode-probes) show why that is two incompatible jobs at once: at 1,024 cells (~217 m/cell) the true cell is top-1 only ~2% of the time despite being in the top-20 33-58% of the time -- ranking that many near-identical candidates is the wall, not precision, since a coarser grid should be far easier to rank correctly (distant lookalike districts are usually NOT in the same coarse region as the truth). But a coarser grid alone destroys the precision the 20 m target needs. No experiment in 39 rounds has ever separated these two jobs into two stages. This is a genuine whole-pipeline pivot, not a parameterization tweak within the same one-shot decode: the field itself becomes a coarse, heavily parameter-shared, fully CONVOLUTIONAL grid (a 1x1 conv read directly off the trunk's own 8x8 spatial feature map -- the trunk's own translation structure DOES the parameter sharing, instead of either 1,024 free-standing rows or exp 39's Fourier-MLP generator, which still had to learn spatial structure abstractly), and a SEPARATE, cheap, shared fine-offset head -- reading the trunk's finer stride-8 tap -- regresses a per-cell (dx, dy) correction so the coarse cell's fixed center is nudged to the true location. Point regression was tried twice before (exp 1/2's single point, exp 37's K=8 hypotheses) and both lost specifically because nothing had resolved WHICH place first, so the regressor had to solve ranking and precision at once and collapsed toward the map centroid on ambiguous crops. Here the coarse field resolves ranking first (an easier 64-way problem); the offset regressor only ever has to solve a small, unimodal, well-conditioned local problem within whichever cell won -- a materially different setup from both prior regression failures.
Method
Replace TinyLocNet's single flat 1024-way field (model/model.py) with a two-stage coarse+fine field: (1) the trunk's existing stride-16 8x8 feature grid is read by a 1x1 conv (2 output channels: bright/dark expert, blended by the existing brightness gate) directly INTO an 8x8=64-cell coarse field -- no flattening through a large Linear layer, the conv IS the field, so nearby coarse cells structurally share features by construction. (2) A NEW stride-8 tap (24ch @ 16x16, exactly 2x the stride-16 grid's resolution) is reshaped into per-coarse-cell 2x2 local blocks and read by ONE small shared conv head (identical weights at all 64 positions) producing a per-cell (Δu, Δv, logσ) correction. (3) Decode becomes a DSNT-style soft-argmax using PER-CELL fine-corrected centers (fixed grid center + that cell's own predicted offset) instead of fixed grid centers -- still fully differentiable, still decode-equals-what-the-loss-optimizes (no new argmax/gather anywhere in the exported graph). (4) Training signal becomes a joint loss: coarse Gaussian-smoothed CE over the 64-way field + a Huber offset-regression term gathered at the ground-truth cell only (a training-time-only gather, not exported) + the existing L2-on-decode and confidence BCE. (5) Confidence combines the coarse field's shape (as today) with the fine field's own predicted log-variance. (6) The confusability-weighted sampler (exp 35, kept) is recomputed at the new 8x8 granularity instead of 32x32. (7) The freshly-initialized offset head gets a 2-epoch LR warmup before joining the shared cosine schedule. This deletes the old loc_logits/dark_logits/layout_squeeze Linear layers entirely (~625k params) and replaces them with a tiny 1x1 conv (~100 params) plus a tiny shared offset conv head (~3k params) -- a large net reduction in output-side parameter count, i.e. far MORE sharing, not less, directly targeting the 'cannot fit its own training locations' signature diagnosed since round 20/25.
Conclusion at the time
REVERTED — metric did not improve (1011.58 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.956 — 0.0% of held-out frames give a usable fix, 95.5% are confident and wrong, 4.5% abstain. Median miss 3.14 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$5.29
implementation agent
$2.17
rented GPU — 81 m 04 s at $0.69/hr
$0.93
total
$8.40
by model — claude-sonnet-5 $7.46 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.01 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9560% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-22T20:05:21 ·
commit 9880938d7742 · artifacts runs/20260722_184417_iter3 ·
took 81 m 04 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.39
Coordinate-generated map field: replace 1,024 free-parameter cell templates with a shared position-conditioned embedding generator 898d8cb5
The loop discarded this — no improvement under the metric then in force.
architecture
1.726
71 m 34 s
$7.28
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
For 38 rounds the model has picked a location by keeping a giant multiple-choice answer sheet: 1,024 separate, totally independent answers, one per map tile, that it must learn from scratch with no help from each other. That's like memorizing 1,024 unrelated flashcards instead of learning a map. This experiment throws the flashcards away and replaces them with a tiny function that GENERATES an answer for any tile just from its map coordinates -- so learning about one tile automatically improves nearby and similar tiles too, instead of each one starting from zero. The photo still gets turned into its own compact fingerprint, and the guess is just 'which generated tile-fingerprint looks most like mine' -- same idea as before, just with a far smaller, far smarter answer sheet.
Hypothesis
Three consecutive reverts (36: hardest-impostor margin hinge on the 1024-way field; 37: K=8 multi-hypothesis regression replacing the field; 38: rejected outright for touching only the trunk's input channels while leaving the field, decode, gate, and confidence self-reported unchanged) all left one thing untouched across the entire 38-round history: the map-cell scorer itself is a flat nn.Linear(560, 1024) -- exactly 1,024 completely independent weight rows, unchanged in kind since exp 2/10, each fit from scratch with zero structural relationship to its neighbors. Exp 26 named the resulting signature precisely: since exp 20/25, train-split and eval-split unfiltered medians are EQUAL (~1 km in every area/bucket) -- the model cannot even fit its OWN training locations, which is the textbook signature of a statistically weak output parameterization, not of missing capacity (exps 26/28 tripled trunk depth three times, all reverted, two after coverage was honestly measured), missing optimization (exp 25 trained to a genuine loss plateau and moved the metric only 5%), or a weak objective (exps 34/36's hardest-impostor margin hinge, twice refuted). The one experiment that DID attack the parameterization directly -- exp 31's neural-map correlation field -- was reverted, but its own pre-registered failure mode was orthogonal to weak-parameterization itself: a spatial 4x4 crop kernel cross-correlated against a map raster is sensitive to the residual +/-45 degree heading error left after the C4 vote, which smears correlation peaks regardless of how good the underlying map representation is. That failure mode does not apply to a HOLISTIC embedding comparison (a single 64-d crop vector dotted against a single 64-d cell vector, exactly the same shape of comparison the current flat head already makes) -- so the parameterization hypothesis is genuinely untested in a form that avoids exp 31's specific breakage. This experiment replaces the flat table with a coordinate-conditioned generator: a fixed Fourier positional encoding of each cell's (u, v) center feeds a tiny shared 2-layer MLP that outputs all 1,024 cell embeddings, so a gradient at one map location updates the SAME ~6k shared parameters that determine every other cell's embedding -- an explicit smoothness/parameter-sharing prior across map positions that a bank of 1,024 independent rows structurally cannot have, directly targeting the diagnosed 'cannot fit own training locations' signature. Per the pivot directive this also forces (not as an afterthought, but as a structural consequence of deleting the flat head) a rewrite of every downstream stage that read it: the two-expert brightness gate (rd 12) is replaced by continuous FiLM conditioning of the embedding MLP; the feature extractor now taps the trunk's stride-8 block (16x16x24) as a second GAP summary alongside the stride-16 block, since a metric-learning embedding benefits from a multi-scale descriptor in a way a single flat classifier never got to exploit; decode and confidence are recomputed over the new cosine-similarity field, with confidence now reading a peak-vs-second-peak embedding margin instead of the old hand-crafted shape detector.
Method
model/model.py: delete loc_logits, dark_logits, and gate (the flat linear head, the dark expert, and the brightness blend -- roughly 625k of the model's 823k parameters). Split the pretrained trunk into features_early = full[:4] (stride-8, 24ch @ 16x16) and features_late = full[4:] (stride-16, 48ch @ 8x8) -- same loaded weights, just referenced as two slices. Add: an embed_hidden/embed_out MLP (584-d descriptor [late GAP 48 + skip GAP 24 + layout 512] -> 128 -> 64, L2-normalized) producing the crop embedding; a film_mlp ([brightness, late GAP] -> gamma/beta, 128-d each) FiLM-modulating the embedding MLP's hidden layer; a fixed Fourier positional encoding of the 1,024 grid-cell centers (registered buffer, L=6 frequencies) feeding a small map_gen MLP (26 -> 64 -> 64, L2-normalized) that generates all 1,024 cell embeddings fresh every forward call; a learned scalar logit_scale (init 10.0) temperature-scaling the cosine-similarity matmul (crop_embedding @ map_embeddings.T) into the same-shaped [N, 1024] logits the rest of the pipeline (C4 vote, Gaussian-CE, sharpened soft-argmax decode) already consumes unchanged. Confidence head's input swaps the old decode-gap feature for a peak-vs-second-peak cosine-similarity margin (torch.topk(2)), kept alongside peak mass and entropy. model/train.py: exactly one line changes -- `trunk_params = list(model.features.parameters())` becomes `list(model.features_early.parameters()) + list(model.features_late.parameters())` -- sampler, calibration, schedule, and loss_fn's math are byte-identical.
Conclusion at the time
REVERTED — metric did not improve (1103.28 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.726 — 0.2% of held-out frames give a usable fix, 72.8% are confident and wrong, 27.0% abstain. Median miss 3.48 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$5.36
implementation agent
$1.10
rented GPU — 71 m 34 s at $0.69/hr
$0.82
total
$7.28
by model — claude-sonnet-5 $6.45 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.10 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.7260% usablecov 0.73
era Four areas, six lighting buckets · ts 2026-07-22T18:43:41 ·
commit 898d8cb5b18b · artifacts runs/20260722_173207_iter2 ·
took 71 m 34 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.38
Illumination-invariant retinex channel joins raw RGB from the pixel level through the trunk 898d8cb5
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
architecture
—
20 m 32 s
$0.24
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Every version of this model so far has looked at the photo exactly as the camera sees it -- raw colors and brightness. But the same street can look totally different depending on how dark it is or how many lights are on, and we've measured that the model's mental fingerprint of a place gets thrown off by that brightness noise, not just by the actual layout of streets and buildings. This experiment hands the model a second picture alongside the first: a version mathematically flattened to remove slow brightness changes and keep only the sharp local edges -- like squinting to ignore how sunny or dim it is and see only shapes. Both pictures are fed in together from the very first layer, so the network can lean on the shape-only picture whenever plain color is confounded by lighting. We also sprinkle a bit of random blur or sharpening onto training photos so the model can't cheat by reading blur artifacts as if they were a location clue.
Hypothesis
Two consecutive reverts (exp 36: hardest-impostor margin hinge on the same 1024-way field; exp 37: multi-hypothesis K=8 regression replacing the field) both left the feature extractor, layout summary, rotation fan, training data, and training schedule byte-identical to round 35 (see arch_json for ids 36/37) -- confirming those five stages are the frozen core, not the decode/loss/head churn happening around them. Every change to that core across the project's 37-round history has been a CAPACITY change within the same RGB-only pretrained-CNN family: exp 8 scaled a from-scratch encoder 4.2x (reverted), exp 26/27/28 tripled the pretrained trunk's depth three separate times (all reverted) -- exp 26/28 even confirmed real like-for-like accuracy gains (munich morning 536->347m, frankfurt evening 798->466m) that were wiped out once coverage was measured honestly, or reversed once it was. No experiment in the entire history has ever changed WHAT the trunk's first layer sees: all 37 rounds fed it raw RGB and nothing else. Two independent live probes point at that exact gap. runs/_probe_iter12_heading.py found the champion's descriptor rides low-level resampling-blur statistics that carry zero location information: eval crops that skip PIL's bilinear rotation-resampling blur nearly DOUBLE the error (983->1668m, berlin midday) from a blur artifact alone, not layout. runs/_probe_iter12_field.py found the true map cell is the field's top-1 pick only 2% of the time despite landing in its own top-20 (of 1024) on 33-58% of crops in every bucket -- the descriptor already narrows the field down, but something confounds fine discrimination among the candidates, exactly what lighting/blur nuisance riding through every learned channel would do (it blurs classifier rows for visually similar districts without erasing their coarse similarity). This experiment gives the network, for the first time, an explicit non-learned illumination-invariant geometric signal -- a Retinex-style channel (log(pixel) minus its own large-radius Gaussian blur, per RGB channel, fixed kernel, no gradient path) concatenated with raw RGB before the very first conv layer -- so the trunk, layout summary, and every downstream stage can draw on a signal invariant to ambient brightness/gain by construction, instead of relying on fine-tuning alone to discover that invariance, which the last three capacity experiments show it has not done.
Method
Concatenate a fixed, non-learned Retinex-style illumination-invariant channel (log(pixel) minus its own large-radius Gaussian blur, per RGB channel, sigma=10px, no gradient path) with raw RGB before the first conv layer; widen the pretrained MobileNetV3-Small stem from 3 to 6 input channels (RGB weights kept verbatim, new channels a 0.1x-scaled copy); L2-normalize the layout-squeeze code per spatial cell before flattening; add exp 33's never-trained per-crop sharpness-jitter augmentation and a short LR warm-up for the newly-initialized stem weights. Files: model/model.py (_retinex, _build_pretrained_trunk, TinyLocNet.__init__/forward), model/train.py (_jitter_sharpness, sample_epoch, train_area's scheduler).
Conclusion at the time
REJECTED — pivot directive was not honored (partial change, not a complete rethink); iteration discarded without training
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
rented GPU — 20 m 32 s at $0.69/hr
$0.24
total
$0.24
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-22T17:32:07 ·
commit 898d8cb5b18b · artifacts runs/20260722_171135_iter1 ·
took 20 m 32 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.37
Multi-hypothesis coordinate regression replaces the 1024-cell field 5a6771be
The loop discarded this — no improvement under the metric then in force.
architecture
1.673
66 m 02 s
$4.59
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
For twenty-some rounds straight, the model has guessed your location the same way: score 1,024 fixed map tiles and pick whichever one scores highest -- like a multiple-choice test with 1,024 options. We measured that the right tile is in the model's own top-20 guesses most of the time, but wins outright only 2% of the time -- so the model roughly knows the neighborhood but keeps losing the final vote to a lookalike tile. This round throws out the fixed 1,024-tile menu and lets the model instead point to 8 of its own candidate spots anywhere on the map, then simply picks whichever one it's most sure about -- like narrowing that multiple-choice test from 1,024 options down to 8, which should be a much easier pick. Each of the four camera headings picks its own best spot, and the four picks get blended by how confident each heading was.
Hypothesis
The champion's field/decode mechanism (32x32-cell classification field -> beta-sharpened soft-argmax) has been completely unchanged since round 16 -- twenty rounds (17-36) have only churned satellite modules around it (samplers, auxiliary losses, gates, a margin hinge) while the frozen core keeps producing the exact failure mode diagnosed in runs/_probe_iter12_field.py and recorded in project memory 'champion-failure-mode-probes': the true cell is the field's top-1 pick on only ~2% of eval crops, yet lands in the field's own top-20 (of 1024) on 33-58% of crops in every lighting bucket. That gap means the descriptor already carries enough signal to narrow the answer down to a small neighborhood -- the failure is specifically that a 1024-way ranking problem is too hard for the head to solve, not that the features are uninformative. Round 34's and round 36's margin-hinge losses attacked this by pushing individual impostor cells down within the SAME 1024-way field and both failed to beat the champion (1e9 gated-fail, then 754.22 vs 743.07) -- evidence the bottleneck is the discretization itself, not which cells get extra gradient. Shrinking the ranking problem from 1-of-1024 fixed grid cells to 1-of-8 data-dependent candidate points should make correct-hypothesis selection tractable while a small K also sidesteps exp 5's diagnosed sparse-supervision problem (a rigid 1024-cell grid needs many training locations per cell to learn anything; 8 free-floating points just need to drift toward wherever they're useful, no fixed-cell occupancy requirement).
Method
In model/model.py, delete the 1024-way classification field entirely (loc_logits, dark_logits, gate, cell_u/cell_v grid, GRID_K, DECODE_BETA, the beta-sharpened soft-argmax decode) and replace it with a K=8 multi-hypothesis regression head: a small MLP reads [GAP descriptor, layout code, raw brightness] and outputs 8 candidate (u,v) points (each an offset added to one of 8 fixed, non-trainable anchor positions spread across the map, purely to break symmetry at init) plus 8 softmax mixture weights. Each of the 4 C4-rotation views independently picks its own highest-weight hypothesis; the 4 views' winning points are blended into the final (u,v) by a softmax over their own weights (replacing the old logit-averaging C4 vote with a point-averaging C4 vote). Confidence is rebuilt from the spread of the 4 views' winning points (tight agreement = confident) and their mean weight, replacing the old field-peak/entropy signal. Training signal changes from Gaussian-smoothed 1024-way cross-entropy + coordinate L2 to a winner-take-all regression loss (only the hypothesis nearest the true (u,v) gets the full L2 gradient each step; the other 7 get an epsilon=0.05 trickle to avoid dead hypotheses) plus an 8-way cross-entropy that trains the weight head to identify which hypothesis was nearest. The exp-35 confusability-weighted sampler (Training data, kept, unchanged) still needs a 32x32 grid to define 'look-alike cells' for oversampling -- since model.py no longer has any grid, that constant moves into model/train.py as a standalone CONFUSABILITY_GRID_K, with identical value and math, so the sampler's actual behavior is byte-for-byte unchanged.
Conclusion at the time
REVERTED — metric did not improve (1100.35 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.673 — 0.0% of held-out frames give a usable fix, 67.2% are confident and wrong, 32.8% abstain. Median miss 3.40 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$3.00
implementation agent
$0.83
rented GPU — 66 m 02 s at $0.69/hr
$0.76
total
$4.59
by model — claude-sonnet-5 $3.82 · claude-haiku-4-5-20251001 $0.01
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.10 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.6730% usablecov 0.67
era Four areas, six lighting buckets · ts 2026-07-22T16:01:49 ·
commit 5a6771be65eb · artifacts runs/20260722_145547_iter1 ·
took 66 m 02 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.36
Hardest-impostor margin hinge, retested on the confusability-weighted champion 3ee64311
The loop discarded this — no improvement under the metric then in force.
loss
1.986
59 m 54 s
$3.14
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Right now the model's best two guesses for ‘where is this’ are often a real place and a look-alike place somewhere else on the map, and it only barely favors the real one. Last round we made it practice more on exactly those confusing pairs; this round we also change how hard it gets corrected when it still ranks a look-alike above the truth. Instead of a gentle nudge spread thinly over the whole map, it now gets a direct penalty aimed specifically at its single worst rival guess, every time, until the true spot clearly wins.
Hypothesis
The §6 metric is bound by ranking quality, not descriptor content or the operating point: iter-12 probes of the exp-25 champion (runs/_probe_iter12_field.py) found the true cell is the field's top-1 on only 2% of eval crops while making the top-20 (of 1024) on 33-58% in every lighting bucket, with decode, rotation, and operating-point mechanisms all ruled out as the wall (see project memory champion-failure-mode-probes). Exp 35 (kept, 797.91 -> 743.07 m) improved this by changing WHICH locations get training exposure (confusability-weighted sampling over cell-descriptor lookalikes) but never touched the training SIGNAL itself: loss_fn's Gaussian-smeared CE (sigma=1.5 cells) still spreads its wrong-cell gradient across all 1024 cells in proportion to softmax mass, so no gradient concentrates specifically on the one distant lookalike currently outranking the truth -- exactly the objective-family gap exp 34 pre-registered (hardest-impostor margin hinge) and never got to test: its run died with ENOSPC inside prepare_realizations before a single gradient step (timings.json score_s: 0, train_wall_s: 268 -- see project memory exp34-enospc-disk-lifecycle). The hypothesis is UNTESTED, not refuted, and the mechanism it targets (the training signal) is a materially different lever from exp 35's (the sampler). The two should compound rather than compete: exp 35 already brings confusable cell pairs to the model more often; the margin hinge is the loss term that actually forces their scores apart once they arrive, rather than relying on CE's diffuse likelihood gradient to do it incidentally. Disk is currently clean (33 GB free per df -h) so this run should not repeat exp 34's infrastructure failure.
Method
ONE change, entirely inside model/model.py's loss_fn (training-only; forward(), export_onnx(), estimate_position(), and all of train.py -- sampler, prepare_realizations, schedule, calibrate_conf_shift -- are untouched): add a hardest-impostor margin hinge on the same C4-voted logits the decode reads. Per crop: s_pos = max logit within Chebyshev radius 1 of the true cell (the 3x3 block a 128 m crop legitimately straddles across a ~220 m cell boundary); s_neg = max logit over cells at Chebyshev radius > 3 (outside the 7x7 ring the sigma=1.5-cell Gaussian CE bump already covers, so the hinge never fights the CE term over near-misses -- same exclusion radius convention train.py's compute_cell_weights already uses for its confusability lookup, NEIGHBOR_EXCLUDE_R=1, just applied at a wider ring for the negative). loss += 0.5 * relu(1.0 + s_neg - s_pos), added to loss_fn's existing returned sum (ce + coord_loss + 0.3 * conf_loss). Margin 1.0 logit is roughly a 20x mass ratio after the beta=3 decode sharpening already in forward(). CE, coord L2, conf BCE, the sampler, the epoch schedule, and the calibration procedure are all unchanged, so the deployment gates and operating-point comparison to the champion stay apples-to-apples.
Conclusion at the time
REVERTED — metric did not improve (754.22 m vs best 743.07 m); change discarded
Re-measured on today's ruler
Mission score 1.986 — 0.0% of held-out frames give a usable fix, 98.5% are confident and wrong, 1.5% abstain. Median miss 3.05 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$1.75
implementation agent
$0.70
rented GPU — 59 m 54 s at $0.69/hr
$0.69
total
$3.14
by model — claude-sonnet-5 $2.45 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 754.2 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9860% usablecov 0.98
era Four areas, six lighting buckets · ts 2026-07-22T12:30:57 ·
commit 3ee64311291b · artifacts runs/20260722_113103_iter2 ·
took 59 m 54 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.35
Confusability-weighted location sampling: oversample look-alike cell pairs, not just more places 3750ddb6
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.928 — worse than silence.
training
1.928
62 m 59 s
$4.20
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model has to recognize 1,024 map tiles from a single photo, and we already know its biggest problem: some far-away tile that just happens to look similar often beats the true tile in the ranking. Until now, training showed the model every tile equally often, whether or not it has a lookalike twin somewhere else on the map. This experiment changes nothing about the model or the grading -- only which practice photos get shown more often. Before training starts, we compare the average color and texture of every tile against every other (a one-time, cheap lookup from the daytime map image itself) and flag pairs of far-apart tiles that look alike. During training, places with a lookalike twin get shown about twice as often as places that look nothing like anywhere else -- half the practice still covers the whole map evenly, so nothing is forgotten, but the confusing pairs get extra practice specifically at telling themselves apart.
Hypothesis
Per the plateau rule this iteration leaves the last nine mechanisms entirely (26-34: trunk capacity x3, stride-8 readout tap, lighting dispatcher, neural-map coordinate reparameterization, fenced/risk calibration, sensor-sharpness augmentation, and a hardest-impostor margin loss -- the last two never actually trained to completion, ENOSPC/OOM-killed before a single score, per runs/_probe_iter12_*.py forensics logged against exps 33/34) and opens a design family CLAUDE.md SS3 invites but the loop has never tried: a training-DATA strategy overhaul, distinct from every loss/architecture/ calibration change already attempted. The iter-12 probes of the exp-25 champion (runs/_probe_iter12_field.py) established the wall precisely: the true cell is the field's top-1 on only 2% of eval crops while making the top-20 (of 1024) on 33-58% in every bucket -- a lookalike cell elsewhere on the map usually outranks the truth. Since exp 20, every cell's classifier row gets the SAME training exposure regardless of how confusable it is (uniform fresh location draw, 6,000/bucket/epoch): a cell with a distant near-duplicate twin gets no more corrective gradient than an entirely distinctive one, even though it is precisely the confusable cells whose classifier rows must be pushed hardest apart to fix the measured top-1 failure. Rural Prignitz (distinctive macro-structure, few self-similar districts) already beats all three self-similar metros in every bucket under this exact uniform scheme -- the metros' worse scores are concentrated in exactly the cells uniform sampling under-serves. Rather than touch the loss (margin family, attempted but crashed untested in exp 34) or the architecture (capacity/dispatcher/coordinate families, all attempted and refuted for real in exps 26-31), this experiment changes WHICH locations the sampler draws: a cheap, one-time-per-area map of each classifier cell's nearest visually-similar DISTANT cell (computed straight from the frozen reference.tif raster, no network, no per-epoch cost) sets a sampling weight, so confusable cells are oversampled relative to distinctive ones -- concentrating the fixed per-epoch gradient budget where the ranking wall actually is.
Method
ONE change, entirely inside model/train.py (model/model.py untouched -- no architecture or loss change): (1) a new one-time-per-area function computes a GRID_K x GRID_K (32x32=1024) cell-descriptor map by average-pooling reference.tif's RGB into the same grid the field head already scores (mean R,G,B + luminance std per cell, 4 numbers), then for every cell finds its nearest OTHER cell in descriptor space excluding itself and its 8 spatial neighbors (so the weight targets genuine distant lookalikes, not trivial local blur-driven near-duplicates), giving each cell a confusability distance d_i and weight w_i = 1/(d_i + eps); (2) every training crop is mapped to its ground-truth cell and assigned sampling probability p = 0.5 x uniform + 0.5 x normalize(w) over that cell's crops; (3) sample_epoch's uniform rng.choice(..., replace=False) is replaced with the weighted rng.choice(..., p=crop_probs, replace=False) for the TRAINING draw only. calibrate_conf_shift's sampling stays uniform/unchanged (coverage-median-coupling memory: do not let a data-strategy change also alter the calibration distribution, or a metric shift can't be attributed to either mechanism cleanly). Model architecture, loss_fn, epoch count, LR schedule, and the C4/gate/decode/conf machinery are byte-identical.
Mission score 1.928 — 0.0% of held-out frames give a usable fix, 92.8% are confident and wrong, 7.2% abstain. Median miss 3.02 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$2.69
implementation agent
$0.78
rented GPU — 62 m 59 s at $0.69/hr
$0.72
total
$4.20
by model — claude-sonnet-5 $3.47 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 743.1 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9280% usablecov 0.93
era Four areas, six lighting buckets · ts 2026-07-22T11:30:46 ·
commit 3750ddb61f7a · artifacts runs/20260722_102747_iter1 ·
took 62 m 59 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.34
Hardest-impostor margin loss: the field must outrank its best lookalike, not just light up the truth bfbca30d
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
loss
—
20 m 01 s
$8.03
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model scores 1,024 map tiles for each camera frame and we fly toward the highest-scoring one. Until now training only rewarded giving the right tile a decent score — like a teacher handing out partial credit but never checking who came FIRST. Measurements show the right tile usually makes the model's top-20 list, yet almost never ranks #1: some lookalike district across town keeps beating it. The new rule is a police-lineup rule: on every training example, find the one impostor tile the model currently likes best and demand the true tile's neighborhood beat it by a clear gap. The specific impostor that keeps winning gets pushed down, the truth pushed up.
Hypothesis
The §6 metric is bound by ranking quality, and the objective family is the one lever nobody has pulled. The iter-12 probes of the exp-25 champion show the true cell is the field's top-1 on only 2% of eval crops while making the top-20 (of 1024) on 33–58% — in every lighting bucket including midday — with median peak mass 0.14 and ~2 separated modes; decode, rotation, and operating-point mechanisms are ruled out. The eight consecutive reverts (26–33) all changed what FEEDS the ranking (3× trunk capacity, stride-8 readout tap, lighting dispatcher, learned map raster) or how its output is thresholded (fenced/risk calibration), or the input statistics (exp 33 — whose 1e9 is an infrastructure artifact: munich training was OOM-killed and the run was never scored). The training signal that CREATES the ranking has been pure likelihood since exp 2: Gaussian-smeared CE spreads its wrong-cell gradient across 1024 cells in proportion to softmax mass, and the σ=1.5-cell smearing makes near-misses cheap, so no gradient ever concentrates on the single distant lookalike that currently outranks the truth — which is precisely the measured failure (truth present in the candidate set, outranked at the top). Visual place recognition trains this exact problem with hardest-negative margin objectives (NetVLAD/FaceNet family). A per-crop hinge that demotes the current best-scoring impostor cell should convert top-20 presence into top-1 rank and raise peak mass, improving median kept error across all 24 area×bucket cells rather than gaming one operating point.
Method
ONE change, entirely inside model/model.py's loss_fn (training-only; forward, export, train.py untouched): add a hardest-impostor margin hinge on the same C4-voted logits the decode uses. Per crop: s_pos = max logit within Chebyshev radius 1 of the true cell (3×3 block — a 128 m crop legitimately straddles ~220 m cells), s_neg = max logit over cells at Chebyshev radius > 3 (outside the 7×7 ring, so the hinge never fights the σ=1.5 CE bump), loss += 0.5 · relu(1.0 + s_neg − s_pos). Margin 1.0 logit ≈ 20× mass ratio after the β=3 decode sharpening. CE, coord L2, conf BCE, sampler, schedule, calibration, and the ONNX graph are unchanged, so the deployment gates and the operating-point calibration procedure are identical to the champion's.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 797.91 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$7.40
implementation agent
$0.40
rented GPU — 20 m 01 s at $0.69/hr
$0.23
total
$8.03
by model — claude-fable-5 $7.39 · claude-sonnet-5 $0.40 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-22T08:53:43 ·
commit bfbca30d5c51 · artifacts runs/20260722_083342_iter7 ·
took 20 m 01 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
augmentation
—
59 m 18 s
$7.04
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
When a computer rotates a photo, the result comes out a tiny bit softer — like a photocopy of a photocopy. Nearly every training picture we generate goes through one such rotation, so they all share that same subtle softness, and the model quietly learned to lean on it as a crutch: when we handed it a perfectly sharp picture, its guesses got twice as bad — even though softness says nothing about WHERE the picture was taken. This round we make the crutch useless: during training, some pictures now arrive pin-sharp and others extra blurry, completely at random, so the only cue that reliably pays off is the actual arrangement of streets and buildings. It's like training a wine taster with the bottles wrapped in paper: hide the label and they have to learn the taste.
Hypothesis
The §6 metric is bound by ranking quality, not decode or operating point: the iter-12 probes on the exp-25 champion show the true cell is field top-1 on only 2% of eval crops while argmax, local-window, and exported decodes agree within 3% (runs/_probe_iter12_field.py), and exp 32's per-regime abstention fix — the operating-point attack — was just refuted. The same probe round measured an untested nuisance axis: eval crops that skip PIL bilinear rotation resampling (headings at exact 90° multiples) nearly DOUBLE the champion's median error, 983→1668 m on berlin midday (runs/_probe_iter12_heading.py), so the descriptor demonstrably rides on low-level resampling-blur statistics. That band is identical everywhere on the map — it carries zero location information — yet it varies with heading, so every unit of descriptor sensitivity spent on it both jitters the place code across eval headings and steals encoder capacity from layout, which is exactly the ranking signal that must improve. Exp 17 already validated the mechanism (randomize a train-time nuisance → only nuisance-stable structure stays discriminative between locations) and the training-data family is 4-for-4 kept (exps 7, 17, 20, 25) while the last seven architecture/operating-point experiments (26–32) all reverted. Per-crop randomization of the imaging chain's sharpness — from crisper-than-eval to softer-than-eval — should force the encoder off the blur band and onto ground layout, improving field ranking in every area×lighting cell. Not built on a library entry; built on the iter-12 probe forensics.
Method
ONE change, entirely inside model/train.py's sample_epoch (the per-epoch fresh-draw sampler): each training crop rolls a random sharpness before entering the tensor. (a) With p=0.25 its heading is snapped to 0° so extract_crop skips rotation resampling entirely and the crop arrives pin-sharp — the model's C4 rotation fan then exposes all four crisp orientations for free. (b) Independently, with p=0.5, the extracted 128×128 uint8 crop gets an extra PIL GaussianBlur with σ ~ U(0.4, 1.4) px. The eval-matched statistic (continuous-heading resample, no extra blur) remains the single most common case (~37.5%), and calibrate_conf_shift stays exactly eval-matched (no jitter there). Model, losses, decode, calibration, EPOCH_MULT schedule, and the frozen pipeline are untouched.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 797.91 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$5.92
implementation agent
$0.44
rented GPU — 59 m 18 s at $0.69/hr
$0.68
total
$7.04
by model — claude-fable-5 $5.91 · claude-sonnet-5 $0.44 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-22T08:33:30 ·
commit 0aaab0f53186 · artifacts runs/20260722_073412_iter6 ·
took 59 m 18 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.32
Risk-controlled abstention: six per-lighting-regime thresholds calibrated on never-trained fenced blocks 4871a8c7
The loop discarded this — no improvement under the metric then in force.
training
1.773
108 m 15 s
$19.07
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model already grades its own guesses and is allowed to answer 'no fix' on frames it can't place — like a student who may skip questions on a test that only grades the questions they answer, as long as they attempt at least 1 in 5. Until now the skip rule was one global bar, tuned on map areas the model had already flown over in training — so how picky it actually was at night versus midday, in Berlin versus Frankfurt, was essentially accidental. We now rope off a slice of the map the model never trains on, measure there — separately for each lighting condition — how accuracy trades against how often it answers, and bake six lighting-specific bars into the model (it senses the lighting from the frame's brightness). A telling detail from the forensics: the last four 'failed' experiments were actually answering MORE questions than the champion at similar accuracy — they lost on a technicality of where their bar happened to land, which this change fixes for every future round too.
Hypothesis
The §6 scalar is currently bound not by representation quality but by the selective-prediction operating point, which is uncontrolled per lighting regime and mis-calibrated by construction. The primary metric is the median over KEPT crops with a 0.2 coverage floor, yet the abstention bar is a single global conf_shift chosen as the MINIMUM of six per-bucket thresholds, calibrated on TRAIN-VISITED ground — so each (area, bucket) cell's eval keep rate is an accident of distribution shift (champion: 0.25–0.67 across cells). Forensics on the six-experiment plateau: exps 28–31 matched or beat the champion cell-by-cell while keeping far more crops — exp 28 was better or equal in 17 of 24 cells at coverage 0.52–0.79 vs the champion's 0.42–0.67 (frankfurt evening 649.5 m @ 0.58 vs 797.9 m @ 0.46) and was reverted on ONE cell (berlin night 1057.7 m @ 0.445 vs 632.1 m @ 0.3125); exp 31 kept 30–60% more crops everywhere (0.60–0.87) and landed within 6%. The keep/revert record since exp 26 has therefore mostly measured where each candidate's threshold happened to land, not which candidate localizes better. Two fresh read-only probes justify attacking the confidence path INSTEAD of the representation this round: (a) _probe_iter12_field.py shows the ranking failure is deep and decode-independent (true cell in top-1 only 2%, argmax/local-window/export decodes within 3% of each other, oracle mode selection still ~500 m) — no cheap representation fix is on the table; (b) _probe_iter12_riskcov.py shows the confidence signal RANKS errors in every cell (Spearman conf-vs-error −0.21 to −0.42) and quantifies the exploitable headroom: with each cell run at its own best keep rate the worst §6 cell falls from 797.9 m to 731.1 m oracle (binding cell moves to frankfurt/night; frankfurt evening itself drops 798→~562-590 m, and 20 of 24 cells improve). The same probe also explains exp 28's veto mechanistically: its one global threshold kept 44.5% at berlin night (1057.7 m), while a per-regime risk-optimal pick would have run that cell at ~0.26-0.32 keep (~650-750 m). Making the operating point a designed, per-regime, distribution-matched quantity should both lower the worst cell directly and remove the measurement distortion that has been vetoing genuine representation gains.
Method
One mechanism changes — the path from confidence score to abstention decision; trunk, heads, gate, field, decode, losses, sampler mechanics, and schedule stay byte-identical. (1) model/model.py: the scalar conf_shift buffer becomes a 6-vector paired with a new conf_lum_anchors buffer; forward() piecewise-linearly interpolates the shift over the frame's own mean brightness (the lum feature the lighting gate already computes), so the exported graph infers the lighting regime from the frame alone: conf = sigmoid(z − shift(lum)). (2) model/train.py: ~10% of train-split blocks (stable-hash selected, bbox-generic) are FENCED — excluded from every training draw with the same window-halo rule the frozen split applies to eval blocks — so their terrain is honestly unseen and per-crop errors are measurable there. (3) Calibration (replaces calibrate_conf_shift): per lighting bucket, run the trained model on fenced crops at fresh random headings, trace the risk–coverage curve (median kept error vs keep rate), pick the keep rate q* in [0.26, 0.58] that minimizes the fenced kept-median (floor 0.26 is safe against the frozen 0.2 coverage gate because exp 28 measured the fenced-to-eval keep transfer as upward-biased, +0.00 to +0.11 — unlike today's train-visited calibration, which transfers DOWN by up to 0.15), and bake the six (median bucket luminance, threshold) pairs into the exported buffers.
Conclusion at the time
REVERTED — metric did not improve (1078.31 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.773 — 0.0% of held-out frames give a usable fix, 77.2% are confident and wrong, 22.8% abstain. Median miss 2.76 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$15.88
implementation agent
$1.94
rented GPU — 108 m 15 s at $0.69/hr
$1.24
total
$19.07
by model — claude-fable-5 $15.88 · claude-sonnet-5 $1.94 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.08 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.7730% usablecov 0.77
era Four areas, six lighting buckets · ts 2026-07-22T07:33:54 ·
commit 4871a8c721c1 · artifacts runs/20260722_054539_iter5 ·
took 108 m 15 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.31
Neural-map correlation field: localization becomes sliding-window matching of a crop fingerprint against a learned 32 m map raster 1ee201ff
The loop discarded this — no improvement under the metric then in force.
architecture
1.991
73 m 46 s
$12.11
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model answered 'where am I?' by comparing one overall impression of the camera frame against about a thousand memorized district flashcards -- and in a city full of lookalike districts, overall impressions collide. Now the model instead paints its own miniature map of the whole area into its weights while training. In flight it turns the camera frame into a small 4x4 fingerprint tile and slides that tile across its painted map to find where the pattern truly lines up, the way you find where a puzzle piece belongs. Because the whole arrangement inside the fingerprint has to line up -- not just the general vibe -- two neighborhoods that merely feel similar no longer fool it, and the answer grid becomes about seven times finer in each direction.
Hypothesis
The last five reverted experiments (26-30: 3x trunk capacity, coverage calibration, stride-8 readout tap, lighting-specialist dispatch) all attacked what feeds or routes around the SAME output parameterization -- a flat table of 1,024 independent ~217 m cell templates scored by dot product against one holistic 560-d crop vector, unchanged since exp 2 -- and were jointly refuted. Per the plateau rule this iteration replaces that parameterization itself, the one design family CLAUDE.md §3 invites ('a different coordinate parameterization') that the history has never touched. Three signatures say the template table is the binding constraint: (1) since exps 20/25 the converged model's train-split and eval-split medians are EQUAL (~600-800 m) -- it cannot even fit visited locations, the signature of a statistically weak output parameterization, not of missing capacity (exps 26/28 proved bigger trunks don't score) or missing optimization (exp 25); (2) rural prignitz, with distinctive macro-structure, beats all three self-similar metros in every bucket -- lookalike-cell confusion, which holistic-vector template scoring cannot resolve because it enforces no spatial-arrangement consistency between crop and cell; (3) mean/median ~= 2 everywhere -- a heavy tail of long-range aliasing errors, the same confusion. The change (OrienterNet-family matching, encoded entirely in weights -- no reference imagery ships): delete the 1,024-template tables and learn a NEURAL MAP, an 8-channel raster over the area at ~32 m/cell (dimensions derived from meta.json width/height -- no area-specific constants), scoring every raster position by cross-correlating a crop-derived 4x4x8 feature kernel whose taps each summarize 32 m of ground, matching the raster's cell size. One mechanism addresses all three signatures: (a) a position scores high only if the crop's whole 4x4 spatial arrangement matches the map there, so lookalike districts differing in sub-crop layout are suppressed geometrically; (b) the scoring function is shared across all ~45k positions (one matching kernel + one map) instead of 1,024 separately-learned discriminants, and overlapping training crops write coherently into the SAME map cells at their true offsets, multiplying effective supervision per output parameter; (c) the decode grid drops from 217 m to ~32 m pitch. The kept exp-12 bright/dark expert pair and gate survive as two kernel generators (layout-aware conv vs GAP-only linear) blended before a single correlation -- correlation is linear in the kernel, so blending kernels equals blending fields; the C4 vote (exp 16), beta-sharpened decode (exp 14), shape-feature confidence + calibration (exp 15), fresh-draw sampler (exp 20), 3-realization renders (exp 17) and 24-epoch cosine schedule (exp 25) are all byte-identical, and supervision smoothness is preserved exactly (Gaussian-CE sigma stays 1.5/32 in normalized map units).
Method
model/model.py: remove loc_logits (560->1024), dark_logits (48->1024) and the GRID_K template machinery. Add per-area parameters map_feat [8, mh, mw] (mh=round(height/32), mw=round(width/32), init 0.01*randn) and map_bias [(mh-3)*(mw-3)] (init 0). The trunk's 8x8x48 fmap is projected by a 1x1 conv (48->8) and 2x2 avg-pooled into a 4x4x8 'bright' kernel; a Linear(48->128) forms a 'dark' kernel from the GAP descriptor; the existing lum+GAP gate blends the two KERNELS per example; logits4 = F.conv2d(map_feat.unsqueeze(0), blended_kernels).squeeze(0).flatten(1) + map_bias -- valid cross-correlation, one logit per raster position, C4-averaged exactly as before. Cell centers: u=(j+2)/mw, v=(i+2)/mh, row-major. Decode, confidence features, and loss keep their exact form with TARGET_SIGMA_UV = 1.5/32. model/train.py: build_model(meta) passes area dims; loss_fn additionally receives the model's cell-center buffers. Sampler, calibration, schedule, CLI, export contract untouched.
Conclusion at the time
REVERTED — metric did not improve (846.09 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.991 — 0.2% of held-out frames give a usable fix, 99.2% are confident and wrong, 0.5% abstain. Median miss 3.40 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$9.79
implementation agent
$1.47
rented GPU — 73 m 46 s at $0.69/hr
$0.85
total
$12.11
by model — claude-fable-5 $9.78 · claude-sonnet-5 $1.47 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 846.1 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9910% usablecov 0.99
era Four areas, six lighting buckets · ts 2026-07-22T05:45:21 ·
commit 1ee201ffc513 · artifacts runs/20260722_043135_iter4 ·
took 73 m 46 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.30
Supervised lighting dispatcher: day/dusk/night specialist field heads replace the two-expert blend, int8-paid 92404766
The loop discarded this — no improvement under the metric then in force.
architecture
1.953
73 m 20 s
$11.12
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model recognizes places by comparing what it sees against a big internal catalog of how every map cell looks. Until now one shared catalog had to describe each place at noon AND at midnight — like one photo album trying to cover both — so every entry was a blurry compromise, and the model coped in the dark mostly by refusing to answer. We split it into three catalogs — day, dusk, night — and added a tiny receptionist that checks how bright the frame is and hands the image to the right catalog. During practice the receptionist is simply told the real time of day, so it can't learn the routing wrong. Three catalogs would normally be too heavy for the UAV's tiny computer, so they're stored in a compact 1-byte number format we measured earlier to be essentially harmless.
Hypothesis
The last four reverted experiments (26-29) all attacked capacity or readout width and were jointly refuted; per the plateau rule this iteration leaves that family entirely and opens the one design family CLAUDE.md §3 explicitly invites but the history has never tried: dispatcher + lighting-condition specialist models. The evidence it targets: the champion's per-bucket medians LOOK flat (berlin 632-760 m), but that flatness is manufactured by the confidence gate — night keeps only 25-31% of crops vs 50-67% for daytime buckets, so the model abstains its way to parity in low light instead of localizing to parity, and the binding §6 cell is a low-ambient one (frankfurt EVENING, 797.91 m at 0.46 coverage). The mechanism: all six lighting regimes share ONE 560→1024 template table, plus exp 12's deliberately crippled texture-only 'dark expert' (48-d input, no layout access, unsupervised gate). The same map cell must therefore be recognized by one template averaged across appearance regimes with nearly disjoint cues — daytime shadow/texture vs night's active-light constellations — so every template is a compromise, worst exactly where cues are scarcest. Exp 12 is direct evidence the axis works: even its crippled version was kept (-8%). This experiment builds the full version: each regime gets its own complete layout-aware 560→1024 template table, routing is SUPERVISED (bucket labels are free at train time), and the 3x table storage is paid in int8 FC bytes, which exps 26/29 mechanically proved passes the frozen gates at ~7 m accuracy cost.
Method
model/model.py: delete dark_logits and the sigmoid gate; replace loc_logits with three identical specialist heads Linear(560→1024) in an nn.ModuleList (day/dusk/night) and add a 3-way dispatcher MLP Linear(49→16)-ReLU-Linear(16→3) reading [lum, GAP]; per turned copy, field logits = Σ_k softmax(dispatcher)_k · specialist_k(desc); C4 vote, decode, confidence all unchanged. loss_fn gains a supervised routing term: 0.3 × cross-entropy of the dispatcher logits vs the crop's regime (morning/midday/afternoon→day, early_evening/evening→dusk, night→night). model/train.py: sample_epoch also returns the per-crop regime index; the train step passes it to loss_fn. export_onnx: fp32 export to <area>_fp32_debug.onnx, then onnxruntime.quantization.quantize_dynamic(QInt8, op_types=['MatMul','Gemm']) to the contract path — the exact recipe exps 26/29 validated (convs stay fp32; no ConvInteger); assert size ≤ 4 MiB.
Conclusion at the time
REVERTED — metric did not improve (808.22 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.953 — 0.2% of held-out frames give a usable fix, 95.5% are confident and wrong, 4.2% abstain. Median miss 3.36 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$8.85
implementation agent
$1.43
rented GPU — 73 m 20 s at $0.69/hr
$0.84
total
$11.12
by model — claude-fable-5 $8.84 · claude-sonnet-5 $1.43 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 808.2 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9530% usablecov 0.96
era Four areas, six lighting buckets · ts 2026-07-22T04:31:16 ·
commit 92404766e474 · artifacts runs/20260722_031756_iter3 ·
took 73 m 20 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.29
Stride-8 fine-layout tap: the field scorer reads an 8-m-resolution mid-trunk snapshot, int8-paid 7e6fb3ea
The loop discarded this — no improvement under the metric then in force.
architecture
1.951
70 m 11 s
$11.05
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Before guessing where it is, the model boils each camera frame down to a short summary — like describing a neighborhood in 560 numbers, where each number can only talk about 16-metre-wide squares. At that coarseness, two similar districts blur together, and our last three experiments proved that a bigger brain and longer studying don't help — the tell-apart detail was already thrown away before the guessing stage ever saw it. This experiment keeps everything else identical but lets the guesser also look at a sharper, earlier snapshot from inside the network, where building edges and narrow roads are still visible at roughly 8-metre precision. To keep the file small enough for the UAV's tiny computer, the guesser's bulky lookup tables are stored as compact 1-byte numbers — a trick we measured beforehand to be harmless.
Hypothesis
The binding constraint is the information content of the head's readout, not trunk capacity, optimization, or memorization — this is exp 26's own pre-registered diagnostic fork (a), now demonstrated by the joint record: exp 20 removed memorization (train-split and eval-split medians are EQUAL), exp 25 trained to a genuine loss plateau and moved the metric only 5.2%, and exps 26+28 tripled trunk depth/channels and made things WORSE at the designed operating point (1057.68 m vs 797.91 m best). Per the plateau rule this iteration leaves the capacity-scaling mechanism entirely and attacks the bottleneck those refutations jointly point at. The field scorer today sees only a 560-d summary of the crop: a 48-d GAP plus a 512-d layout code squeezed from the stride-16 8x8 grid — every layout cell aggregates a 16x16 m patch, so NOTHING finer than 16 m granularity survives to the 1024-way cell scorer, while the ~215 m map cells it must discriminate differ precisely in sub-16-m arrangement (building outlines, road widths, lot patterns) that the 1 m/px input plainly contains. Two signatures say the discarded fine scale is what's missing: midday errors equal night errors in every area (656-839 m metros) even though midday crops carry clean 1-m detail — if the readout could use it, daytime would lead; and rural prignitz (distinctive macro-structure, low self-similarity) beats all three self-similar metros (449-539 m), the signature of lookalike-cell confusion, not lighting. The change adds the one axis never scaled: SPATIAL resolution of the readout. The trunk's stride-8 activation (features block 3, 16x16x24) is tapped, squeezed by a 1x1 conv to 4 channels, and flattened into a 1,024-d fine layout code concatenated into the bright field head's input (560 -> 1,584). Trunk computation, pretrained weights, C4 vote, decode, confidence, and training are all byte-identical — unlike refuted exps 26/28, no capacity is added to the encoder; the head is simply allowed to SEE a scale the encoder already computes and then throws away. The enlarged FC heads fly as int8 (quantize_dynamic on MatMul/Gemm only), which runs/_probe_iter6_quant2.py proved metrically inert on this exact head family (~7 m median decode shift, no ConvInteger, latency fine): estimated export ~2.6 MB against the 4 MiB gate.
Method
model/model.py only. (1) TinyLocNet.__init__: probe the stride-8 tap shape by running features[:4] on a zero tensor (gives 24x16x16); add self.fine_squeeze = nn.Conv2d(24, 4, 1); widen loc_logits input from feat_ch + layout_ch*8*8 = 560 to feat_ch + layout_ch*8*8 + 4*16*16 = 1584. (2) forward: run the trunk as an enumerated loop over self.features, capturing the activation after block index 3 as the tap; fine4 = self.fine_squeeze(tap).flatten(1); bright head becomes self.loc_logits(torch.cat([f4, layout4, fine4], dim=1)). Dark head, gate, conf head, C4 stack, decode, loss_fn all untouched. (3) export_onnx: export fp32 to <stem>_fp32_debug.onnx, then onnxruntime.quantization.quantize_dynamic(QInt8, op_types_to_quantize=['MatMul','Gemm']) to the contract path <out>/models/<area>.onnx; assert no ConvInteger node and size <= 4 MiB. model/train.py unchanged.
Conclusion at the time
REVERTED — metric did not improve (798.53 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.951 — 0.2% of held-out frames give a usable fix, 95.2% are confident and wrong, 4.5% abstain. Median miss 3.01 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$9.64
implementation agent
$0.60
rented GPU — 70 m 11 s at $0.69/hr
$0.81
total
$11.05
by model — claude-fable-5 $9.64 · claude-sonnet-5 $0.60 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 798.5 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9510% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-22T03:17:36 ·
commit 7e6fb3ea1ed9 · artifacts runs/20260722_020725_iter2 ·
took 70 m 11 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.28
Rerun, never scored: unseen-ground confidence calibration + reinstated 3x trunk (iter 7 died on a full disk before training) 83bf925a
The loop discarded this — no improvement under the metric then in force.
training
1.663
57 m 43 s
$5.51
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Two rounds ago we gave the model a bigger brain and its guesses genuinely got better — but the result was thrown out on a technicality: the bar for when the model may say 'no fix, not sure' was tuned on places it had already visited, and the bigger brain is so much more confident on visited ground that the bar landed wildly wrong for new ground — it went nearly silent on the exam. Last round we designed the honest fix — fence off a slice of the map the model never studies and tune the bar there — but the computer's hard drive filled up before training even began, so that experiment was marked 'failed' without ever actually running. The disk problem is fixed; this round simply runs the same experiment for real.
Hypothesis
Exp 27's recorded 1e9 is an infrastructure artifact, not a refutation: its train logs end in OSError [Errno 28] No space left on device inside prepare_realizations of the FIRST area (berlin), before a single optimizer step — metrics.json has an empty areas list and timings.json shows score_s=0, train_wall_s=158. The disk was filled by ~5.7 GB/iteration of per-area training scratch that earlier iterations never purged; the harness fix ('Never persist per-area training scratch') landed right after, and the volume now has 42 GB free against a ~6 GB per-run scratch need, so the crash cause is removed. The scientific hypothesis is therefore still the untested, pre-registered exp-27 one, restated: exp 26's 3x-capacity pretrained trunk delivered real accuracy gains (like-for-like medians down 20-35%: munich morning 536->347 m, frankfurt evening 798->466 m, prignitz morning 450->350 m; deployment gates passed at 3.09 MB / 4.6 ms) but was vetoed solely by the coverage gate, because calibrate_conf_shift tunes the abstention threshold on TRAIN-visited ground: the bigger trunk sharpened the confidence head's separation between visited and unseen ground, conf_shift leapt from 0.2-0.7 to 2.5-3.6 at identical calibration-time keep rates, and eval coverage collapsed to 0.08-0.43 (8 of 24 cells under the 0.2 floor). Calibrating on train blocks fenced off from every training draw measures the confidence distribution the scorer actually faces, so the 0.40 keep floor transfers to eval and the real capacity gain becomes scoreable. Precedent for this rerun: exp 24 retested exp 23 after it was OOM-killed mid-harness and never scored — an unmeasured pre-registered design is not a refuted one.
Method
Verbatim re-registration of exp 27's pre-registered design — no design delta; the only thing that changed between iter 7 and now is the harness disk fix. ONE new mechanism in model/train.py — block-held-out confidence calibration: deterministically hash ~1 in 10 train-split blocks (stable_hash, per area) into a calibration-only set; the per-epoch fresh-draw sampler uses only crops whose 182-px windows touch no calibration block (mirror of the frozen eval-buffer rule, so no calibration pixel is ever trained on); calibrate_conf_shift draws its 400 crops per bucket exclusively from calibration-block crops. MIN_KEEP_RATE=0.40, CAL_CROPS_PER_BUCKET=400, losses, schedule, sampler mechanics unchanged. Alongside, model/model.py reinstates exp 26's pre-registered architecture verbatim (MobileNetV3-Small features[:11] with stride/dilation surgery preserving the 8×8 grid; int8 dynamic quantization of MatMul/Gemm at export), which was refuted only through the calibration artifact this experiment removes.
Conclusion at the time
REVERTED — metric did not improve (1057.68 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.663 — 0.8% of held-out frames give a usable fix, 67.0% are confident and wrong, 32.2% abstain. Median miss 2.78 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$3.59
implementation agent
$1.26
rented GPU — 57 m 43 s at $0.69/hr
$0.66
total
$5.51
by model — claude-fable-5 $3.58 · claude-sonnet-5 $1.26 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.06 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.6631% usablecov 0.68
era Four areas, six lighting buckets · ts 2026-07-22T02:07:02 ·
commit 83bf925a5c35 · artifacts runs/20260722_010919_iter1 ·
took 57 m 43 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.27
Unseen-ground confidence calibration unlocks the reinstated 3×-capacity trunk cc3faa2c
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
training
—
14 m 55 s
$6.71
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last round we gave the model a bigger brain and its guesses genuinely got better — but the result was thrown out on a technicality. The model is allowed to say 'no fix' when unsure, and the rules demand it answers at least 20% of the time. We tune its shyness bar using places from its own training tour, and the bigger brain became so much more confident about places it had already visited than about new ones that the bar landed wildly wrong for new ground: it went nearly silent on the exam. The fix is to fence off a slice of the map the model never gets to study and tune the shyness bar there — on ground exactly as unfamiliar as the exam's. Same bigger brain, bar set honestly.
Hypothesis
Exp 26's capacity scaling delivered its predicted accuracy gain but was vetoed solely by the coverage gate: its deployment gates passed (3.09 MB, 4.6 ms) and its like-for-like medians fell 20–35% (munich morning 536→347 m, frankfurt evening 798→466 m, prignitz morning 450→350 m), yet 8 of 24 cells dropped below the 0.2 coverage floor → 1e9. This iteration's forensics isolate why: calibrate_conf_shift sets the abstention threshold on TRAIN-split crops at locations the model trained on, and the 3× trunk sharpened the confidence head's separation between trained-on and unseen ground — calibration-time keep rates were IDENTICAL between iter 5 and iter 6 (0.40–0.88 per bucket) while conf_shift leapt from 0.2–0.7 to 2.5–3.6 and eval coverage collapsed from 0.25–0.67 to 0.08–0.43. A threshold that keeps 40% of visited ground kept only 8–19% of held-out ground. Calibrating instead on train blocks fenced off from every training draw measures the confidence distribution the scorer actually faces, so the 40% keep floor transfers to eval and the real capacity gain becomes scoreable. (The same mechanism also explains exp 25's near-floor night coverage of 0.25–0.31 — this fix de-risks every future capacity increase, not just this one.)
Method
ONE new mechanism in model/train.py — block-held-out confidence calibration: deterministically hash ~1 in 10 train-split blocks (stable_hash, per area) into a calibration-only set; the per-epoch fresh-draw sampler uses only crops whose 182-px windows touch no calibration block (mirror of the frozen eval-buffer rule, so no calibration pixel is ever trained on); calibrate_conf_shift draws its 400 crops per bucket exclusively from calibration-block crops. MIN_KEEP_RATE=0.40, CAL_CROPS_PER_BUCKET=400, losses, schedule, sampler mechanics unchanged. Alongside, model/model.py reinstates exp 26's pre-registered architecture verbatim (MobileNetV3-Small features[:11] with stride/dilation surgery preserving the 8×8 grid; int8 dynamic quantization of MatMul/Gemm at export), which was refuted only through the calibration artifact this experiment removes.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 797.91 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$5.39
implementation agent
$1.16
rented GPU — 14 m 55 s at $0.69/hr
$0.17
total
$6.71
by model — claude-fable-5 $5.38 · claude-sonnet-5 $1.16 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-21T23:34:48 ·
commit cc3faa2c230b · artifacts runs/20260721_231953_iter7 ·
took 14 m 55 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.26
Deployment-envelope capacity scaling: 3× pretrained trunk depth paid for by int8 FC-head storage 4fb65e2a
The loop discarded this — no improvement under the metric then in force.
architecture
1.273
69 m 41 s
$10.18
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last round we gave the model three times longer to study and it finished everything it could hold — yet scores barely moved. That means its brain is full: it isn't failing to study, it's out of room. The UAV's flight computer caps the model file at 4 MB and we were already near the cap, but we found that the biggest part of the file — a huge table of connection strengths — works just as well stored as cheap 1-byte numbers instead of exact 4-byte ones (we measured: answers move by ~7 meters on errors of ~700). The space that trick frees pays for a three-times-bigger image-understanding brain, borrowed from the same well-trained library the model already uses.
Hypothesis
The binding constraint is model capacity, demonstrated by exp 25's own pre-registered fork: convergence-scaled training drove the loss to a genuine plateau (berlin 6.29→4.78, flat for the last 5 epochs at near-zero LR; prignitz 4.51) yet the metric moved only 5.2% (839.12→797.91 m) against the 10–25% predicted if optimization were binding — and train-split and eval-split unfiltered medians are now EQUAL, so the model cannot even fit its training locations. A converged, non-memorizing, underfitting model has exactly one lever left: make it bigger. The only prior capacity experiment (exp 8, reverted) scaled a FROM-SCRATCH encoder in the pre-pretrained era; exp 11 then showed pretrained features are what carry this task, and pretrained capacity has never been scaled since — the trunk has sat at 190k params (MobileNetV3-Small features[:9]) for 15 iterations because the 4 MiB deployment gate appeared full (3.30 MB). Fresh probes (runs/_probe_iter6_quant2.py, _probe_iter6_export.py) break that impasse: int8 dynamic quantization of ONLY the FC heads (which hold 727k of the 823k params) is metrically inert on the current best model — median decode shift 0.001 uv ≈ 7 m against 650–800 m medians, conf shift 0.006, latency fine — while shrinking the export 3.30→1.44 MB. The freed bytes exactly pay for tripling the pretrained trunk: features[:9]→[:11] (190k→576k ImageNet-pretrained params, 48→96 output channels), with block 9's stride-2 depthwise run at stride 1 and block 10's depthwise dilated 2 (the standard DeepLab trick) so the 8×8 feature grid every kept head reads is preserved and all pretrained weights load with unchanged shapes. Dry-run export of the full candidate: 3,091,446 bytes and 4.8 ms single-thread — both frozen gates pass with margin.
Method
model/model.py: (a) trunk builder loads MobileNetV3-Small features[:11] from a new pretrained snapshot model/pretrained/mnv3s_features10.pt, sets features[9]'s depthwise stride (2,2)→(1,1) and features[10]'s depthwise dilation→2/padding→4 — output 96×8×8; all heads re-width automatically via the existing shape probe. (b) export_onnx exports fp32 to a temp file then writes the final artifact with onnxruntime quantize_dynamic(op_types=['MatMul','Gemm'], QInt8) — conv layers stay fp32. model/train.py: only the init-strategy log string changes. Sampler, losses, decode, calibration, EPOCH_MULT=3, cosine schedule: all untouched; the two new pretrained blocks land in the existing 1e-4 trunk LR group automatically.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 797.91 m); change discarded
Re-measured on today's ruler
Mission score 1.273 — 0.2% of held-out frames give a usable fix, 27.5% are confident and wrong, 72.2% abstain. Median miss 3.22 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$8.69
implementation agent
$0.68
rented GPU — 69 m 41 s at $0.69/hr
$0.80
total
$10.18
by model — claude-fable-5 $8.69 · claude-sonnet-5 $0.68 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.2730% usablecov 0.28
era Four areas, six lighting buckets · ts 2026-07-21T23:18:46 ·
commit 4fb65e2a19d4 · artifacts runs/20260721_220905_iter6 ·
took 69 m 41 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.25
Convergence-scaled training: 3× optimizer steps with cosine LR decay under the kept fresh-draw sampler 7f8a2986
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.911 — worse than silence.
training
1.911
63 m 08 s
$9.15
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The previous improvement gave the model fresh flashcards every study pass so it could no longer cram answers — but we kept ringing the end-of-class bell at the same early time, set back when cramming made classes short. Its grades were still climbing when the bell rang. This experiment simply lets it study three times longer, and — like slowing down smoothly before parking — makes each learning step gentler toward the end so what it learned settles in place. The model that flies is completely unchanged; only the length and pacing of school changes.
Hypothesis
The binding constraint is no longer the held-out-location generalization gap — it is plain underfitting, created as a side effect of kept exp 20 and never addressed because the training schedule has been frozen since bootstrap. Evidence from a fresh read-only probe of the kept exp-20 model (runs/_probe_iter5_evalcells.py): the ~3× train-vs-eval gap that exps 18/19/22/23/24 all attacked is GONE — berlin midday train-split 1014 m vs eval-split 1017 m unfiltered median, prignitz midday 580 vs 673 m (pre-exp-20 probes measured 267–400 m on train). Exp 20's single-exposure fresh draws removed memorization as a fitting strategy, which turned the 8-epoch constant-LR budget — sized in the bootstrap era, when 8 passes over one frozen tensor sufficed to memorize — into a truncation: the training loss is still descending ~0.065/epoch at cutoff (berlin 6.29→5.11 over 8 epochs, no plateau) at a never-decayed Adam LR (head 1e-3, trunk 1e-4), and unfiltered errors are flat-mediocre on BOTH splits (train-split medians 580–1889 m) — the signature of an underconverged model, not a transfer failure. This also reinterprets the three consecutive reverts (22, 23/24): their auxiliary losses competed for the same ~4,500 undertrained optimizer steps, diluting an optimization budget that was already the bottleneck. Per the plateau rule this leaves that mechanism family entirely for training-scale — the one plateau-list family never tried (exp 7 scaled data, never optimization). The same probe also tested and rejected an output-side suspicion: the decode does NOT structurally avoid the never-trained eval-block cells (P(decode in eval block) = 0.13–0.21 vs 0.20 base rate), so a head redesign is not the leading term. The change: 3× the optimizer steps (24 fresh-draw epochs from the harness's --epochs 8) with per-step cosine LR annealing to zero, so the kept sampler is finally trained to convergence — near-full coverage of the ~45k train locations per bucket, each still seen only ~1–2×, and a settled endpoint instead of a noisy constant-LR stop.
Method
model/train.py ONLY (model/model.py untouched — inference path, losses, decode, calibration, export all identical). (1) Module constant EPOCH_MULT = 3; train_area runs total_epochs = epochs × EPOCH_MULT sampled epochs (harness passes --epochs 8 → 24), with the per-epoch fresh-draw sample_epoch and the epoch_rng = default_rng([seed, epoch]) formula unchanged — epochs 8..23 automatically get fresh independent draws. (2) torch.optim.lr_scheduler.CosineAnnealingLR stepped once per optimizer step, T_max = precomputed total step count (6 buckets × min(max_crops_per_bucket, n_train_crops) crops/epoch, batch 64, × total_epochs), eta_min 0 — both param groups (trunk 1e-4, head 1e-3) anneal proportionally. Per-epoch memory profile is byte-identical to the kept baseline (sample_epoch untouched — the exp-23 OOM lesson); wall time ≈3× (~19 → ~58 min for the 4 parallel areas).
Mission score 1.911 — 0.2% of held-out frames give a usable fix, 91.2% are confident and wrong, 8.5% abstain. Median miss 3.06 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$7.90
implementation agent
$0.52
rented GPU — 63 m 08 s at $0.69/hr
$0.73
total
$9.15
by model — claude-fable-5 $7.89 · claude-sonnet-5 $0.52 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 797.9 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9110% usablecov 0.92
era Four areas, six lighting buckets · ts 2026-07-21T22:07:44 ·
commit 7f8a298620e4 · artifacts runs/20260721_210436_iter5 ·
took 63 m 08 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py251 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current approach: DSNT-style spatial probability field. The conv stack'sglobal feature maps to logits over a GRID_K x GRID_K grid of map cells; thepredicted coordinate is the differentiable soft-argmax (probability-weightedexpected value) over fixed cell centers, trained with cross-entropy againstGaussian-smoothed cell targets plus an expected-coordinate L2 term. Unlikehard cell classification + offset regression (archived exp 5, reverted),there is no argmax quantization and no decoupled head — the decode used atinference is exactly what the loss optimizes.Exp 10: the field head reads a spatial layout code alongside the GAPdescriptor. GAP alone is a bag-of-textures — it destroys WHERE features sitin the crop, which is what distinguishes lookalike districts. A 1x1 convsqueezes the 8x8x128 feature map to 8 channels; the flattened 512-d layoutcode is concatenated with the 128-d GAP vector before the logits FC, makingthe head a low-rank linear read of the full feature map (a strict supersetof the old GAP-only head).Exp 11: the from-scratch 4-conv stack is replaced by an ImageNet-pretrainedMobileNetV3-Small trunk (torchvision, BSD-3-licensed; first 9 feature blocks= stem + 8 inverted-residual blocks, 190k params, stride 16 -> the same 8x8spatial grid the exp-10 head already reads, now 48 channels instead of 128).Weights load strict from model/pretrained/mnv3s_features8.pt (verbatimIMAGENET1K_V1 tensors). ImageNet mean/std normalization is baked intoforward() as buffers so the ONNX input contract ([0,1] float, no externalpreprocessing) is unchanged. The layout-squeeze + GAP + field head areotherwise identical to exp 10, only re-widthed for 48 input channels.Exp 12: exp 11 was kept and, for the first time in the project's history,produced a clear per-lighting-bucket gradient instead of a flat errorprofile -- night is worst in all four development areas (e.g. Munich night2010 m vs Munich midday 1381 m), meaning the single shared field head isbeing asked to serve both a well-lit regime the pretrained features handlewell and a low-light regime it does not. A second, cheap "dark expert" fieldhead (Linear on the 48-d GAP descriptor only, 50k params -- no layout code,since the spatial layout signal is assumed to be the least reliable part ofthe descriptor once texture is mostly gone) is blended with the existinglayout-aware head via a per-example learned gate. The gate reads the crop'sown raw-pixel mean brightness plus the 48-d GAP descriptor -- both computedfrom the frame itself, so the frozen (frame in) -> (lat, lon, conf) contractis untouched -- through a tiny 2-layer MLP into a sigmoid blend weight. Thisis a budget-safe MoE-lite stand-in for a full dispatcher+specialist design(a second full 560->1024 head would cost ~2.2 MB, blowing the 4 MiB ONNXgate on top of exp 11's 2.94 MiB); the cheap dark head + gate adds ~200 KB.Exp 14: expected-value soft-argmax over the full field returns theposterior MEAN, so any diffuse or multimodal residual mass shrinks everyprediction toward the map centroid -- the error profile after exp 10-12(medians 1.0-1.9 km vs. a ~3.2 km center-guess floor, mean/median ratioonly ~1.2 in every area x bucket cell) is the shrinkage signature ofexactly this effect, not heavy-tailed mode-commitment error. Decoding fromsoftmax(DECODE_BETA * logits) instead sharpens the field before thesoft-argmax, committing to its dominant mode while leaving a uniform fieldexactly uniform (so an untrained model still decodes near the map center --the same bounded-downside floor every kept experiment has relied on). Thefield itself still trains on the same calibrated Gaussian-bump CE attemperature 1 (loss_fn is unchanged); only the coordinate L2's decode issharpened, so training now grades the committed answer that would fly.Exp 15: the frozen scorer already implements selective prediction (conf <0.3 abstains, coverage >= 0.2 required per cell) but coverage has been1.000 in every logged cell -- the confidence head never learned to predictanything but "always sure". It is replaced with a calibrated hit predictorover the DECODE'S OWN SHAPE (sharpened-field peak mass, normalized fieldentropy, and the distance between the sharpened and unsharpened decodes --all detached, so no confidence gradient reaches the trunk/heads/gate),trained to predict whether the committed decode lands withinGOOD_ERR_UV. A registered conf_shift buffer (calibrated post-training bytrain.py, baked into the ONNX export) converts that hit probability intothe frozen 0.3 abstention threshold with a per-bucket >= 40% keep floor.Exp 16: the frozen eval set is heading-agnostic (each held-out crop gets adeterministic random rotation), but training shows each location at exactlyone random heading, frozen for the whole run -- so at eval time the modelmust recognize places across up to 180 degrees of heading mismatch with ahead that has no rotational structure. Teaching invariance by data (freshrotations every epoch, exp 6) was tried and reverted -- it made thememorization task harder without helping. Instead the field is now madeinvariant by construction: the crop and its three exact 90-degree pixelrotations all pass through the same trunk/heads, and the four resultingfield logit maps are averaged (a geometric-mean vote) before the unchangedsharpened decode. One of the four evaluated views always lies within 45degrees of the one trained heading, and a lookalike cell that only fires atone heading is multiplicatively suppressed by the other three."""import numpy as np
import torch
import torch.nn as nn
from pathlib import Path
from torchvision.models import mobilenet_v3_small
GRID_K =32# 32x32 cells over the map (~220 m cells on a ~7 km area)
TARGET_SIGMA_CELLS =1.5# Gaussian soft-target spread, in cell units
DECODE_BETA =3.0# inverse-temperature sharpening of the decode distribution (exp 14): softmax(β·logits) commits the soft-argmax to the dominant mode instead of the field mean; a uniform field stays uniform, so the untrained decode still starts at the map center
GOOD_ERR_UV =0.05# confidence 'hit' radius in normalized map units (~350 m on a ~7 km area, ~1.6 grid cells)
PRETRAINED_TRUNK_PATH = Path(__file__).parent /"pretrained"/"mnv3s_features8.pt"
IMAGENET_MEAN =(0.485,0.456,0.406)
IMAGENET_STD =(0.229,0.224,0.225)def _grid_centers(k: int)-> tuple[torch.Tensor, torch.Tensor]:"""Flat [k*k] tensors of cell-center u and v (cell index = gy * k + gx)."""
centers =(torch.arange(k, dtype=torch.float32)+0.5)/ k
return centers.repeat(k), centers.repeat_interleave(k)def _build_pretrained_trunk()-> nn.Module:"""ImageNet-pretrained MobileNetV3-Small stem + first 8 inverted-residual blocks (torchvision, BSD-3). 128x128 in -> 48x8x8 out (stride 16)."""
trunk = mobilenet_v3_small(weights=None).features[:9]
state_dict = torch.load(PRETRAINED_TRUNK_PATH, map_location="cpu", weights_only=True)
stripped ={k[len("features."):]: v for k, v in state_dict.items()}
trunk.load_state_dict(stripped, strict=True)return trunk
def _c4_stack(x):"""[N,3,H,W] -> [4N,3,H,W]: x with its three 90-degree pixel rotations (exact permutations via transpose+flip; rotation-major block order)."""
r90 = x.transpose(2,3).flip(2)
r180 = x.flip(2).flip(3)
r270 = x.transpose(2,3).flip(3)return torch.cat([x, r90, r180, r270], dim=0)class TinyLocNet(nn.Module):"""ImageNet-pretrained MobileNetV3-Small trunk (48x8x8) -> {GAP descriptor + 1x1-squeezed spatial layout code} -> map-cell probability field -> soft-argmax (u, v), plus a separate sigmoid conf head. Exp 12: the field logits are a per-example gated blend of two experts -- the existing layout-aware head (GAP + layout code) and a cheap GAP-only "dark expert" -- so the network can compute a different effective cell-scoring function for low-light crops without duplicating the expensive layout-aware FC. The gate is a tiny MLP over [raw-pixel mean brightness, GAP descriptor], both derived from the input frame alone. """def __init__(self, grid_k: int = GRID_K, layout_ch: int =8, gate_hidden: int =16):
super().__init__()self.grid_k = grid_k
self.features = _build_pretrained_trunk()self.register_buffer("norm_mean", torch.tensor(IMAGENET_MEAN).view(1,3,1,1))self.register_buffer("norm_std", torch.tensor(IMAGENET_STD).view(1,3,1,1))with torch.no_grad():
probe =self.features(torch.zeros(1,3,128,128))
feat_ch, fmap_hw = probe.shape[1], probe.shape[2]self.layout_squeeze = nn.Conv2d(feat_ch, layout_ch,1)self.loc_logits = nn.Linear(feat_ch + layout_ch * fmap_hw * fmap_hw,
grid_k * grid_k)self.dark_logits = nn.Linear(feat_ch, grid_k * grid_k)self.gate = nn.Sequential(
nn.Linear(feat_ch +1, gate_hidden), nn.ReLU(),
nn.Linear(gate_hidden,1),)self.conf_head = nn.Sequential(nn.Linear(feat_ch +3,32), nn.ReLU(), nn.Linear(32,1))self.register_buffer("conf_shift", torch.zeros(1))
cell_u, cell_v = _grid_centers(grid_k)self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward(self, x, return_logits: bool =False):
n = x.shape[0]
lum = x.mean(dim=(1,2,3)).unsqueeze(1)# raw-pixel brightness, [N,1] in [0,1], rotation-invariant
x4 = _c4_stack(x)
fmap =self.features((x4 -self.norm_mean)/self.norm_std)
f4 = fmap.mean(dim=(2,3))
layout4 =self.layout_squeeze(fmap).flatten(1)
lum4 = lum.repeat(4,1)
bright_logits4 =self.loc_logits(torch.cat([f4, layout4], dim=1))
dark_logits4 =self.dark_logits(f4)
g4 = torch.sigmoid(self.gate(torch.cat([lum4, f4], dim=1)))
logits4 =(1- g4)* bright_logits4 + g4 * dark_logits4 # [4N, K*K] per-turn gated blend
logits = logits4.reshape(4, n,-1).mean(dim=0)# C4 logit average (geometric-mean vote)
f = f4.reshape(4, n,-1).mean(dim=0)# averaged GAP descriptor for the conf head
p = torch.softmax(DECODE_BETA * logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)
p1 = torch.softmax(logits, dim=1)# unsharpened field
u1 =(p1 *self.cell_u).sum(dim=1, keepdim=True)
v1 =(p1 *self.cell_v).sum(dim=1, keepdim=True)
pd = p.detach()
peak = pd.max(dim=1, keepdim=True).values # sharpened-field peak mass
ent =-(pd * torch.log(pd +1e-9)).sum(dim=1, keepdim=True)/ float(np.log(self.grid_k *self.grid_k))
gap = torch.sqrt((u.detach()- u1.detach())**2+(v.detach()- v1.detach())**2+1e-12)
z =self.conf_head(torch.cat([f.detach(), peak, ent, gap], dim=1))
conf = torch.sigmoid(z -self.conf_shift)
out = torch.cat([u, v, conf], dim=1)if return_logits:return out, logits
return out
def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, logits: torch.Tensor,
target_uv: torch.Tensor)-> torch.Tensor:"""CE against a Gaussian-smoothed cell target + expected-coord L2 + conf BCE."""
k = GRID_K
cell_u, cell_v = _grid_centers(k)
cell_u, cell_v = cell_u.to(logits.device), cell_v.to(logits.device)
du =(cell_u[None,:]- target_uv[:,0:1])* k # distance in cell units
dv =(cell_v[None,:]- target_uv[:,1:2])* k
g = torch.exp(-(du **2+ dv **2)/(2* TARGET_SIGMA_CELLS **2))
g = g / g.sum(dim=1, keepdim=True)
ce =-(g * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# conf is now a calibrated hit predictor for selective prediction --# the frozen scorer treats conf < 0.3 as abstention and requires# coverage >= 0.2 per cell.
good =(coord_err.sqrt()< GOOD_ERR_UV).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return ce + coord_loss +0.3* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py258 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Training scale (exp 7): 6,000 of the ~45k enumerable train locations perbucket (was 800 / ~1.8%, which left a quarter of the 32x32 field cells withzero training example in any given lighting bucket). The training tensor isheld as uint8 and converted to float per minibatch — 36k float32 crops wouldbe ~7 GB; uint8 is ~1.8 GB.Exp 11: the encoder is now an ImageNet-pretrained trunk (model.py), fine-tunedgently rather than trained from scratch — trunk params use a 10x lower LRthan the freshly-initialized head params, so early large head gradientsdon't wash out the transferred features before they adapt.Exp 12: model.py adds a gated dark-expert field head; its new params (darkhead + gate MLP) are fresh-initialized and fall into the existing "head"param group here unchanged, so they train at the same 1e-3 LR as the restof the head — no changes needed to this file's training loop.Exp 15: after the epoch loop, the new conf head (model.py) is calibrated onfresh-rotation TRAIN-split crops per lighting bucket so that the frozenscorer's fixed conf >= 0.3 abstention threshold keeps >= 40% of crops inevery bucket (double the scorer's 0.2 coverage floor) before ONNX export;the resulting conf_shift buffer is exported with the model.Exp 17: night is the binding constraint everywhere, and a stored nightrender freezes one seeded roll of the relight sim's stochastic nuisances(sensor noise, lamp thinning) that differs roll-to-roll by ~half the image'scontent -- so the 1024-way head was memorizing roll-specific texture thatcan't transfer to held-out locations. Each bucket's training crops are nowdrawn from three seeded realizations of the frozen pipeline.relight.relightfunction (the stored eval-matched render plus two fresh re-renders), so onlyseed-stable structure stays discriminative between locations. Eval renders,model, losses, decode, and calibration are unchanged.Exp 20: per-epoch location resampling. The kept trainer built ONE tensor --6,000 locations per bucket, each at one frozen heading and one frozen relightrealization -- and passed over it every epoch, making per-crop memorizationthe cheapest way down the training loss even though ~39k other enumerabletrain locations per bucket were never seen. Locations, headings, andrealization assignment are now redrawn fresh at the start of every epoch(same per-epoch crop count and gradient-step count), raising distinctlocations seen per bucket to ~30k over an 8-epoch run, each seen only ~1-2times and never twice identically. Model, losses, decode, and calibrationare unchanged.Exp 25: convergence-scaled training. A read-only probe of the kept exp-20model showed train-split and eval-split unfiltered medians both ~1 km --the fresh-draw sampler removed memorization, but the 8-epoch constant-LRschedule (sized in the bootstrap era, when a few passes over one frozentensor sufficed to memorize) was cutting training off while loss was stillfalling ~0.065/epoch. Training now runs 3x the epochs (EPOCH_MULT) with aper-step cosine LR anneal to zero, so the same fresh-draw sampler isfinally trained to convergence instead of truncated mid-descent.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import rasterio
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta, stable_hash
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
from pipeline.relight import relight
CAL_CROPS_PER_BUCKET =400
MIN_KEEP_RATE =0.40# per-bucket keep floor at calibration (2x the scorer's 0.2 coverage floor)
SCORER_CONF_THRESHOLD =0.3# mirrors pipeline/score.py's frozen CONF_THRESHOLD; restated here, not imported
TRAIN_REALIZATIONS =3# exp 17: seeded relight re-renders per bucket, incl. the stored eval-matched one
EPOCH_MULT =3# exp 25: convergence scaling -- the harness's --epochs is an outer budget fixed# at bootstrap; the exp-20 fresh-draw sampler needs ~3x the steps to converge# (loss still falling ~0.065/epoch at the old cutoff)def prepare_realizations(area: str, data_dir: Path, out_dir: Path)-> Path:"""One-time render of each bucket's extra relight realizations (exp 17's seeded scheme) to <out_dir>/renders/, so per-epoch sampling only needs to load cached PNGs instead of re-running the relight sim every epoch."""
renders_dir = Path(out_dir)/"renders"
renders_dir.mkdir(parents=True, exist_ok=True)
meta = load_meta(area, data_dir)with rasterio.open(area_dir(area, data_dir)/"reference.tif")as src:
ref = src.read().transpose(1,2,0)# HxWx3 uint8for bucket in LIGHTING_BUCKETS:for r in range(1, TRAIN_REALIZATIONS):
img = relight(ref, LIGHTING_BUCKETS[bucket], meta["gsd_m"],
stable_hash(f"{area}:{bucket}:trainreal:{r}"))
Image.fromarray(img).save(renders_dir / f"{bucket}_r{r}.png")del img
del ref
return renders_dir
def sample_epoch(area: str, meta: dict, crops: list[dict], renders_dir: Path,
data_dir: Path, max_crops_per_bucket: int, rng):"""Fresh draw of locations, headings, and realization assignment for one epoch (exp 20): only cues that transfer between locations reduce the training loss, since no crop is seen twice identically."""
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for r in range(TRAIN_REALIZATIONS):
part = picks[r::TRAIN_REALIZATIONS]if r ==0:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))else:
img = np.asarray(Image.open(renders_dir / f"{bucket}_r{r}.png"))for i in part:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))del img
x = torch.from_numpy(np.stack(xs))# uint8 NxHxWx3; float-converted per batch
y = torch.tensor(ys, dtype=torch.float32)return x, y
def calibrate_conf_shift(model, area: str, data_dir: Path, device: str, rng)-> dict:"""Set model.conf_shift so the scorer's fixed 0.3 threshold keeps >= MIN_KEEP_RATE of crops in every lighting bucket (TRAIN split only)."""
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
model.eval()
z_by_bucket ={}with torch.no_grad():for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(CAL_CROPS_PER_BUCKET, len(crops)),
replace=False)
xs =[]for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
xb_all = torch.from_numpy(np.stack(xs))
confs =[]for i in range(0, len(xb_all),64):
xb = xb_all[i:i +64].to(device).permute(0,3,1,2).contiguous().float().div_(255.0)
out = model(xb)
confs.append(out[:,2].cpu().numpy())
conf_values = np.concatenate(confs)
c = np.clip(conf_values,1e-6,1-1e-6)
z_by_bucket[bucket]= np.log(c /(1- c))
t_per_bucket ={b: float(np.quantile(z,1.0- MIN_KEEP_RATE))for b, z in z_by_bucket.items()}
T = min(t_per_bucket.values())with torch.no_grad():
model.conf_shift.fill_(T - float(np.log(SCORER_CONF_THRESHOLD /(1.0- SCORER_CONF_THRESHOLD)))-1e-4)return{"conf_shift": float(model.conf_shift.item()),"cal_logit_threshold": float(T),"cal_keep_rate_per_bucket":{b: float(np.mean(z > T -1e-4))for b, z in z_by_bucket.items()},}def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
total_epochs = epochs * EPOCH_MULT
n_per_epoch =6* min(max_crops_per_bucket, len(crops))
steps_per_epoch =(n_per_epoch +63)//64
total_steps = steps_per_epoch * total_epochs
renders_dir = prepare_realizations(area, data_dir, out_dir)
model = build_model().to(device)
trunk_params = list(model.features.parameters())
trunk_ids ={id(p)for p in trunk_params}
head_params =[p for p in model.parameters()if id(p)notin trunk_ids]
opt = torch.optim.Adam([{"params": trunk_params,"lr":1e-4},{"params": head_params,"lr":1e-3},])
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=total_steps, eta_min=0.0)
n =0for epoch in range(total_epochs):
epoch_rng = np.random.default_rng([seed, epoch])
x, y = sample_epoch(area, meta, crops, renders_dir, data_dir,
max_crops_per_bucket, epoch_rng)
n = len(x)
print(f"[{area}] epoch {epoch +1}/{total_epochs}{n} crops, device={device}")
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb = x[idx].to(device).permute(0,3,1,2).contiguous().float().div_(255.0)
yb = y[idx].to(device)
out, logits = model(xb, return_logits=True)
loss = loss_fn(out, logits, yb)
opt.zero_grad(); loss.backward(); opt.step(); sched.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{total_epochs} loss={np.mean(losses):.4f}")del x, y
cal = calibrate_conf_shift(model, area, data_dir, device, rng)
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))
info ={"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,# §9: log init strategy per experiment"init":"pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..8] (torchvision, BSD-3)","train_realizations": TRAIN_REALIZATIONS,"epoch_location_resampling":True,"total_epochs_run": total_epochs,"epoch_mult": EPOCH_MULT,"lr_schedule": f"cosine-per-step to 0 over {total_steps} steps",}
info.update(cal)return info
def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=6000)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
2.24
Daytime-redraw auxiliary, rerun: exp 23 was OOM-killed mid-harness, never scored — retest it with a memory-lean epoch sampler 5794e840
The loop discarded this — no improvement under the metric then in force.
loss
1.953
42 m 59 s
$7.56
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Last iteration we designed a promising exercise for the network: from its internal impression of a dark, noisy night photo, it must also sketch what that exact spot looks like in clean daylight — like a student proving they truly saw through the darkness by redrawing the street in daytime colors. The sketching module is thrown away before anything flies, so the aircraft carries nothing extra. But the experiment never actually ran: the training computer ran out of memory and the operating system silently killed one of the four training jobs, so the scoreboard recorded a bogus worst-possible number. This iteration re-runs the exact same exercise after fixing the memory waste (the training data was being copied twice for no reason) — now the whole thing uses LESS memory than the setup that has worked for weeks, and the idea finally gets its fair test.
Hypothesis
Exp 23's hypothesis was never tested, and this iteration retests it rather than abandoning an untried mechanism. The forensic record is unambiguous: loop.sh line 203 logged 'Killed' (SIGKILL) for the berlin training process, berlin's log is 0 bytes with no model exported, while prignitz/munich/frankfurt trained to completion under the identical code with healthy final losses (4.78-5.05, vs 4.77-5.11 in the kept exp-20 run) and normal calibration keep-rates — so the 1e9 in the DB is the scorer's missing-model sentinel, not a measured error. The recorded REVERTED at 1e9 is an infrastructure artifact, and leaving it unchallenged would poison the history: future iterations would read the reconstruction-auxiliary family as refuted when it was merely crashed. Cause of death: the four areas train IN PARALLEL inside a constrained cgroup (loop.sh's own comment cites the 'small cgroup quota'), and the kept sampler already peaks at ~3.6 GB transient per process (a 36k-crop uint8 list ~1.77 GB plus its np.stack copy ~1.77 GB); exp 23's implementation added a per-process reference raster (~0.14 GB) and a 36k x 64x64x3 uint8 target list plus ITS stack copy (~0.9 GB), pushing four concurrent processes over the quota — the kernel OOM-killer shot the first process (berlin), which freed enough memory for the remaining three to finish, exactly the observed pattern. A SIGKILLed python loses its ~1 KB of block-buffered prints, which is why the log is empty. The scientific hypothesis is unchanged from exp 23 (library L1, flavor B): the binding constraint is the held-out-location generalization gap (train-split 267-400 m vs eval-split 708-1153 m median, ~3x, every bucket), the trunk still passes lighting nuisance into the descriptor because its ImageNet features were never adapted to the sim's night statistics, and a training-only decoder that must redraw the clean daytime reference crop (pixel-aligned pairs free from the frozen sim; same cx/cy/angle) from the encoder's 8x8x48 feature grid can only succeed via features that cancel lighting and noise while preserving ground structure — canonicalization inside the encoder at zero inference cost, location-generic by construction (unlike reverted exp 22's per-patch place labels) and structure-preserving (unlike refuted exp 9's collapsible contrastive objective). The one new engineering fact this rerun adds: the epoch sampler is rewritten to preallocate its uint8 tensors and fill them in place, eliminating the list+stack doubling — peak sampler RSS drops to ~2.4 GB per process INCLUDING the new target tensor and reference raster, ~1.2 GB BELOW the kept baseline that has survived 20+ iterations, so the rerun sits inside a proven memory envelope with margin. The preallocation is numerically inert: identical RNG stream, byte-identical training tensors.
Method
ONE scientific change, identical to exp 23's pre-registration: attach a training-only reconstruction decoder (~55k params; 1x1 conv 48->64, then 3x [nearest-upsample x2 + 3x3 conv + ReLU] 64->48->32->24, final 1x1 conv ->3 + sigmoid; 8x8x48 in, 64x64x3 out) to the identity-turn feature map via a new return_feat flag on TinyLocNet.forward; add LAMBDA_RECON=0.3 * L1(decoder(feat), daytime_target_64px) to the loss; decoder params train at head LR 1e-3 and are discarded before export. Plus the OOM fix that lets it actually run: model/train.py's sample_epoch is rewritten to preallocate np.empty uint8 arrays for crops and daytime targets and fill them by running index (no list-of-arrays, no np.stack copy), loading the daytime reference raster once per run and reusing the already-drawn per-crop angle for the pixel-aligned target (zero new RNG draws). Both epoch prints gain flush=True so a future SIGKILL can no longer leave an empty log. Exported graph, decode, confidence, calibration, sampling distribution, epochs, and LRs are all byte-identical to the current best.
Conclusion at the time
REVERTED — metric did not improve (915.68 m vs best 839.12 m); change discarded
Re-measured on today's ruler
Mission score 1.953 — 0.0% of held-out frames give a usable fix, 95.2% are confident and wrong, 4.8% abstain. Median miss 2.97 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$6.09
implementation agent
$0.97
rented GPU — 42 m 59 s at $0.69/hr
$0.49
total
$7.56
by model — claude-fable-5 $6.09 · claude-sonnet-5 $0.97 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 915.7 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9530% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-21T21:02:57 ·
commit 5794e8405c98 · artifacts runs/20260721_201958_iter4 ·
took 42 m 59 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.23
Daytime-redraw auxiliary: a throwaway decoder must reconstruct the clean daytime crop from the encoder's features adfc8b91
Failed outright: training or scoring crashed, it broke a deployment limit, or it never produced a single usable fix.
loss
—
42 m 08 s
$6.88
GATED FAIL
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The network learns to recognize places from noisy night photos. We gave it one extra practice exercise: from its internal impression of a scene, it must also sketch what that exact spot looks like in clean daylight — like a student proving they truly saw through the darkness by redrawing the street in daytime colors. The sketching module is thrown away before anything flies, so the aircraft carries nothing extra. What remains is a network whose mental image of the ground ignores darkness and sensor grain — and if its inner picture is always the daytime one, recognizing the place gets easier in every lighting condition at once.
Hypothesis
The binding constraint is still the held-out-location generalization gap the exp-18 probe measured (train-split crops 267-400 m median vs eval-split 708-1153 m, ~3x, in every bucket), and after exp 20 the error profile is flat across lighting buckets and areas — flat but mediocre (best 839.12 m vs the ~20 m target). The trunk is the shared weak link that flatness points at: every gradient it receives comes from ONE whole-crop place grade per crop at a gentle 1e-4 LR, while its ImageNet-pretrained features were never adapted to the sim's night-time statistics (sensor gain noise, lamp thinning, washed-out color are far outside ImageNet's input distribution). So lighting nuisance still reaches the descriptor, and the 1024-way head must generalize jointly across location x lighting with only ~30k single-exposure examples (exp 20) to do it. This experiment builds on library entry L1, flavor B (training-only reconstruction auxiliary): a small throwaway decoder must redraw the clean daytime reference crop — same location, same heading, pixel-aligned pairs free from the frozen sim — from the encoder's 8x8x48 feature grid, with an L1 loss at 64x64 weighted 0.3, then be deleted before export. All six lighting renders of a place share ONE daytime answer, so the cheapest way down this loss is features that cancel lighting and noise while preserving ground structure: canonicalization inside the encoder, at zero inference cost. Two mechanisms should move the Sec-6 metric: (a) descriptor variance across buckets collapses, so the head's capacity and exp 20's fresh location draws concentrate on place discrimination alone instead of place x lighting; (b) unlike reverted exp 22, whose dense auxiliary was per-patch PLACE classification — 64 more memorization targets of exactly the kind the transfer gap punishes — night-to-day redrawing is location-generic (the same inversion applies everywhere on the map, and under exp 20's sampling no location is seen often enough to memorize its output), so its gradients transfer to never-trained eval terrain by construction. It is also materially different from refuted exp 9 (cross-lighting NT-Xent): that was a contrastive ranking objective on the GLOBAL descriptor of the old from-scratch encoder, satisfiable by collapsing information; a dense generative target must PRESERVE structure per pixel, and it acts on today's pretrained trunk.
Method
ONE change: attach a training-only reconstruction decoder to the encoder. model/model.py gains ReconDecoder (~55k params: 1x1 conv 48->64 then 3x [nearest-upsample x2 + 3x3 conv + ReLU] 64->48->32->24, final 1x1 conv ->3 + sigmoid; 8x8x48 in, 64x64x3 out), build_recon_decoder(), constants RECON_SIZE=64 / LAMBDA_RECON=0.3, and an optional return_feat flag on TinyLocNet.forward exposing the identity-turn feature map. model/train.py loads the daytime reference raster once per area, samples for every training crop the pixel-aligned clean reference crop (same cx/cy/angle) downsampled to 64x64, and adds LAMBDA_RECON * L1(decoder(feat), target) to the existing loss. Decoder params train at the head LR (1e-3) and are discarded — never exported. Everything else (architecture, decode, confidence, calibration, sampling, epochs, LRs, ONNX export) is untouched; the exported graph is byte-identical in shape to the current best.
Conclusion at the time
REVERTED — metric did not improve (1000000000.0 m vs best 839.12 m); change discarded
Not on today's ruler
It failed outright and left no scoreable result: training or scoring crashed, the model broke a deployment limit, or it never produced a single usable fix. (Models failed only by the old coverage floor, retired 2026-11-01, are re-scored instead.)
What it cost
design agent
$5.66
implementation agent
$0.74
rented GPU — 42 m 08 s at $0.69/hr
$0.48
total
$6.88
by model — claude-fable-5 $5.65 · claude-sonnet-5 $0.74 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring —. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-21T20:18:28 ·
commit adfc8b919d19 · artifacts runs/20260721_193619_iter3 ·
took 42 m 08 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.22
Train-only per-patch place supervision: every feature cell places its own patch, the flying decode is untouched 9df5c839
The loop discarded this — no improvement under the metric then in force.
loss
1.916
40 m 44 s
$8.67
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model got one graded question per practice photo: 'where is the CENTER of this photo on the map?' A student can pass that test by memorizing whole photos -- which fails on parts of the city held back from practice. Now, during practice only, every small tile of the photo also gets its own graded question: 'where does THIS tile sit on the map?' -- 64 grades per photo instead of one. To score well the network must learn what roads, buildings and field edges actually look like from above, knowledge that transfers to never-practiced places. On the real flight nothing changes: the extra quiz machinery is thrown away before takeoff and the aircraft carries exactly the same network as before.
Hypothesis
The binding constraint is still the held-out-location generalization gap the exp-18 probe measured (train-split crops 267-400 m median vs eval-split 708-1153 m, ~3x, in every bucket), and after exp 20 the error profile is flat across lighting and areas (metros 656-839 m, prignitz 449-539 m; night is no longer the worst bucket anywhere) -- lighting is solved as a differentiator, transfer to unseen terrain is the whole game. Exp 20 removed repetition-driven whole-crop memorization on the DATA side (kept, 1054.87 -> 839.12 m). The remaining untried side is the SUPERVISION density: the trunk's features are trained through exactly one grade per crop -- a single whole-crop Gaussian-CE at the crop centre -- so nothing ever demands that each local feature column be location-predictive on its own; the cheapest fit is whole-crop gestalt, which the probe shows failing to transfer. Exps 4 and 18 both made per-patch localization the INFERENCE mechanism and were reverted; their joint lesson (recorded in exp 19's design) is that the whole-crop arrangement signal must stay intact at decode time -- but neither ever tested per-patch supervision as a training-only regularizer under the kept whole-crop decode, which is standard deep-supervision practice and is exactly the configuration their failures leave open. A dense auxiliary head (one shared 1x1 conv 48->1024 on the identity-turn feature grid) that makes each of the 64 feature columns predict its OWN Gaussian-CE map field at its patch's true ground position multiplies the supervision 64x per crop, and -- combined with exp 20's single-exposure sampling, where a location is seen only ~1-2 times -- can only be satisfied by local cues that transfer between locations. At eval, ~76% of eval crops contain SOME train-seen terrain at a known offset (exp 19's geometry analysis); locally location-predictive feature columns put that partial familiarity into the 8x8 layout code the kept head already reads spatially -- delivering exp 18's intended benefit through the decode that works, instead of the per-patch fusion that failed.
Method
model/model.py: add aux_patch_head = nn.Conv2d(48, GRID_K*GRID_K, 1) and a forward_train() that returns (out, logits, aux_logits) where aux_logits [N,1024,8,8] is the aux head applied to the identity-rotation slice of the trunk feature map; forward() and the ONNX export are byte-for-byte unchanged (the aux head is not traced, so exported size stays 3.30 MiB). Add aux_patch_loss(): per-patch Gaussian-CE (same GRID_K/TARGET_SIGMA_CELLS formula as loss_fn) against each patch's true map uv. model/train.py: sample_epoch additionally returns per-crop patch targets [N,64,2] computed as (cx,cy) + R(angle) @ d for each feature cell's crop-plane offset d = ((j+0.5)*16-64, (i+0.5)*16-64) px, with the numerically verified rotation R(angle) = [[cos,-sin],[sin,cos]] (angle in degrees exactly as passed to extract_crop; verified against extract_crop at 0/90/30/217 deg). Training loss becomes loss_fn(...) + 0.5 * aux_patch_loss(...). Nothing else changes: same epochs, sampling, calibration, export.
Conclusion at the time
REVERTED — metric did not improve (1125.53 m vs best 839.12 m); change discarded
Re-measured on today's ruler
Mission score 1.916 — 0.0% of held-out frames give a usable fix, 91.5% are confident and wrong, 8.5% abstain. Median miss 3.14 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$6.78
implementation agent
$1.42
rented GPU — 40 m 44 s at $0.69/hr
$0.47
total
$8.67
by model — claude-fable-5 $6.78 · claude-sonnet-5 $1.42 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.13 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9160% usablecov 0.92
era Four areas, six lighting buckets · ts 2026-07-21T19:34:42 ·
commit 9df5c83968e9 · artifacts runs/20260721_185358_iter2 ·
took 40 m 44 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.21
Periodic blind holdout check (hamburg) cac6ec61
Blind Hamburg holdout check. Logged for honesty, never allowed to drive keep/revert.
other
—
—
—
HOLDOUT
Hypothesis
If the pipeline is genuinely generic, holdout error should track the development worst-case.
Method
Train current best model code on hamburg, score read-only (§5).
Not on today's ruler
A blind Hamburg holdout check (§5). It measures a different area, so no Berlin mission score exists for it.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 714.0 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-21T18:51:51 ·
commit cac6ec613fa9 · artifacts runs/20260721_175707_iter1/holdout ·
took —
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.20
Per-epoch training-set resampling: a fresh 6,000-location draw per bucket every epoch replaces the one frozen 36k-crop tensor cac6ec61
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.948 — worse than silence.
training
1.948
35 m 33 s
$7.80
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model studied the exact same 36,000 flashcards eight times over, so it started remembering individual cards instead of learning to read terrain. Cards it had memorized it could place well, but over ground it had never studied -- which is exactly what the test uses -- it was three times worse. Now it gets a brand-new deck drawn from the whole training area on every pass: same study time, eight times more distinct places, each seen only once or twice. Remembering single cards stops working, so the only strategy that pays off is learning what actually makes a place recognizable -- the skill it needs over terrain it has never seen.
Hypothesis
The binding constraint is the ~3x held-out-location gap the exp-18 probe measured directly: train-split crops localize to 267-400 m median while eval-split crops sit at 708-1153 m, in every lighting bucket (the per-bucket error profile of the kept model is now flat, so lighting is no longer the leading term). Exps 18 and 19 both attacked this gap by making the model handle partially-familiar crops -- one architecturally (64 per-patch votes; discarded the global arrangement signal, 1135.85 m) and one by corrupting training content (off-site distractor patches; made training strictly harder, 1241.24 m) -- and both were reverted. Jointly they say: the whole-crop arrangement signal must stay intact and the training content clean. The third, untouched axis is repetition. The kept trainer builds ONE tensor -- 6,000 locations per bucket, each at one frozen heading and one frozen relight realization -- and passes over it 8 times. Eight identical passes over 6k fixed templates per bucket, with a 573k-param 1024-way FC head on top, make per-crop memorization the cheapest way down the training loss, and memorized templates are exactly what the probe shows failing to transfer; meanwhile the other ~39k enumerable train locations per bucket are never seen at all. Redrawing the 6,000 locations, their headings, and their realization assignment fresh at the start of every epoch keeps per-epoch cost and total gradient-step count identical while raising distinct locations seen to ~30k per bucket (1-(1-0.133)^8 ~= 68% of ~45k), each seen only ~1-2 times and never twice identically (different heading and often different simulator roll on a repeat). Single-exposure data removes template memorization as an available fitting strategy: only cues that transfer between locations can reduce the loss -- precisely the capability an eval crop over never-trained terrain demands. This is materially distinct from refuted exp 6, which resampled only the ROTATIONS of the same 800 locations on the from-scratch encoder, pre-trunk and pre-C4-vote: heading invariance has been architectural since exp 16; what varies here, and what exp 6 never varied, is location coverage.
Method
model/model.py is untouched. model/train.py only: (1) a one-time prepare_realizations step renders each bucket's two extra relight realizations with the exact seeds exp 17 introduced and caches them as PNGs under <out-dir>/renders/; (2) the single load_training_tensors call before the epoch loop is replaced by a per-epoch sample_epoch(...) that redraws locations, headings, and realization assignment with a fresh rng seeded [seed, epoch]; the minibatch loop, optimizer/param groups, loss, confidence calibration, and ONNX export are byte-identical.
Mission score 1.948 — 0.0% of held-out frames give a usable fix, 94.8% are confident and wrong, 5.2% abstain. Median miss 2.98 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$6.74
implementation agent
$0.65
rented GPU — 35 m 33 s at $0.69/hr
$0.41
total
$7.80
by model — claude-fable-5 $6.74 · claude-sonnet-5 $0.65 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 839.1 m. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9480% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-21T18:32:40 ·
commit cac6ec613fa9 · artifacts runs/20260721_175707_iter1 ·
took 35 m 33 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.19
Off-site distractor patching: half the training crops carry a pasted block of terrain from elsewhere, labels unchanged d5080d5d
The loop discarded this — no improvement under the metric then in force.
augmentation
1.911
42 m 51 s
$9.87
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
When the UAV flies over ground the model never studied, most of the picture is new to it -- but a corner usually shows land it does know. Until now, every practice picture the model ever saw was 100% familiar ground, so it never learned what to do with a half-strange view: one odd patch throws off its whole answer. We now sabotage half of the practice pictures by pasting in a square from somewhere else in the same city, while keeping the answer key unchanged. To keep scoring well, the model must learn to base its answer on the parts of the picture that fit together and shrug off the parts that don't -- like solving a jigsaw with a few pieces from the wrong box mixed in.
Hypothesis
The binding constraint is the held-out-location generalization gap the exp-18 probe measured directly: train-split crops localize to 267-400 m median while eval-split crops sit at 708-1153 m -- a ~3x structural gap, present in every lighting bucket. The frozen split's geometry says exactly what an eval crop looks like: its center pixel always lies in a 360-px eval block whose pixels were never trained on (train windows are dropped if they touch an eval block), while ~76% of eval crops still contain SOME train-seen terrain entering from an edge or corner of the 182-px window. So the canonical eval crop is unfamiliar terrain around the center with familiar terrain at the periphery. The kept head is a whole-crop template matcher (GAP + 512-d layout code -> FC 1024), and every single crop it has ever been trained on was 100% familiar terrain -- partial familiarity is literally outside its training distribution, so at eval the unfamiliar portion shifts the descriptor away from every learned template: fields go diffuse (night coverage sits at the abstention floor) or commit to a lookalike. Exp 18 attacked this same gap architecturally (64 per-patch field votes) and was reverted (1135.85 m) -- forcing each 16-px patch to localize alone discarded the global-arrangement signal that carries most of the discrimination. The materially new angle: keep the kept architecture untouched and make partial familiarity the TRAINING condition instead. With probability 0.5 a training crop gets a square block (side 48-96 px, i.e. 14-56% of its pixels, uniform position) overwritten with the same-position block from a different training location of the same lighting bucket, while the label and Gaussian-CE target stay at the base crop's true center. The pasted content is a worst-case stand-in for eval's unfamiliar content -- not merely uninformative but actively misleading, since its texture genuinely belongs elsewhere on the map. The only way to fit patched crops is to score map cells from the subset of content consistent with a single location and down-weight content that disagrees -- precisely the computation an eval crop demands and that nothing in the current training distribution has ever required. The confidence head trains on the same crops, so it simultaneously learns to flag conflicted content -- the exact crops it should abstain on at eval. This is the first input-composition augmentation in the project's history (exp 6, the only prior augmentation experiment, resampled rotations; it never altered crop content).
Method
One change, entirely inside model/train.py's load_training_tensors: collect each bucket's extracted crops into per-bucket lists; after the three-realization extraction loop, for each crop independently with p=0.5 paste a square block (side ~ uniform int in [48,96] px, top-left uniform over valid positions) copied from the SAME position in a different, pre-patching crop of the same bucket (donors read from a clean snapshot). Labels, Gaussian-CE targets, loss_fn, model.py, decode, confidence calibration, CLI, and ONNX export are all untouched.
Conclusion at the time
REVERTED — metric did not improve (1241.24 m vs best 1054.87 m); change discarded
Re-measured on today's ruler
Mission score 1.911 — 0.5% of held-out frames give a usable fix, 91.5% are confident and wrong, 8.0% abstain. Median miss 2.96 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$8.87
implementation agent
$0.50
rented GPU — 42 m 51 s at $0.69/hr
$0.49
total
$9.87
by model — claude-fable-5 $8.87 · claude-sonnet-5 $0.50 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.24 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9110% usablecov 0.92
era Four areas, six lighting buckets · ts 2026-07-21T16:19:08 ·
commit d5080d5dc73e · artifacts runs/20260721_153617_iter6 ·
took 42 m 51 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.18
Dense per-patch field voting: 64 local place votes with learned fusion replace the global 1024-way template head 48e17da6
The loop discarded this — no improvement under the metric then in force.
architecture
1.901
45 m 05 s
$10.24
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model looked at the whole photo at once and asked 'which spot in the city does this whole picture remind me of?' -- like recognizing a street from a single glance. Our measurement shows it does that three times better on places it studied than on the gaps in between, which is exactly where it gets tested. Now each of 64 small tiles of the photo votes independently -- 'my little piece of ground belongs THERE' -- and a learned referee counts trustworthy tiles more heavily before merging the votes. Even over unfamiliar ground, a few tiles usually catch a road or building the model does know, and those few good votes can carry the answer.
Hypothesis
A read-only probe of the last kept model (berlin+prignitz, midday, matched random headings, 300 crops/condition) shows train-split crops localize to 267-400 m median while eval-split crops sit at 708-1153 m: a ~3x held-out-location generalization gap now dominates the metric, and it is structural, not a lighting problem. The current head is a single 560-d whole-crop descriptor feeding a 573k-param 1024-way FC -- it memorizes whole-crop gestalt templates, which cannot fire correctly on terrain whose pixels were never seen (eval blocks are fully excluded from training with a buffer). But the geometry helps: eval blocks are 360 px squares and crop windows are 182 px, so ~76% of eval crops contain SOME train-seen pixels at a known in-crop offset -- and a global-template head has no mechanism to exploit partially recognized content. Dense per-patch voting does exactly that: each of the 8x8 feature-grid cells casts its own full-map probability field for its OWN patch of ground, supervised with its own patch-level target; at inference a learned informativeness softmax weights the 64 per-patch log-fields into one fused field. Patches over recognized terrain vote precisely and carry the answer; unrecognizable patches are down-weighted. Because the patch-offset pattern is symmetric about the crop center, the fused field peaks at the crop center with no heading knowledge needed. Weight sharing (one 1x1 MLP serves all 64 positions) also cuts head capacity from ~573k to ~137k params, so per-location gestalt memorization -- the thing the probe shows failing to transfer -- is architecturally discouraged: local features must become location-predictive everywhere in the crop. This is materially different from reverted exp 4, which regressed per-patch COORDINATES (sigmoid + smooth-L1, mean-of-64 decode) on a from-scratch encoder with 4.8k crops: mean-decoding suffers the centroid-shrinkage disease exp 14 later diagnosed and fixed, and the from-scratch trunk had no local features worth reading. This design keeps every kept mechanism -- pretrained trunk (exp 11), calibrated Gaussian-CE field + beta-sharpened decode (exps 2/14), C4 rotation vote (exp 16), shape-based confidence + calibration (exp 15), three-realization renders (exp 17) -- and changes only who produces the field logits.
Method
model/model.py: delete layout_squeeze, loc_logits, dark_logits and the luminance gate; add a shared per-position head (1x1 conv 48->128, ReLU, 1x1 conv 128->1024) producing per-patch field logits [*,1024,8,8] and a 1x1 conv 48->1 whose softmax over the 64 positions gives fusion weights; fused per-view logits = sum_p w_p * logits_p; everything downstream (C4 logit mean, sharpened decode, conf head, conf_shift calibration, ONNX export) is unchanged. model/train.py: store each training crop's heading angle next to its (u,v) target; the loss adds a dense term -- each patch's logits get Gaussian-CE against the map cell of that patch's own ground content, computed as crop center + R(heading) . patch offset, on the identity C4 view.
Conclusion at the time
REVERTED — metric did not improve (1135.85 m vs best 1054.87 m); change discarded
Re-measured on today's ruler
Mission score 1.901 — 0.0% of held-out frames give a usable fix, 90.0% are confident and wrong, 10.0% abstain. Median miss 2.72 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$8.58
implementation agent
$1.14
rented GPU — 45 m 05 s at $0.69/hr
$0.52
total
$10.24
by model — claude-fable-5 $8.58 · claude-sonnet-5 $1.14 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.14 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9010% usablecov 0.90
era Four areas, six lighting buckets · ts 2026-07-21T15:36:03 ·
commit 48e17da6b2cf · artifacts runs/20260721_145057_iter5 ·
took 45 m 05 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.17
Nuisance-randomized training renders: each bucket's training crops drawn from three seeded realizations of the frozen relighting sim 95b4c3a0
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.963 — worse than silence.
relighting
1.963
39 m 10 s
$8.60
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model learns night navigation from simulated night photos, and the simulator rolls dice for two things: the grainy sensor static, and which streetlights and lit windows happen to be on. Until now, every practice photo of a place used one single dice roll, frozen forever — so the model could ace practice by memorizing the static, like recognizing a photocopy by its smudges instead of reading it. On new places the smudges are different, and it gets lost exactly where the picture is mostly smudge: at night. Now the practice photos come from three different dice rolls of the same city, so the only thing worth memorizing is what is actually there — the roads, the buildings, and where the lit areas sit.
Hypothesis
Night is now the binding constraint everywhere: it is the worst lighting bucket in all four development areas, the primary metric IS Frankfurt night (1094.59 m), and night coverage has collapsed toward the abstention floor (0.285-0.37 vs 0.46-0.71 in bright buckets) — the confidence head is already throwing away two thirds of night crops and the survivors still miss by ~1 km. The cause this experiment attacks: each (area, bucket) training/eval image is ONE frozen realization of the relighting sim's stochastic nuisances — the seeded shot/read sensor noise and the seeded random thinning that decides which built-up pixels become lamps. Measured directly on prignitz: two different seeds of the night render differ by mean |dpx| 29/255 (79% of pixels differ by >8) against a render mean of only ~60/255 — roughly HALF the night image is realization-specific nuisance — while midday differs by just 6/255. Training crops therefore show each location with a fixed noise/lamp texture for all epochs, and a 1024-way location-memorization head keys each cell's template on the easiest discriminative signal available, which at night SNR~1 is precisely that frozen texture. Held-out eval locations carry unseen realizations of the same nuisances, so the learned templates misfire, fields go diffuse, and the model abstains to the floor or commits wrongly — exactly the observed night signature. Sampling each bucket's training crops from THREE seeded realizations of the frozen sim (the stored eval-matched render plus two fresh-seed re-renders of reference.tif through the untouched pipeline.relight.relight) makes realization texture non-discriminative between locations, forcing templates onto the seed-stable structure (roads, building masses, where the built-up glow sits) — which is exactly what eval crops share with training crops. This is the first experiment in the relighting family in 16 iterations, and it is the training-side relighting that pipeline/relight.py's own NOTE explicitly sanctions; the eval set is untouched.
Method
model/train.py only. load_training_tensors() partitions each bucket's rng.choice picks into three near-equal parts: part 0 is extracted from the stored data/<area>/relight/<bucket>.png (seed_0 — exactly what eval sees); parts 1 and 2 are extracted from relight(ref, LIGHTING_BUCKETS[bucket], meta['gsd_m'], stable_hash(f'{area}:{bucket}:trainreal:{r}')) for r=1,2, rendered on the fly from the area's reference.tif via the frozen pipeline.relight.relight function (imported, never modified), holding at most one full raster + the reference in memory at a time (~19 s/render measured, +12 renders = ~4 min/area). Everything else — model.py, losses, decode, C4 vote, conf calibration on the stored PNGs, CLI, ONNX export — unchanged.
Mission score 1.963 — 0.0% of held-out frames give a usable fix, 96.2% are confident and wrong, 3.8% abstain. Median miss 2.93 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$7.51
implementation agent
$0.64
rented GPU — 39 m 10 s at $0.69/hr
$0.45
total
$8.60
by model — claude-fable-5 $7.50 · claude-sonnet-5 $0.64 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.05 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9630% usablecov 0.96
era Four areas, six lighting buckets · ts 2026-07-21T14:50:42 ·
commit 95b4c3a0c7c7 · artifacts runs/20260721_141132_iter4 ·
took 39 m 10 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.16
C4 rotation-vote field: average field logits over the crop's four 90° turns 5c5373df
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.956 — worse than silence.
architecture
1.956
36 m 53 s
$7.58
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
A UAV photo can be taken facing any direction, but during practice the model only ever saw each place from one direction — so at test time it often fails to recognize a spot simply because the picture is turned. The fix: show the model every photo four times — spun by 0°, 90°, 180° and 270° — and let the four looks vote on where the UAV is. A wrong guess that only appears at one spin gets outvoted; the right answer keeps winning at every spin. Same brain, four glances, one vote.
Hypothesis
The frozen eval set is heading-agnostic (dataset.py gives every held-out crop a deterministic random rotation), but train.py's training tensor shows each training location at exactly ONE random heading, frozen for all 8 epochs — so at eval the model must recognize places across up to 180° of heading mismatch with a plain CNN + FC field head that has no rotational structure whatsoever. Invariance-by-data was tried once (exp 6, fresh rotations every epoch) and refuted: making a 1024-way memorization head learn every location at every heading is sample-inefficient, and more rotated examples did not help. The untried alternative is invariance by construction: evaluate the field on the crop's four exact 90° pixel rotations and average the logits (C4 symmetrization). This (a) guarantees one of the four evaluated views lies within 45° of the one trained heading, versus up to 180° today; (b) makes the model exactly invariant over the C4 subgroup, so training capacity only has to cover a ±45° residual; and (c) since a logit mean is a geometric-mean ensemble, a lookalike cell that fires at only one heading is multiplicatively suppressed — directly attacking the committed-wrong 2–4 km error mode that exps 14/15 diagnosed as what pins every cell's median near 1 km.
Method
model/model.py forward() only: stack the input with its three 90° pixel rotations (transpose+flip — exact permutations, no interpolation, ONNX-safe) into a 4N batch, run the unchanged trunk + layout squeeze + lighting gate + two-expert heads on all four copies, average the four 1024-d field logit vectors (and the four GAP descriptors for the confidence head's input) before the unchanged β-sharpened decode and field-shape confidence. loss_fn, train.py, calibration, and the ONNX export contract untouched.
Mission score 1.956 — 0.0% of held-out frames give a usable fix, 95.5% are confident and wrong, 4.5% abstain. Median miss 3.12 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$6.34
implementation agent
$0.81
rented GPU — 36 m 53 s at $0.69/hr
$0.42
total
$7.58
by model — claude-fable-5 $6.34 · claude-sonnet-5 $0.81 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.09 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9560% usablecov 0.95
era Four areas, six lighting buckets · ts 2026-07-21T14:11:14 ·
commit 5c5373dff494 · artifacts runs/20260721_133421_iter3 ·
took 36 m 53 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.15
Selective prediction: field-shape confidence head with per-bucket calibrated abstention f3b87247
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.848 — worse than silence.
architecture
1.848
40 m 01 s
$11.51
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the UAV's navigator shouted out a position guess for every single photo, even the hopeless ones, and those wild guesses dragged its accuracy score down. This change teaches it to look at its own heat map of candidate locations and notice the difference between one crisp hotspot (sure) and a washed-out smear of weak maybes (not sure) — and in the unsure case to say 'no fix this time', letting the UAV coast on its last known position for a few extra seconds, which the mission profile explicitly allows. The scoring rules have always worked this way — only answers it commits to count, as long as it doesn't stay silent too often — so we tuned it to keep answering at least 40% of the time in every lighting condition, double the required minimum.
Hypothesis
The frozen §6 scorer has implemented selective prediction since bootstrap — a prediction with conf < 0.3 is an abstention excluded from that cell's median, and only coverage ≥ 0.2 is required — but the confidence pathway is still the bootstrap placeholder trained toward 'error < half the map extent', so conf saturates near 1 and coverage has been 1.000 in every one of the 24 cells of every experiment ever logged: the abstention mechanism §6 explicitly designed for ('a model that honestly abstains on bad frames is more useful than one that confidently guesses wrong') has never once fired. Meanwhile exp 14 (kept, 1856.69 -> 1638.3 m) established exactly the error-population structure that selective prediction exploits: its mixture analysis put only p ≈ 0.45–0.6 of field mass near truth, and its peak-commit decode splits predictions into a committed-correct subpopulation (a few hundred m) and committed-wrong misses (2–4 km) — confirmed by the predicted rise of the mean/median ratio from ~1.2 to ~1.35–1.4 in every area × bucket cell. Each cell's median therefore sits just on the wrong side of a bimodal error distribution: if the model can RANK its own crops by whether the field committed correctly, abstaining on the worst-ranked ones moves the median into the correct-commit mode. The ranking signal is already computed at inference and thrown away: the SHAPE of the decode distribution — sharpened-field peak mass, field entropy, and the distance between the sharpened and unsharpened decodes (a direct diffuseness/multimodality readout, the same diagnostic exp 14's analysis was built on). The confidence mechanism is a design family untouched in 14 experiments; it is deployment-honest (a UAV that skips an unsure fix coasts on dead reckoning for the 5–10 s until the next frame per §2's adaptive schedule — strictly better than ingesting a 2-km-wrong fix); and it can be made safe against the coverage-FAIL gate by construction: train the head as a calibrated hit predictor (BCE on 'committed decode within τ = 0.05 uv ≈ 350 m ≈ 1.6 grid cells') on detached inputs, then bake a per-area logit offset into the export, calibrated per lighting bucket on fresh-rotation TRAIN-split crops so that ≥40% clear the fixed 0.3 threshold in EVERY bucket — double the 0.2 coverage floor.
Method
ONE focused change: the deployed confidence pathway. model/model.py — replace the placeholder Linear(48->1) conf head with a small MLP over [48-d GAP descriptor, sharpened-field peak mass, normalized field entropy, distance between sharpened and unsharpened decodes], ALL inputs detached so no confidence gradient can touch trunk/heads; conf = sigmoid(z - conf_shift) with conf_shift a registered buffer (0 during training); loss_fn's conf target tightens from err<0.5 to err<GOOD_ERR_UV=0.05 (weight 0.1->0.3). model/train.py — after the epoch loop, per-area calibration on ~400 fresh-rotation TRAIN-split crops per lighting bucket sets conf_shift so the scorer's fixed 0.3 threshold keeps ≥40% in the worst bucket, then export. Trunk, layout head, dark expert, gate, β=3 decode, Gaussian-CE and coordinate L2: unchanged.
Mission score 1.848 — 0.5% of held-out frames give a usable fix, 85.2% are confident and wrong, 14.2% abstain. Median miss 2.89 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$10.06
implementation agent
$0.99
rented GPU — 40 m 01 s at $0.69/hr
$0.46
total
$11.51
by model — claude-fable-5 $10.06 · claude-sonnet-5 $0.99 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.37 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.8480% usablecov 0.86
era Four areas, six lighting buckets · ts 2026-07-21T13:34:06 ·
commit f3b87247b232 · artifacts runs/20260721_125405_iter2 ·
took 40 m 01 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.996 — worse than silence.
architecture
1.996
31 m 13 s
$7.30
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model draws a heat map of 'where might this photo be?' over the whole city, then has to give one answer. Until now it answered with the average of every warm spot at once — like aiming a dart at the average of three boards you suspect, which lands you in the wall between them. We now turn up the contrast on the heat map first, so the strongest hotspot dominates and the faint background noise vanishes, and the model answers at that hotspot. It is also graded during training on this committed answer, so it learns to put its hotspot in the right place rather than hedging toward the middle of the map.
Hypothesis
After exps 10-12 (all kept: layout head, pretrained trunk, gated dark expert; 2489 -> 1857 m) the binding constraint is no longer feature quality but the decode itself: global soft-argmax returns the probability-weighted MEAN of the whole 32x32 field, so any residual diffuse or multimodal mass drags every prediction toward the map centroid. Three lines of evidence converge on this. (1) The error profile has the exact shrinkage signature: medians sit at 1.0-1.9 km against a ~3.2 km center-guess floor with mean/median ratios of only ~1.15-1.25 in every area x bucket cell — a light-tailed, globally-shrunk distribution, not the heavy tail that confident-but-wrong mode commitment would produce. Under a mixture model 'p mass near truth + (1-p) diffuse', median ≈ (1-p) x center-distance gives p ≈ 0.45-0.6 across buckets: the field already places roughly half its mass near the right answer and the expectation decode throws that away. (2) The training loss actively teaches this failure: the coordinate term is an L2 on the decoded expectation, whose minimizer IS the posterior mean, while the §6 metric is a MEDIAN of radial error, which rewards committing to the dominant mode — a direct loss-metric mismatch nothing in the history has addressed. (3) The only prior attack on the decode, exp 3 (argmax-anchored 5x5-window soft-argmax), was refuted in the from-scratch-encoder era, and its own conclusion attributed the failure to near-uniform fields making the argmax pure noise; that failure mode no longer applies now that exps 10-12 produced fields with real structure (first-ever per-lighting-bucket error gradient). The materially new angle vs exp 3: no hard argmax anchor and no window — a fully differentiable global sharpening (decode from softmax(β·logits), inverse-temperature β = 3) that leaves a uniform field exactly uniform (so the untrained model still decodes to the map center — same bounded-downside floor as every kept experiment) but drives any field with a dominant mode toward that mode, and lets the existing coordinate L2 automatically retrain the network on the committed answer.
Method
One line in model/model.py's TinyLocNet.forward(): the decode distribution becomes p = softmax(DECODE_BETA * logits) with a new module constant DECODE_BETA = 3.0; the soft-argmax expectation over cell centers, the confidence head, and the gated two-head field are untouched. loss_fn is left byte-identical: its cross-entropy consumes the raw logits (log_softmax(logits)), so the field keeps learning the same calibrated Gaussian-bump targets, while its coordinate L2 reads pred[:, :2] and therefore automatically grades the sharpened, committed decode — training and inference stay coupled on exactly what flies. No new parameters, train.py unchanged, ONNX contract and deployment gates unaffected.
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 3.03 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
design agent
$6.52
implementation agent
$0.42
rented GPU — 31 m 13 s at $0.69/hr
$0.36
total
$7.30
by model — claude-fable-5 $6.51 · claude-sonnet-5 $0.42 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.64 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-21T12:53:43 ·
commit d2a0a2b9d817 · artifacts runs/20260721_122230_iter1 ·
took 31 m 13 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.13
Periodic blind holdout check (hamburg) fe745eb4
Blind Hamburg holdout check. Logged for honesty, never allowed to drive keep/revert.
other
—
—
—
HOLDOUT
Hypothesis
If the pipeline is genuinely generic, holdout error should track the development worst-case.
Method
Train current best model code on hamburg, score read-only (§5).
Not on today's ruler
A blind Hamburg holdout check (§5). It measures a different area, so no Berlin mission score exists for it.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.29 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
era Four areas, six lighting buckets · ts 2026-07-21T12:20:37 ·
commit fe745eb4fa91 · artifacts runs/20260721_113214_iter2/holdout ·
took —
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.12
Luminance-gated dark-expert field head blended with the existing layout head fe745eb4
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.993 — worse than silence.
architecture
1.993
42 m 10 s
$4.95
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The last experiment gave the model 'eyes' that already knew how to see from a million daytime photos, and it worked -- but only for well-lit shots. At night, that same borrowed vision is guessing worse, because those eyes never really learned what a dark, sparsely-lit scene looks like. This experiment adds a second, smaller decision-maker that only looks at the crop's overall texture (not its detailed layout, which is mostly invisible in the dark anyway), plus a tiny 'how dark is this shot?' switch that blends the two decision-makers' guesses. In bright shots the switch leans on the original, more detailed guesser; in dark shots it leans on the simpler one built for low light. Nothing about the camera or the final answer changes -- just how the guess gets made inside.
Hypothesis
Exp 11 (ImageNet-pretrained MobileNetV3-Small trunk, kept, 2299.74 -> 2010.15 m) produced, for the first time in this project's history, a clear per-lighting-bucket error gradient instead of the flat profile every from-scratch experiment showed: night is worst in all four development areas (Berlin 1600 vs 1381 m midday; Prignitz 1604 vs 1007 m morning; Munich 2010 vs 1381 m midday -- Munich night IS the current primary worst-case metric; Frankfurt 1585 vs 1063 m afternoon). This is new, decisive evidence of a kind no prior experiment produced: pretrained ImageNet features, however gently fine-tuned (trunk lr 1e-4), carry a systematic bias toward well-lit natural-image statistics, and the single shared field head (GAP + layout code -> FC -> 1024 logits) is being forced to compute the same cell-scoring function for both regimes. CLAUDE.md SS3 explicitly leaves 'several small lighting-condition-specific models behind a lightweight dispatcher' vs. one unified model as an open, loop-decided question, and it is the one design family the plateau-rule history (exps 1-11) has never tried -- every experiment so far has kept a single head. A full duplicate specialist head sized like the existing one would blow the deployment gate (loc_logits is a 560->1024 FC, ~573k params / ~2.2 MB; exp 11's export is already 2.94 MiB of the 4 MiB ONNX budget), so this experiment tests the dispatcher/specialist hypothesis with a budget-safe mixture-of-experts-lite mechanism instead of a full dispatcher.
Method
model/model.py TinyLocNet: add a second, cheap 'dark expert' field head -- nn.Linear(48, 1024) reading ONLY the 48-d GAP descriptor (no 512-d layout code, on the theory that spatial layout is the least reliable signal once texture is mostly gone at night) -- and a tiny gate MLP (Linear(49,16)+ReLU+Linear(16,1)+sigmoid) over [raw-pixel mean brightness of the input frame, 48-d GAP], both derived from the frame itself so the frozen (frame in) -> (lat, lon, conf) contract is untouched. Forward pass: logits = (1-g)*bright_logits + g*dark_logits, where bright_logits is the existing, architecturally unchanged layout-aware head and g in [0,1] is the learned blend weight; softmax/soft-argmax decode, confidence head, GRID_K, and both loss terms are identical to exp 11 -- loss_fn already receives the blended logits via forward(return_logits=True), no changes needed there. No explicit lighting-bucket label is used anywhere; the gate learns to route purely from brightness + features. Adds ~51k params (~200 KB): dark head 50,176 params, gate MLP 817 params. model/train.py: no logic changes -- new params are fresh-initialized and fall into the existing 'head' LR group (1e-3) automatically since they are not in model.features. Verified locally: 816,418 total params (was 765,433), forward+backward flows gradients through both heads and the gate, ONNX 3.14 MiB (< 4 MiB gate, 150 KB of headroom left), torch/ONNX parity 6e-8, untrained decode sits at the map center (0.4999, 0.5023) confirming bounded downside.
Mission score 1.993 — 0.2% of held-out frames give a usable fix, 99.5% are confident and wrong, 0.2% abstain. Median miss 2.90 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$4.46
rented GPU — 42 m 10 s at $0.69/hr
$0.48
total
$4.95
by model — claude-sonnet-5 $4.46 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 1.86 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9930% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-21T12:14:24 ·
commit fe745eb4fa91 · artifacts runs/20260721_113214_iter2 ·
took 42 m 10 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.11
ImageNet-pretrained MobileNetV3-Small trunk replaces the from-scratch encoder d69862d9
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.991 — worse than silence.
architecture
1.991
31 m 35 s
$2.64
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model's 'eyes' started out completely blind: they had to learn to see edges, corners and textures using only pictures of the one training area -- like learning to read from a single book. This experiment swaps in eyes that were already trained on 1.2 million everyday photographs, so they arrive knowing how to see, and we only gently retune them to our night-time aerial views. Everything after the eyes -- the part that guesses the position on the map -- stays exactly the same. If the guesses were bad because the eyes were weak, this should help a lot; if not, we have learned the eyes were never the problem.
Hypothesis
The binding constraint is the quality of the conv features themselves, and no within-dataset signal can fix it: exp 8 showed more from-scratch capacity does not help, exp 9 showed a direct place-discrimination objective (InfoNCE) on from-scratch features does not help, and exp 10's layout-aware head — which finally lets the head read WHERE features sit — was kept but recovered only 1.2%, implying the features it reads carry little discriminative content. All ten experiments trained the encoder from random init on ~36k synthetic relit crops of ONE area — far too little visual diversity to learn the general edge/corner/texture/junction vocabulary that makes local patterns separable. CLAUDE.md §3/§9 explicitly reserves permissively-licensed pretrained init as an open call, and it is the one family in the plateau-rule list never tried. Swapping the from-scratch 4-conv stack for the first 9 feature blocks of ImageNet-pretrained MobileNetV3-Small (190k params, BSD-3, output 8x8x48 — the exact spatial grid the kept exp-10 head already reads) imports a feature vocabulary learned from 1.2M real photographs; low/mid-level features are the standard transferable layer even across large domain gaps (ground-level photos -> overhead relit imagery).
Method
model/model.py: replace the 4x stride-2 from-scratch conv stack with torchvision's actual mobilenet_v3_small().features[:9] module (stem + 8 inverted-residual blocks), loading the verbatim IMAGENET1K_V1 tensors from model/pretrained/mnv3s_features8.pt with strict=True; bake ImageNet mean/std normalization into forward() as buffers so the [0,1] ONNX input contract is unchanged. Head adapts only in width (layout squeeze 48->8, FC 560->1024, conf 48->1, dims probed dynamically from the trunk's actual output shape); GRID_K, losses, decode, export contract all unchanged. model/train.py: two-tier fine-tuning LR (trunk param group 1e-4, fresh-head param group 1e-3) so early large head gradients do not destroy the transferred features; logs 'pretrained:mobilenet_v3_small IMAGENET1K_V1 features[0..8] (torchvision, BSD-3)' as init strategy per §9. Verified locally: strict load OK, 765k total params, forward + backward pass flows gradients into both trunk and head, ONNX 2.94 MiB (< 4 MiB gate), host latency proxy ~40 ms (< 250 ms gate), torch/ONNX parity 9e-8, untrained decode sits at the map center (0.4999, 0.4991) confirming bounded downside.
Mission score 1.991 — 0.0% of held-out frames give a usable fix, 99.0% are confident and wrong, 1.0% abstain. Median miss 2.88 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$2.28
rented GPU — 31 m 35 s at $0.69/hr
$0.36
total
$2.64
by model — claude-sonnet-5 $2.28 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.01 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9910% usablecov 0.99
era Four areas, six lighting buckets · ts 2026-07-21T11:32:06 ·
commit d69862d9a3b1 · artifacts runs/20260721_110031_iter1 ·
took 31 m 35 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.10
Layout-aware field head: squeezed 8×8 spatial code ⊕ GAP replaces GAP-only head input ff271753
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
architecture
2.001
38 m 08 s
$4.27
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model summarized each aerial photo as a recipe list — 'this much road, this much rooftop, this much trees' — with no memory of where anything sat in the picture. Two different neighborhoods with the same mix of ingredients looked identical to it, which may be why it kept guessing near the middle of the map. This experiment adds a second, position-preserving summary — roads on the left, courtyard in the middle, park at the top — and lets the location-guessing layer read both summaries. Places are arrangements, not ingredient lists, so keeping the arrangement should finally let it tell lookalike districts apart.
Hypothesis
Every design so far has fed the 1024-cell field head a spatially averaged descriptor: GAP collapses the 8×8×128 feature map to a bag-of-textures that destroys WHERE features sit in the crop — and the arrangement of roads, buildings and open space is precisely what distinguishes lookalike districts at 1 m/px. This one invariant explains the joint evidence better than any refuted hypothesis: capacity was null (exp 8: a deeper bag-of-textures is still a bag), contrastive descriptor learning was null (exp 9: no training signal can make the descriptor place-discriminative when pooling already destroyed the discriminating information), 7.5× data recovered only 7% (exp 7: more examples do not add information per example), and medians are FLAT across lighting buckets (texture statistics are roughly equally ambiguous in every lighting, while layout would be most readable in bright buckets). Exp 4 is the only non-GAP design ever tried, and it went to the opposite extreme — 64 independent per-patch coordinate regressions with no global read of the arrangement — so a layout-aware GLOBAL decision has never been tested. The fix: a 1×1 conv squeezes the feature map to 8 channels, its flattened 512-d layout code is concatenated with the existing 128-d GAP descriptor, and the FC to 1024 logits reads both — mathematically, the head upgrades from a linear map on the spatial average to a low-rank linear map on the full feature map, a strict superset of every function the old head could compute.
Method
model/model.py only. TinyLocNet gains self.layout_squeeze = nn.Conv2d(128, 8, 1); forward() keeps the 8×8×128 feature map, computes the usual GAP vector f (128-d) AND layout = layout_squeeze(fmap).flatten(1) (8×8×8 = 512-d), and loc_logits becomes nn.Linear(640, 1024) applied to cat([f, layout]). Confidence head (reads GAP only), softmax + soft-argmax decode, loss_fn, export and train.py are all byte-identical. Params 232k → ~757k, ONNX ≈ 2.9 MiB (< 4 MiB gate), latency delta negligible (one 1×1 conv + a wider FC).
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.53 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$4.27
total
$4.27
by model — claude-fable-5 $4.27 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.30 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T23:08:48 ·
commit ff2717532634 · artifacts runs/20260720_223039_iter4 ·
took 38 m 08 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py128 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current approach: DSNT-style spatial probability field. The conv stack'sglobal feature maps to logits over a GRID_K x GRID_K grid of map cells; thepredicted coordinate is the differentiable soft-argmax (probability-weightedexpected value) over fixed cell centers, trained with cross-entropy againstGaussian-smoothed cell targets plus an expected-coordinate L2 term. Unlikehard cell classification + offset regression (archived exp 5, reverted),there is no argmax quantization and no decoupled head — the decode used atinference is exactly what the loss optimizes.Exp 10: the field head reads a spatial layout code alongside the GAPdescriptor. GAP alone is a bag-of-textures — it destroys WHERE features sitin the crop, which is what distinguishes lookalike districts. A 1x1 convsqueezes the 8x8x128 feature map to 8 channels; the flattened 512-d layoutcode is concatenated with the 128-d GAP vector before the logits FC, makingthe head a low-rank linear read of the full feature map (a strict supersetof the old GAP-only head)."""import numpy as np
import torch
import torch.nn as nn
GRID_K =32# 32x32 cells over the map (~220 m cells on a ~7 km area)
TARGET_SIGMA_CELLS =1.5# Gaussian soft-target spread, in cell unitsdef _grid_centers(k: int)-> tuple[torch.Tensor, torch.Tensor]:"""Flat [k*k] tensors of cell-center u and v (cell index = gy * k + gx)."""
centers =(torch.arange(k, dtype=torch.float32)+0.5)/ k
return centers.repeat(k), centers.repeat_interleave(k)class TinyLocNet(nn.Module):"""~757k-param CNN: strided conv stack -> {GAP descriptor + 1x1-squeezed spatial layout code} -> map-cell probability field -> soft-argmax (u, v), plus a separate sigmoid conf head."""def __init__(self, grid_k: int = GRID_K, layout_ch: int =8):
super().__init__()self.grid_k = grid_k
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)
fmap_hw =128//2**(len(chans)-1)# 8 for the frozen 128 px inputself.layout_squeeze = nn.Conv2d(chans[-1], layout_ch,1)self.loc_logits = nn.Linear(chans[-1]+ layout_ch * fmap_hw * fmap_hw,
grid_k * grid_k)self.conf_head = nn.Linear(chans[-1],1)
cell_u, cell_v = _grid_centers(grid_k)self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward(self, x, return_logits: bool =False):
fmap =self.features(x)
f = fmap.mean(dim=(2,3))
layout =self.layout_squeeze(fmap).flatten(1)
logits =self.loc_logits(torch.cat([f, layout], dim=1))
p = torch.softmax(logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)
conf = torch.sigmoid(self.conf_head(f))
out = torch.cat([u, v, conf], dim=1)if return_logits:return out, logits
return out
def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, logits: torch.Tensor,
target_uv: torch.Tensor)-> torch.Tensor:"""CE against a Gaussian-smoothed cell target + expected-coord L2 + conf BCE."""
k = GRID_K
cell_u, cell_v = _grid_centers(k)
cell_u, cell_v = cell_u.to(logits.device), cell_v.to(logits.device)
du =(cell_u[None,:]- target_uv[:,0:1])* k # distance in cell units
dv =(cell_v[None,:]- target_uv[:,1:2])* k
g = torch.exp(-(du **2+ dv **2)/(2* TARGET_SIGMA_CELLS **2))
g = g / g.sum(dim=1, keepdim=True)
ce =-(g * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Conf target stays deliberately loose (abstain only on catastrophic# misses > half the map extent) so the model stays scoreable instead# of abstaining its way into the §6 coverage FAIL; calibrating# confidence properly is a separate research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return ce + coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py109 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Training scale (exp 7): 6,000 of the ~45k enumerable train locations perbucket (was 800 / ~1.8%, which left a quarter of the 32x32 field cells withzero training example in any given lighting bucket). The training tensor isheld as uint8 and converted to float per minibatch — 36k float32 crops wouldbe ~7 GB; uint8 is ~1.8 GB.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs))# uint8 NxHxWx3; float-converted per batch
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb = x[idx].to(device).permute(0,3,1,2).contiguous().float().div_(255.0)
yb = y[idx].to(device)
out, logits = model(xb, return_logits=True)
loss = loss_fn(out, logits, yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=6000)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
2.9
Cross-lighting contrastive pairs: NT-Xent metric learning on the place descriptor 76c45e3c
The loop discarded this — no improvement under the metric then in force.
loss
1.991
23 m 41 s
$4.93
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model has been describing every photo so vaguely that different places end up with nearly identical descriptions — like describing every street as 'houses and a road'. We now train it flash-card style: each round it gets two photos of the exact same spot — say one at noon and one at night, turned to different compass headings — and is graded on giving both the same description, while its descriptions of the 62 other places in the round must stay clearly different. That pressure forces it to notice what makes each place unique, which is exactly what pointing to the right spot on the map requires.
Hypothesis
The encoder's 128-d descriptor is not place-discriminative, and no existing training signal ever directly demands that it be: Gaussian-CE against a near-uniform 1024-way target gives each crop a diffuse gradient that shapes the head more than the features. The joint evidence — near-uniform fields (exp 3's argmax test), nulls from supervision form (3-5), rotation resampling (6) and capacity (8), only 7% from 7.5x data (7), and medians flat across lighting buckets at ~2.3 km near the 3.2 km center-guess floor — all points at descriptor quality, not head, data volume, or capacity. An InfoNCE objective on location-paired batches (same place, two different lighting renders, two independent headings, 62 in-batch negatives) supplies exactly the missing signal: per-sample 'same place -> same descriptor, different place -> different descriptor' gradients far stronger than the near-uniform CE, and it builds precisely the two invariances (heading, lighting) the frozen rotated multi-bucket eval demands.
Method
train.py: sample ONE shared 6,000-location set per area and extract it in all six relight buckets with independent random headings (same 36k-crop, ~1.8 GB uint8 budget; previously each bucket sampled locations independently, so no cross-bucket pairs existed). Each step draws 32 locations x 2 distinct buckets -> a 64-crop batch of 32 positive pairs. model.py: add a train-only 128->128->64 MLP projection head and NT-Xent (temperature 0.2, weight 1.0) on the projected GAP descriptors, added to the unchanged Gaussian-CE + coord L2 + conf BCE. Inference path, decode, and ONNX export are byte-identical; the projection head is never traced.
Conclusion at the time
REVERTED — metric did not improve (2342.1 m vs best 2326.54 m); change discarded
Re-measured on today's ruler
Mission score 1.991 — 0.5% of held-out frames give a usable fix, 99.5% are confident and wrong, 0.0% abstain. Median miss 2.47 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$4.93
total
$4.93
by model — claude-fable-5 $4.92 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.34 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9910% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T22:30:37 ·
commit 76c45e3c4850 · artifacts runs/20260720_220655_iter3 ·
took 23 m 41 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
architecture
1.996
48 m 45 s
$5.33
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model was a tiny four-layer network trying to memorize what every corner of a 7 km-wide city looks like — like sketching an entire city map on a sticky note. Recent experiments kept changing how we teach it (better lessons, more flashcards) and nothing broke through, because the student's notebook was simply full: it scored almost equally badly in bright daylight and at night, the classic sign of a model too small for its task rather than a task too hard. The flight computer actually has room for a model four times bigger than the one we've been flying. This experiment keeps the lessons exactly the same and only swaps in a deeper, four-times-larger network — built with 'residual' shortcuts, a standard trick that keeps deep networks easy to train — so it finally has enough room to write the whole map down.
Hypothesis
The binding constraint is encoder capacity, not supervision, decode, rotation handling, or data volume. Exps 3-5 changed supervision/decode and were all null; exp 6 (rotation resampling) was null; exp 7's 7.5× data scale — the family every reverted mechanism jointly pointed at — recovered only 7% (2489 → 2326 m), meaning the model could not absorb the added coverage. The kept run's error profile is the signature of underfitting: ~1.55-2.33 km medians nearly FLAT across lighting buckets (Berlin night 1760 m vs midday 1642 m), so even the easiest bright-daylight discrimination is not being learned — a lighting- or supervision-side bottleneck would show a bucket gradient. The current encoder is 4 plain stride-2 convs whose 128-d GAP descriptor must separate 1,024 map cells × 6 lightings across ~45k locations at 1 m/px, while using only 0.93 MB of the 4 MiB deployment gate and 1.25 ms of the 250 ms latency budget. Depth/width is the one axis no experiment has ever touched.
Method
model/model.py only: replace TinyLocNet.features (4 plain stride-2 convs 3→16→32→64→128, GAP→128-d) with an 11-conv residual encoder sized to the deployment envelope — stem 3→32 s2; stage1 down 32→64 s2 + bottleneck residual block (1×1 reduce to 32, 3×3, 1×1 expand); stage2 down 64→128 s2 + bottleneck block (mid 64); stage3 down 128→160 s2 + full 3×3+3×3 residual block; GAP → 160-d. Bottlenecks sit early where 32²/16² resolution makes compute expensive; the full block sits at 8² where parameters are cheap. Field head (Linear→1024 + softmax soft-argmax), conf head, loss, decode, training data, epochs, and lr are untouched, so attribution is purely encoder capacity/depth. Verified pre-registration: 972,993 params, ONNX 3.72 MiB < 4 MiB gate, host latency proxy 2.91 ms < 250 ms.
Conclusion at the time
REVERTED — metric did not improve (2427.33 m vs best 2326.54 m); change discarded
Re-measured on today's ruler
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 2.84 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$5.33
total
$5.33
by model — claude-fable-5 $5.33 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.43 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T22:06:53 ·
commit 76c45e3c4850 · artifacts runs/20260720_211808_iter2 ·
took 48 m 45 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.7
Scale training coverage 7.5x: 6,000 of ~45k available train locations per bucket (was 800) 76c45e3c
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
training
2.001
21 m 44 s
$3.83
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model has been studying flashcards covering only about 2% of the map — most neighborhoods were never shown to it at all, in any lighting. The last four experiments all tried smarter study techniques and none helped, which suggests the problem was never the technique: you can't recognize a place you've never seen. This experiment changes nothing about the model or how it learns — it just hands it 7.5 times more flashcards, enough that every part of the map appears in the deck under every lighting condition. Training takes a few minutes longer per area, which was affordable all along.
Hypothesis
All four consecutive reverted experiments (3: decode commitment, 4: dense per-patch supervision, 5: hierarchical pooling, 6: rotation resampling) changed the supervision/decode mechanism while inheriting the same starved data regime, and all failed by nearly identical margins — the shared substrate, not the mechanisms, is the bottleneck. train.py samples only 800 of the ~45,000 enumerable train locations per lighting bucket (1.8%). At 1 m/px GSD (exp-5's density analysis assumed 10 m/px, so it attacked label-space density when the real scarcity is input-space coverage), a 128x128 crop spans 128 m of a ~7 km map, and 800 random locations put ~0.78 training crops per 220 m field cell per bucket — a quarter of grid cells have zero training example in any given lighting condition, and a typical eval crop shares content with roughly half of one training crop in its bucket. The probability field stays near-uniform because most of the map was literally never shown to the model. Raising the per-bucket sample to 6,000 gives ~5.9 crops per cell per bucket (every cell supervised in every lighting condition), makes neighboring overlapping crops (24 m stride, 80%+ shared content) appear at many independent random headings — rotation robustness through spatial density rather than exp-6's refuted temporal resampling of the same sparse 800 — and raises gradient steps from 600 to ~4,500 as a direct consequence.
Method
In model/train.py only: (1) raise the --max-crops-per-bucket default from 800 to 6,000 (~36k crops/area); (2) hold the training tensor as uint8 and convert each minibatch to float on device — required because 36k float32 crops would be ~7 GB, uint8 is ~1.8 GB. Model, loss, decode, optimizer (Adam 1e-3), batch size 64, epoch count (harness-set 8), and the one-shot static extraction with one random heading per location all stay byte-identical to the kept exp-2 code. Cost: ~3.5 min/area (21 s extraction + ~4,500 steps) vs ~28 s — iteration wall-clock rises to roughly 15 min.
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.52 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$3.83
total
$3.83
by model — claude-fable-5 $3.82 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.33 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T21:18:06 ·
commit 76c45e3c4850 · artifacts runs/20260720_205622_iter1 ·
took 21 m 44 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py114 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current approach: DSNT-style spatial probability field. The conv stack'sglobal feature maps to logits over a GRID_K x GRID_K grid of map cells; thepredicted coordinate is the differentiable soft-argmax (probability-weightedexpected value) over fixed cell centers, trained with cross-entropy againstGaussian-smoothed cell targets plus an expected-coordinate L2 term. Unlikehard cell classification + offset regression (archived exp 5, reverted),there is no argmax quantization and no decoupled head — the decode used atinference is exactly what the loss optimizes."""import numpy as np
import torch
import torch.nn as nn
GRID_K =32# 32x32 cells over the map (~220 m cells on a ~7 km area)
TARGET_SIGMA_CELLS =1.5# Gaussian soft-target spread, in cell unitsdef _grid_centers(k: int)-> tuple[torch.Tensor, torch.Tensor]:"""Flat [k*k] tensors of cell-center u and v (cell index = gy * k + gx)."""
centers =(torch.arange(k, dtype=torch.float32)+0.5)/ k
return centers.repeat(k), centers.repeat_interleave(k)class TinyLocNet(nn.Module):"""~230k-param CNN: strided conv stack -> GAP -> map-cell probability field -> soft-argmax (u, v), plus a separate sigmoid conf head."""def __init__(self, grid_k: int = GRID_K):
super().__init__()self.grid_k = grid_k
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.loc_logits = nn.Linear(chans[-1], grid_k * grid_k)self.conf_head = nn.Linear(chans[-1],1)
cell_u, cell_v = _grid_centers(grid_k)self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward(self, x, return_logits: bool =False):
f =self.features(x).mean(dim=(2,3))
logits =self.loc_logits(f)
p = torch.softmax(logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)
conf = torch.sigmoid(self.conf_head(f))
out = torch.cat([u, v, conf], dim=1)if return_logits:return out, logits
return out
def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, logits: torch.Tensor,
target_uv: torch.Tensor)-> torch.Tensor:"""CE against a Gaussian-smoothed cell target + expected-coord L2 + conf BCE."""
k = GRID_K
cell_u, cell_v = _grid_centers(k)
cell_u, cell_v = cell_u.to(logits.device), cell_v.to(logits.device)
du =(cell_u[None,:]- target_uv[:,0:1])* k # distance in cell units
dv =(cell_v[None,:]- target_uv[:,1:2])* k
g = torch.exp(-(du **2+ dv **2)/(2* TARGET_SIGMA_CELLS **2))
g = g / g.sum(dim=1, keepdim=True)
ce =-(g * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Conf target stays deliberately loose (abstain only on catastrophic# misses > half the map extent) so the model stays scoreable instead# of abstaining its way into the §6 coverage FAIL; calibrating# confidence properly is a separate research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return ce + coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py109 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Training scale (exp 7): 6,000 of the ~45k enumerable train locations perbucket (was 800 / ~1.8%, which left a quarter of the 32x32 field cells withzero training example in any given lighting bucket). The training tensor isheld as uint8 and converted to float per minibatch — 36k float32 crops wouldbe ~7 GB; uint8 is ~1.8 GB.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs))# uint8 NxHxWx3; float-converted per batch
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb = x[idx].to(device).permute(0,3,1,2).contiguous().float().div_(255.0)
yb = y[idx].to(device)
out, logits = model(xb, return_logits=True)
loss = loss_fn(out, logits, yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=6000)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
2.6
Per-epoch rotation resampling replaces the one-shot frozen training tensor de614d47
The loop discarded this — no improvement under the metric then in force.
augmentation
2.001
6 m 52 s
$1.67
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Until now the model studied each training photo from one fixed compass direction only -- like memorizing your neighborhood while always facing north, then being quizzed while facing random directions. Unsurprisingly, it froze on the quiz. Now, every time it re-reads its study deck, every photo is re-dealt at a new random rotation, so the only way to get good grades in practice is to recognize places no matter which way it is facing -- which is exactly what the real quiz (and a real UAV) demands.
Hypothesis
The probability field stays near-uniform not because of supervision form (exp-3/4/5 all attacked the head/loss and failed identically) but because the encoder never learns rotation-invariant features: train.py extracts each of the few hundred train locations exactly once, at one fixed random heading, into a static tensor reused every epoch, while the frozen eval rotates every crop by a different deterministic angle. The model can fit 'this place seen at heading 137 degrees' without ever being forced to recognize the same place at another heading, so at eval time features do not fire, the field stays flat, and the soft-argmax decode collapses toward the map center. Re-extracting all training crops with fresh uniform-random angles at the start of every epoch multiplies heading diversity per location by the epoch count and makes rotation invariance the only way to reduce training loss.
Method
In model/train.py only: split load_training_tensors into a one-time loader (meta, train-crop list, six relight images cached in memory) and a per-epoch sampler that re-runs extract_crop with a fresh rng.uniform(0,360) angle for every (location, bucket) pair; the training loop rebuilds x each epoch from the cached images. Locations stay on the frozen list_crops grid (no position jitter, so the no-eval-leakage guarantee in pipeline/dataset.py is untouched). model/model.py, the loss, and the exported inference path are unchanged.
Conclusion at the time
REVERTED — metric did not improve (2509.97 m vs best 2489.03 m); change discarded
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.39 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$1.67
total
$1.67
by model — claude-fable-5 $1.67 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.51 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T20:26:38 ·
commit de614d47e3ea · artifacts runs/20260720_201946_iter5 ·
took 6 m 52 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.5
Hierarchical coarse-to-fine supervision of the probability field via probability pooling 7d02e02d
The loop discarded this — no improvement under the metric then in force.
loss
1.996
6 m 20 s
$1.91
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The model localizes by painting a heat map over a 32x32 grid of the area — but we only have enough training photos to give most grid squares zero examples, so the heat map never learned to commit and stayed lukewarm everywhere. The fix is to grade the same heat map at several zoom levels at once: first 'did you put the heat in the right quarter of the map?', then the right sixteenth, and so on down to the fine grid. Coarse questions have plenty of examples to learn from, and getting them right automatically steers the fine answer — like learning an address by first nailing the district, then the street, then the house.
Hypothesis
The kept 32x32 field stays near-uniform (confirmed by exp-3's argmax test and exp-4's failure to beat it) because supervision density in label space is below one example per class: at 10 m/px with a 24 px sampling stride a ~7 km area yields only ~600 distinct train locations per bucket spread over 1,024 fine cells, so the Gaussian-CE mostly teaches 'not here' uniformly and no cell ever accumulates enough positive gradient to stand out. Sum-pooling the same softmax field to 16x16, 8x8, and 4x4 and applying the identical Gaussian-CE at each level gives coarse cells 10-40 positive training locations each — dense enough to learn real discrimination — and because coarse probabilities are exact sums of fine-cell probabilities, that well-conditioned coarse gradient flows directly into the fine logits ('put mass somewhere in this quadrant'), letting the fine level refine a coarse decision instead of learning 1,024-way classification from scratch.
Method
model/model.py loss_fn only: reshape softmax(logits) to [B,32,32], build coarser fields by 2x2/4x4/8x8 sum-pooling (avg_pool2d * factor^2), and compute the existing Gaussian-smoothed cross-entropy at levels k in {4, 8, 16, 32} with sigma held constant in map units (TARGET_SIGMA_CELLS * k / GRID_K cells), averaging the four CE terms in place of the single fine CE. Forward pass, decode, export, and train.py are untouched — zero new parameters, identical ONNX artifact shape.
Conclusion at the time
REVERTED — metric did not improve (2516.25 m vs best 2489.03 m); change discarded
Re-measured on today's ruler
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 2.91 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$1.91
total
$1.91
by model — claude-fable-5 $1.91 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.52 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T20:19:45 ·
commit 7d02e02d9ca2 · artifacts runs/20260720_201325_iter4 ·
took 6 m 20 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.4
ACE-style dense per-patch scene-coordinate regression replaces global map-cell probability field 7d02e02d
The loop discarded this — no improvement under the metric then in force.
architecture
2.001
9 m 11 s
$2.92
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Rather than one verdict per photo, the network was made to answer 64 times per photo: the image is split into an 8×8 grid of patches, and each patch must separately name the map coordinate of the ground it shows (the training data knows the right answer for every patch). The final position is the average of those 64 mini-answers. The hope: 64× more feedback per photo forces the network to learn which ground textures give away a location. It scored slightly worse than the heat-map approach (~2.56 km vs ~2.49 km), so it was reverted.
Hypothesis
The encoder never learns geo-discriminative local features because supervision is one target per 128x128 crop: the GAP bottleneck plus a single global 32x32 map-cell field gives every conv feature the same diffuse gradient, which is why fields stay near-uniform (exp-3 refuted multimodality) and errors sit at ~2.1-2.5 km, barely under the 3.2 km center-guess bound, uniformly across all lighting buckets. Dense scene-coordinate regression (the ACE/DSAC family CLAUDE.md §3 explicitly names) supervises each of the 8x8 stride-16 feature cells with the map coordinate of its own patch — computable at train time from crop center + rotation — multiplying supervision density 64x on the same 4,800-crop budget and forcing local textures to become location-predictive. Because the patch-offset grid is symmetric about the crop center and rotation is linear, the unweighted mean of per-cell predictions is an unbiased crop-center estimate requiring no heading knowledge at inference, so the frozen rotated-eval contract is satisfied unchanged.
Method
In model/model.py: replace the GAP -> 1024-way map-cell logits head with (a) one 3x3 dilation-2 conv context stage on the 8x8x128 feature map (receptive field ~95 px, block-level context per cell), (b) a 1x1 conv -> sigmoid head emitting per-cell normalized (u,v) map coordinates, (c) forward output = unweighted mean of the 64 per-cell coordinates plus the existing loose sigmoid conf head on GAP'd context features. Loss becomes per-cell smooth-L1 against per-cell targets plus the unchanged 0.1-weighted conf BCE. In model/train.py: load_training_tensors computes the [2,8,8] per-cell target grid per sample by rotating the fixed patch-offset lattice by the sampled crop angle and adding the crop-center pixel coordinate (helper cell_target_grid in model.py). ONNX export contract, CLI contract, and crop sampling untouched.
Conclusion at the time
REVERTED — metric did not improve (2563.37 m vs best 2489.03 m); change discarded
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.56 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$2.92
total
$2.92
by model — claude-fable-5 $2.92 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.56 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T20:13:25 ·
commit 7d02e02d9ca2 · artifacts runs/20260720_200413_iter3 ·
took 9 m 11 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.3
Argmax-anchored local soft-argmax decode replaces global expected-coordinate ff65590e
The loop discarded this — no improvement under the metric then in force.
architecture
1.991
4 m 58 s
$1.25
DISCARDED
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
An attempted fix for experiment 2's “dragged toward the middle” problem. Rather than averaging the whole heat map, the model first commits to the single hottest cell, then fine-tunes its answer using only the 5×5 neighborhood around it — decide roughly where first, then refine locally. It backfired: the hottest cell is apparently often wrong (the heat maps are still too scattered), so committing to it made the error worse (~2.9 km vs ~2.5 km) and the change was reverted.
Hypothesis
Global soft-argmax over the 32x32 field decodes the probability-weighted mean of ALL cells, so any diffuse or multimodal probability field is pulled toward the map centroid — the kept exp-2 result (worst-case median 2489 m) barely beats the 3217 m center-guess bound, consistent with predictions huddling near the map mean rather than committing to the dominant mode. Anchoring the decode at the argmax cell and taking soft-argmax only within a +/-2-cell window forces mode commitment while keeping differentiable sub-cell refinement, and the training coordinate loss is computed on exactly this decode so train and inference stay coupled.
Method
In model/model.py forward(): after softmax over the 1024 cell logits, take the argmax cell, build a window mask |gx-gx*|<=2 and |gy-gy*|<=2 (5x5 cells, ~1.1 km on a ~7 km map), renormalize probabilities inside the window, and decode (u,v) as the expected coordinate over the window only. The mask is non-differentiable (straight-through-style); gradients flow through the windowed probabilities. CE-against-Gaussian-target term, conf head, train.py, and the ONNX export contract are unchanged — the exported graph uses ArgMax/Mod/floor-Div ops supported at opset 17.
Conclusion at the time
REVERTED — metric did not improve (2937.73 m vs best 2489.03 m); change discarded
Re-measured on today's ruler
Mission score 1.991 — 0.5% of held-out frames give a usable fix, 99.5% are confident and wrong, 0.0% abstain. Median miss 3.40 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$1.25
total
$1.25
by model — claude-fable-5 $1.25 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.94 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9910% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T20:04:13 ·
commit ff65590e776f · artifacts runs/20260720_195914_iter2 ·
took 4 m 58 s
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
2.2
DSNT-style spatial probability field over the map replaces direct (u,v) regression ff65590e
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
architecture
2.001
7 m 08 s
$2.06
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
Instead of blurting out one guess, the network now lays a 32×32 grid of cells over the map and gives each cell a score for “the photo probably came from here” — a heat map of suspicion. Its answer is the balance point (weighted average) of that heat map. Training became much more informative — every cell is told individually whether it should have been hotter or colder — and the error improved from ~3.2 km to ~2.5 km. Remaining weakness: averaging a spread-out heat map drags answers toward the middle of the map.
Hypothesis
Direct MSE regression to sigmoid (u,v) collapses to the map-mean (center-guess ~3.2 km) because under early-training ambiguity the MSE optimum IS the mean and the gradient gives no per-location signal; the one prior classification attempt (archived exp 5) failed for a different reason — hard argmax cells + a decoupled offset head quantize the decision and decouple training from the metric. A dense probability field over a 32x32 grid of map cells, decoded by differentiable soft-argmax (expected coordinate) and trained with cross-entropy against Gaussian-smoothed cell targets plus an expected-coordinate L2 term, gives per-cell gradient signal that escapes the mean-collapse while remaining trained end-to-end on the exact coordinate the metric measures.
Method
In model/model.py, replace TinyLocNet's Linear(128->3)+sigmoid head with: Linear(128->1024) map-cell logits over a 32x32 grid (~220 m cells at 7 km), softmax, expected (u,v) = probability-weighted sum of fixed cell centers (registered buffers, ONNX-friendly), plus an unchanged separate sigmoid conf head trained with the same loose BCE target (err < 0.5 extent) so the coverage gate is untouched. Loss becomes CE(softmax logits, Gaussian soft target sigma=1.5 cells) + expected-coord L2 + 0.1*conf BCE. model/train.py changes only the loss call to pass logits through.
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.92 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
summary agent
$2.06
total
$2.06
by model — claude-fable-5 $2.06 · claude-haiku-4-5-20251001 $0.00
The agent lines are the equivalent API cost of the tokens each agent used, as recorded by the harness when it ran. The research ran on a claude.ai Max subscription, so that is what it would have cost billed per token — not money that left the account. The GPU line is real spend.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 2.49 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T19:59:14 ·
commit ff65590e776f · artifacts runs/20260720_195206_iter1 ·
took 7 m 08 s
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py114 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Current approach: DSNT-style spatial probability field. The conv stack'sglobal feature maps to logits over a GRID_K x GRID_K grid of map cells; thepredicted coordinate is the differentiable soft-argmax (probability-weightedexpected value) over fixed cell centers, trained with cross-entropy againstGaussian-smoothed cell targets plus an expected-coordinate L2 term. Unlikehard cell classification + offset regression (archived exp 5, reverted),there is no argmax quantization and no decoupled head — the decode used atinference is exactly what the loss optimizes."""import numpy as np
import torch
import torch.nn as nn
GRID_K =32# 32x32 cells over the map (~220 m cells on a ~7 km area)
TARGET_SIGMA_CELLS =1.5# Gaussian soft-target spread, in cell unitsdef _grid_centers(k: int)-> tuple[torch.Tensor, torch.Tensor]:"""Flat [k*k] tensors of cell-center u and v (cell index = gy * k + gx)."""
centers =(torch.arange(k, dtype=torch.float32)+0.5)/ k
return centers.repeat(k), centers.repeat_interleave(k)class TinyLocNet(nn.Module):"""~230k-param CNN: strided conv stack -> GAP -> map-cell probability field -> soft-argmax (u, v), plus a separate sigmoid conf head."""def __init__(self, grid_k: int = GRID_K):
super().__init__()self.grid_k = grid_k
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.loc_logits = nn.Linear(chans[-1], grid_k * grid_k)self.conf_head = nn.Linear(chans[-1],1)
cell_u, cell_v = _grid_centers(grid_k)self.register_buffer("cell_u", cell_u)self.register_buffer("cell_v", cell_v)def forward(self, x, return_logits: bool =False):
f =self.features(x).mean(dim=(2,3))
logits =self.loc_logits(f)
p = torch.softmax(logits, dim=1)
u =(p *self.cell_u).sum(dim=1, keepdim=True)
v =(p *self.cell_v).sum(dim=1, keepdim=True)
conf = torch.sigmoid(self.conf_head(f))
out = torch.cat([u, v, conf], dim=1)if return_logits:return out, logits
return out
def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, logits: torch.Tensor,
target_uv: torch.Tensor)-> torch.Tensor:"""CE against a Gaussian-smoothed cell target + expected-coord L2 + conf BCE."""
k = GRID_K
cell_u, cell_v = _grid_centers(k)
cell_u, cell_v = cell_u.to(logits.device), cell_v.to(logits.device)
du =(cell_u[None,:]- target_uv[:,0:1])* k # distance in cell units
dv =(cell_v[None,:]- target_uv[:,1:2])* k
g = torch.exp(-(du **2+ dv **2)/(2* TARGET_SIGMA_CELLS **2))
g = g / g.sum(dim=1, keepdim=True)
ce =-(g * torch.log_softmax(logits, dim=1)).sum(dim=1).mean()
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Conf target stays deliberately loose (abstain only on catastrophic# misses > half the map extent) so the model stays scoreable instead# of abstaining its way into the §6 coverage FAIL; calibrating# confidence properly is a separate research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return ce + coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py102 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
out, logits = model(xb, return_logits=True)
loss = loss_fn(out, logits, yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
architecture
2.001
—
—
KEPT
The design under test — technical diagram — gray = frozen contract · ink = the current design · red = this experiment's change
In plain words
The deliberately-dumb starting point. A tiny neural network looks at a single 128 m square of aerial photo and, in one shot, blurts out two numbers: how far across and how far up the map that view belongs. With so little capacity and training it effectively learns to always point near the middle of the map, which is why its guesses are ~3.2 km off. Its only job is to be the reference every later experiment must beat.
Hypothesis
A deliberately naive ~300k-param CNN (strided conv stack, direct coordinate regression, loose confidence head) trained 8 epochs on 4,800 crops/area cannot memorize a ~7 km area at 1 m detail — its error should sit near the center-guess bound (~3 km), establishing the reference point the loop must beat.
Method
Frozen pipeline: 1 m/px open DOP orthophotos (source registry), 6-bucket relighting with ambient-compensated auto-exposure and golden/blue-hour grading, leakage-guarded 360 m block split (~45k train positions/area). One model per development area (berlin, prignitz, munich, frankfurt), ONNX export, frozen §6 scoring.
Conclusion at the time
Starting baseline for the autoresearch loop. Every subsequent experiment is measured against this on the same frozen eval data (no further eval-set changes are planned). Bootstrap-phase history (7 experiments incl. two deliberate eval-set revisions) is archived in archive/bootstrap-experiments.sqlite.
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 3.48 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), target 20 m, scoring 3.22 km. Asked over: region holdout, 6 lighting buckets, 4 areas. The long grind: 62 experiments over ten days against a general-purpose, four-area, six-lighting-bucket problem. Scored on a region holdout that asked a memorization model to locate ground it had never been shown.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Four areas, six lighting buckets · ts 2026-07-20T19:50:47 ·
commit b47d44a8fb64 · artifacts runs/bootstrap_baseline_v4 ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
relighting
2.001
—
—
KEPT
Hypothesis
The v0 sensor model's uncompensated auto-exposure re-brightened every bucket up to the same target, making morning-through-evening nearly indistinguishable (user-observed). Scaling the exposure target with ambient (real AE under-exposes as light falls) plus golden-hour warmth and the existing blue-hour ramp should produce a visible day->dusk->night progression (measured tile brightness 0.56 -> 0.49 -> 0.41 -> 0.35 -> 0.27), giving the model genuinely distinct lighting domains; the naive baseline should stay in the center-guess regime.
Method
pipeline/relight.py: AE target = TARGET_MEAN * (0.25 + 0.75 * ambient^0.7); ambient color gains a Gaussian golden-hour warm tint peaking at ambient 0.5. All five areas re-rendered; baseline retrained (8 epochs, matching the loop default) and rescored. Deliberate frozen-pipeline revision during the bootstrap window, agreed with the human; marks an era boundary in the dashboard.
Conclusion at the time
KEPT as the new Phase 2 starting best on relight v1 eval data (era reset — prior scores not comparable). Lighting buckets are now genuinely distinct domains.
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 3.48 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 3.22 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Bootstrap · ts 2026-07-20T19:43:59 ·
commit 678dd1e7acd2 · artifacts runs/bootstrap_baseline_v4 ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
1.6
Per-epoch crop resampling — train on fresh positions/rotations every epoch instead of a fixed 4,800-crop snapshot 4959f8fb
The loop discarded this — no improvement under the metric then in force.
training
2.001
—
—
DISCARDED
Hypothesis
The split rebalance (exp 4) exposed ~45k train positions per area, but train.py still pre-extracts one fixed sample of 800 crops/bucket (4,800 total) and iterates it for all 8 epochs, so the model sees ~1.8% of available positions with one fixed rotation each. Exp 5's failure isolated data volume/diversity (not coordinate parameterization) as the suspected binding constraint keeping the model in the center-guess regime (~2968 m): with so few distinct positions the loss-minimizing generalization to unseen eval crops is still 'predict the middle'. Resampling a fresh 800/bucket set (new positions AND new rotation angles) at the start of every epoch raises distinct training crops from 4,800 to up to ~38,400 over 8 epochs, directly attacking that constraint while holding architecture, loss, batch size, learning rate, and epoch count fixed.
Method
model/train.py only: load the 6 relight bucket images and the train crop list once, then move crop sampling/extraction inside the epoch loop — each epoch draws a fresh rng.choice of positions per bucket and a fresh uniform rotation per crop, builds that epoch's tensors, trains on them, and discards them. model/model.py, loss, optimizer, lr, batch size, and the CLI/ONNX contracts are untouched.
Conclusion at the time
REVERTED — metric did not improve (3124.07 m vs best 2968.56 m); change discarded
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.61 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 3.12 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Bootstrap · ts 2026-07-20T19:18:56 ·
commit 4959f8fb8867 · artifacts runs/20260720_191230_iter2 ·
took —
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
The loop discarded this — no improvement under the metric then in force.
loss
1.996
—
—
DISCARDED
Hypothesis
The baseline's direct sigmoid-(u,v) regression under MSE is what pins the score at the center-guess bound (~2968 m): with visually aliased crops across a ~7 km area, the loss-minimizing response to ambiguity is the mean of plausible positions, i.e. the map center, so gradient descent never leaves that regime. Reparameterizing localization as softmax classification over a 16x16 grid of normalized-coordinate cells (cross-entropy) plus a regression head for the fractional offset within the cell gives a loss whose minimum under ambiguity is a multi-modal distribution over candidate cells rather than their average, letting the model commit to discrete place hypotheses; argmax decoding at inference then escapes the center-collapse entirely.
Method
model/model.py: keep the conv backbone identical; replace the 3-unit head with three heads off the GAP feature — 256 cell logits (16x16 grid over normalized u,v; bbox-generic since cells are defined in [0,1]^2), a 2-unit sigmoid within-cell offset head, and the unchanged loose-BCE confidence head (so coverage does not collapse and attribution stays on the localization mechanism). loss_fn becomes cross-entropy on the true cell + MSE on the true within-cell offset + 0.1*conf BCE. forward() decodes argmax cell + offset to [[u,v,conf]] so the ONNX export contract and frozen scorer are untouched. model/train.py changes only the loss call to use the raw heads.
Conclusion at the time
REVERTED — metric did not improve (3429.15 m vs best 2968.56 m); change discarded
Re-measured on today's ruler
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 3.58 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 3.43 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Bootstrap · ts 2026-07-20T19:12:30 ·
commit 7b7b491a32b5 · artifacts runs/20260720_190612_iter1 ·
took —
The code for this experiment — not retained
Source not retained. Until 2026-07-31 the loop discarded a reverted experiment’s code outright, and this row predates that fix. Its design record, its verdict and its exported model survive; the code does not. It is left blank rather than filled with the parent’s code, which is what this row’s recorded commit actually contains.
▸
1.4
Split rebalance — 360 m blocks so the no-leakage buffer stops eating the train area 2e5b3020
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 2.001 — worse than silence.
other
2.001
—
—
KEPT
Hypothesis
With 144 m blocks, the rotation-window buffer around eval blocks rejected most train positions (~11k train vs ~15.6k eval per area — 59% of usable positions were eval). Enlarging blocks to 360 m should cut buffer frequency and roughly quadruple train positions (~45k per area) without weakening the leakage guarantee; the naive baseline's score should stay in the center-guess regime since 3 epochs on 4.8k crops still cannot memorize a 7 km area.
Method
pipeline/dataset.py BLOCK_PX 144 -> 360 (frozen-pipeline data revision during bootstrap, before Phase 2 starts; eval sets change, so this is a new comparison baseline). Baseline model and training unchanged.
Conclusion at the time
KEPT as the new Phase 2 starting best (eval sets changed, so prior scores are not comparable). Training-data bottleneck removed: the frozen split now offers ~4x more train positions per area.
Re-measured on today's ruler
Mission score 2.001 — 0.0% of held-out frames give a usable fix, 100.0% are confident and wrong, 0.0% abstain. Median miss 2.58 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 2.97 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
2.0010% usablecov 1.00
era Bootstrap · ts 2026-07-20T18:55:57 ·
commit 2e5b3020e8f9 · artifacts runs/bootstrap_baseline_v3 ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
1.3
Data v2 baseline — same TinyLocNet on 1 m/px DOP imagery, all 4 dev areas c0a1bdfe
The loop kept this — it beat the running best under the metric then in force. On today's ruler it scores 1.996 — worse than silence.
other
1.996
—
—
KEPT
Hypothesis
Switching reference imagery from 10 m Sentinel-2 to 1 m open DOP orthophotos (UAV-scale crops, 128 m footprint) resets the task: the naive baseline should again land near the center-guess bound (~2.5-3 km for ~7 km boxes) since 3 epochs on 4.8k crops cannot memorize a 7 km area at 1 m detail, but the harness must run unchanged across all four development areas, proving the registry-driven fetch and GSD-aware relighting are bbox- and source-generic.
Method
Frozen pipeline data v2 (pipeline/sources.yaml registry: BB-BE/BY/HE/HH DOP WMS at 1 m/px, Sentinel-2 fallback; GSD-aware relighting with meter-denominated lamp density and glow). Unchanged TinyLocNet + training procedure, 3 epochs, 800 crops/bucket, per-area models for berlin/prignitz/munich/frankfurt.
Conclusion at the time
Data v2 harness proven across all four development areas on 1 m/px DOP imagery; starting best for Phase 2 set to 2765.67 m. The abstention gate demonstrably works — a real (not hypothetical) failure mode was caught twice.
Re-measured on today's ruler
Mission score 1.996 — 0.2% of held-out frames give a usable fix, 99.8% are confident and wrong, 0.0% abstain. Median miss 3.20 km. Measured, not converted: its exported model was re-run through the current scorer for this page.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 2.77 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
Scoreboard — re-scored today
Produced by running this experiment's exported model through the current frozen scorer on the current eval set. It is not what this experiment was told at the time.
area
truedop 2024
berlin
1.9960% usablecov 1.00
era Bootstrap · ts 2026-07-20T18:02:26 ·
commit c0a1bdfe7738 · artifacts runs/bootstrap_baseline_v2 ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py79 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():# Baseline conf target is deliberately loose (abstain only on# catastrophic misses > half the map extent) so the naive model# stays scoreable instead of abstaining its way into the §6# coverage FAIL; calibrating confidence properly is an obvious# loop research target.
good =(coord_err.sqrt()<0.5).float()
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
▸
1.2
Harness smoke test (SKIP_AGENT loop.sh iteration, 1 epoch) 0687f20e
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
other
—
—
—
NO SCORE
Hypothesis
loop.sh mechanics (train/score/log/keep-revert/gallery) function without an agent
Conclusion at the time
Loop mechanics verified; metric delta is training-noise, not an improvement in method
Not on today's ruler
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 2.19 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
era Bootstrap · ts 2026-07-20T17:21:22 ·
commit 0687f20ea168 · artifacts runs/20260720_172115_iter1 ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py74 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():
good =(coord_err.sqrt()<0.05).float()# within 5% of map extent
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
The loop kept this — it beat the running best under the metric then in force. It cannot be placed on today's ruler at all — see the row for why.
architecture
—
—
—
NO SCORE
Hypothesis
A ~300k-param from-scratch CNN trained for 3 epochs will produce a valid end-to-end harness run but nowhere near the 20 m target; its error should approach the trivial 'predict the area center' bound (~2.9 km for a 7 km box), confirming the metric, gates, and lineage plumbing are trustworthy before the autoresearch loop starts.
Method
Frozen pipeline run unmodified on two structurally different bboxes (berlin dense-urban, prignitz rural): Sentinel-2 fetch -> 6-bucket relighting -> per-area TinyLocNet training with rotation augmentation -> ONNX export -> frozen §6 scoring with deployment gates.
Conclusion at the time
Harness proven end-to-end on two areas with unmodified bbox-generic pipeline; baseline behaves as hypothesized (near center-guess bound). Ready for Phase 2 loop.
Not on today's ruler
It ran on 10 m/px imagery, before the switch to 1 m/px orthophotos. Feeding it today's crops would not be asking it the same question, so it is left unscored rather than given a number that means nothing.
What it cost
No agent accounting survives for this experiment — its run directory was deleted. That is a missing receipt, not a zero.
What it was measured against then
Optimised: worst-case median error (m), scoring 2.93 km. Asked over: region holdout, 6 lighting buckets, 4 areas. Harness proving runs. The imagery itself changed mid-era: experiments 1-2 ran on 10 m/px Sentinel-class tiles, and from experiment 3 on it was 1 m/px orthophoto (commit c0a1bdf, 2026-07-20 18:02 UTC). A 10 m/px model fed 1 m/px crops is not being asked the same question at all, so the first two are the only experiments in the whole project that cannot be placed on today's ruler.
era Bootstrap · ts 2026-07-20T17:19:49 ·
commit 15b43a251d60 · artifacts runs/bootstrap_baseline ·
took —
The code for this experiment — its code, from the commit
Read back out of this experiment’s own commit. It was kept, so the loop committed model/ and then recorded that commit — the tree is this experiment’s code. · on GitHub ↗
model/model.py74 lines
"""AGENT-EDITABLE — model architecture + deployment inference wrapper.The autoresearch loop may rewrite anything here (architecture, loss,confidence mechanism, unified vs. dispatcher+specialists, pretrained initper CLAUDE.md §3/§9) as long as: - train.py exports one ONNX per area at <out>/models/<area>.onnx taking a 1x3x128x128 float32 input in [0,1] and returning [[u, v, conf]] with u, v normalized map coords and conf in [0,1]; - the export passes pipeline/score.py's frozen deployment gates.Baseline: deliberately naive tiny CNN direct-coordinate regressor, from-scratchinit. It exists to prove the harness, not to be good."""import numpy as np
import torch
import torch.nn as nn
class TinyLocNet(nn.Module):"""~300k-param CNN: strided conv stack -> GAP -> (u, v, conf)."""def __init__(self):
super().__init__()
chans =[3,16,32,64,128]
layers =[]for cin, cout in zip(chans, chans[1:]):
layers +=[nn.Conv2d(cin, cout,3, stride=2, padding=1),
nn.BatchNorm2d(cout), nn.ReLU(inplace=True)]self.features = nn.Sequential(*layers)self.head = nn.Linear(chans[-1],3)def forward(self, x):
f =self.features(x).mean(dim=(2,3))
out =self.head(f)
uv = torch.sigmoid(out[:,:2])
conf = torch.sigmoid(out[:,2:3])return torch.cat([uv, conf], dim=1)def build_model()-> nn.Module:return TinyLocNet()def loss_fn(pred: torch.Tensor, target_uv: torch.Tensor)-> torch.Tensor:"""MSE on coords + BCE training the conf head to predict 'error is small'."""
coord_err =((pred[:,:2]- target_uv)**2).sum(dim=1)
coord_loss = coord_err.mean()with torch.no_grad():
good =(coord_err.sqrt()<0.05).float()# within 5% of map extent
conf_loss = nn.functional.binary_cross_entropy(
pred[:,2].clamp(1e-6,1-1e-6), good)return coord_loss +0.1* conf_loss
def export_onnx(model: nn.Module, path: str):
model.eval()
dummy = torch.zeros(1,3,128,128)
torch.onnx.export(model, dummy, path, input_names=["frame"],
output_names=["uvc"], opset_version=17, dynamo=False)def estimate_position(frame: np.ndarray, onnx_path: str, meta: dict):"""Deployment-shaped inference: frame (128x128x3 uint8) -> (lat, lon, conf). On-device this maps to the P4 runtime; here it runs the same ONNX artifact. """import onnxruntime as ort
from pipeline.common import px_to_lonlat
sess = ort.InferenceSession(onnx_path, providers=["CPUExecutionProvider"])
x = frame.astype(np.float32).transpose(2,0,1)[None]/255.0
u, v, conf = sess.run(None,{"frame": x})[0][0]
lon, lat = px_to_lonlat(meta, float(u)* meta["width"], float(v)* meta["height"])return lat, lon, float(conf)
model/train.py101 lines
"""AGENT-EDITABLE — training procedure. One model per area (CLAUDE.md §1).Baseline: sample train-split crops from all six relight buckets with randomrotation augmentation, train TinyLocNet briefly, export ONNX.Usage: python -m model.train --area berlin --out-dir runs/<id> [--epochs 2]"""import argparse
import json
import time
from pathlib import Path
import numpy as np
import torch
from PIL import Image
from model.model import build_model, export_onnx, loss_fn
from pipeline.common import DATA_DIR, LIGHTING_BUCKETS, area_dir, load_meta
from pipeline.dataset import crop_center_norm, extract_crop, list_crops
def load_training_tensors(area: str, data_dir: Path, max_crops_per_bucket: int, rng):
meta = load_meta(area, data_dir)
crops = list_crops(area, meta["width"], meta["height"],"train")
xs, ys =[],[]for bucket in LIGHTING_BUCKETS:
img = np.asarray(Image.open(area_dir(area, data_dir)/"relight"/ f"{bucket}.png"))
picks = rng.choice(len(crops), size=min(max_crops_per_bucket, len(crops)),
replace=False)for i in picks:
c = crops[i]
angle = float(rng.uniform(0,360))# heading augmentation
xs.append(extract_crop(img, c["cx"], c["cy"], angle))
ys.append(crop_center_norm(meta, c["cx"], c["cy"]))
x = torch.from_numpy(np.stack(xs)).permute(0,3,1,2).contiguous().float()/255.0
y = torch.tensor(ys, dtype=torch.float32)return x, y
def train_area(area: str, out_dir: Path, data_dir: Path, epochs: int,
max_crops_per_bucket: int, seed: int)-> dict:
torch.manual_seed(seed)
rng = np.random.default_rng(seed)
device ="mps"if torch.backends.mps.is_available()else \
"cuda"if torch.cuda.is_available()else"cpu"
t0 = time.time()
x, y = load_training_tensors(area, data_dir, max_crops_per_bucket, rng)
model = build_model().to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)
n = len(x)
print(f"[{area}] {n} crops, device={device}")for epoch in range(epochs):
perm = torch.randperm(n)
losses =[]for i in range(0, n,64):
idx = perm[i:i +64]
xb, yb = x[idx].to(device), y[idx].to(device)
loss = loss_fn(model(xb), yb)
opt.zero_grad(); loss.backward(); opt.step()
losses.append(loss.item())
print(f"[{area}] epoch {epoch +1}/{epochs} loss={np.mean(losses):.4f}")
models_dir = out_dir /"models"
models_dir.mkdir(parents=True, exist_ok=True)
onnx_path = models_dir / f"{area}.onnx"
export_onnx(model.cpu(), str(onnx_path))return{"area": area,"n_train_crops": n,"epochs": epochs,"device": device,"train_seconds": round(time.time()- t0,1),"onnx_bytes": onnx_path.stat().st_size,"init":"from-scratch",# §9: log init strategy per experiment}def main():
ap = argparse.ArgumentParser()
ap.add_argument("--area", required=True)
ap.add_argument("--out-dir", required=True)
ap.add_argument("--data-dir", default=None)
ap.add_argument("--epochs",type=int, default=2)
ap.add_argument("--max-crops-per-bucket",type=int, default=800)
ap.add_argument("--seed",type=int, default=0)
args = ap.parse_args()
data_dir = Path(args.data_dir)if args.data_dir else DATA_DIR
out_dir = Path(args.out_dir)
info = train_area(args.area, out_dir, data_dir, args.epochs,
args.max_crops_per_bucket, args.seed)
out_dir.mkdir(parents=True, exist_ok=True)
train_log = out_dir /"train_info.json"
logs = json.loads(train_log.read_text())if train_log.exists()else[]
logs.append(info)
train_log.write_text(json.dumps(logs, indent=2))
print(json.dumps(info))if __name__ =="__main__":
main()
What do the columns and marks mean?
Mission score
The single number the loop optimizes, and
deliberately the product requirement rather than a statistic about
errors. The aircraft takes a vision fix every 5–10 s and it is
its only drift correction, so per frame exactly three things can happen:
it is confident and within 100 m (a usable fix — the
product), not confident (it abstains — safe, it waits), or
confident and wrong (a false fix — dangerous, it feeds a
wrong position into navigation). The score is
(1 − usable-fix rate) + false-fix rate: 0 means every frame
is a usable fix, 1.0 means it abstains on everything, 2.0 means it
is confidently wrong on everything — strictly worse than silence, which is
the point. Error statistics (median, geometric mean, p10, p25) are all still
recorded, but none is optimized: each was tried as the target and each rewarded
something the aircraft does not want.
Region-holdout (diagnostic)
A small 1-in-32-block slice of Berlin
is kept genuinely out of training and scored separately. It is logged and
never optimized — it cannot move keep/revert. Its only job is to show
whether the model has real spatial structure or is just a lookup table over
memorized vantages, so expect it to read far worse than the headline number.
That gap is information, not failure.
not tested (○)
Never measured. The design and code were fine as
far as anyone knows, but the cloud run failed before a result came back (no GPU
capacity, or the connection to the training machine dropped). It says nothing
about the idea, which the loop is free to try again.
gated fail (×)
The §6 score also enforces the aircraft's hard
limits: the exported model must fit the ESP32-P4 flight computer
(≤ 32 MiB exported, about 8 MiB once compressed to 8-bit for the
chip; 4 MiB until 1 November 2026) and answer within the latency budget
(≤ 250 ms host proxy), and it must produce at least one usable fix (a model
that only ever stays silent or is always wrong counts as failed; until
1 November 2026 this was a cruder rule that failed any cell abstaining on
> 80% of frames). Any violation scores the whole experiment as failed
regardless of accuracy.
rejected
Never trained at all. After a losing streak, the loop
demands a genuine pivot — every non-frozen part of the design must change,
not just the one piece that's gone stalest. If the proposed design doesn't
clear that bar (checked against the actual code diff, not just what the
agent claims it changed), it's rejected before spending any GPU time on
it.
cov (coverage)
Share of test frames the model was confident
enough to answer at all. Abstaining honestly on bad frames is allowed —
down to the 20% floor above.
Kept / Discarded
Karpathy-style loop discipline: branch from the
best code, run one focused experiment, keep the change (git commit)
only if the worst-case error improves — otherwise revert it. The
step line in the chart is the running best.
Eval-set reset (┆)
During the bootstrap phase the frozen
evaluation data itself was revised twice (10 m satellite → 1 m orthophotos;
then a split rebalance). Scores on different eval sets are measurements on
different rulers and must not be compared — the dashed vertical rule marks
the break, and the running-best line restarts there instead of pretending
continuity. From Phase 2 on, the eval set does not change.
Holdout (○)
Hamburg is the blind fifth area: structurally
different (port, river, spread-out), never seen by the loop, scored only as
a periodic read-only check. If its error diverges from the four development
areas, the pipeline has learned their quirks rather than a general method.
Its result never influences keep/revert.
Pivot-directed (▽)
After 4 consecutive experiments in a
row fail to beat the running best, the harness injects a mandatory pivot
preamble into the next design prompt: do not refine the champion's current
mechanism again — propose from a design family absent from the recent
history. Marked ones ran under that directive; the streak resets every time
an experiment is kept.
Cost
Estimated cloud-GPU spend for that one experiment: its
measured wall time × a $0.69/hr rate, billed continuously by the clock
(not per phase), so it covers the whole experiment — design, implementation,
training, scoring, publishing — not GPU time alone. Shown only for the middle,
rented-GPU window; the bootstrap and later local eras run at ~$0 marginal
compute and show —.
Category
Which lever the experiment pulls: architecture, loss,
augmentation, relighting, training procedure, or quantization.
Where the deployment numbers went
Exported model size, weight
initialization and single-frame latency each used to have a column. All three
were dropped: nearly every row read the same, and the size and latency gates
are already folded into the mission score — a model that misses either scores
as a gated fail, so the column was restating the Status column. All three
remain in the expanded record, and init also on the
model designs page.
Training set
Each area offers ~45,000 distinct training
positions (1 m/px, 128 m crops, times random rotation); how many crops an
experiment actually samples per lighting condition is its own choice and is
shown in the detail view. Training crops never overlap the eval blocks —
enforced by the frozen split, not by convention.
Agent prompt
Every loop experiment records the exact prompt its
headless agent received — expandable in the detail view, so any experiment
can be re-run or audited later.
In plain words
Each experiment's own jargon-free explanation of
what it tried, pre-registered alongside the technical design — read this
first if the title looks like alphabet soup.
One real test
The figure at the top of each detail view is not
an illustration: the same held-out Berlin viewpoint is fed to that
experiment's actual exported model, and the red glow on the map is the
probability field recovered from the deployed ONNX artifact itself —
with the true location (○), the model's answer (×), and the real miss
distance. Because every experiment sees the identical crop, any difference
between two figures is the mechanism change, not the example. The pipeline
sentence beneath names the stages; red
marks what that experiment changed (a “+” stage is training-only and never
flies).
Click any row — or any point in the chart — to see the
experiment's pre-registered hypothesis, method and expected outcome, the
measured result, the per-area × lighting scoreboard, and what the model
actually looked at.
Every experiment the project has run, across 6 evaluation eras. The lineage was wiped at each era boundary, so the numbering restarts inside every band — but the vertical scale is one ruler throughout. 61 of these were re‑measured for this chart by running their exported model through today’s frozen scorer on today’s held‑out viewpoints; 24 are native to the current era; 0 had their run artifacts deleted and have their usable- and false-fix rates recovered arithmetically from the logged record; 17 failed a deployment gate and had no working model to score, then or now. Nothing was converted by a fudge factor. Black means a new best on today’s ruler — the dot that lowered the step line. The step line is the best mission score anyone had actually achieved, and it is unbroken across the boundaries because the ruler no longer changes at them. What the loop decided at the time, under whatever metric was then in force, is in each dot’s tooltip; the two disagree often in the early bands, because the old metrics rewarded the wrong thing.
click anywhere or press Esc to close
scroll to zoom · drag to pan · double-click to reset