Alexis Rondeau

Newsfeed

Everything I publish, in the order I published it: dispatches from Twitter, videos from YouTube and notes from my vault, archived here in full — text, images, video and links — so they outlive the platforms.

921 dispatches since January 2012 · page 14 of 37

15 views

Thank you for the reminder for both, the idea and how well this was written.

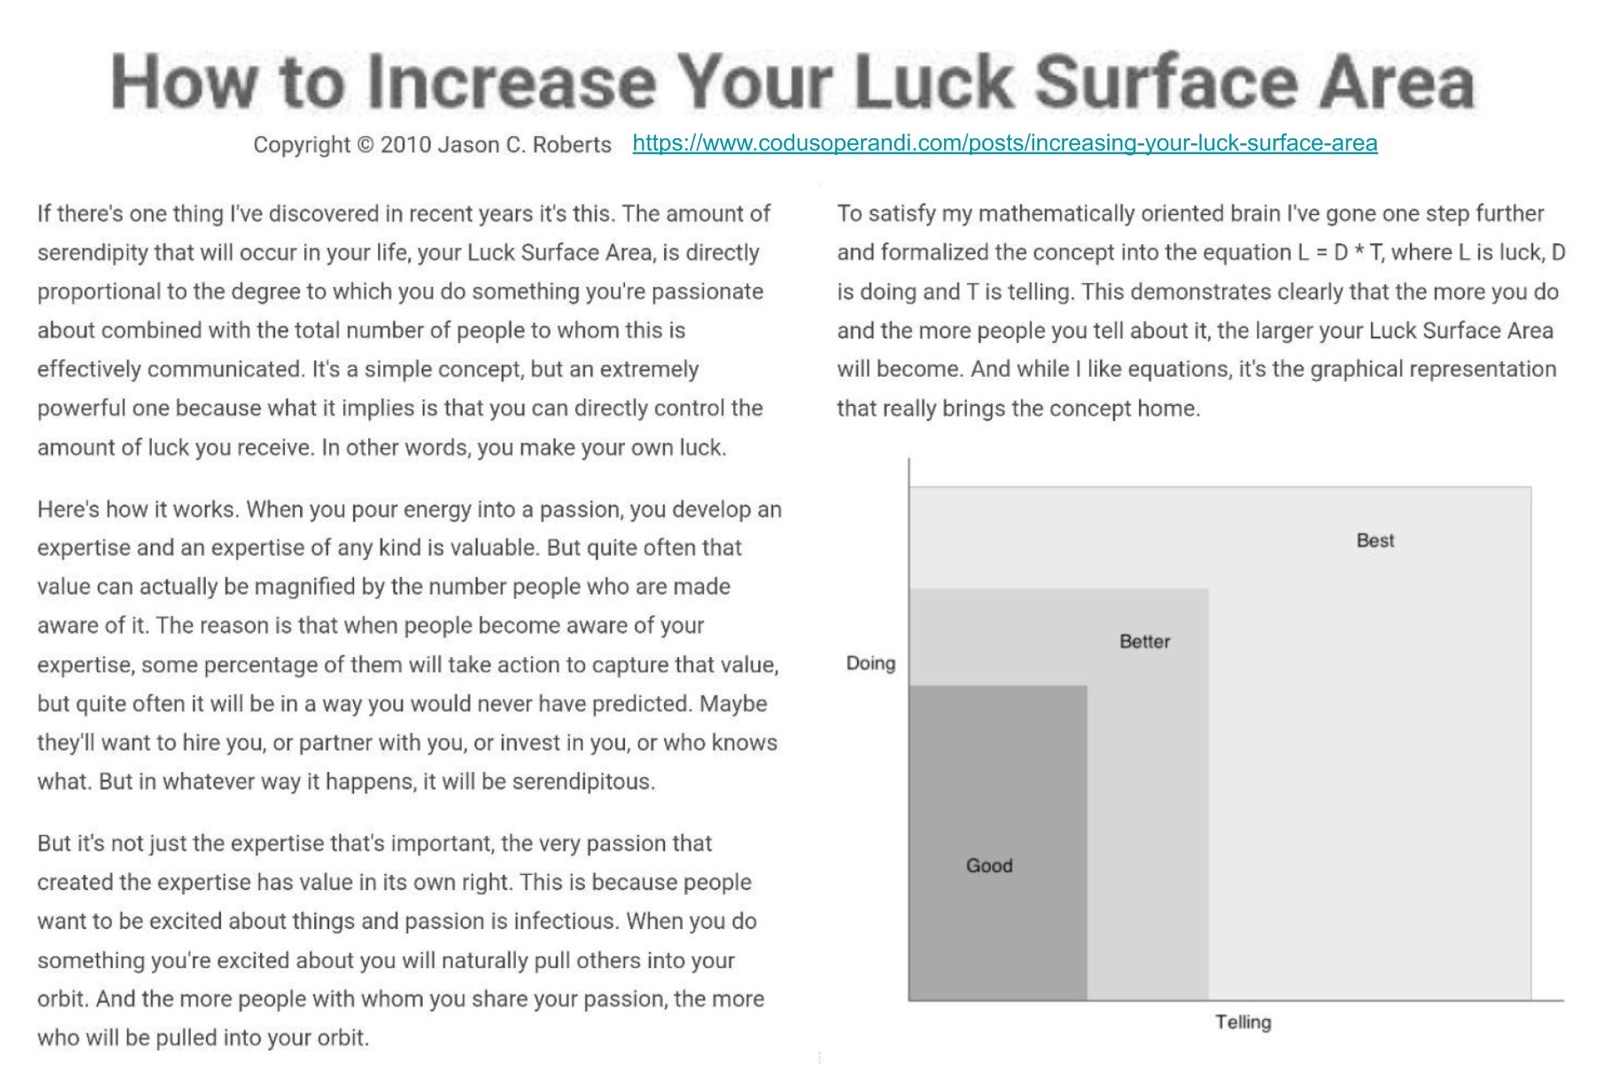
"... Luck Surface Area, is directly proportional to the degree to which you do something you're passionate about combined with the total number of people to whom this is effectively communicated. ..."

That's a banger summary IMHO.

Quoting @justinskycak · Jan 21, 2026

@hamptonism How to increase your luck surface area
(according to @exojason, who coined the phrase "Luck Surface Area" back in 2010)
t.co/s9kGqWPqRz t.co/h9azhFiDVI

Image from the post
1 like · 143 views

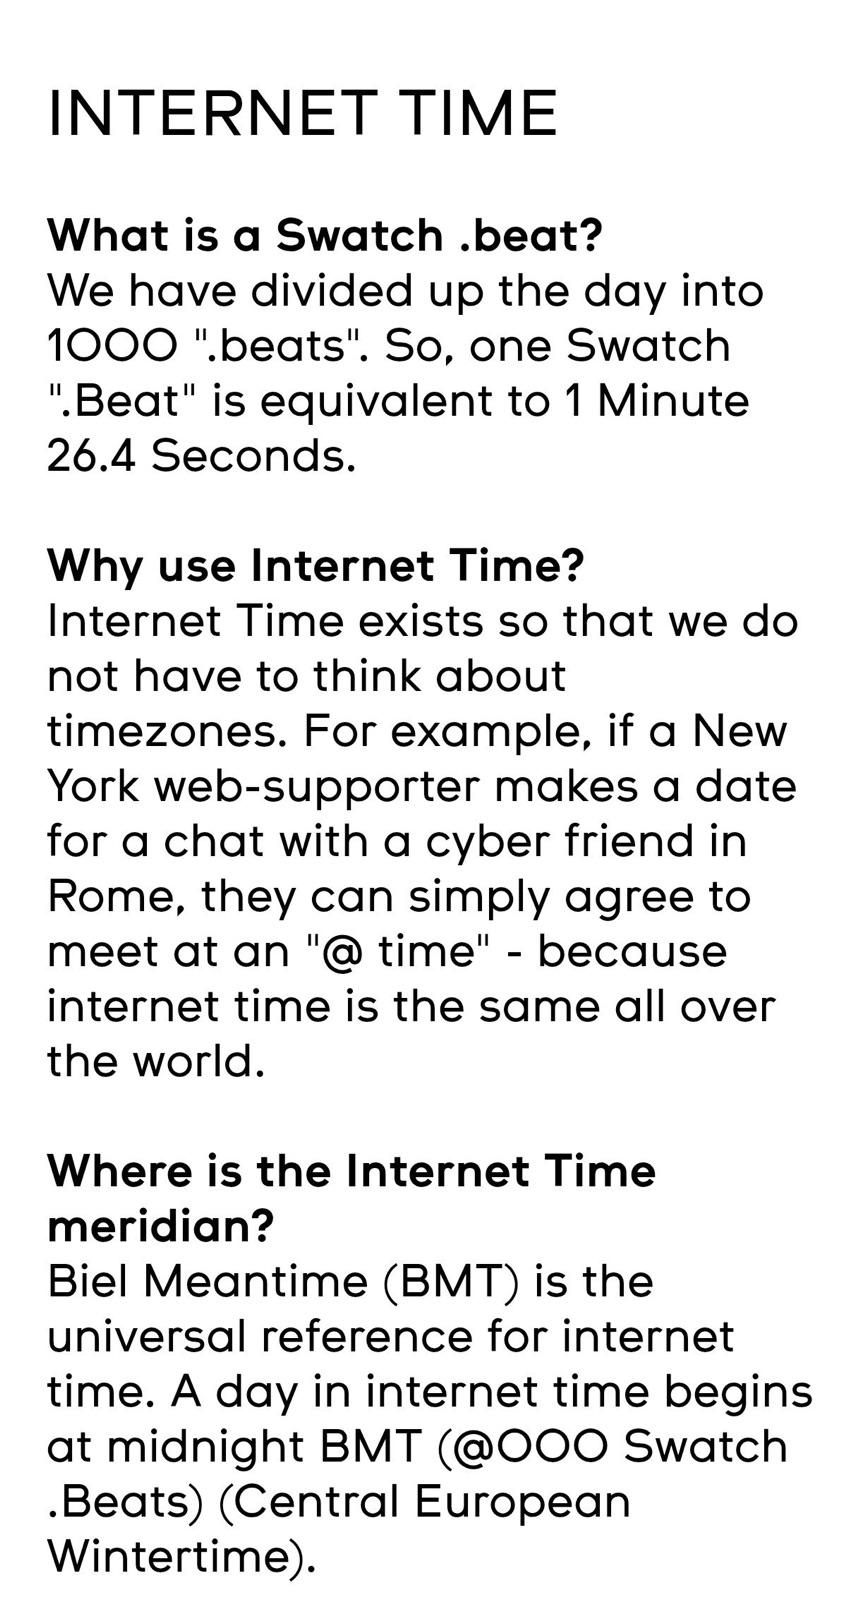
Still think Swatch's .beat Internet Time for living without timezones was such a solid idea. For web-supporters, cyber friends and everyone else!

Just went to their flagship store in Marseille and they said it's been discontinued for a while. I'd buy one right away.

Image from the post
swatch.comINTERNET TIMEWhat is a Swatch .beat? We have divided up the day into 1000 ".beats". So, one Swatch ".Beat" is equivalent to 1 Minute 26.4 Seconds.↗ swatch.com
24 views

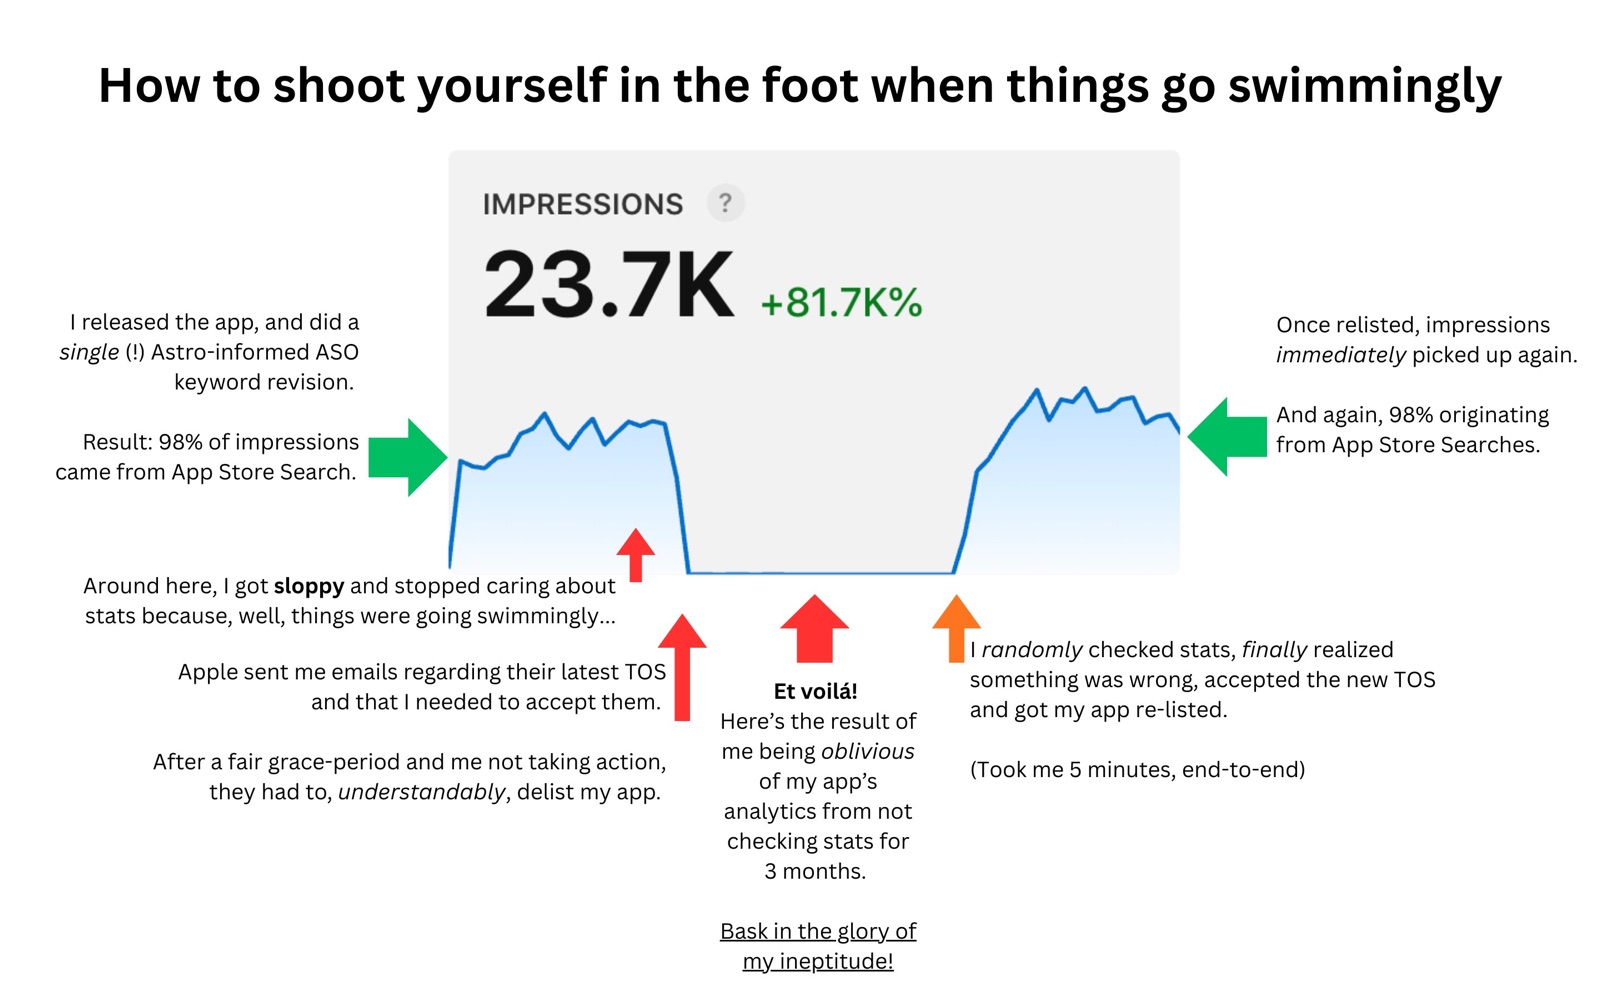
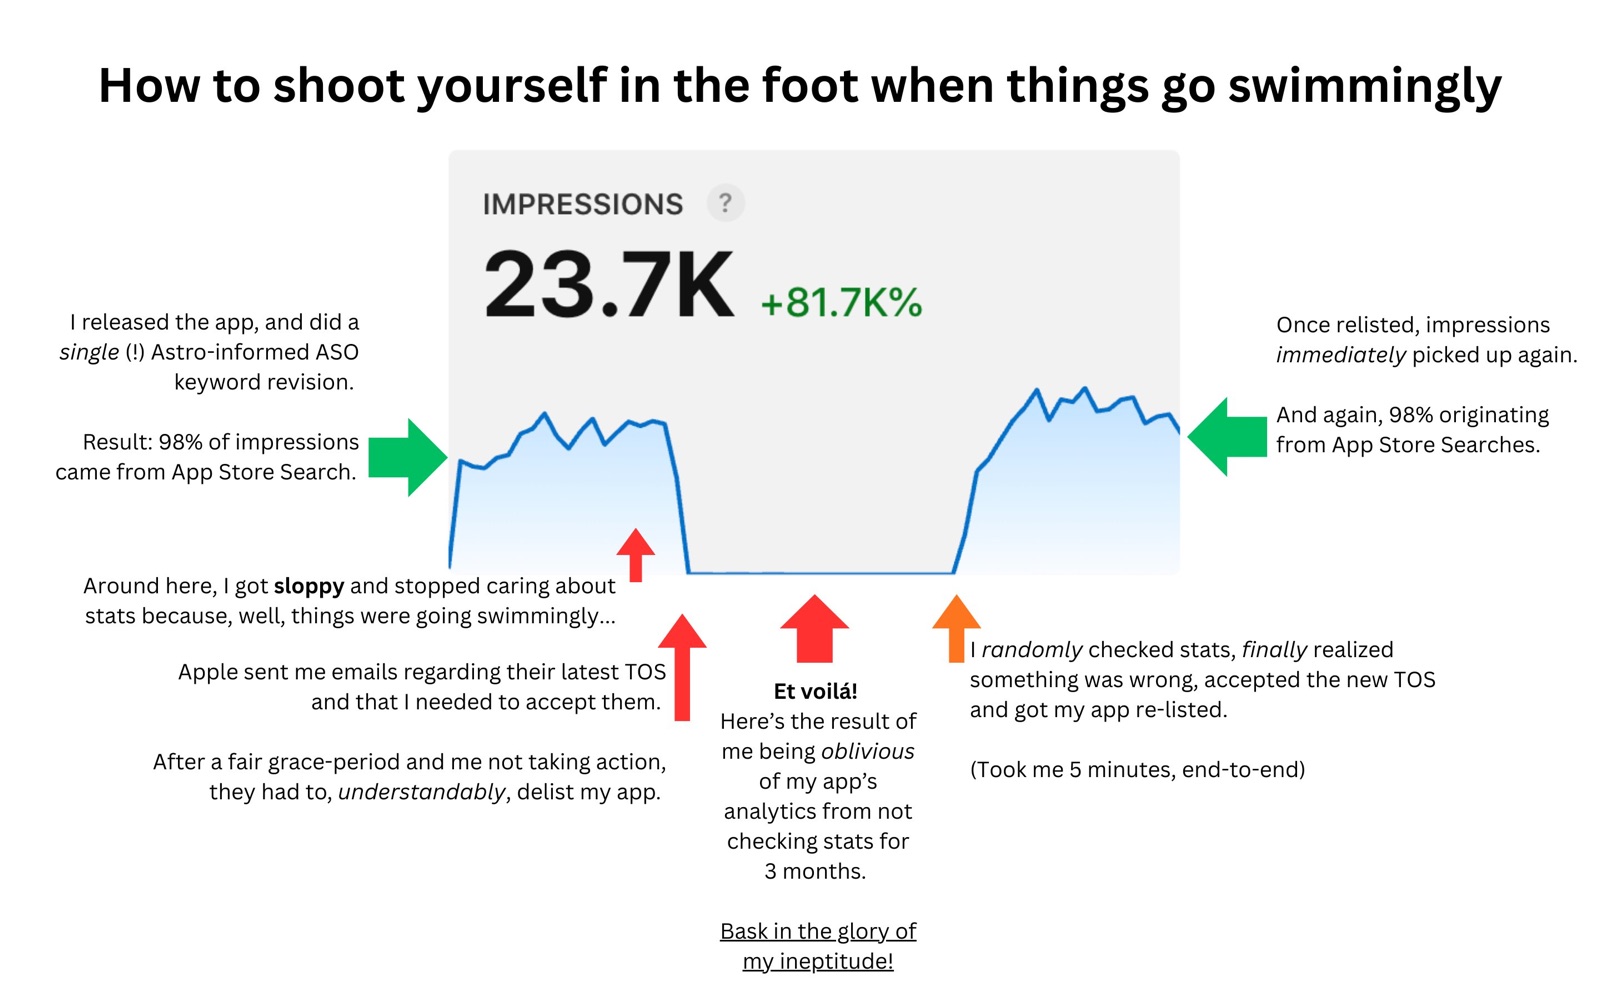
Proud of this one: "Bask in the glory of my ineptitude!" 🤪

Quoting @SpringStreetNYC · Dec 16, 2025

"How to shoot yourself in the foot when things go swimmingly" – A short story of the rise, fall and rise of a small macOS app I published last year.

TLDR;
1. ASO with @TryAstroApp works. Like, really, really well.
2. Nothing can save your app, not even ASO, when you stop caring.

Image from the post
71 views

Noted. Using my Luminette before breakfast affected my sleep-quality more than using it throughout the day.
For anyone interested: I've compiled 8 years of experiments with bright light therapy devices here:

Quoting @caloriesproper2 · Dec 15, 2025

For every 30 minutes of sun exposure before 10am, you fall asleep 20 minutes earlier at night and sleep quality is significantly improved ☀️ 🌑 💤 t.co/ImjZRmjnFJ

Image from the post
publish.obsidian.md⭐️ Happier Through Bright Light (Experiment) - Alexis Rondeau - Obsidian Publish⭐️ Happier Through Bright Light (Experiment) - Alexis Rondeau - Powered by Obsidian Publish.↗ publish.obsidian.md
1 like · 186 views

And from what I understand also built from scratch!

Quoting @Teknium · Dec 12, 2025

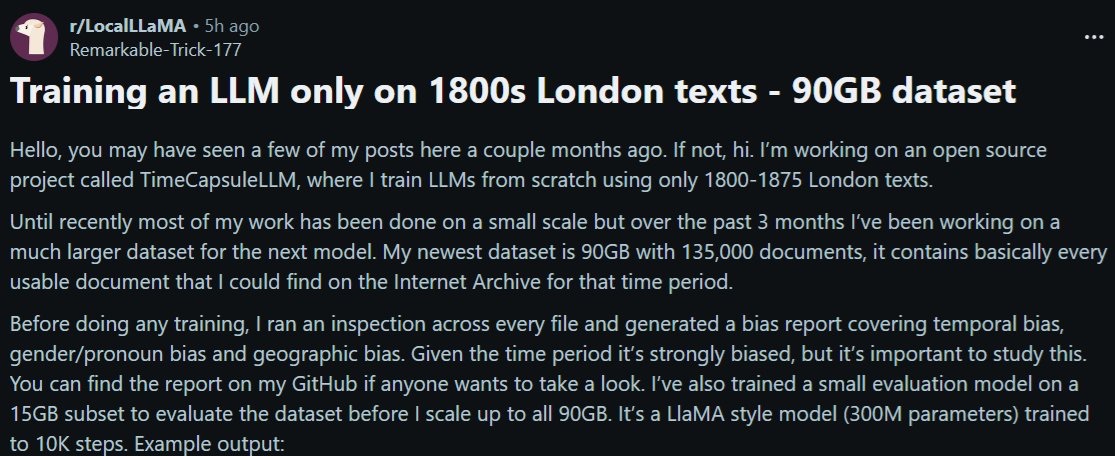
Very cool project that a lot of people have asked for for a long time, an LLM trained on 90GB of only 1800s and older texts

t.co/pio0FXssp4 t.co/ch1pxIWaHm

Image from the post
GitHubGitHub - haykgrigo3/TimeCapsuleLLM: A LLM trained only on data from certain time periods to reduce modern biasA LLM trained only on data from certain time periods to reduce modern bias - haykgrigo3/TimeCapsuleLLM↗ github.com
15 views
In reply to @SpringStreetNYC · Dec 5, 2025

LOL, got 100% nerd-sniped by my friend Sönke this week and wound up building a small spaceship.

On Monday he's like "Hey, what if you found obscure seed phrases embedded in public texts? You'd only need to remember the name of the book and the paragraph and go from there."

I honestly could care less about crypto(currencies) and I'm 100% sure this is like cryptanalysis 101. But, yeah, it seemed like an interesting problem anyways.

First, I downloaded a few hundred books from Gutenberg, wrote a ruby script and found BIP39 word sequences with a tolerable buffer for filler-words.

Then, I was like, okay, gotta now check them against actual addresses. Downloaded a list of funded ETH addresses. Wrote the checker in ruby. Ran it. No hits but this was now definitely weirdly interesting.

Because: And what if I downloaded the whole pg19 text corpus to scan! And what if I'd add BTC addresses! And what if I checked every permutation of the seed phrase!

Everything got really slow once I got to processing 12G of raw text for finding sequences and then checking a few million candidates with 44.000+ variations per candidate.

So, let's rewrite this into C! And since I've got 16 cores, let's parallelize this puppy! And since it's a MacBook, let's use GCD! Optimize all the things!

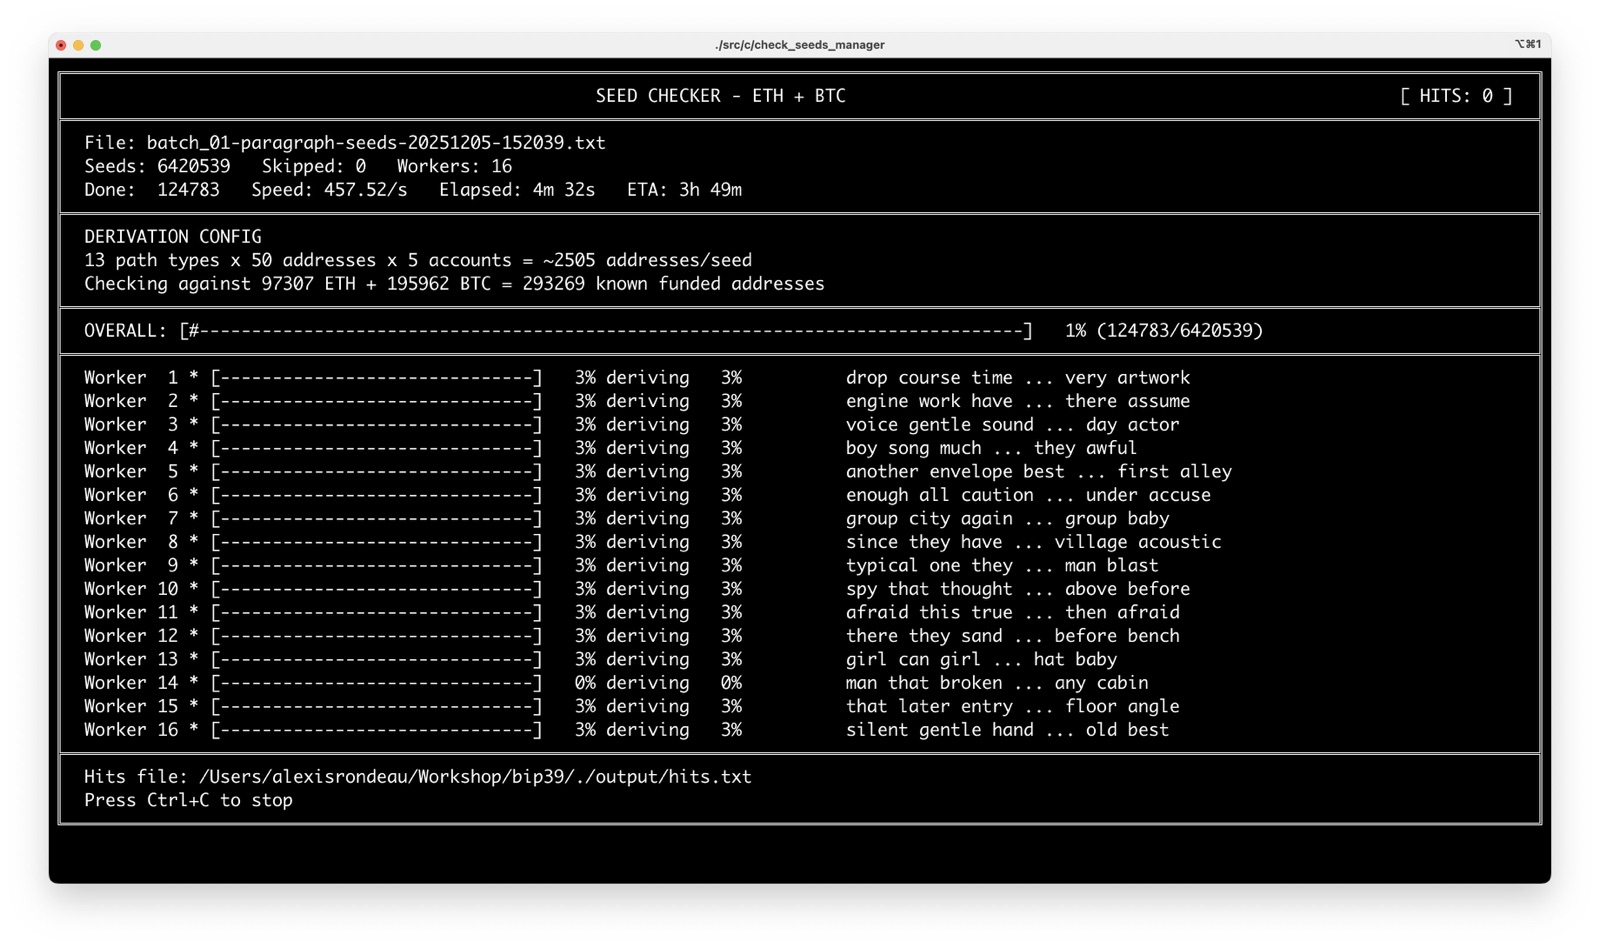
Lol, so NOW this thing is so fucking FAST. Takes four minutes to go through the full pg19 corpus and generates 64,205,390 "interesting" seed phrases. The fully parallelized checker (see Terminal screenshot) processes 460 derived addresses per second.

I really don't care if I get a match or not. I feel like I started with building a canoo and wound up with a spaceship is in itself just the best thing in the world.

Anyways. Just wanted to share this. If anyone wants, I can put the whole thing on github, too. Let me know!

Image from the post

Alright! Crazy-ass clang BIP39 scan/verify thingy is on github: github.com/akaalias/bipsc…

Here are the three main heavy-lifting workers:

-

GitHubGitHub - akaalias/bipscanContribute to akaalias/bipscan development by creating an account on GitHub.↗ github.com GitHubbipscan/src/c/generate_paragraph_seeds.c at main · akaalias/bipscanContribute to akaalias/bipscan development by creating an account on GitHub.↗ github.com GitHubbipscan/src/c/find_sequences_worker.c at main · akaalias/bipscanContribute to akaalias/bipscan development by creating an account on GitHub.↗ github.com GitHubbipscan/src/c/check_seeds_worker_btc.c at main · akaalias/bipscanContribute to akaalias/bipscan development by creating an account on GitHub.↗ github.com

bipscan

2 stars · Ruby

BIP-39 Seed Phrase Finder

Find BIP-39 seed phrase sequences hidden in classic literature and generate seeds from common patterns.

Project Structure

bip39/
├── README.md
├── Gemfile
│
├── src/                        # All source code
│   ├── ruby/
│   │   ├── generators/         # Seed generators
│   │   │   ├── generate_paragraph_seeds.rb      # Text-based seeds
│   │   │   ├── generate_birthday_seeds.rb       # Birthday index patterns
│   │   │   ├── generate_birthday_hash_seeds.rb  # SHA256(date) seeds
│   │   │   ├── generate_password_seeds.rb       # Common password seeds
│   │   │   ├── generate_rockyou_seeds.rb        # Rockyou wordlist seeds
│   │   │   ├── generate_character_sequences.rb  # Pattern-based seeds
│   │   │   ├── find_sequences.rb                # Find sequences in texts
│   │   │   ├── find_sequences_texts.rb          # Wrapper for texts/
│   │   │   ├── find_sequences_pg19.rb           # Wrapper for pg19/
│   │   │   └── check_seeds_etherscan.rb         # Etherscan API checker
│   │   └── lib/                # Shared modules
│   │       ├── bip39_common.rb
│   │       ├── seed_utils.rb
│   │       ├── sequence_utils.rb
│   │       └── sequence_generators/   # Pattern generator modules
│   │           ├── base.rb
│   │           ├── character_based.rb
│   │           ├── constructed_constants.rb
│   │           ├── cultural.rb
│   │           ├── deeper_constants.rb
│   │           ├── famous_random.rb
│   │           ├── math_based.rb
│   │           ├── mathematical_constants.rb
│   │           ├── memorable_patterns.rb
│   │           ├── misc.rb
│   │           ├── name_based.rb
│   │           ├── name_crypto.rb
│   │           ├── pattern_based.rb
│   │           ├── physics_constants.rb
│   │           ├── pin_patterns.rb
│   │           ├── prime_patterns.rb
│   │           ├── report.rb
│   │           ├── visual_spatial.rb
│   │           └── weak_known.rb
│   │
│   ├── c/                      # High-performance C implementation
│   │   ├── check_seeds_manager.c      # TUI manager for checking
│   │   ├── check_seeds_worker_btc.c   # ETH+BTC address checker
│   │   ├── check_seeds_worker.c       # ETH-only address checker
│   │   ├── check_seeds_gpu.c          # GPU-accelerated checker
│   │   ├── generate_paragraph_seeds.c # Fast paragraph seed generator
│   │   ├── find_sequences_worker.c    # Fast sequence finder
│   │   ├── base58.c / base58.h        # Base58 encoding for BTC
│   │   ├── bech32.c / bech32.h        # Bech32 encoding for SegWit
│   │   ├── keccak256.h                # Keccak hash for ETH
│   │   ├── ripemd160_neon.h           # RIPEMD160 with NEON optimization
│   │   ├── uthash.h                   # Hash table library
│   │   ├── Makefile
│   │   └── metal/                     # Apple Metal GPU shaders
│   │       ├── metal_pbkdf2.h
│   │       ├── metal_pbkdf2.m
│   │       └── pbkdf2_sha512.metal
│   │
│   ├── scripts/                # Download utilities
│   │   ├── download_data.sh
│   │   ├── download_texts.sh
│   │   └── download_pg19.sh
│   │
│   ├── assets/                 # Report styling
│   │   └── pdf-style.css
│   │
│   └── test/                   # Test scripts
│       └── test_paragraph_seeds.sh
│
├── data/                       # Reference data (downloaded)
│   ├── bip39.txt               # BIP-39 wordlist (2048 words)
│   ├── eth_rich_addresses.txt  # ETH addresses to check
│   ├── btc_rich_addresses.txt  # BTC addresses to check
│   ├── metadata.csv            # Book metadata
│   └── wordlists/              # Password wordlists
│       └── rockyou.txt
│
├── docs/                       # Documentation
│   ├── BOOTSTRAPPING.md
│   ├── HISTORY.md
│   ├── PERFORMANCE.md
│   ├── RESEARCH.md
│   ├── STRATEGIES.md
│   └── SUMMARY.md
│
├── inputs/                     # Text corpora (downloaded, gitignored)
│   ├── texts/                  # Curated texts (~150 books)
│   └── pg19/                   # Project Gutenberg (~28K books)
│       └── batch_01..10/       # Split into 10 batches
│
├── output/                     # Generated files (gitignored)
│   └── seeds/                  # Generated seed phrases
│
└── reports/                    # Generated reports

Quick Start

1. Bootstrap Data

Download the essential data files (BIP-39 wordlist, address lists):

./src/scripts/download_data.sh

2. Download Text Corpora

# Curated texts (~150 classic books)
./src/scripts/download_texts.sh

# Or full PG19 corpus (~28K books, ~12GB)
./src/scripts/download_pg19.sh

3. Build C Workers

cd src/c && make btc manager paragraph

Generate Seeds

Paragraph-Based Seeds (from texts)

Extract BIP-39 words from paragraph starting points in literature:

# Generate 24-word seeds from curated texts (default)
ruby src/ruby/generators/generate_paragraph_seeds.rb texts

# Generate 12-word seeds
ruby src/ruby/generators/generate_paragraph_seeds.rb texts --words=12

# From PG19 corpus (split into 10 batches of ~2800 books each)
ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_01 --words=24
ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_02 --words=12
# ... through batch_10

Birthday-Based Seeds

Generate seeds using birthday date components as word indices:

# 24-word seeds (default)
ruby src/ruby/generators/generate_birthday_seeds.rb

# 12-word seeds
ruby src/ruby/generators/generate_birthday_seeds.rb --words=12

Generates seeds for years 1960-2000 using:

  • Multiple date formats (US, EU, ISO)
  • Full year and short year variants
  • Absolute indexing and walk-through modes

Birthday Hash Seeds

SHA256(date_string) derivation for all date formats:

ruby src/ruby/generators/generate_birthday_hash_seeds.rb --words=12
ruby src/ruby/generators/generate_birthday_hash_seeds.rb --words=24

Password-Based Seeds

Generate seeds from common passwords using SHA256 derivation:

ruby src/ruby/generators/generate_password_seeds.rb --words=12
ruby src/ruby/generators/generate_password_seeds.rb --words=24

Rockyou Wordlist Seeds

Generate seeds from the full rockyou.txt password list:

# First download rockyou.txt to data/wordlists/
ruby src/ruby/generators/generate_rockyou_seeds.rb --words=24

Character Sequence Seeds

Generate seeds using mathematical and linguistic patterns:

ruby src/ruby/generators/generate_character_sequences.rb

Methods include:

  • Character-based (a-z groupings, reverse order, alternating)
  • Mathematical (Fibonacci, primes, golden ratio, triangular numbers)
  • Pattern-based (word length, skip patterns, phonetic)
  • Cultural (keyboard layouts, musical scales, chess notation)

Regenerate All Seeds

mkdir -p output/seeds

ruby src/ruby/generators/generate_paragraph_seeds.rb texts --words=12
ruby src/ruby/generators/generate_paragraph_seeds.rb texts --words=24
ruby src/ruby/generators/generate_birthday_seeds.rb --words=12
ruby src/ruby/generators/generate_birthday_seeds.rb --words=24
ruby src/ruby/generators/generate_birthday_hash_seeds.rb --words=12
ruby src/ruby/generators/generate_birthday_hash_seeds.rb --words=24
ruby src/ruby/generators/generate_password_seeds.rb --words=12
ruby src/ruby/generators/generate_password_seeds.rb --words=24
ruby src/ruby/generators/generate_character_sequences.rb --words=12
ruby src/ruby/generators/generate_character_sequences.rb --words=24

ruby src/ruby/generators/generate_paragraph_seeds.rb texts --words=12
ruby src/ruby/generators/generate_paragraph_seeds.rb texts --words=24

ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_01 --words=12
ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_01 --words=24
ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_02 --words=12
ruby src/ruby/generators/generate_paragraph_seeds.rb pg19/batch_02 --words=24

Check Seed Phrases

Use the C-based parallel manager with live TUI:

./src/c/check_seeds_manager output/seeds/my_seeds.txt [workers]

Example UI:

╔══════════════════════════════════════════════════════════════════════════════════════════════════╗
║                              SEED CHECKER MANAGER - PARALLEL TUI                                 ║
╠══════════════════════════════════════════════════════════════════════════════════════════════════╣
║  File: my_seeds.txt                                                                              ║
║  Seeds: 75   Skipped: 25   Workers: 8   Hits: 0                                                  ║
║  Done:  10   Speed: 2.5/s   Elapsed: 4s   ETA: 26s                                               ║
╠══════════════════════════════════════════════════════════════════════════════════════════════════╣
║  OVERALL: [######################------------------------------] 40%  (10/25)                    ║
╠══════════════════════════════════════════════════════════════════════════════════════════════════╣
║  Worker  1 ● [##############################] deriving  85%      abandon ability able...         ║
║  Worker  2 ● [######################--------] checking 53000 addr  abuse access accident...      ║
╚══════════════════════════════════════════════════════════════════════════════════════════════════╝

Features:

  • Splits work across all CPU cores (configurable)
  • Live progress display for each worker
  • Shows derivation and checking phases
  • Resume support: Progress is saved automatically
  • Skip duplicates: Already-processed seeds are automatically skipped
  • Graceful Ctrl+C handling with progress persistence

Etherscan API Check

Check actual on-chain balances:

ruby src/ruby/generators/check_seeds_etherscan.rb output/seeds/my_seeds.txt YOUR_ETHERSCAN_API_KEY

Get an API key: https://etherscan.io/apis (free tier: 100K requests/day)

Output Files

All generators support --words=12 or --words=24 and include a marker in the filename:

  • texts-paragraph-12w-seeds-YYYYMMDD-HHMMSS.txt (12-word)
  • texts-paragraph-24w-seeds-YYYYMMDD-HHMMSS.txt (24-word)
  • birthday-absolute-full-year-us-12w-YYYYMMDD-HHMMSS.txt
  • etc.

Derivation Paths Covered

The seed checkers derive addresses from 14 different wallet formats:

NamePathDescription
BIP-44 Standardm/44'/60'/0'/0/{i}MetaMask, Trezor, most wallets
BIP-44 Accountsm/44'/60'/{a}'/0/{i}Multiple accounts (MetaMask)
Ledger Livem/44'/60'/{a}'/0/0Ledger Live (one addr per account)
Ledger Legacym/44'/60'/0'/{i}Ledger legacy, old MEW/Jaxx
BTC Legacym/44'/0'/0'/0/{i}Bitcoin P2PKH (1…)
BTC SegWitm/49'/0'/0'/0/{i}Bitcoin P2SH-SegWit (3…)
BTC Native SegWitm/84'/0'/0'/0/{i}Bitcoin Bech32 (bc1q…)

Where {a} = account index (0-19) and {i} = address index (0-499).

Total addresses derived per seed: ~53,000
18 views
In reply to @SpringStreetNYC · Dec 5, 2025

LOL, got 100% nerd-sniped by my friend Sönke this week and wound up building a small spaceship.

On Monday he's like "Hey, what if you found obscure seed phrases embedded in public texts? You'd only need to remember the name of the book and the paragraph and go from there."

I honestly could care less about crypto(currencies) and I'm 100% sure this is like cryptanalysis 101. But, yeah, it seemed like an interesting problem anyways.

First, I downloaded a few hundred books from Gutenberg, wrote a ruby script and found BIP39 word sequences with a tolerable buffer for filler-words.

Then, I was like, okay, gotta now check them against actual addresses. Downloaded a list of funded ETH addresses. Wrote the checker in ruby. Ran it. No hits but this was now definitely weirdly interesting.

Because: And what if I downloaded the whole pg19 text corpus to scan! And what if I'd add BTC addresses! And what if I checked every permutation of the seed phrase!

Everything got really slow once I got to processing 12G of raw text for finding sequences and then checking a few million candidates with 44.000+ variations per candidate.

So, let's rewrite this into C! And since I've got 16 cores, let's parallelize this puppy! And since it's a MacBook, let's use GCD! Optimize all the things!

Lol, so NOW this thing is so fucking FAST. Takes four minutes to go through the full pg19 corpus and generates 64,205,390 "interesting" seed phrases. The fully parallelized checker (see Terminal screenshot) processes 460 derived addresses per second.

I really don't care if I get a match or not. I feel like I started with building a canoo and wound up with a spaceship is in itself just the best thing in the world.

Anyways. Just wanted to share this. If anyone wants, I can put the whole thing on github, too. Let me know!

Image from the post

Small changes, up from 460 to 12,898 checks per second.

37 views

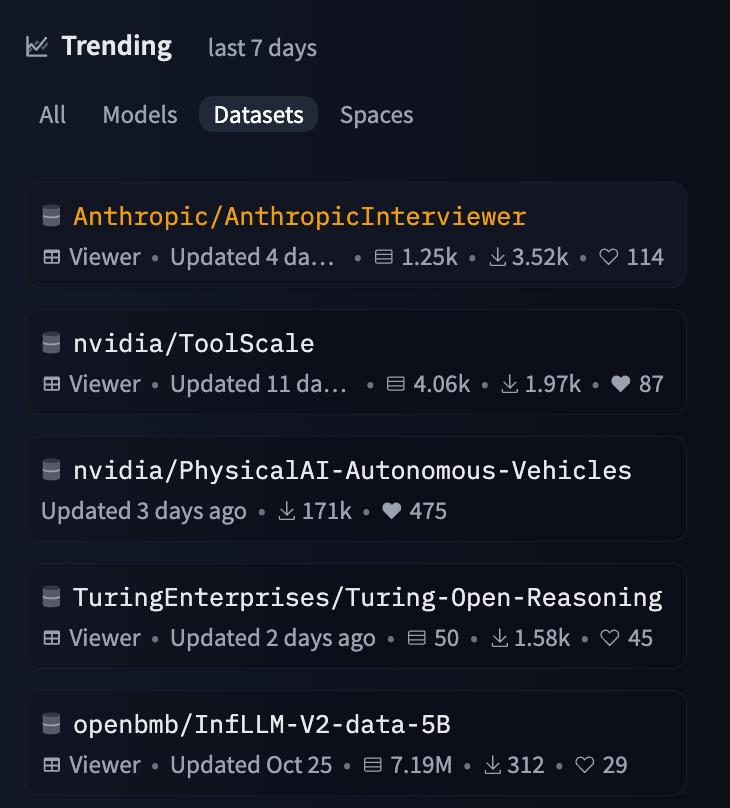
I took the interview just this morning!
Now, here's the whole dataset :D

Quoting @ClementDelangue · Dec 8, 2025

The @AnthropicAI interviewer dataset is number one trending on HF, congrats! t.co/gqmXtaAtk4 t.co/JBCCtxgP27

Image from the post
huggingface.coAnthropic/AnthropicInterviewer · Datasets at Hugging FaceWe’re on a journey to advance and democratize artificial intelligence through open source and open science.↗ huggingface.co
2 views

@haydendevs Wrote down an idea around this yesterday - basically have LLMs generate text using homoglyphs. Which would be perfectly readable and verifiably of non-human origin

Quoting @SpringStreetNYC · Dec 6, 2025

Idea for "marking" AI-generated text: Make a final pass that replaces the regular letters with UTF8 homoglyphs instead. Still 100% readable and verifiably of non-human origin.

Case in point, here's the homoglyph version of this message:

ꓲdеа fоr "mаrkіոց" ꓮꓲ-ցеոеrаtеd tехt: ꓟаkе а fіոаꓲ раѕѕ tһаt rерꓲасеѕ tһе rеցսꓲаr ꓲеttеrѕ ԝіtһ ꓴꓔꓝ8 һоmоցꓲурһѕ іոѕtеаd. ꓢtіꓲꓲ 100% rеаdаbꓲе аոd νеrіfіаbꓲу оf ոоո-һսmаո оrіցіո.

395 views
In reply to @kimmonismus · Dec 7, 2025

This is actually the biggest danger: that workers still have to keep it a secret that they use AI at work because so many employers still think AI is still at the GPT-4 level.

This has to change, ASAP. t.co/C80moLWxo2

Image from the post
finalroundai.comAnthropic Study Finds Most Workers Use AI Daily, but 69 Percent Hide It at WorkAnthropic research shows most workers rely on AI but stay quiet about it, with 69% reporting social stigma around using AI tools at work.↗ finalroundai.com
32 views
In reply to @SpringStreetNYC · Dec 6, 2025

Idea for "marking" AI-generated text: Make a final pass that replaces the regular letters with UTF8 homoglyphs instead. Still 100% readable and verifiably of non-human origin.

Case in point, here's the homoglyph version of this message:

ꓲdеа fоr "mаrkіոց" ꓮꓲ-ցеոеrаtеd tехt: ꓟаkе а fіոаꓲ раѕѕ tһаt rерꓲасеѕ tһе rеցսꓲаr ꓲеttеrѕ ԝіtһ ꓴꓔꓝ8 һоmоցꓲурһѕ іոѕtеаd. ꓢtіꓲꓲ 100% rеаdаbꓲе аոd νеrіfіаbꓲу оf ոоո-һսmаո оrіցіո.

Love it. Unicode calls them "confusables" and they have the full list here:

18 views
In reply to @SpringStreetNYC · Dec 5, 2025

LOL, got 100% nerd-sniped by my friend Sönke this week and wound up building a small spaceship.

On Monday he's like "Hey, what if you found obscure seed phrases embedded in public texts? You'd only need to remember the name of the book and the paragraph and go from there."

I honestly could care less about crypto(currencies) and I'm 100% sure this is like cryptanalysis 101. But, yeah, it seemed like an interesting problem anyways.

First, I downloaded a few hundred books from Gutenberg, wrote a ruby script and found BIP39 word sequences with a tolerable buffer for filler-words.

Then, I was like, okay, gotta now check them against actual addresses. Downloaded a list of funded ETH addresses. Wrote the checker in ruby. Ran it. No hits but this was now definitely weirdly interesting.

Because: And what if I downloaded the whole pg19 text corpus to scan! And what if I'd add BTC addresses! And what if I checked every permutation of the seed phrase!

Everything got really slow once I got to processing 12G of raw text for finding sequences and then checking a few million candidates with 44.000+ variations per candidate.

So, let's rewrite this into C! And since I've got 16 cores, let's parallelize this puppy! And since it's a MacBook, let's use GCD! Optimize all the things!

Lol, so NOW this thing is so fucking FAST. Takes four minutes to go through the full pg19 corpus and generates 64,205,390 "interesting" seed phrases. The fully parallelized checker (see Terminal screenshot) processes 460 derived addresses per second.

I really don't care if I get a match or not. I feel like I started with building a canoo and wound up with a spaceship is in itself just the best thing in the world.

Anyways. Just wanted to share this. If anyone wants, I can put the whole thing on github, too. Let me know!

Image from the post

I would say it's pretty performance but, the actual cryptanalysis is very naïve. I call it a cute-force attack 😁

18 views
In reply to @SpringStreetNYC · Dec 6, 2025

Idea for "marking" AI-generated text: Make a final pass that replaces the regular letters with UTF8 homoglyphs instead. Still 100% readable and verifiably of non-human origin.

Case in point, here's the homoglyph version of this message:

ꓲdеа fоr "mаrkіոց" ꓮꓲ-ցеոеrаtеd tехt: ꓟаkе а fіոаꓲ раѕѕ tһаt rерꓲасеѕ tһе rеցսꓲаr ꓲеttеrѕ ԝіtһ ꓴꓔꓝ8 һоmоցꓲурһѕ іոѕtеаd. ꓢtіꓲꓲ 100% rеаdаbꓲе аոd νеrіfіаbꓲу оf ոоո-һսmаո оrіցіո.

Until then you can also use Pudding to prove you're writing is human!

1 like · 32 views
In reply to @SpringStreetNYC · Dec 6, 2025

Idea for "marking" AI-generated text: Make a final pass that replaces the regular letters with UTF8 homoglyphs instead. Still 100% readable and verifiably of non-human origin.

Case in point, here's the homoglyph version of this message:

ꓲdеа fоr "mаrkіոց" ꓮꓲ-ցеոеrаtеd tехt: ꓟаkе а fіոаꓲ раѕѕ tһаt rерꓲасеѕ tһе rеցսꓲаr ꓲеttеrѕ ԝіtһ ꓴꓔꓝ8 һоmоցꓲурһѕ іոѕtеаd. ꓢtіꓲꓲ 100% rеаdаbꓲе аոd νеrіfіаbꓲу оf ոоո-һսmаո оrіցіո.

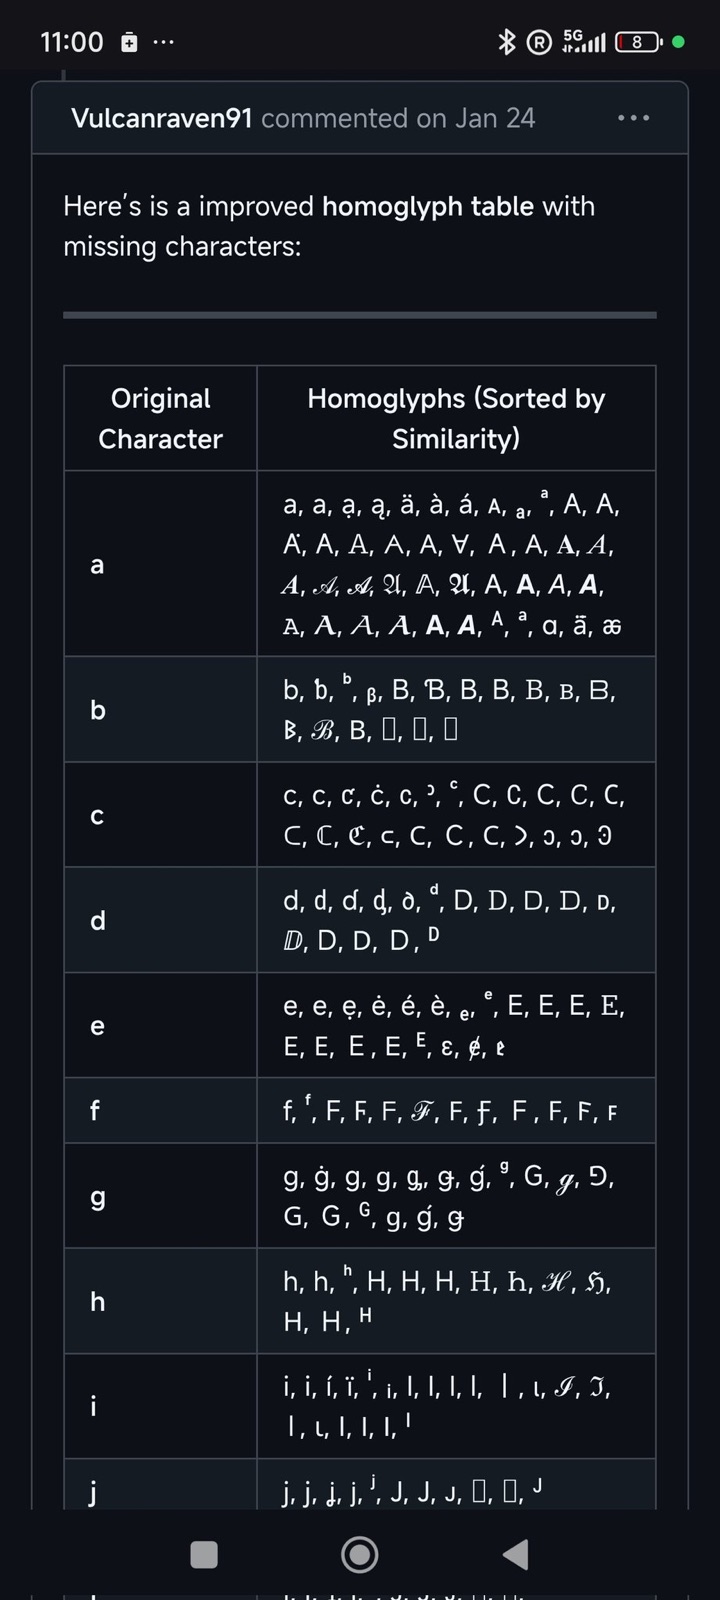
This conversation doesn't need to be covert either. In fact, I think that AI-generated text should have it's own visual voice! And it looks like, for the Latin alphabet at least, there are several 'typefaces" that could be built.

Source:

Image from the post
GistUnicode Look-alikesUnicode Look-alikes. GitHub Gist: instantly share code, notes, and snippets.↗ gist.github.com
3 replies · 1 like · 32 views

Idea for "marking" AI-generated text: Make a final pass that replaces the regular letters with UTF8 homoglyphs instead. Still 100% readable and verifiably of non-human origin.

Case in point, here's the homoglyph version of this message:

ꓲdеа fоr "mаrkіոց" ꓮꓲ-ցеոеrаtеd tехt: ꓟаkе а fіոаꓲ раѕѕ tһаt rерꓲасеѕ tһе rеցսꓲаr ꓲеttеrѕ ԝіtһ ꓴꓔꓝ8 һоmоցꓲурһѕ іոѕtеаd. ꓢtіꓲꓲ 100% rеаdаbꓲе аոd νеrіfіаbꓲу оf ոоո-һսmаո оrіցіո.