Alexis Rondeau

Newsfeed

Everything I publish, in the order I published it: dispatches from Twitter, videos from YouTube and notes from my vault, archived here in full — text, images, video and links — so they outlive the platforms.

857 dispatches since March 2014 · page 7 of 35

50 views
In reply to @SpringStreetNYC · Jun 8, 2026

Dear #wwdc

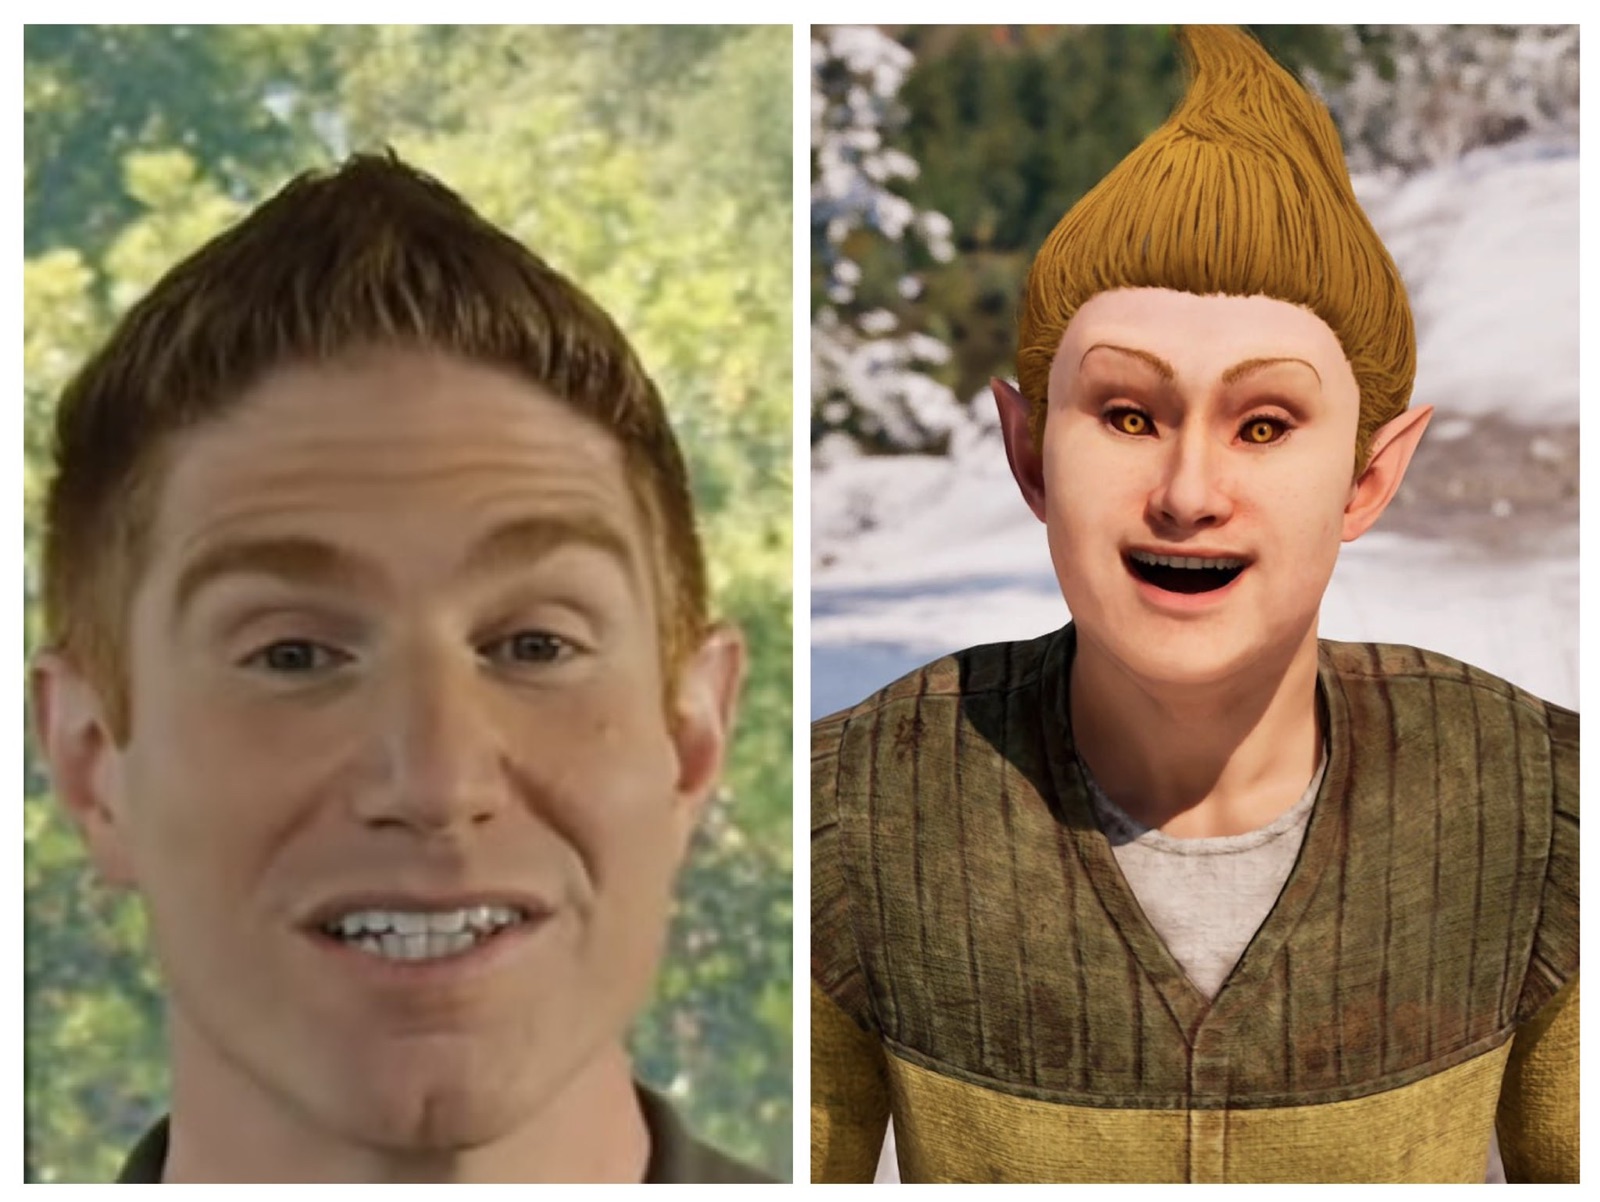
Right now and somewhere, the next Kane Parsons/Jony Ive/Steve Jobs is graduating from/dropping out of college. Given today's demos, they're CLEARLY NOT anywhere near SV but I'm sure you can find them.

PLEASE do and put them on those same $840k/year salaries. Give them a year or so. Let them define the next two decades IN and ON their own terms.

Thank you.

PS: Unintentionally made my list dude-only. Sorry about that. Add the next Jane Jacobs/Kiki Smith/Klári von Neumann to that list.
1 reply · 1 like · 20 views
In reply to @_ralRo · Jun 8, 2026

@SchallerDomenic Die diesjährige #WWDC war auf jeden Fall eine der ungewöhnlichsten der letzten zehn Jahre.
😟
Was haben sich @tim_cook und sein Team dabei gedacht?
🤷‍♂️
Ich bin irgendwie sprachlos.

@_ralRo @SchallerDomenic @tim_cook Jupp. Ich bin auch sprachlos.

Ein kleiner Teil in mir will glauben, dass das alles AI-generierten Figuren waren und es deswegen so ein Uncanny-Valley Gefühl ausgelöst hat.

I don't know. Einfach weird.

1 reply · 20 views
In reply to @LPirro93 · Jun 8, 2026

Not sure if I’m getting old or if today’s Apple #WWDC was super boring

@LPirro93 No, you're not getting old. In my opinion, this was really, really uninspired.

Been an Apple customer for 26 years myself. There was nothing about today that would have resonated with me way back in 1999.

(And I wasn't even a Jobs-fan, tbh.)

1 reply · 190 views

Dear #wwdc

Right now and somewhere, the next Kane Parsons/Jony Ive/Steve Jobs is graduating from/dropping out of college. Given today's demos, they're CLEARLY NOT anywhere near SV but I'm sure you can find them.

PLEASE do and put them on those same $840k/year salaries. Give them a year or so. Let them define the next two decades IN and ON their own terms.

Thank you.

1 reply · 74 views
In reply to @SchallerDomenic · Jun 8, 2026

@iPhone14ProDirk Es war ein reinfall diese #WWDC

Aber hallo. Was war denn das?

Bin seit 26 Jahren Apple-Kunde und dachte mir nach Goatee-Daddy #2 und Stressika aus der Buchhaltung einfach nur noch: Wir leben offensichtlich nicht auf dem gleichen Planeten.

Ich wünsche mir auch ganz ehrlich Jobs nicht zurück. Sondern mit dem Kapital muss doch was geiles gehen.

Anstelle diesen völlig banalen Konzern-Nasen, gebt doch ein paar Studenten jeweils die $840K/Jahr Gehälter. Da wird schon was gutes rauskommen, bin ich mir 100% sicher.

So wie damals mit Jony Ive in den späten 90ern.

Aber das? WAHNSINN.

68 views

Okay, thank you! I'm watching this in total disbelief.

Is this real? I had a moment with goatee-dude from accounting staring at his phone exactly as un-charismatically as I do.

Or Stressica from HR painfully pitching me context-awareness in Safari. Like, W. T. F?

Is this a simulation?

"We don't write the rules. We just discover them. With AI.": How an autonomous agent searches for the groundrule, and what makes the loop different

A job-shop scheduling problem dressed up as a lunch rush: one grill, one shared range, and sequencing as my only lever. Rather than hand-write the rule, I let an agent propose candidates, run them across simulated services, and keep whatever beat the champion — trained on six scenarios, then held out against three more to check it found a principle, not a memory. Built on Nima H. Siboni’s “The Heuristic Scientist: Open-Ended Algorithm Discovery with LLMs” workshop.

Open →

66 views
In reply to @SpringStreetNYC · Jun 1, 2026

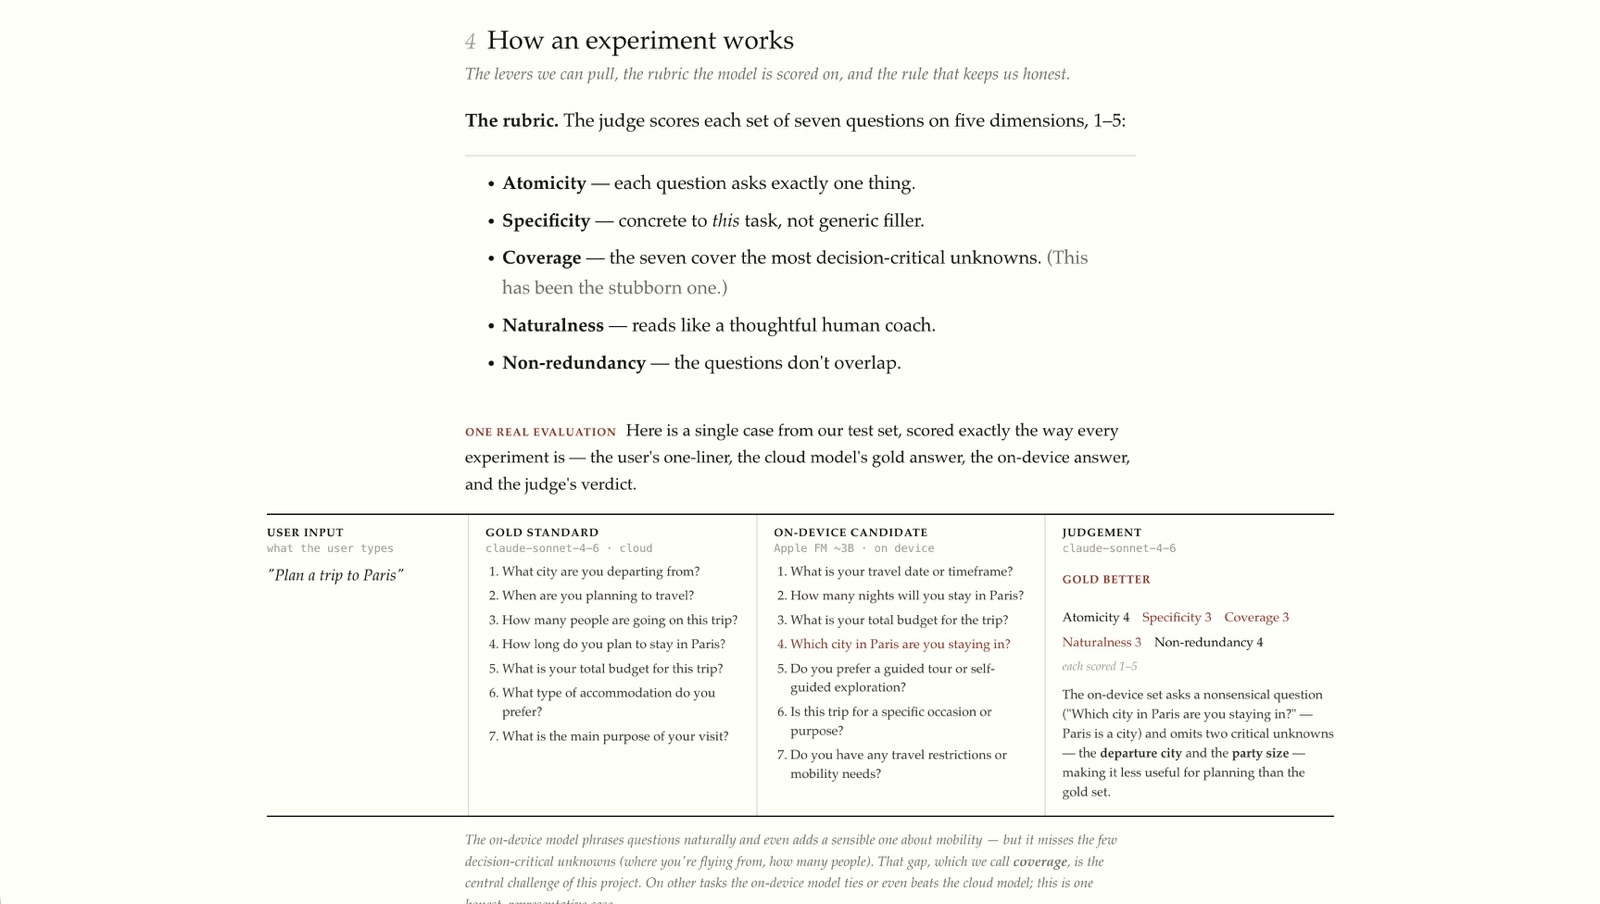
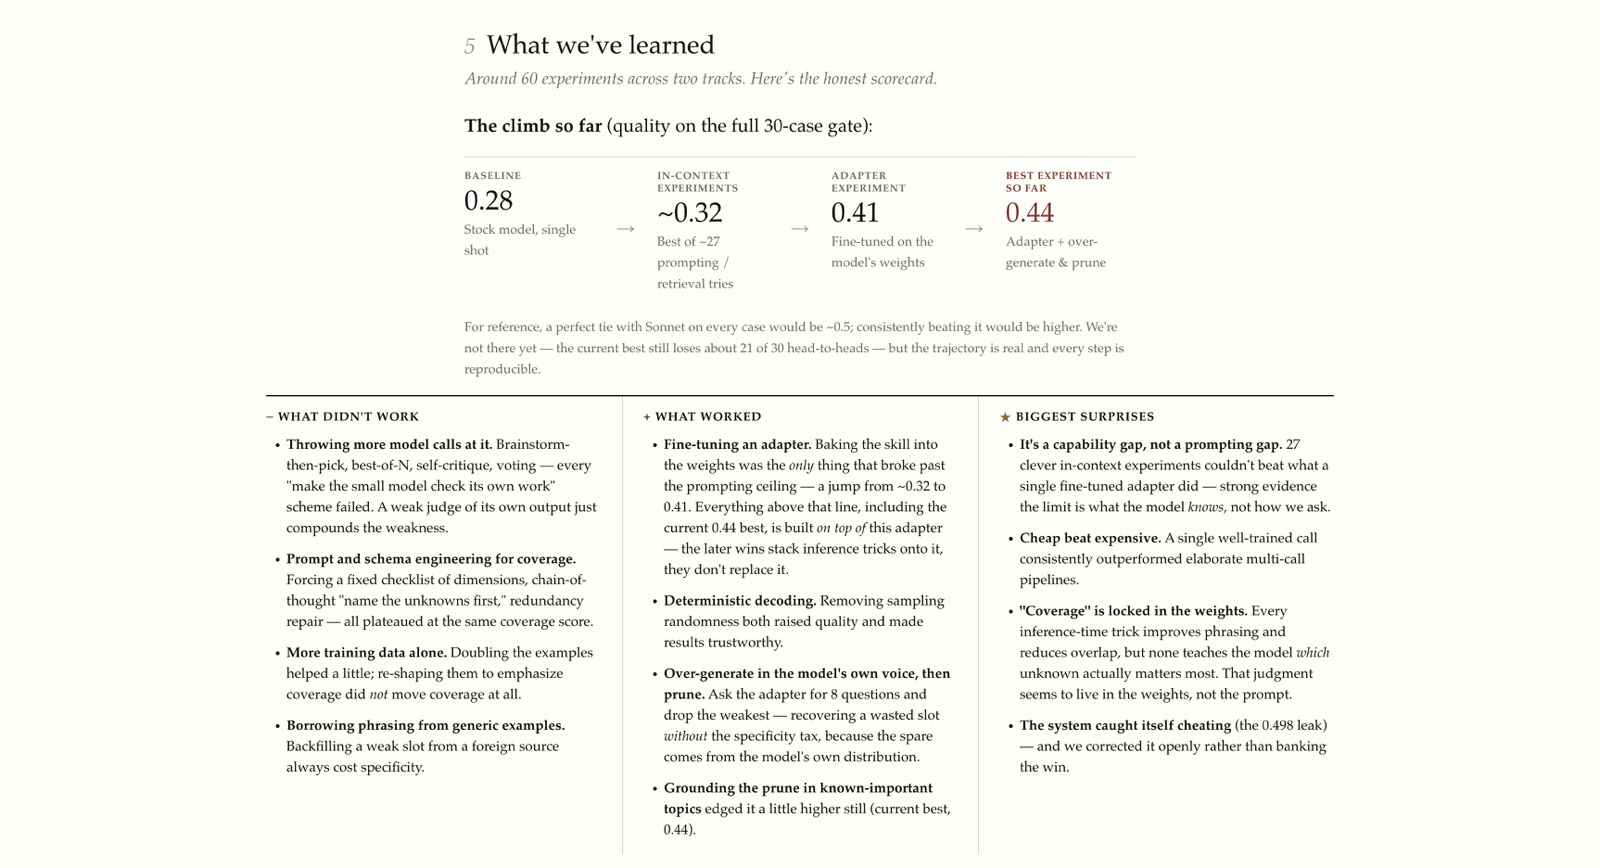
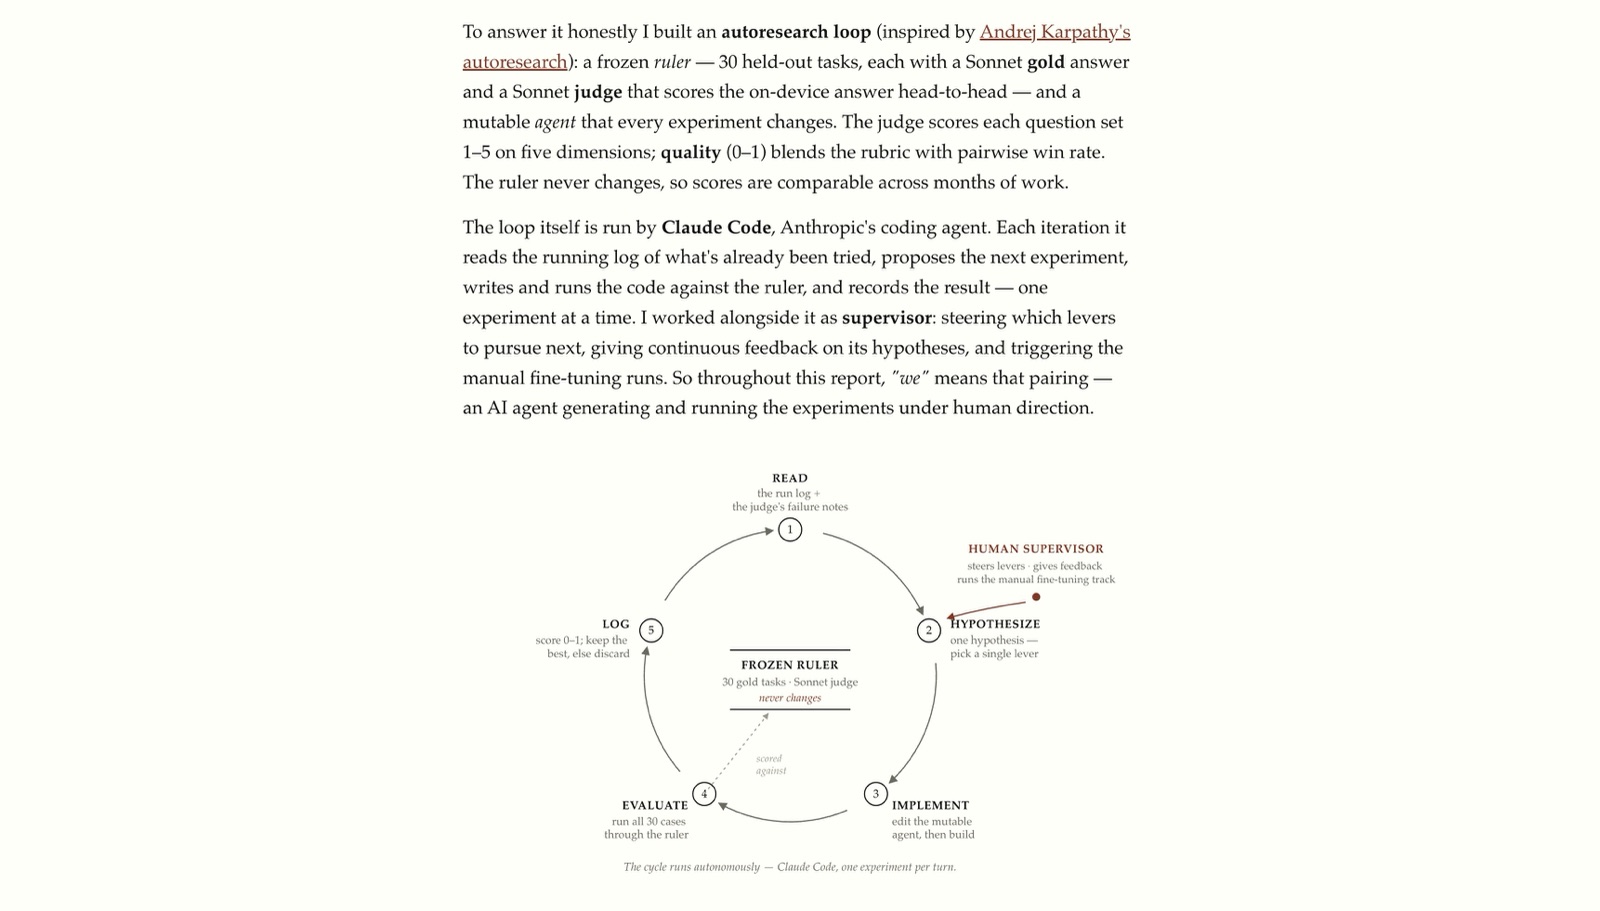
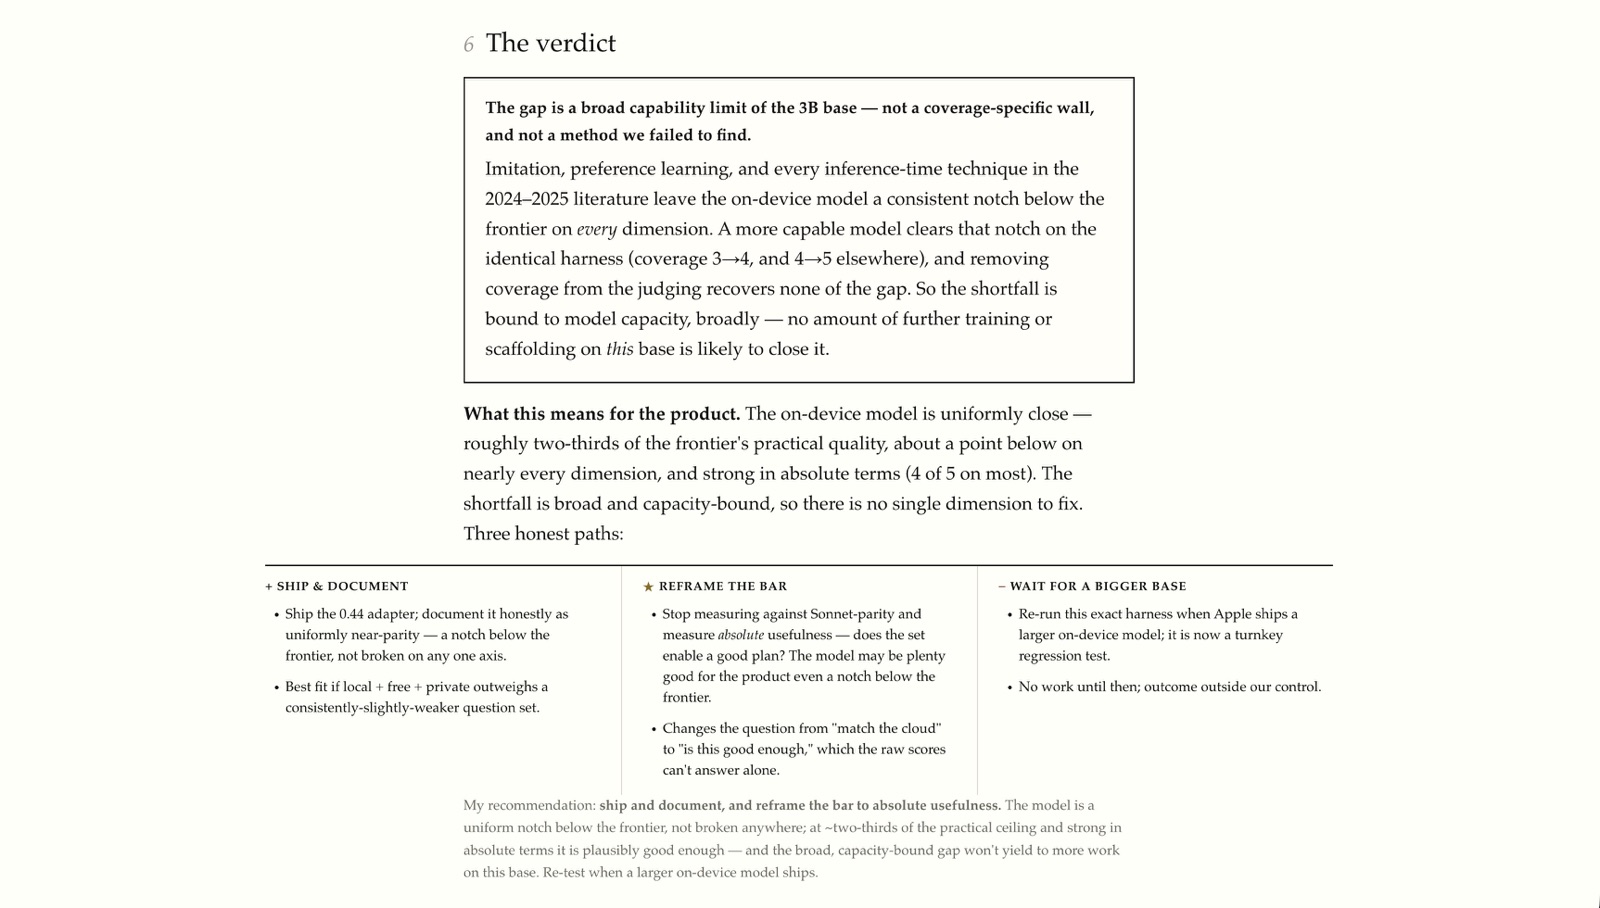
Can a phone-sized model learn to ask the right questions? Can they? Do they? Let's find out!

Full report here: t.co/BhyEkws5AZ t.co/SJUmjKNofM

Image from the post
Image from the post
Image from the post
Image from the post

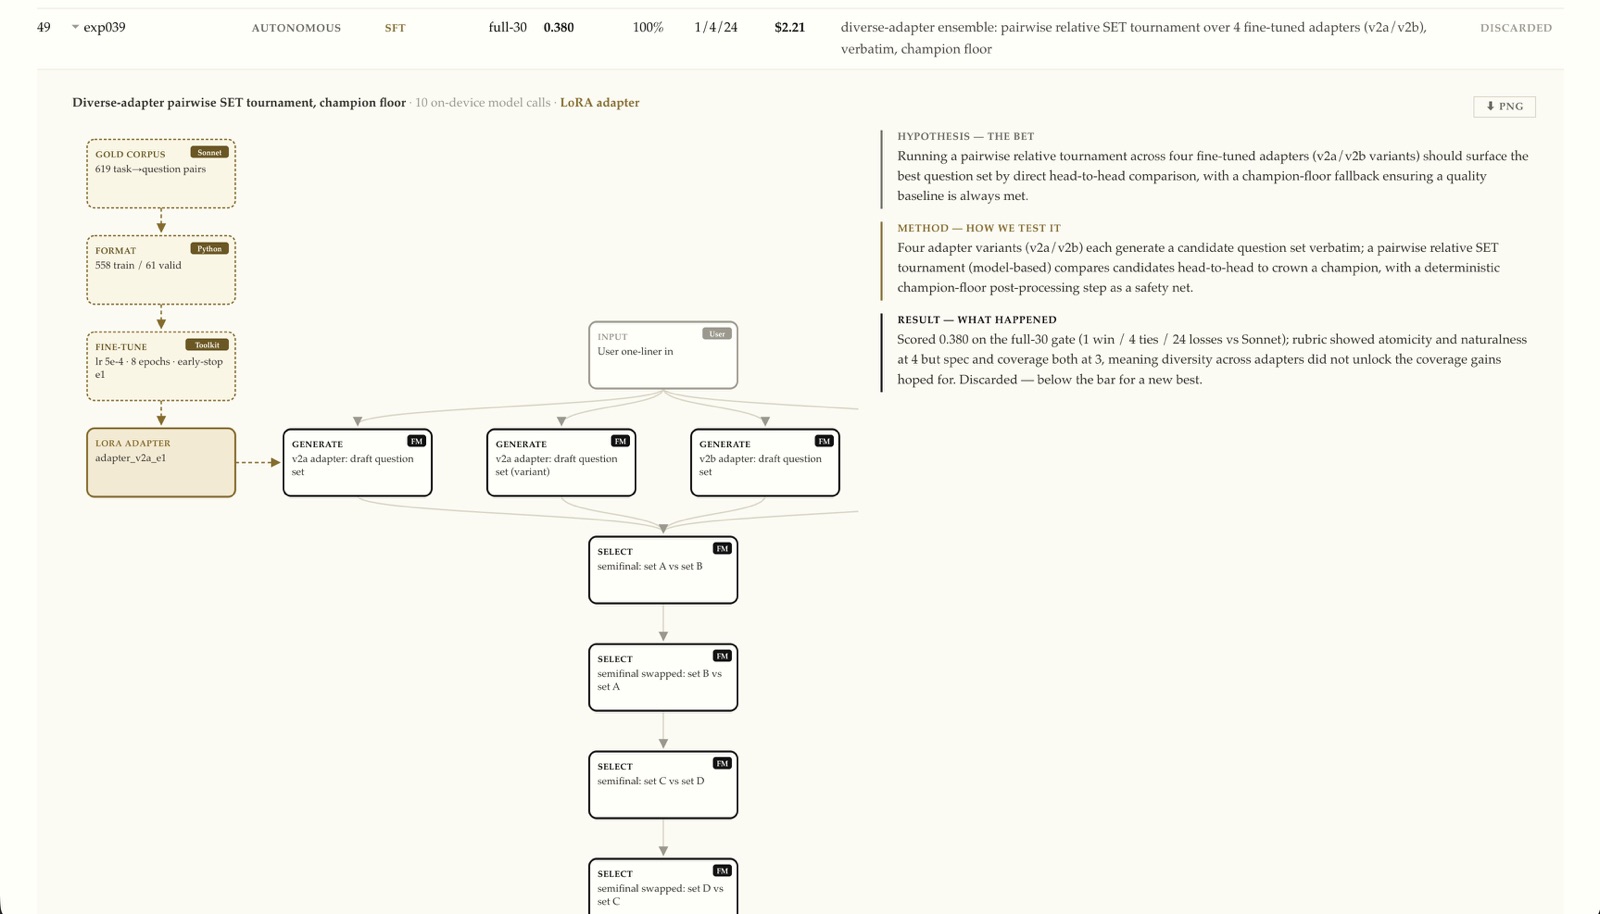
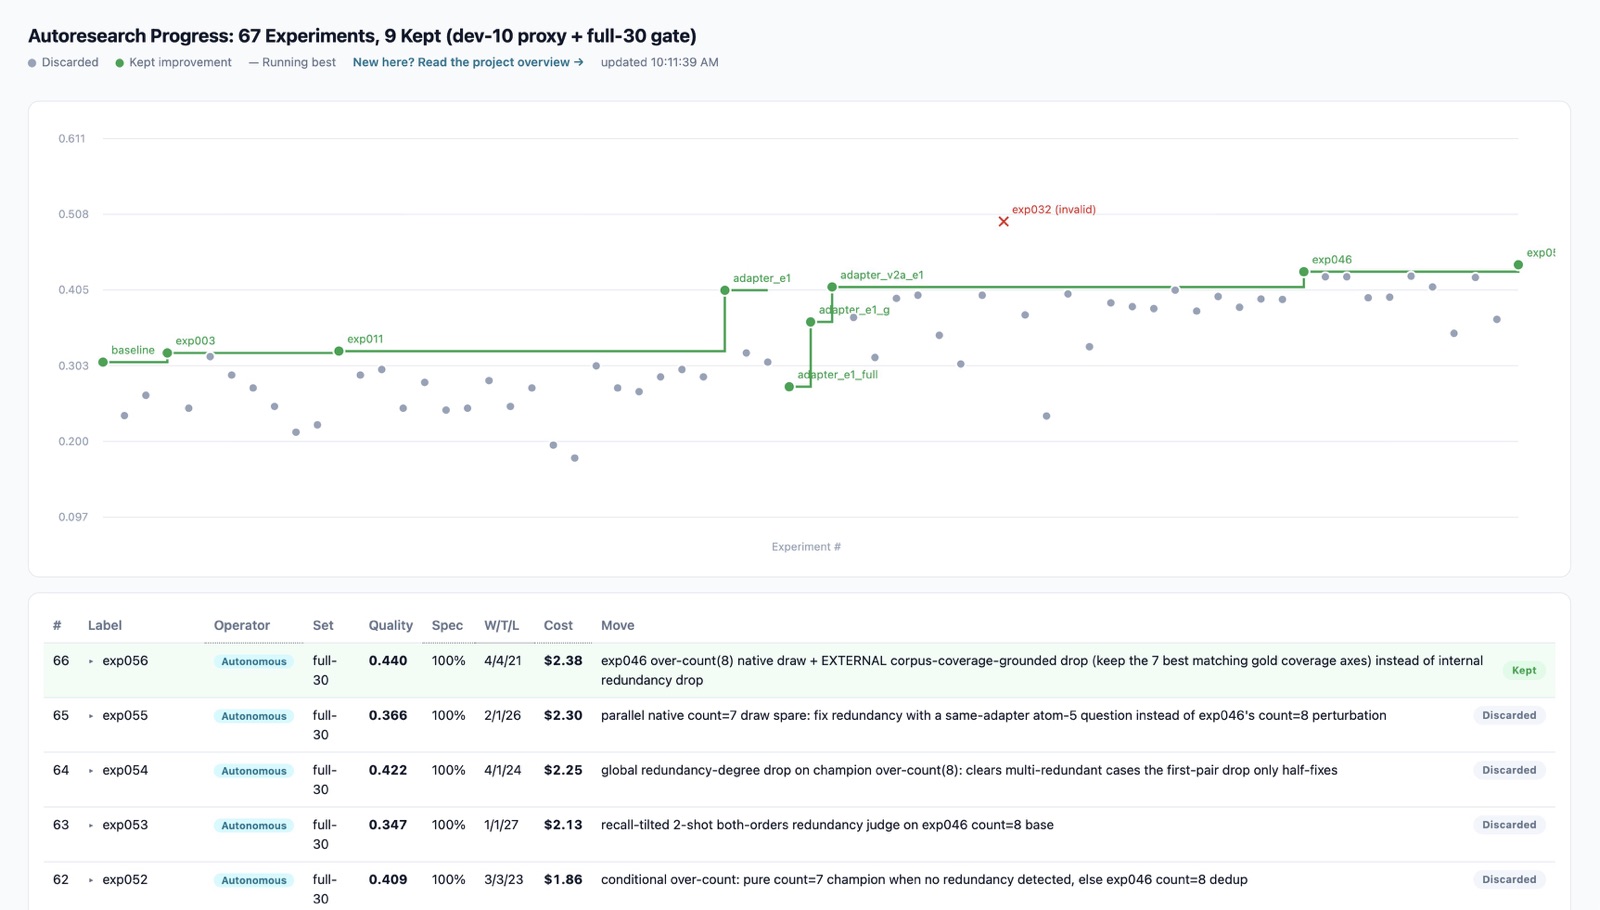
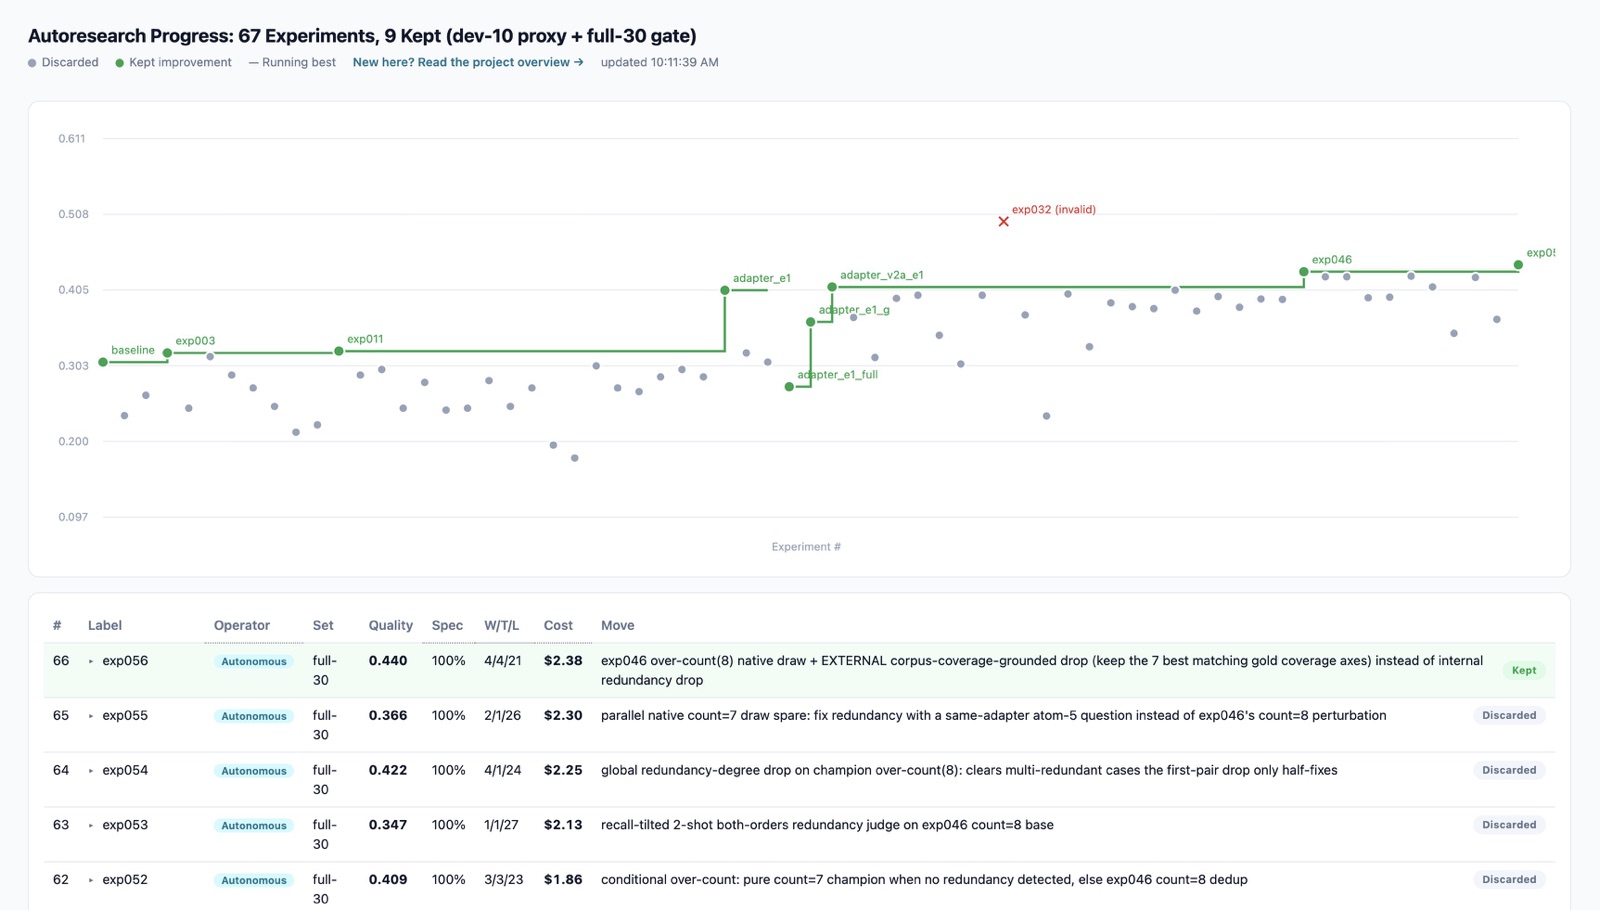
PPS: And here's the full listing for each experiment, including the hypothesis, method, architecture and individual evals like this one: alexisrondeau.me/tada/research/… (Click on a table-row to expand)

Image from the post
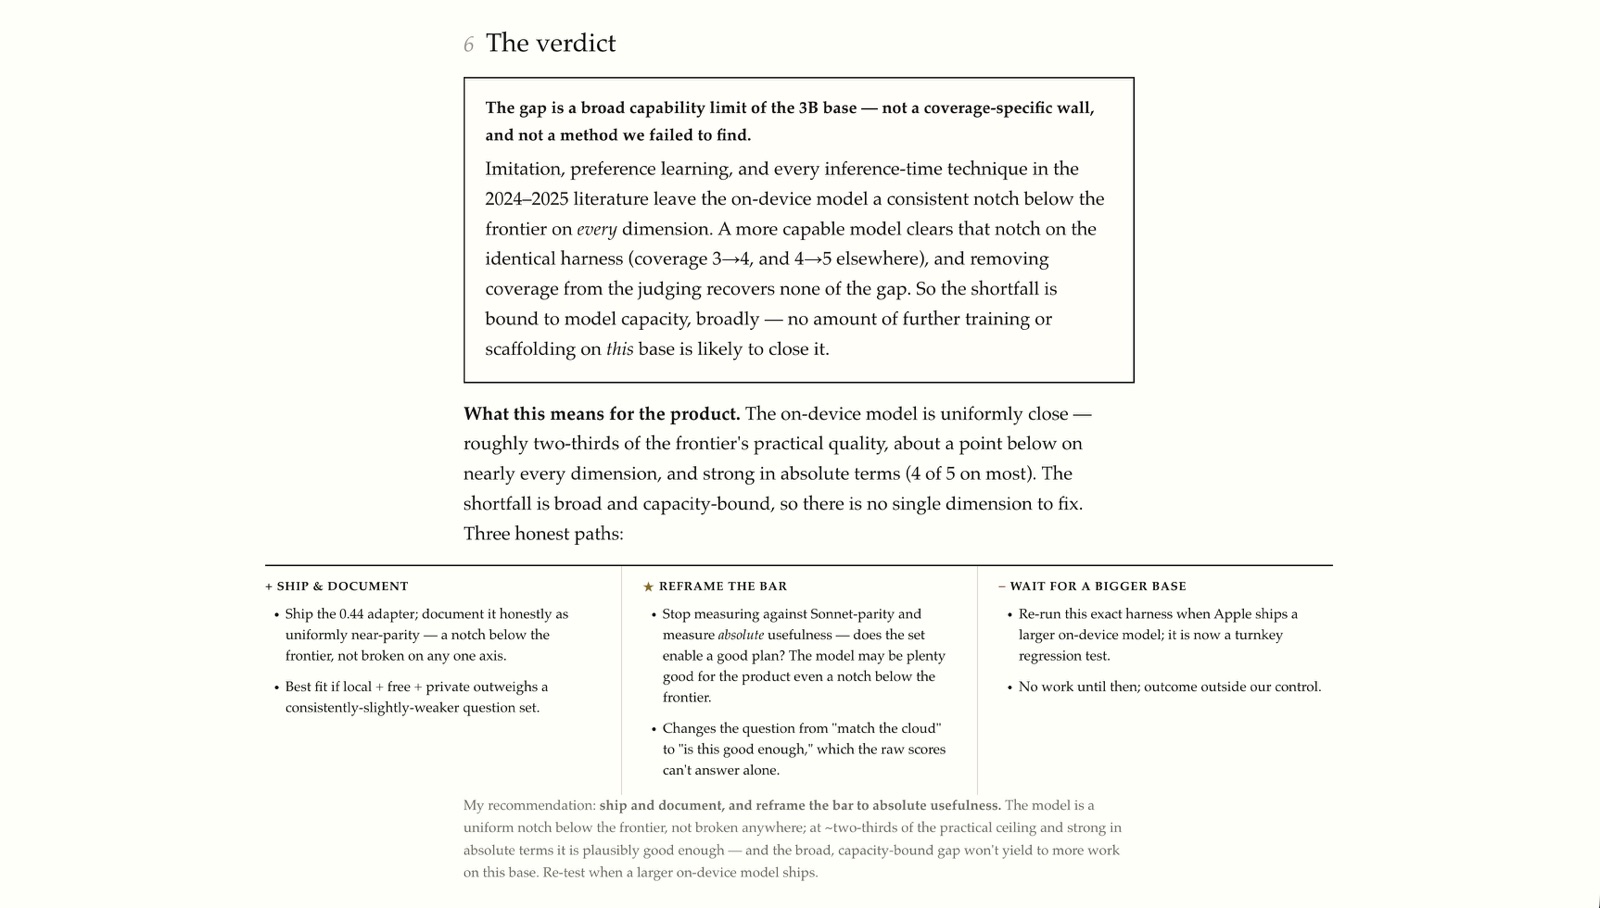
alexisrondeau.me"Which city in Paris are you staying in?" - A post-training study on small-model specialization with an autoresearch loopAcross 77 experiments — every lever from prompting and retrieval to fine-tuning and 2025's rubric-grounded RL — an on-device 3B model landed within about one rubric point of a frontier cloud model on every quality dimension: close, but consistently a notch below. None of the post-training playbook closed the last notch, and the controlled tests show why — the gap is a broad capability limit, not a…↗ alexisrondeau.me
88 views
In reply to @SpringStreetNYC · Jun 1, 2026

Can a phone-sized model learn to ask the right questions? Can they? Do they? Let's find out!

Full report here: t.co/BhyEkws5AZ t.co/SJUmjKNofM

Image from the post
Image from the post
Image from the post
Image from the post

PS: For anyone interested, a more detailed project onboarding is here:

Image from the post
Image from the post
Image from the post
alexisrondeau.me"Which city in Paris are you staying in?" - A post-training study on small-model specialization with an autoresearch loopAcross 77 experiments — every lever from prompting and retrieval to fine-tuning and 2025's rubric-grounded RL — an on-device 3B model landed within about one rubric point of a frontier cloud model on every quality dimension: close, but consistently a notch below. None of the post-training playbook closed the last notch, and the controlled tests show why — the gap is a broad capability limit, not a…↗ alexisrondeau.me
2 replies · 1 like · 91 views

Can a phone-sized model learn to ask the right questions? Can they? Do they? Let's find out!

Full report here:

Image from the post
Image from the post
Image from the post
Image from the post
alexisrondeau.me"Which city in Paris are you staying in?" - A post-training study on small-model specialization with an autoresearch loopAcross 77 experiments — every lever from prompting and retrieval to fine-tuning and 2025's rubric-grounded RL — an on-device 3B model landed within about one rubric point of a frontier cloud model on every quality dimension: close, but consistently a notch below. None of the post-training playbook closed the last notch, and the controlled tests show why — the gap is a broad capability limit, not a…↗ alexisrondeau.me
12 views
In reply to @SpringStreetNYC · May 31, 2026

Alright!

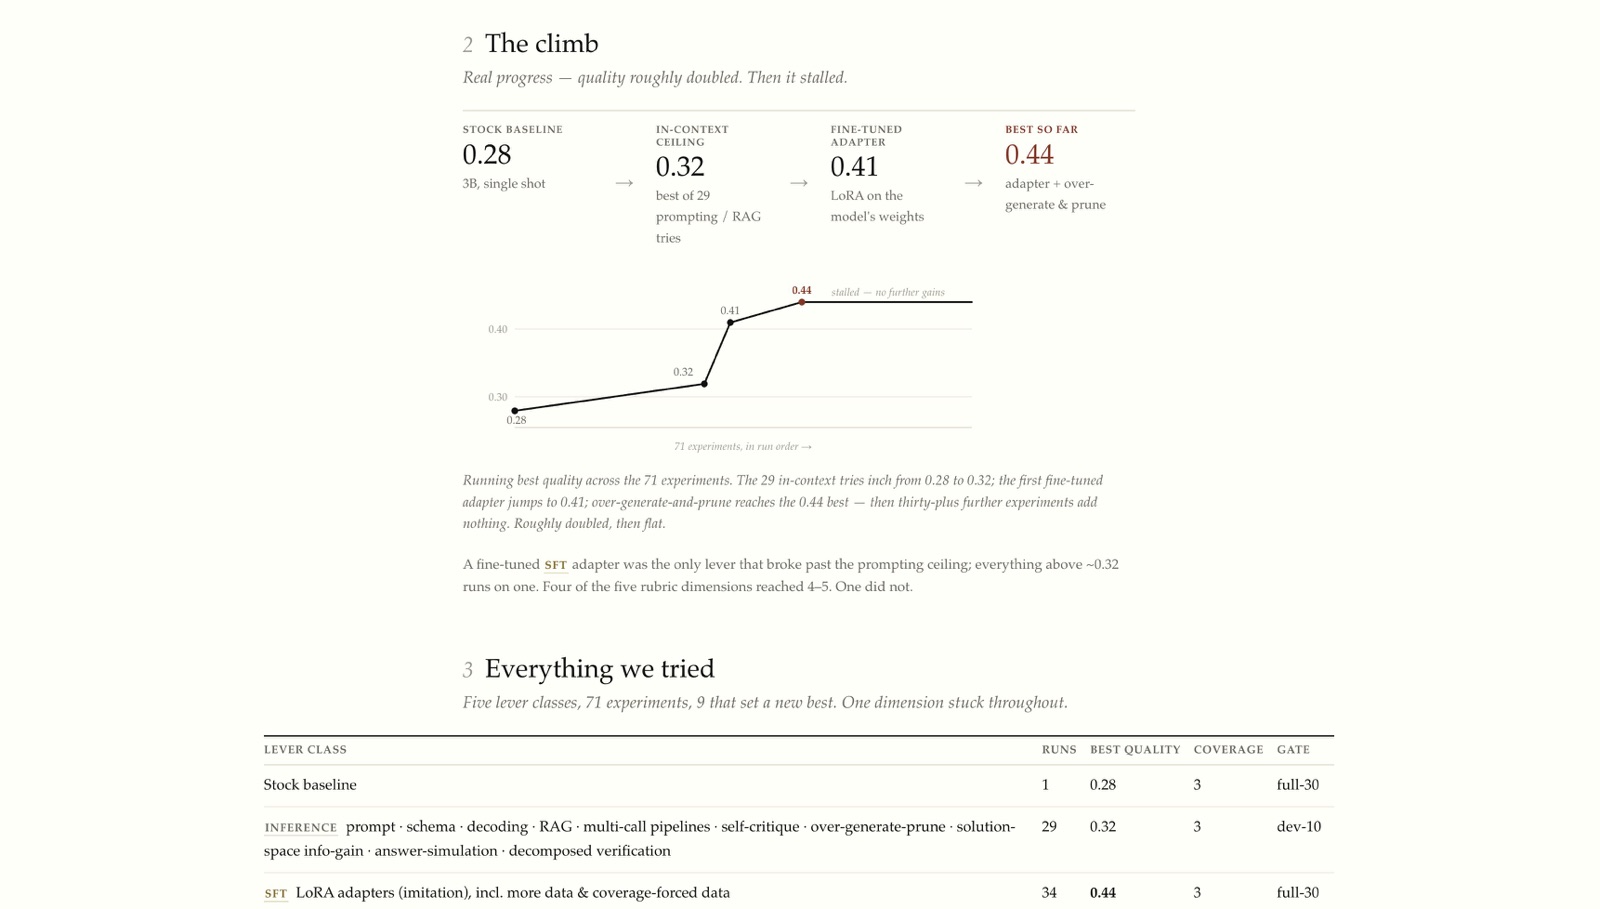
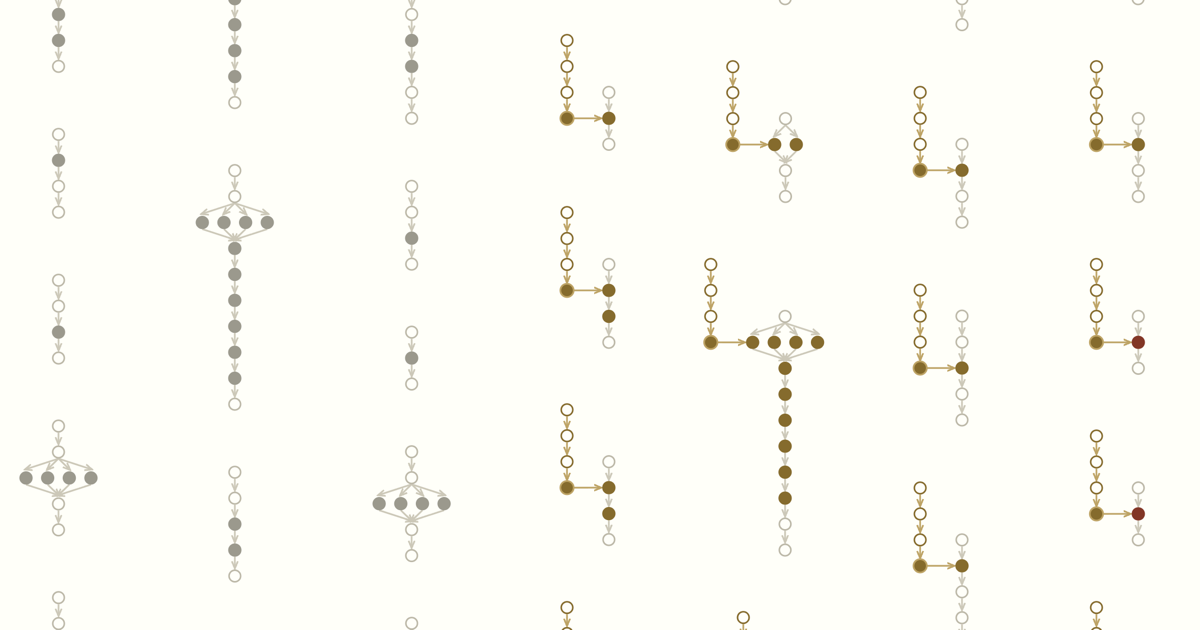
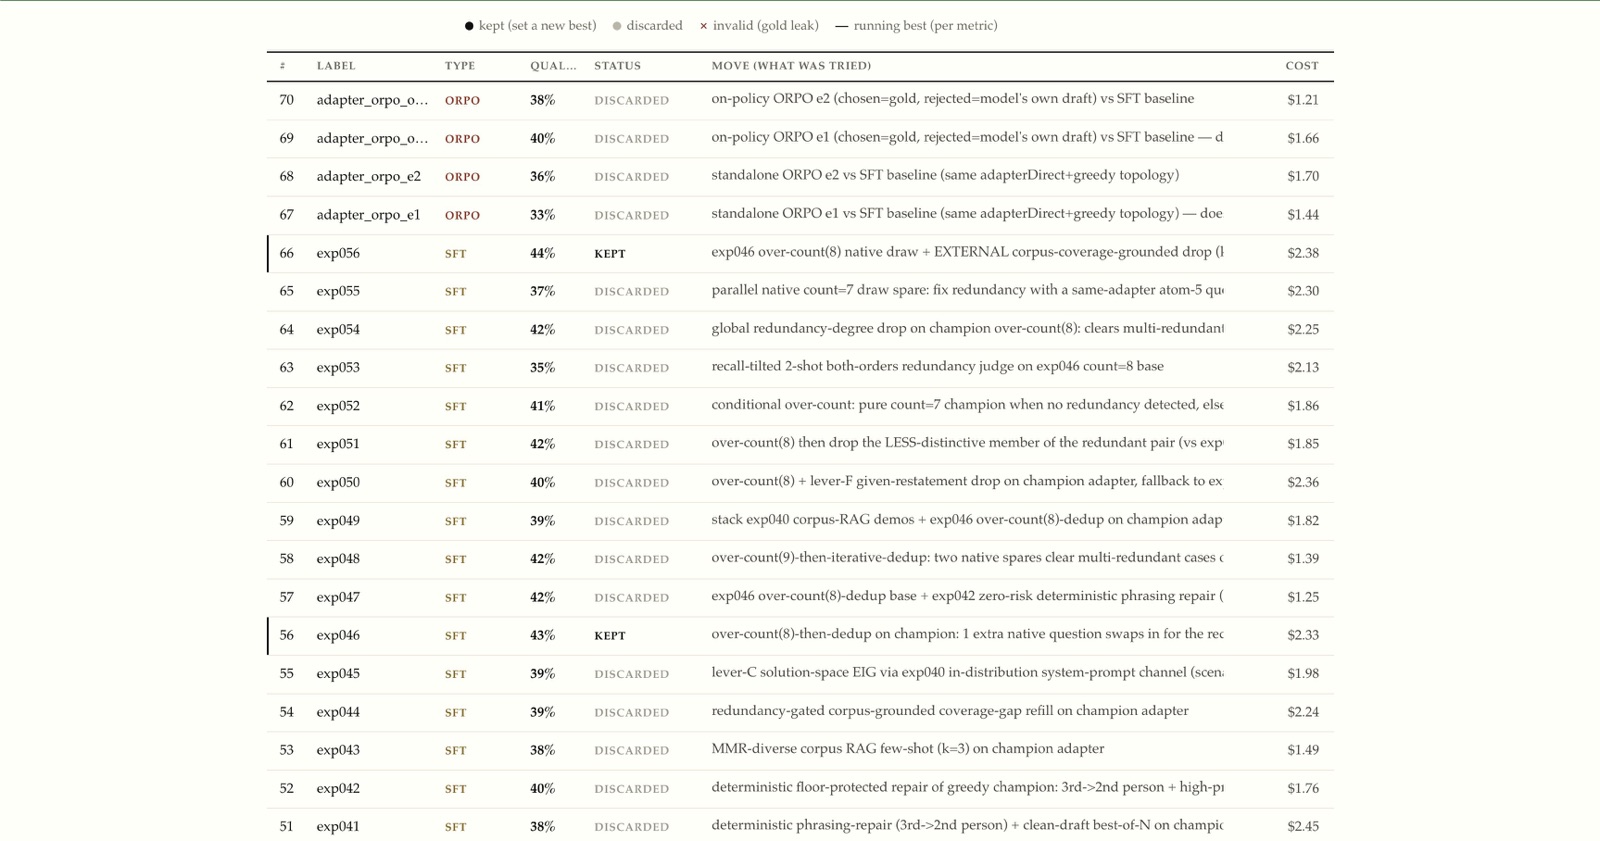
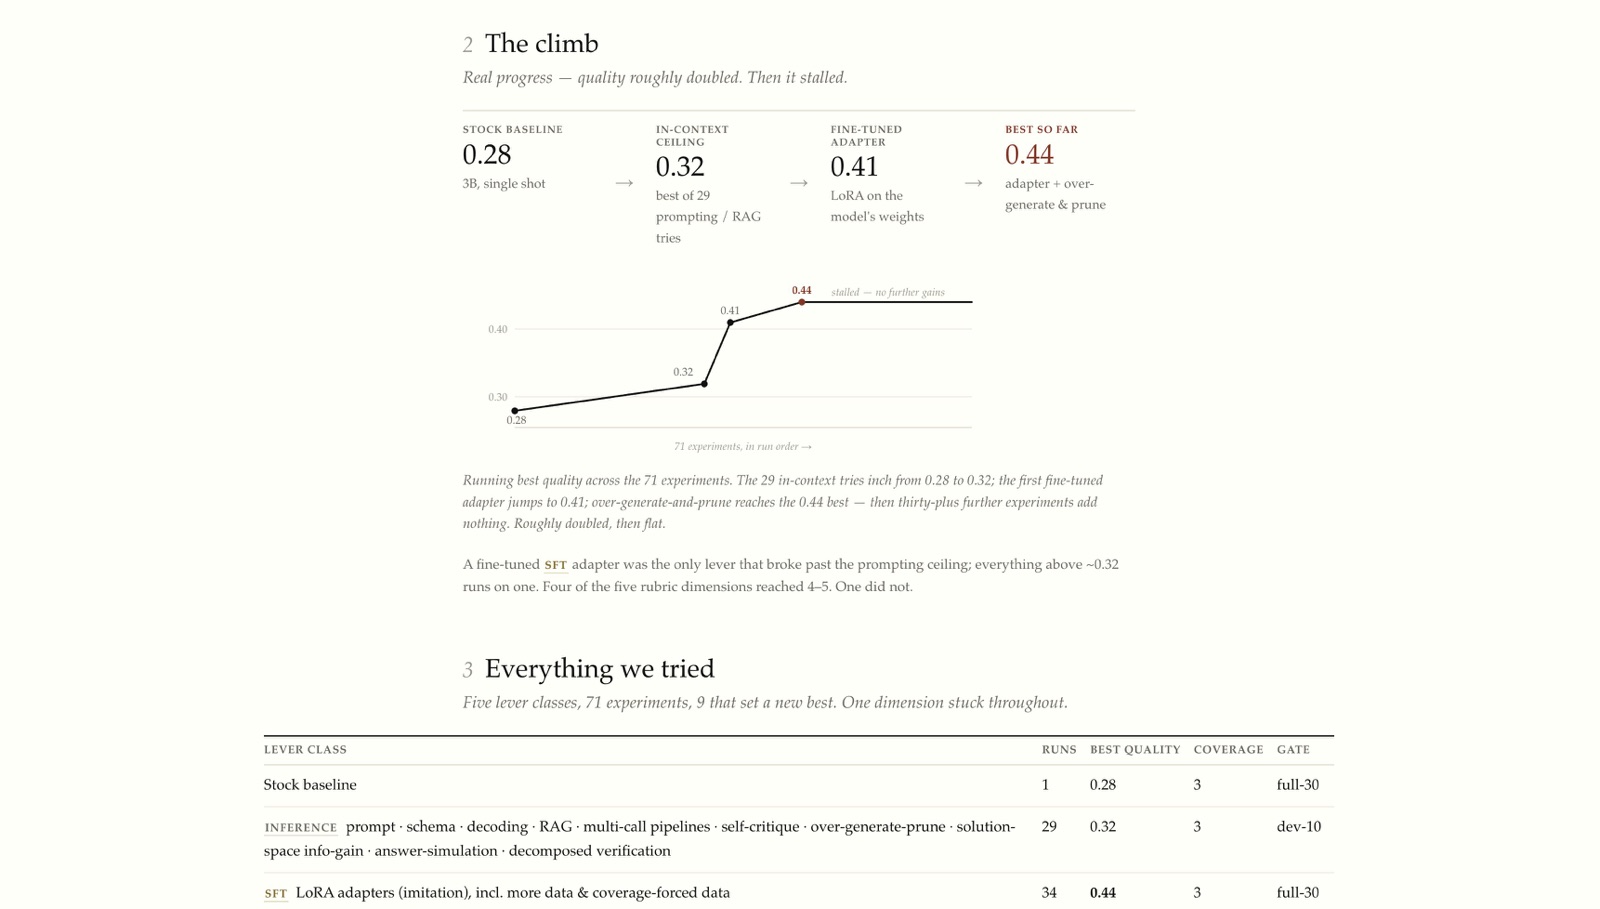
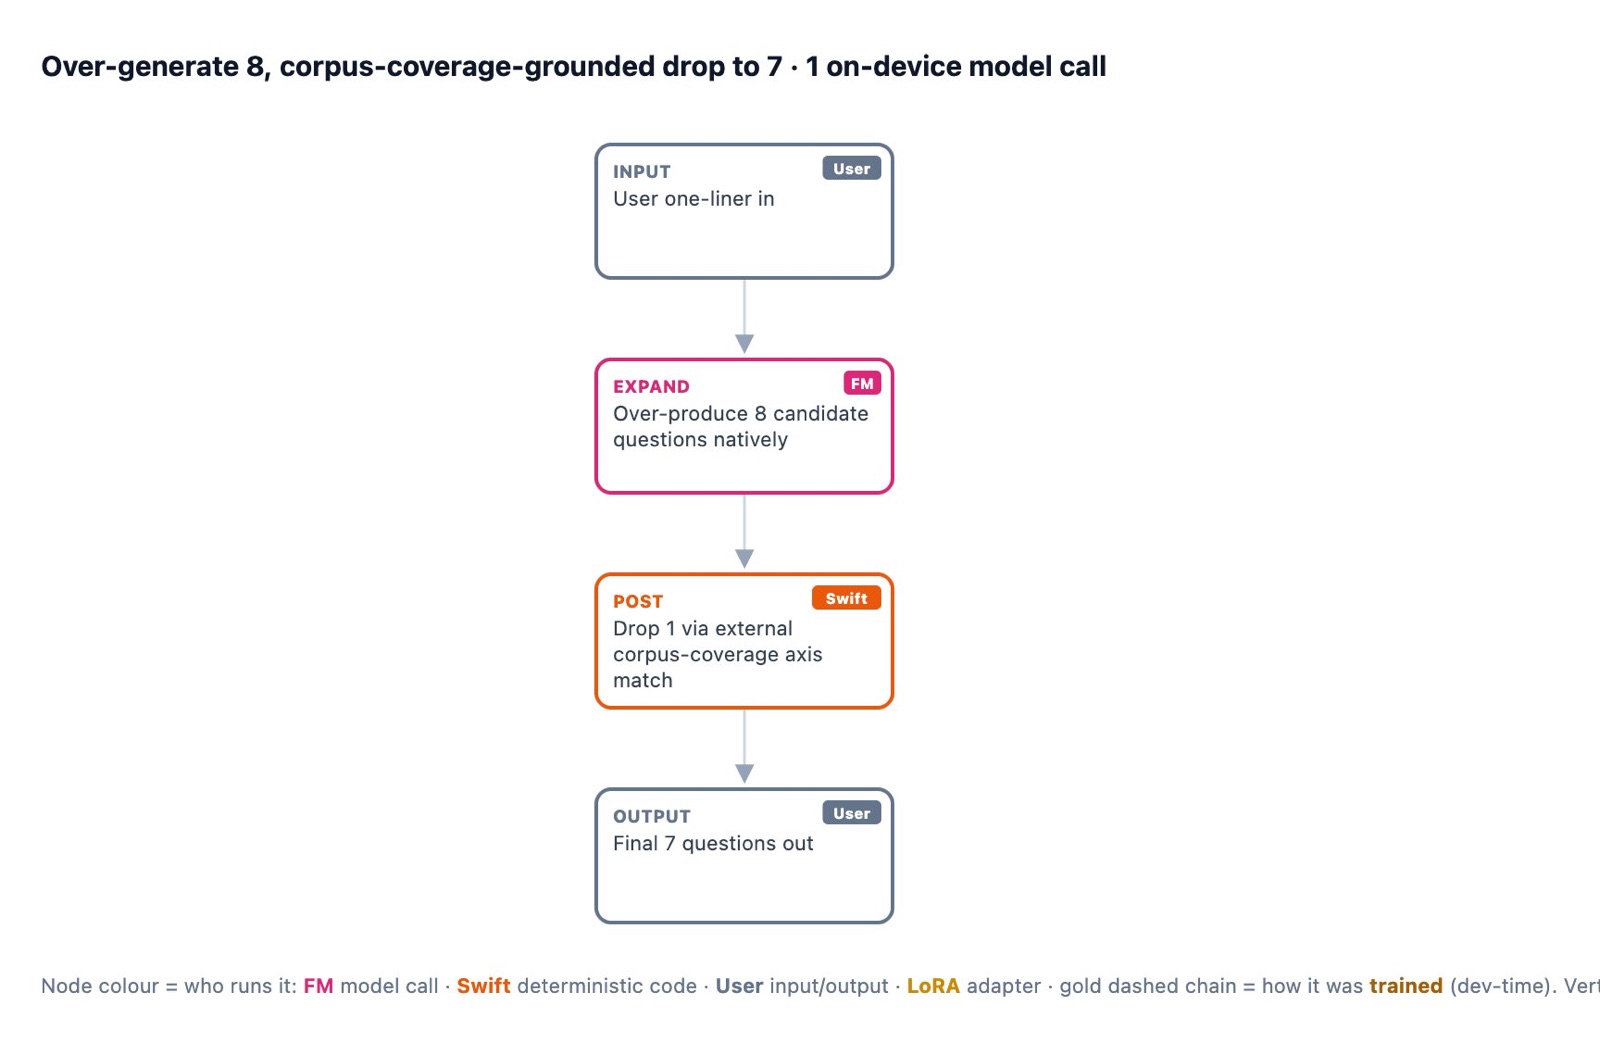
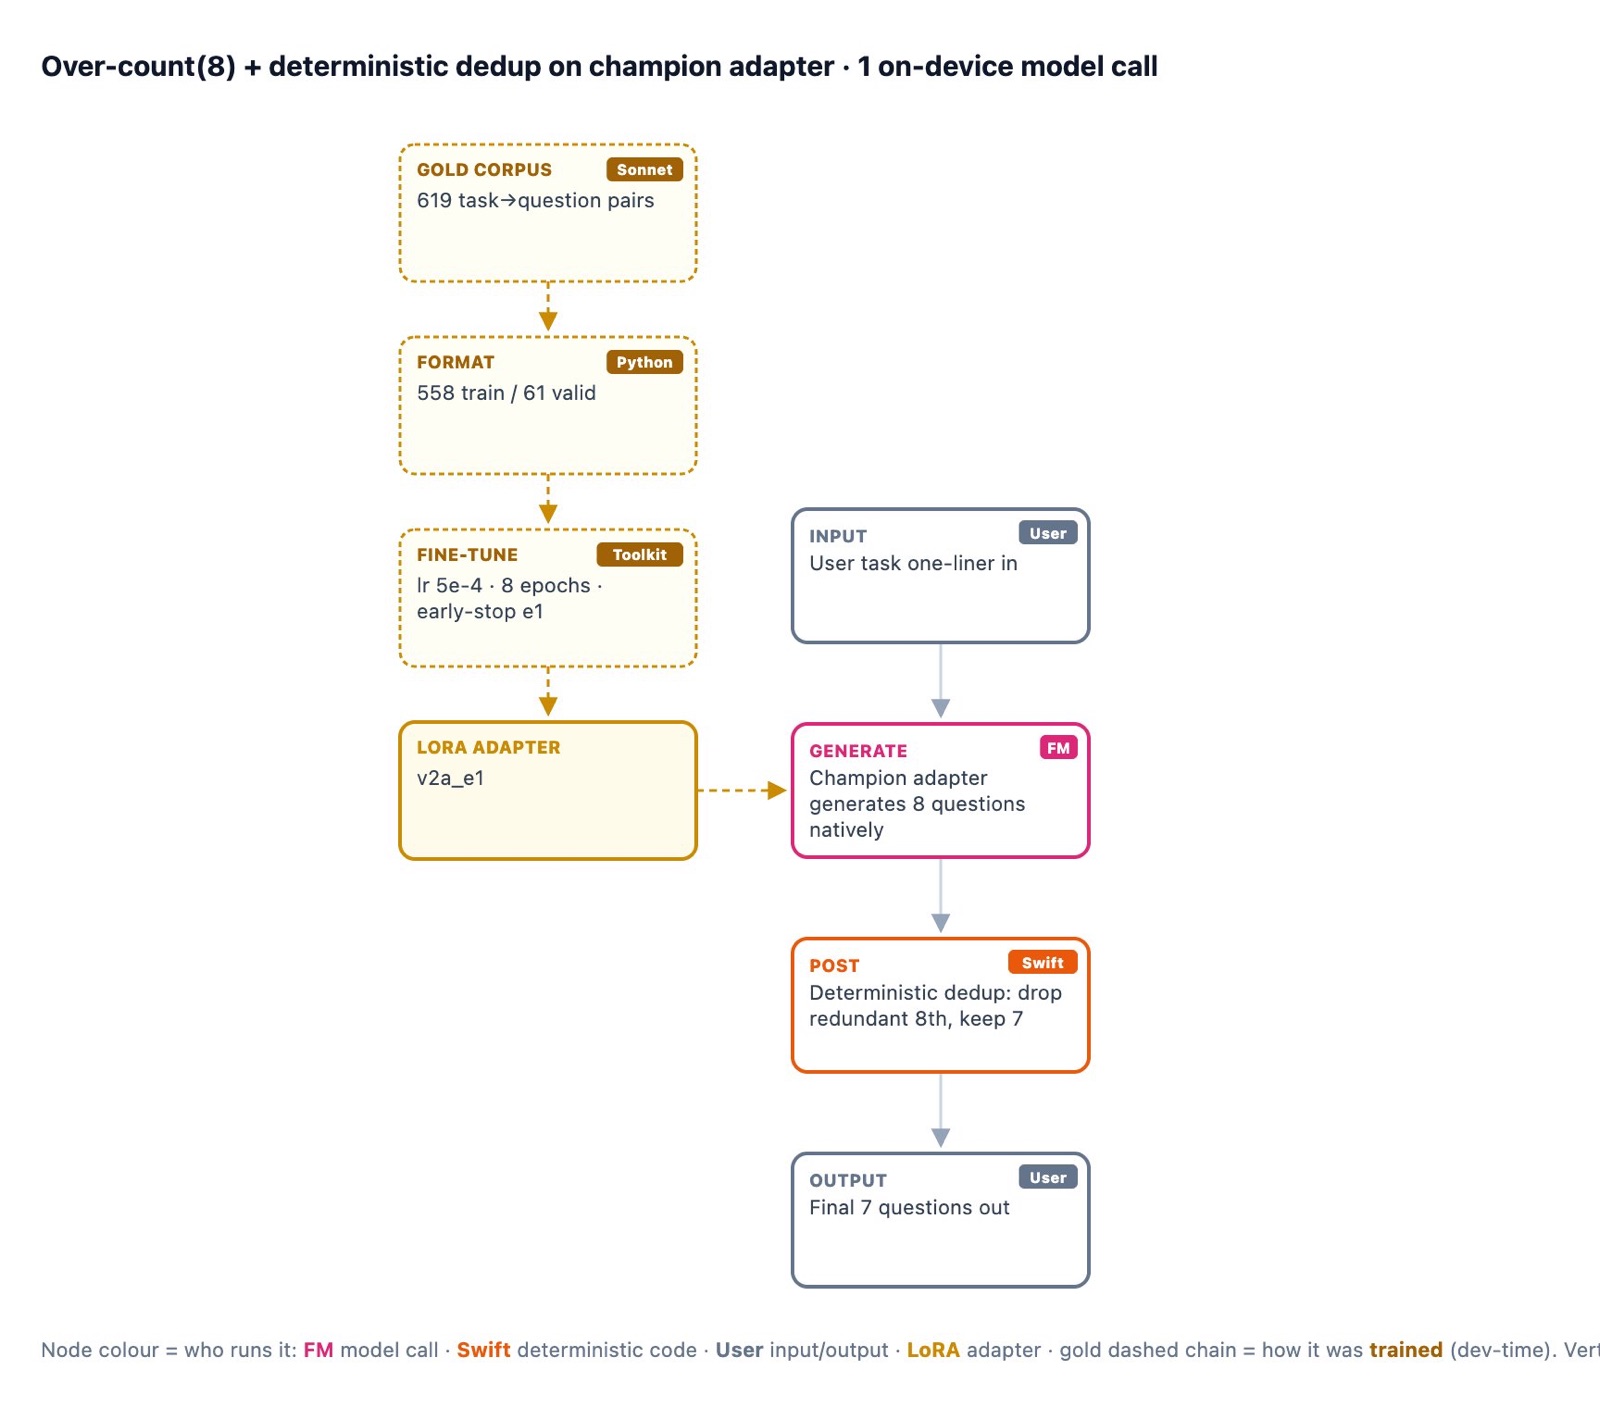
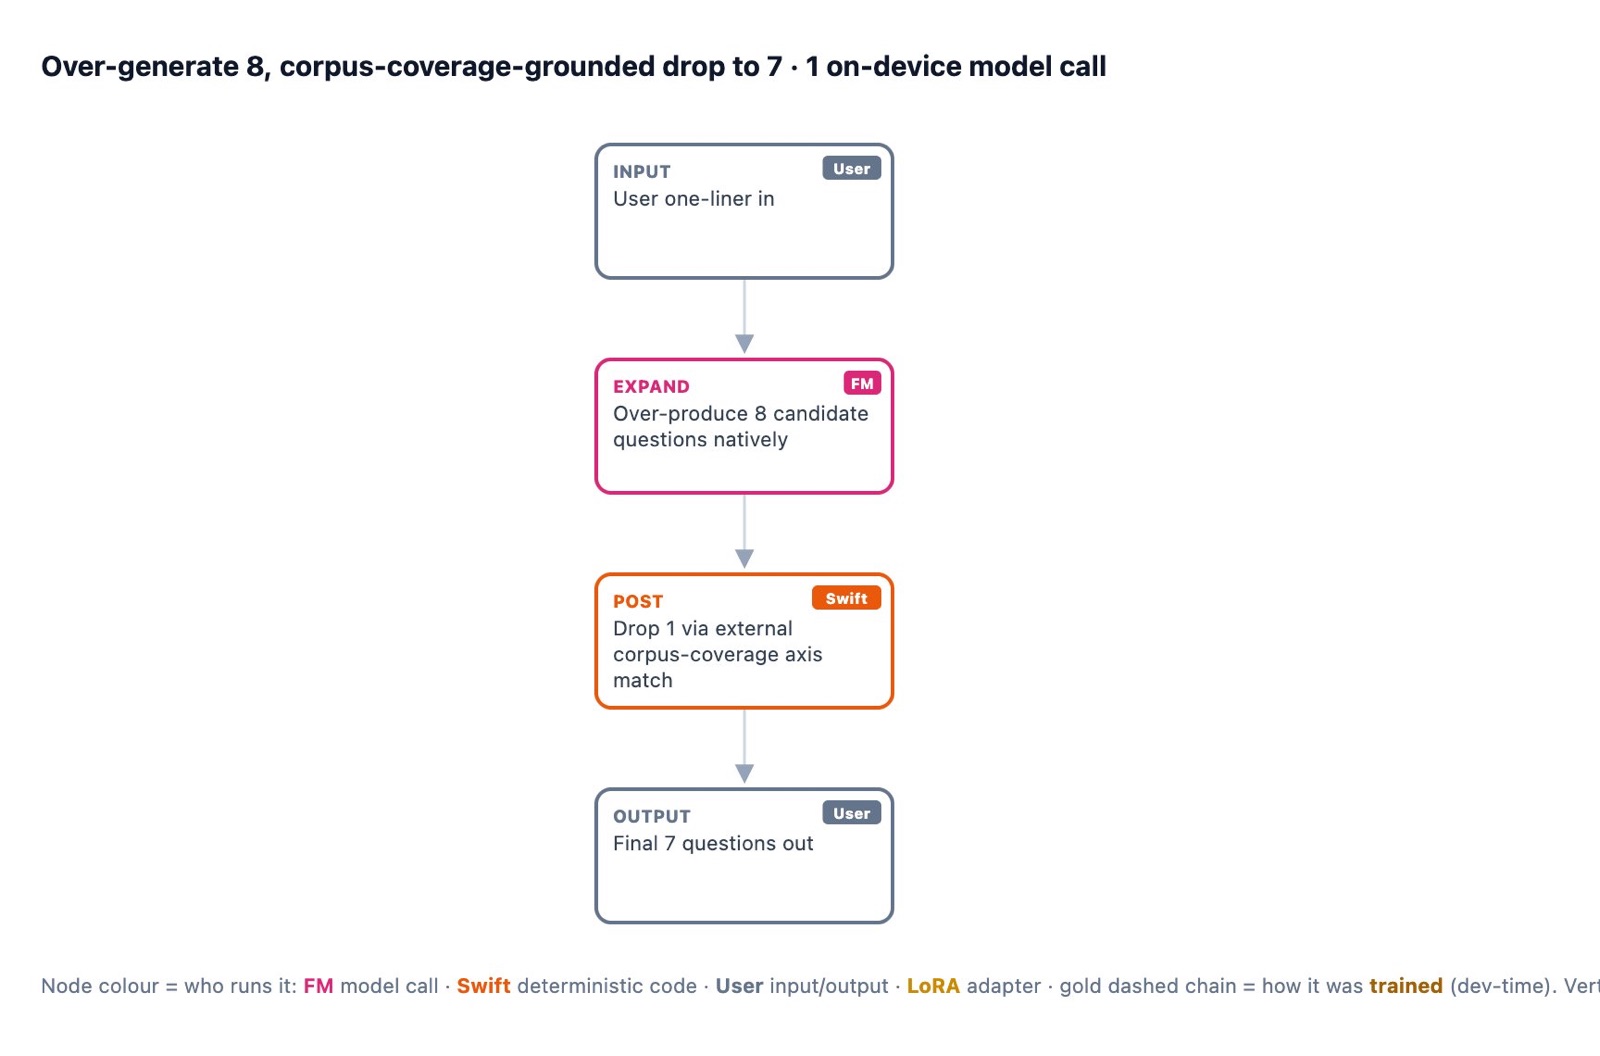
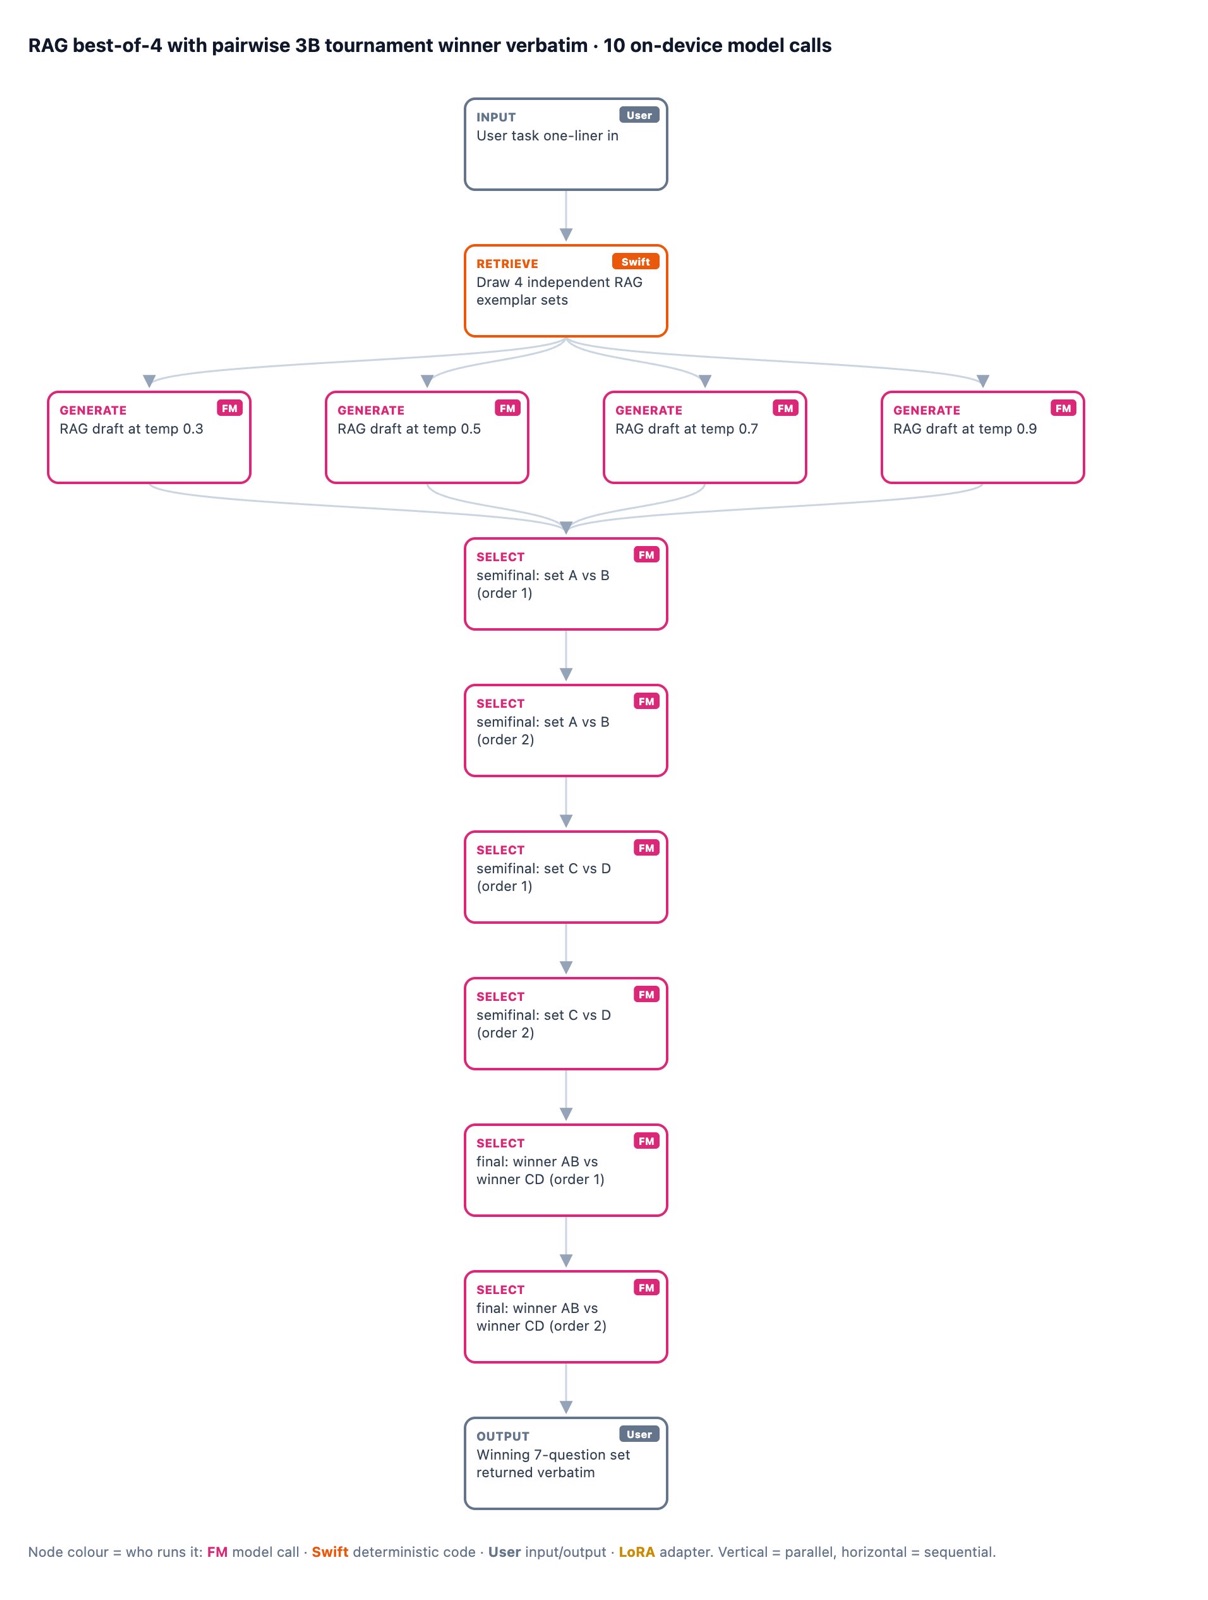
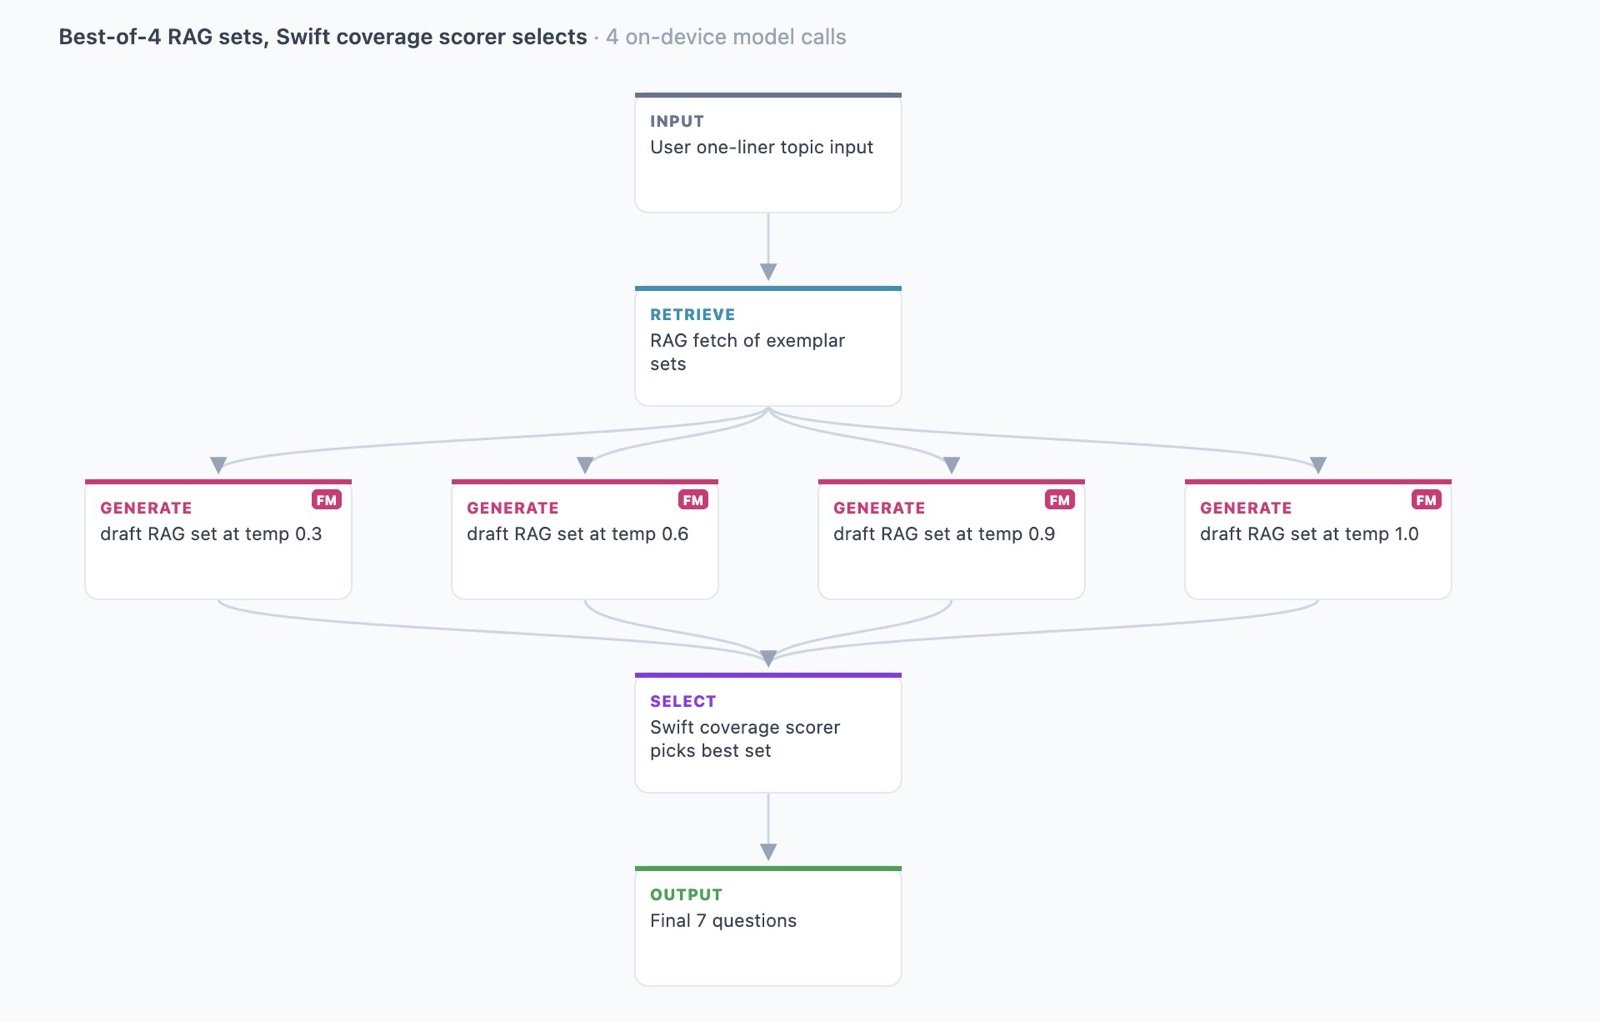
The autoresearch agent came up with an unexpected way to push quality to from 40% to 44%:

"First, generate one more option than we actually need, then throw away the one we can most afford to lose, keeping the rest."

Suprises:
1. It's much simpler than the LoRA adapter route
2. It produced four responses that were significantly better than their eval targets
3. I hit an Anthropic API usage limit for the first time (Yay!)

And, man, I have to say: As an experimenter autoresearch is really, really fun to work with, guide and learn from. I wish more people would have this experience in their domains.

Image from the post
Image from the post

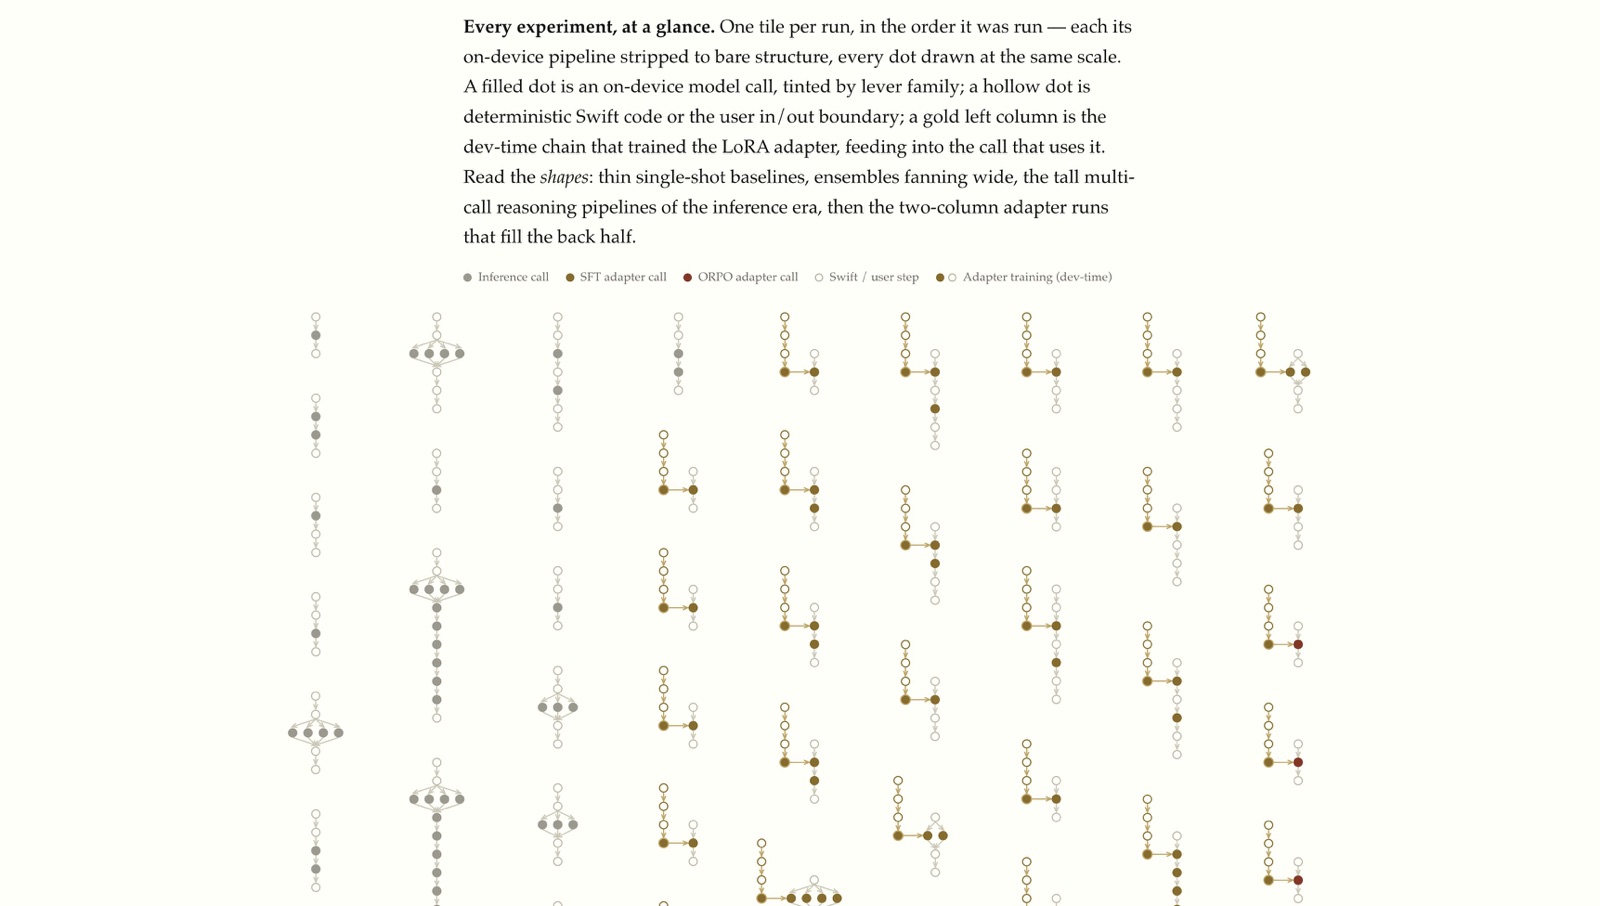
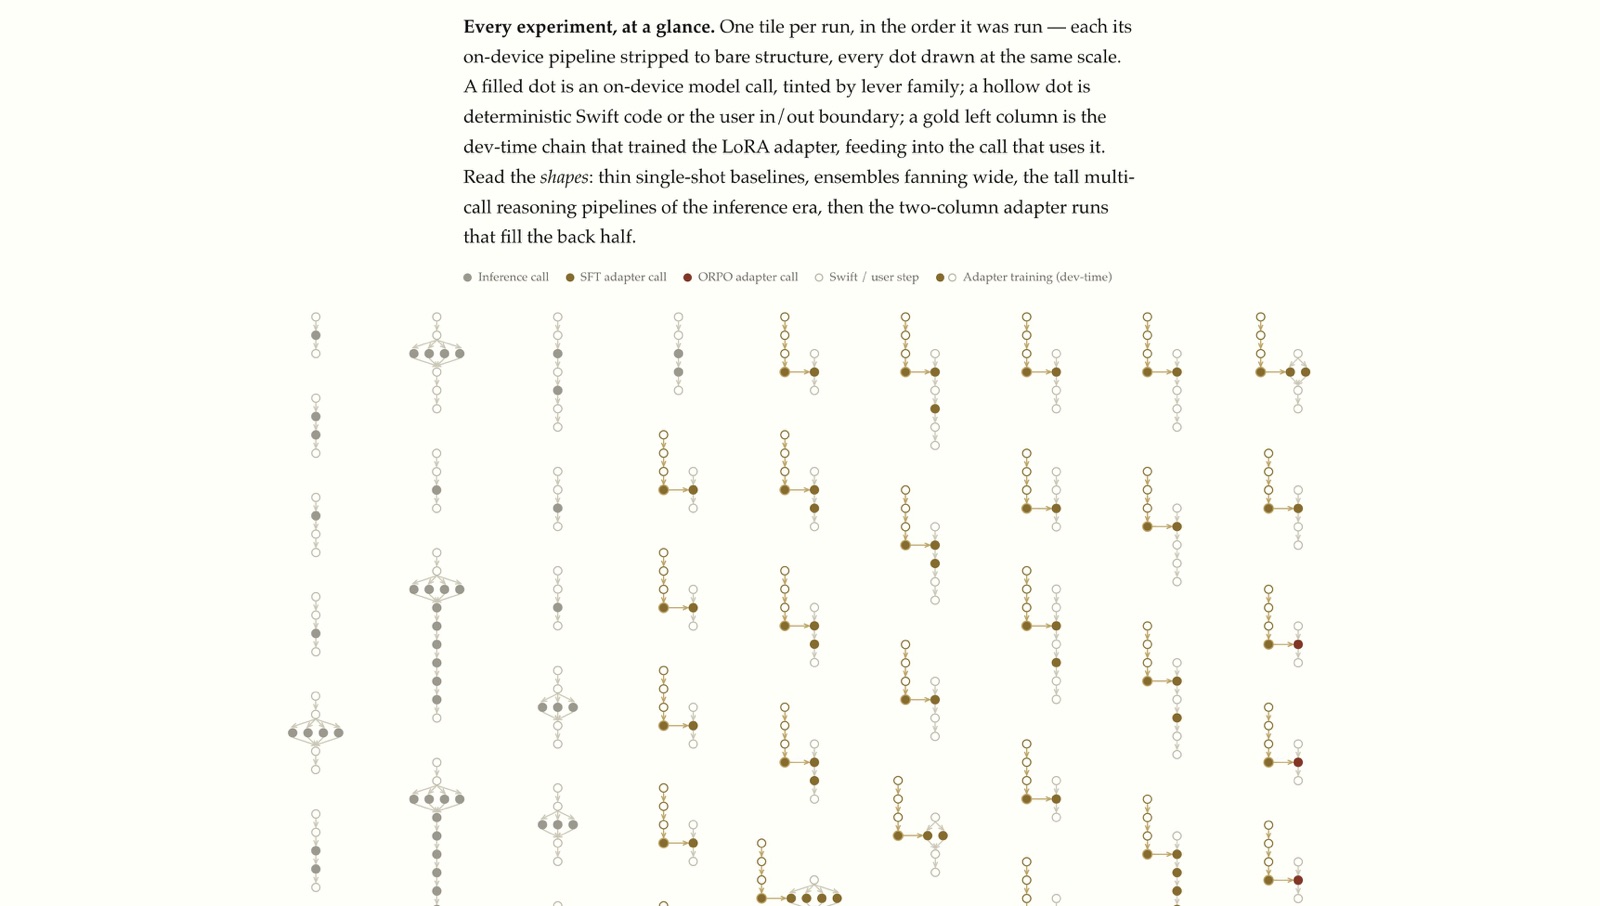
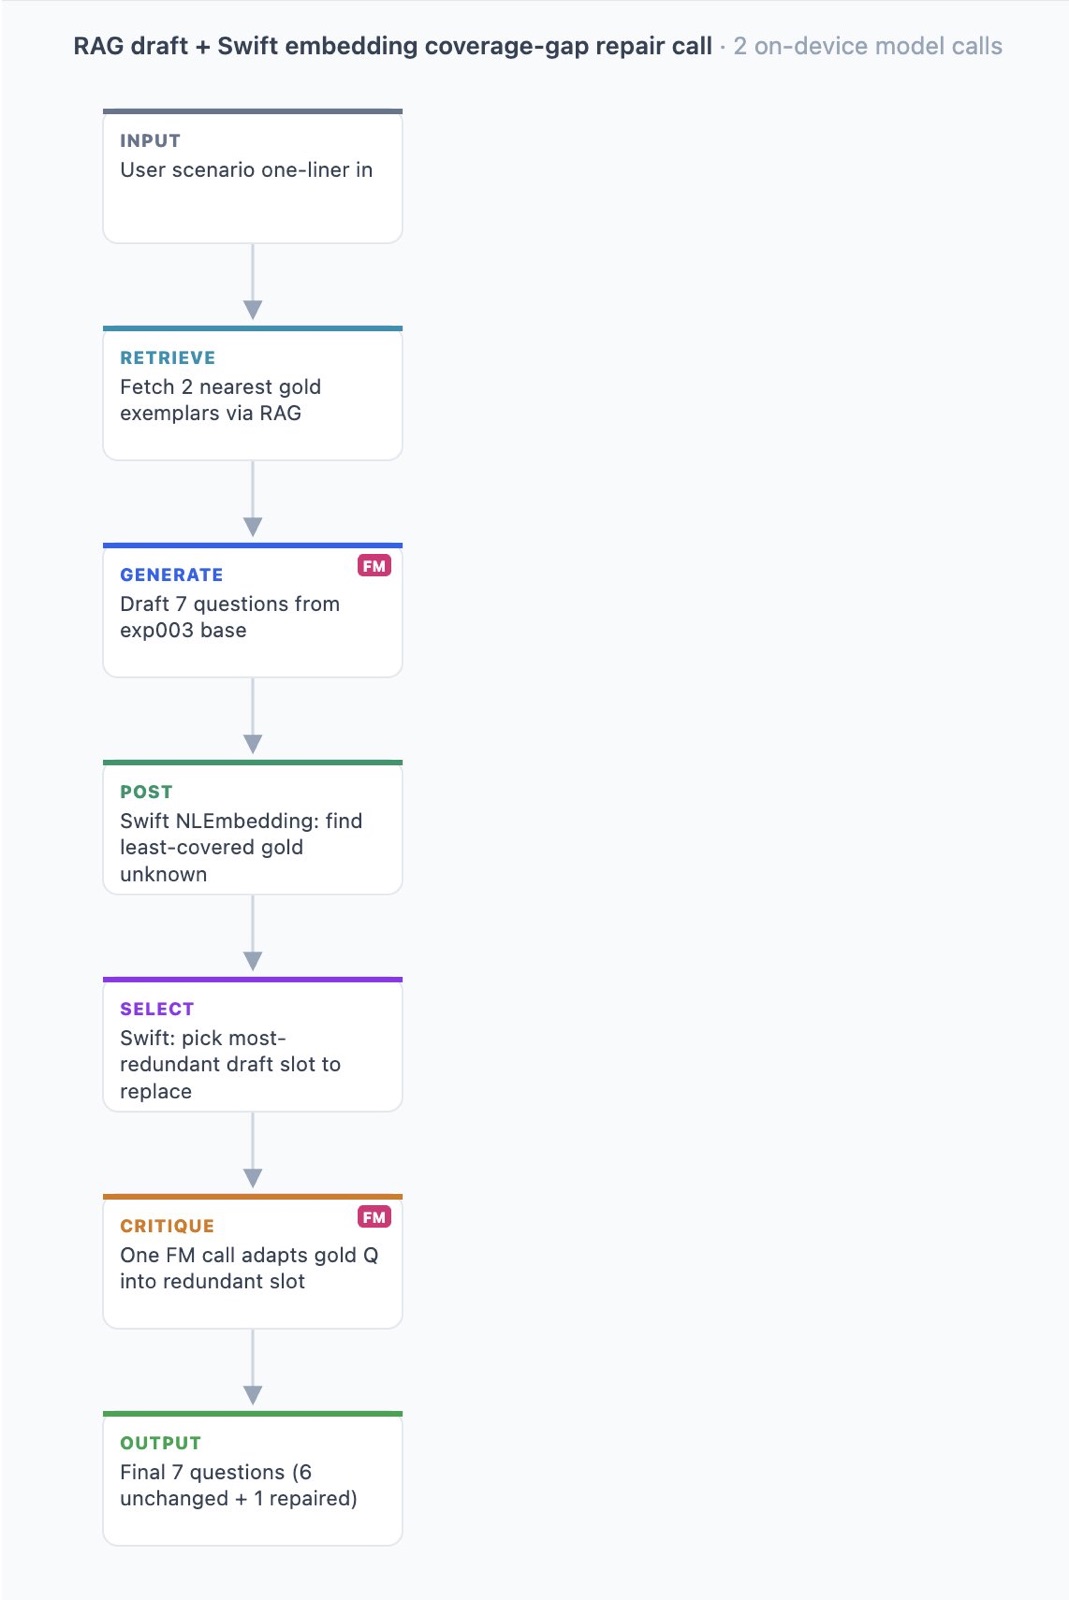
Ah, scratch the "Doesn't use LoRA" surprise. Experiment 056 is built ON-TOP of 046. I forgot to make the diagram-generator aware of this kind of experiment heritage.

Image from the post
1 reply · 1 like · 49 views
In reply to @SpringStreetNYC · May 29, 2026

I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.

Alright!

The autoresearch agent came up with an unexpected way to push quality to from 40% to 44%:

"First, generate one more option than we actually need, then throw away the one we can most afford to lose, keeping the rest."

Suprises:
1. It's much simpler than the LoRA adapter route
2. It produced four responses that were significantly better than their eval targets
3. I hit an Anthropic API usage limit for the first time (Yay!)

And, man, I have to say: As an experimenter autoresearch is really, really fun to work with, guide and learn from. I wish more people would have this experience in their domains.

Image from the post
Image from the post
34 views
In reply to @SpringStreetNYC · May 29, 2026

I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.

But basically I'm using frontier models to train a local ("homestead"?) model as to impart some of that good brain stuff but minus the overwhelm. Like a teacher, hopefully.

42 views
In reply to @SpringStreetNYC · May 29, 2026

I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.

LOL, yeah, this one also not a keeper.

An old friend of mine shared this nugget of wisdom from art school with me:

"Good from far, but far from good."

Image from the post
36 views
In reply to @SpringStreetNYC · May 29, 2026

I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.

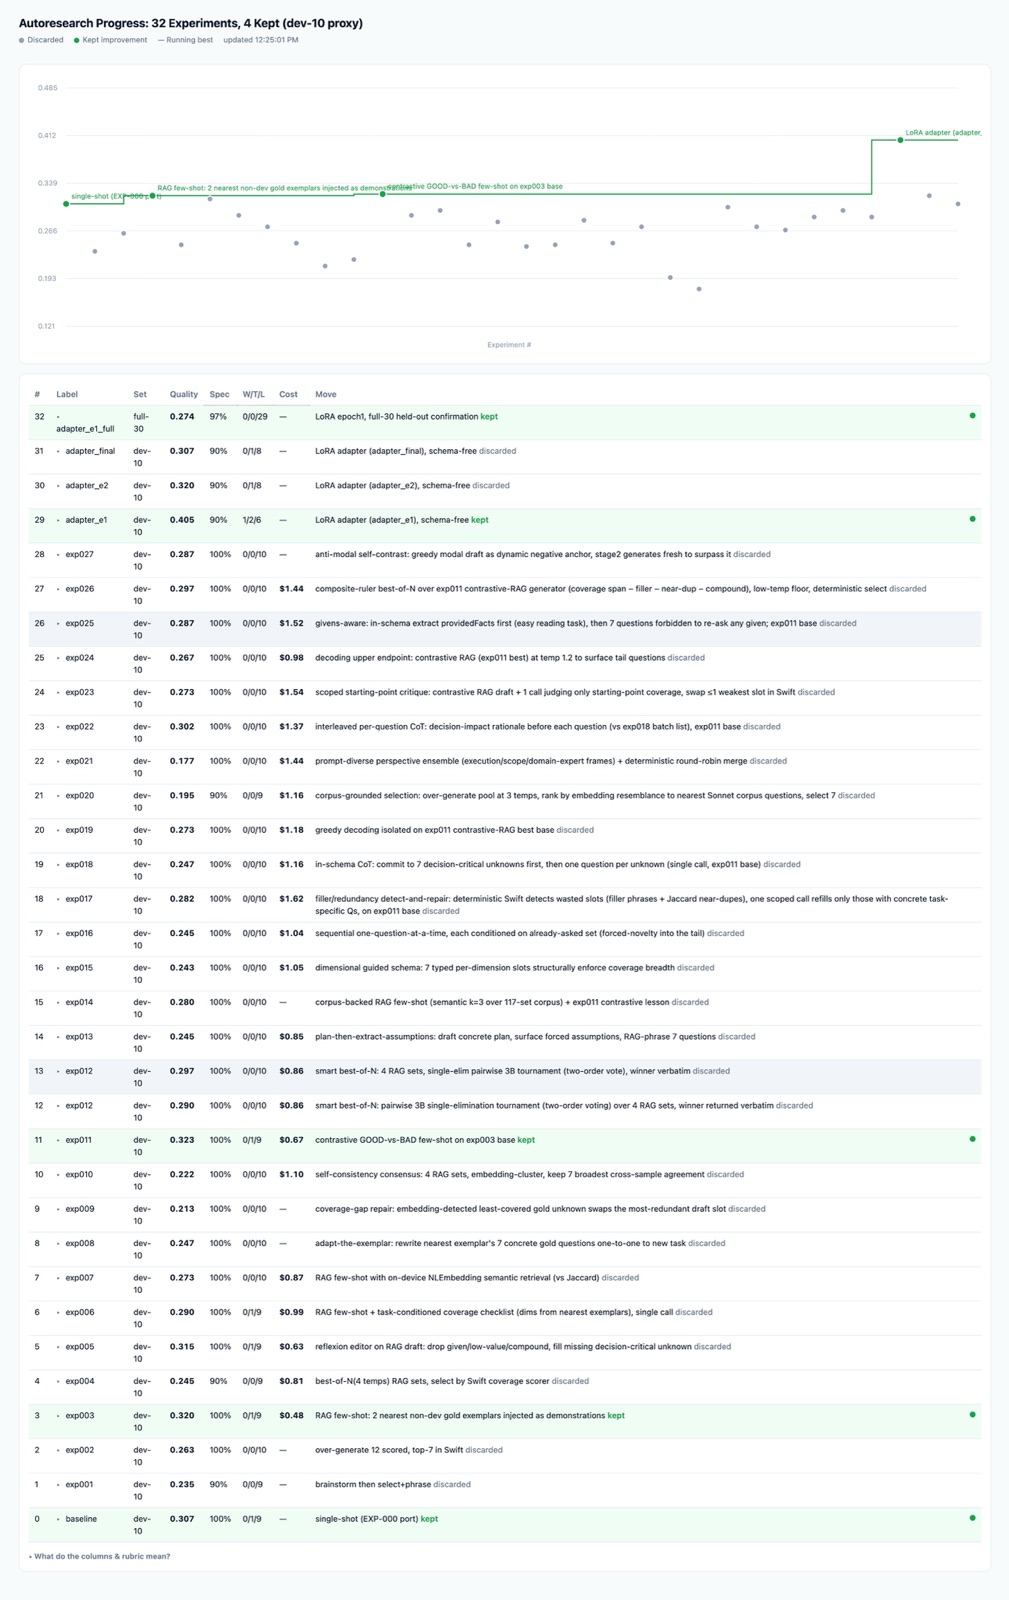
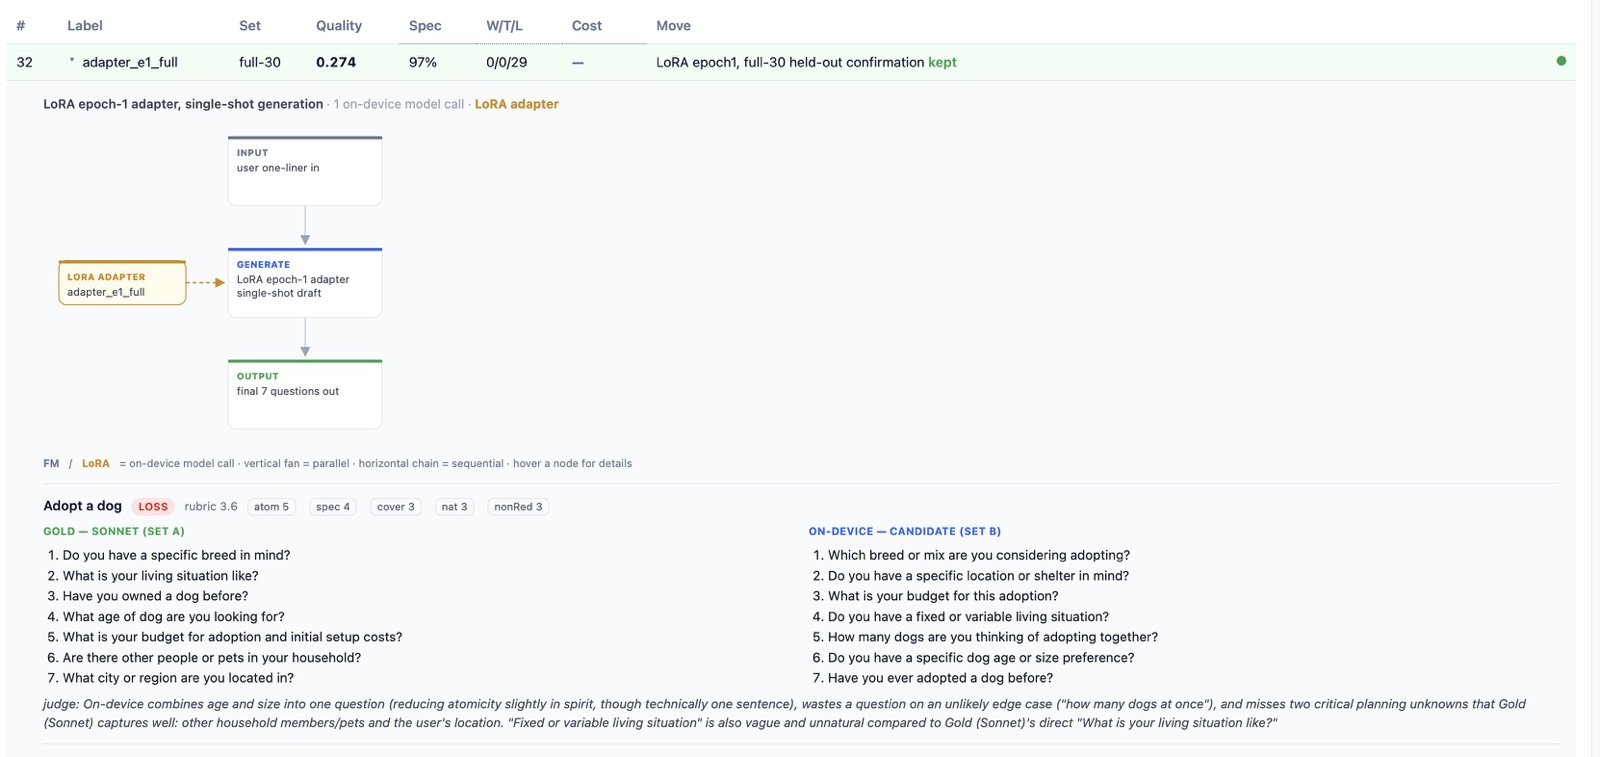
Okay! Adding a domain-specific LoRA adapter moved the needle the most.

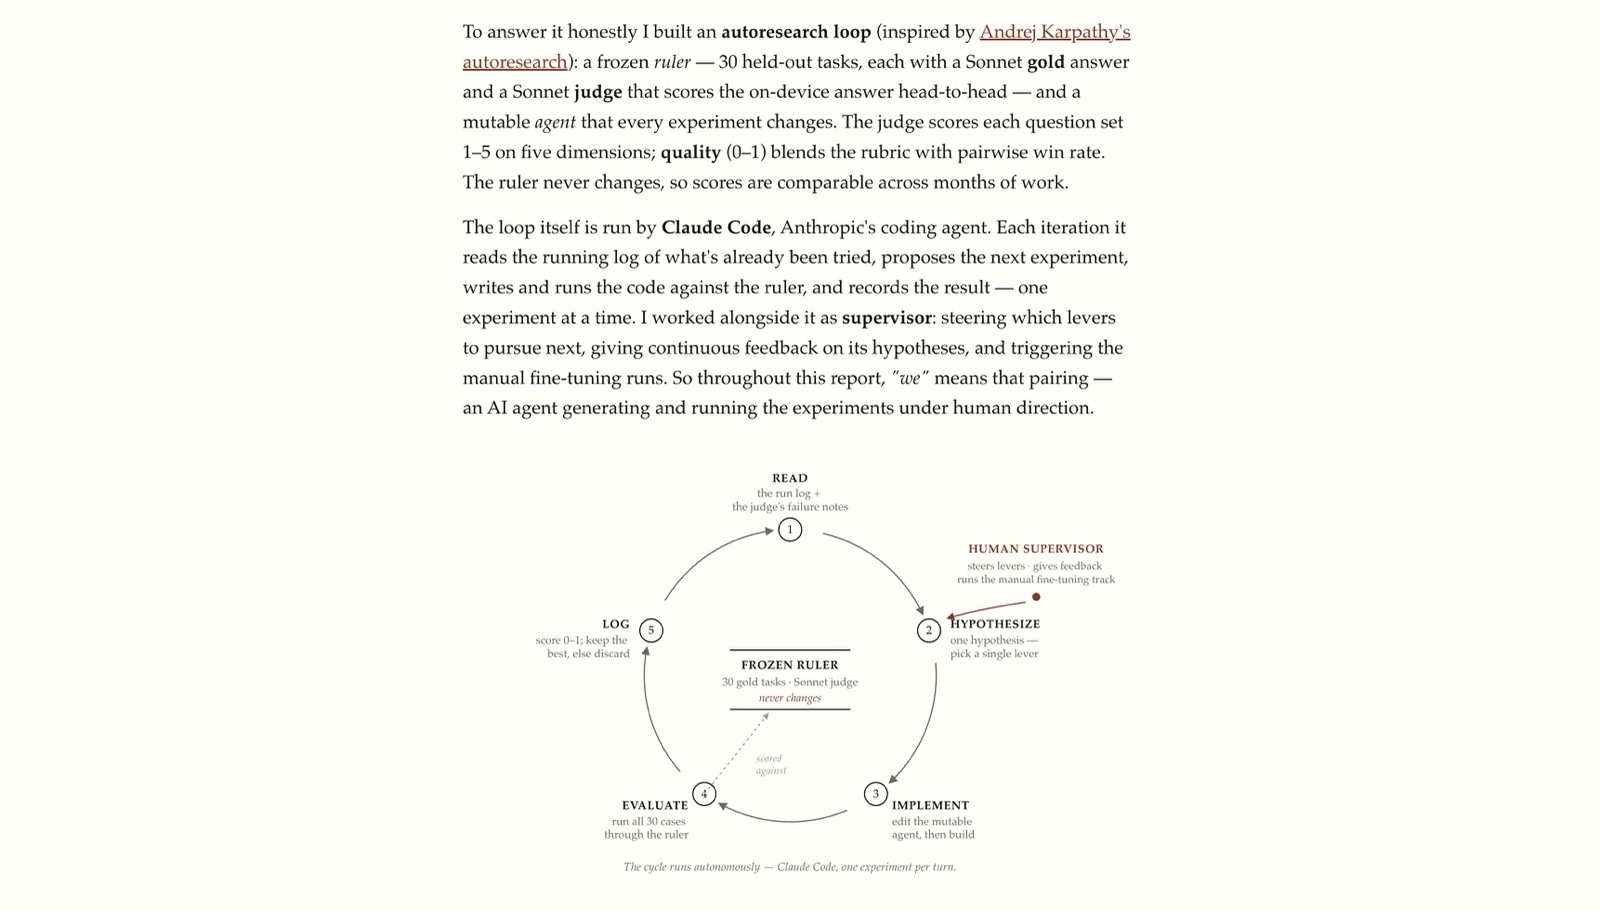
I bootstrapped an autoresearch loop that initially went through a bunch of experiments that tested a bunch of prompt/sequence/selection/critique and reflexion combos. Those didn't really result in much lift.

PS: If you haven't seen this yet, Apple provides the "Foundation Models Adapter Training Toolkit" over at

Image from the post
Image from the post
Image from the post
Image from the post
Apple DeveloperFoundation Models adapter training - Apple Intelligence - Apple Developer↗ developer.apple.com
1 like · 30 views

Infermation (/ɪnfərˈmeɪʃən/; portmanteau of inference and information) is knowledge produced by inferential processes rather than direct observation, measurement, or first-hand transmission.

Unlike conventional information, which is grounded in a source, infermation is derived — synthesized from patterns, priors, and partial evidence.