Everything I publish, in the order I published it: dispatches from Twitter, videos from YouTube and notes from my vault, archived here in full — text, images, video and links — so they outlive the platforms.
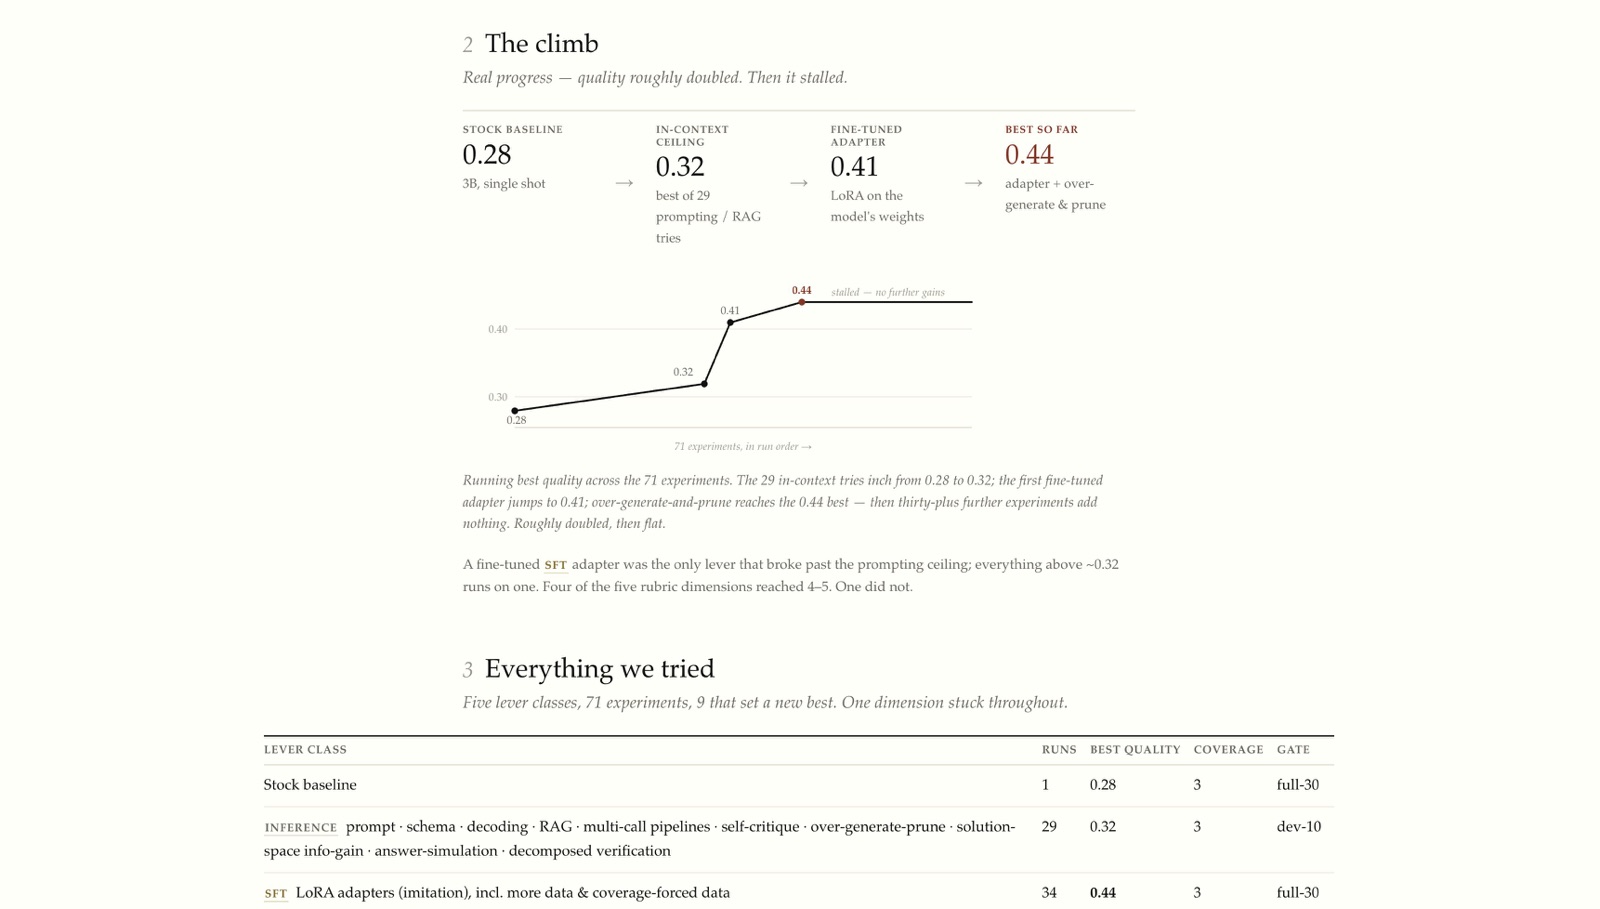
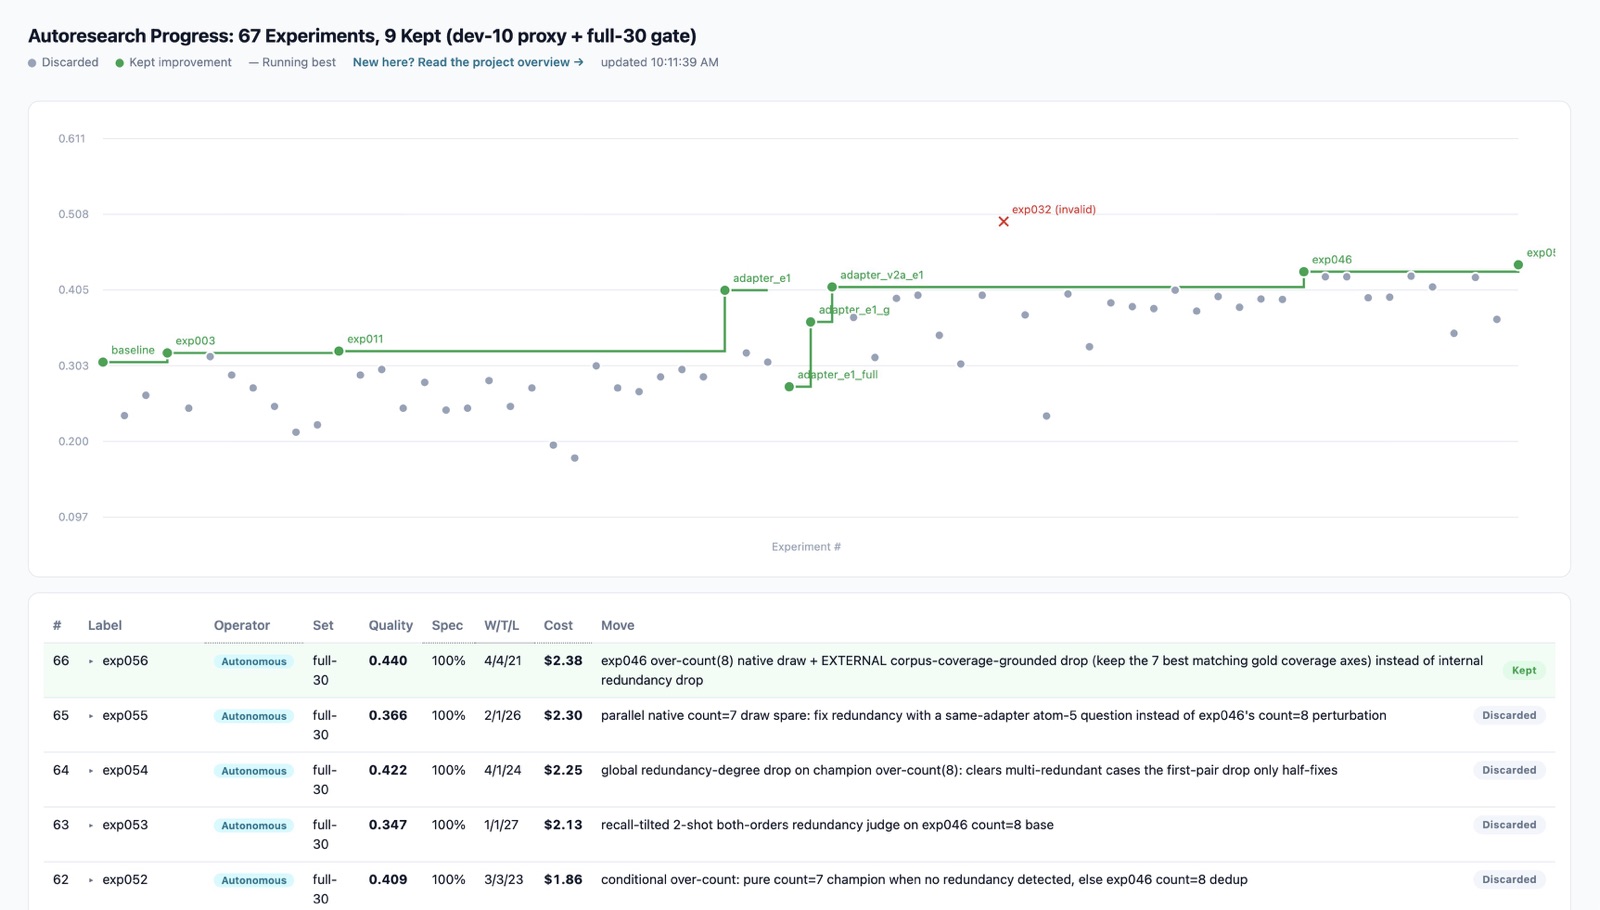
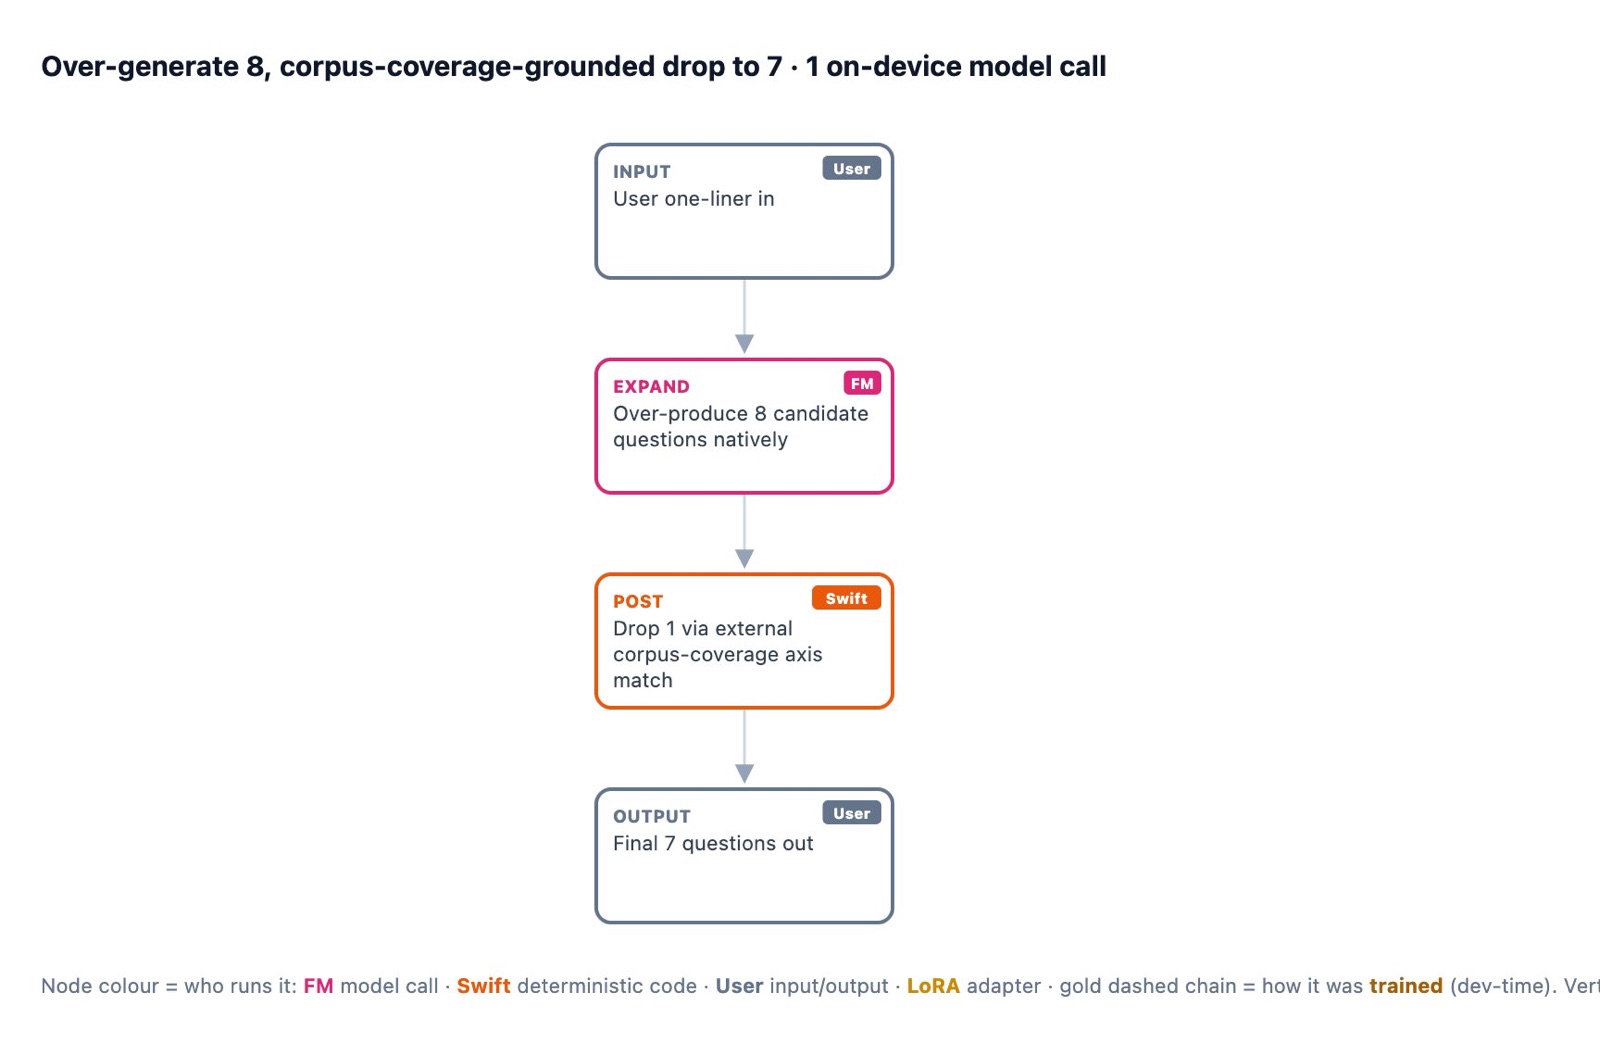
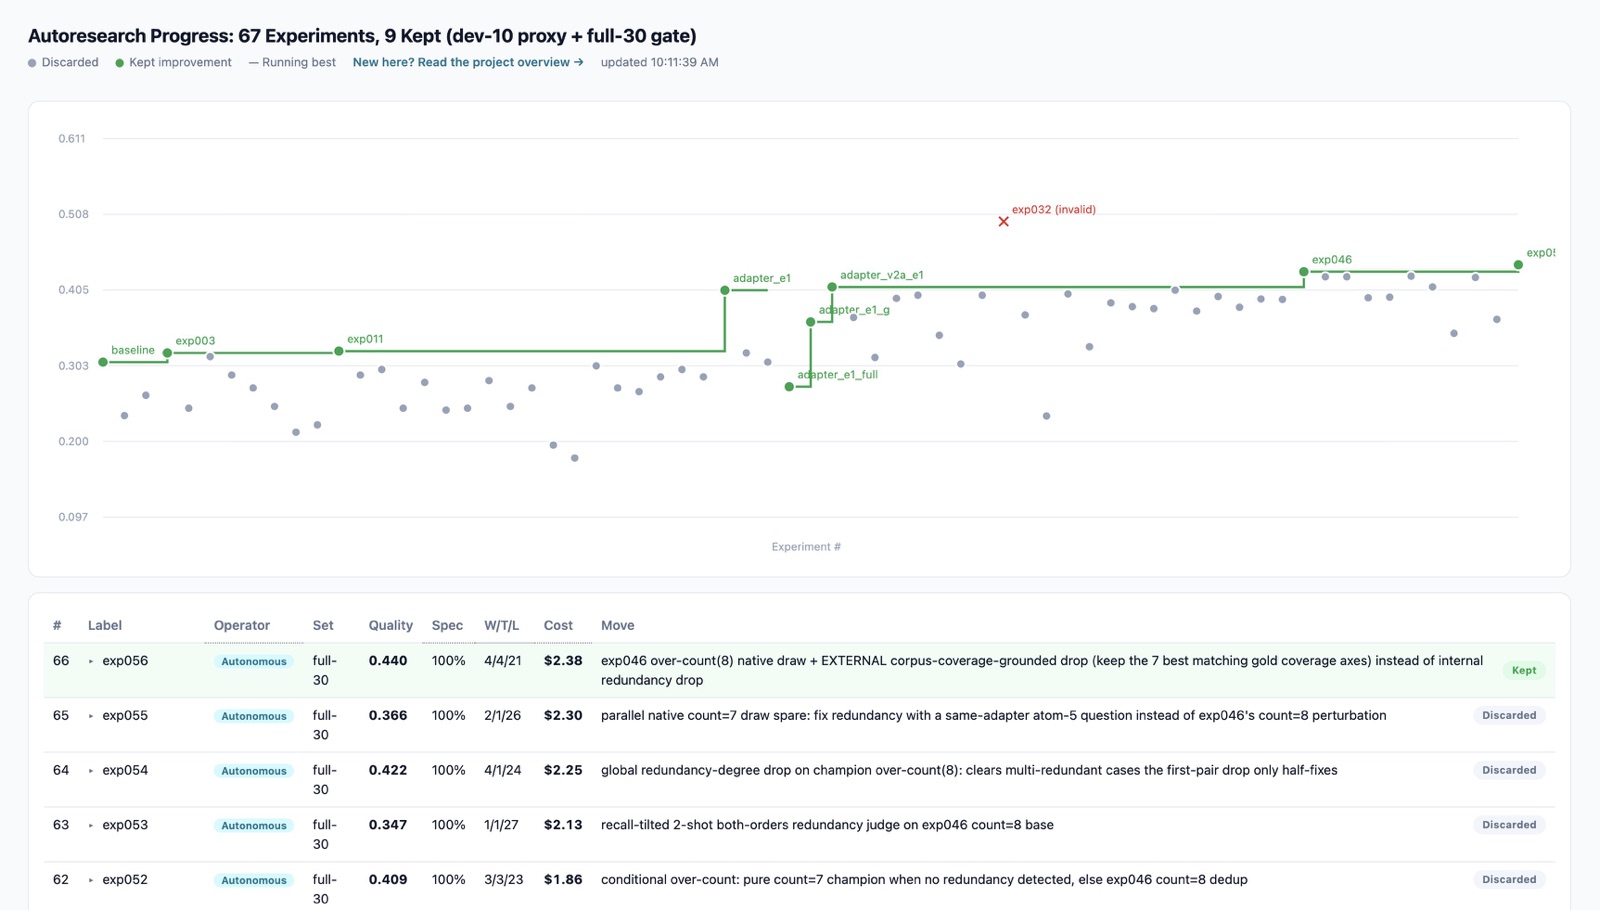
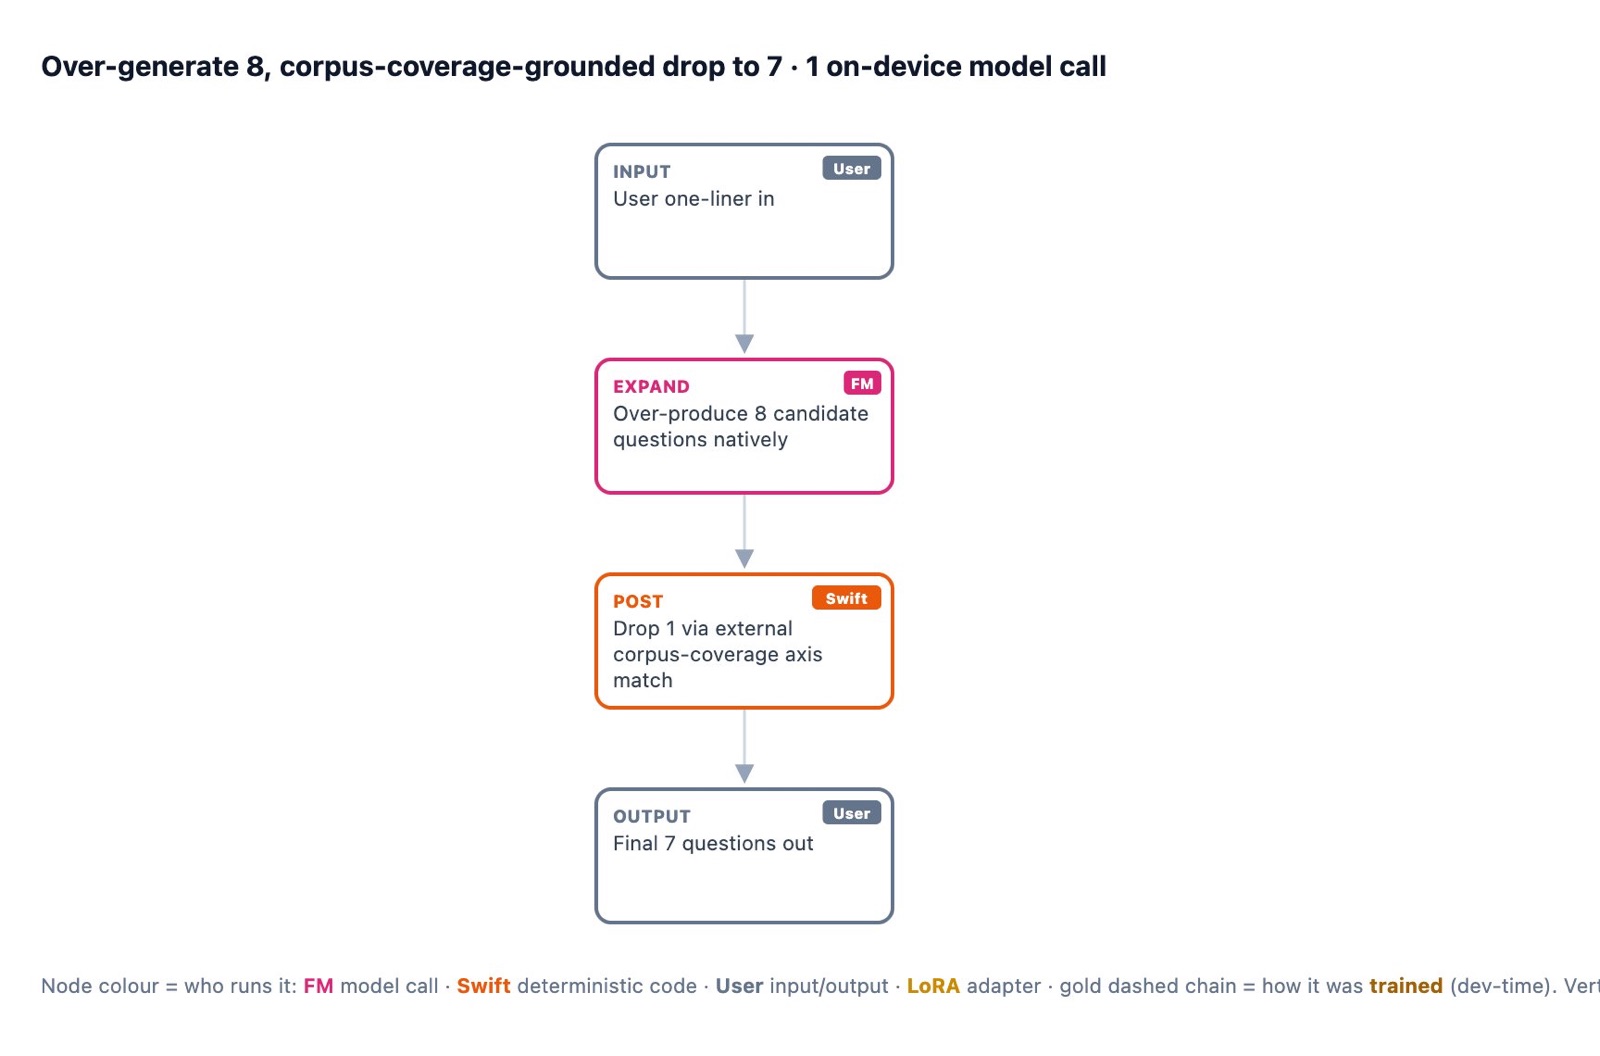
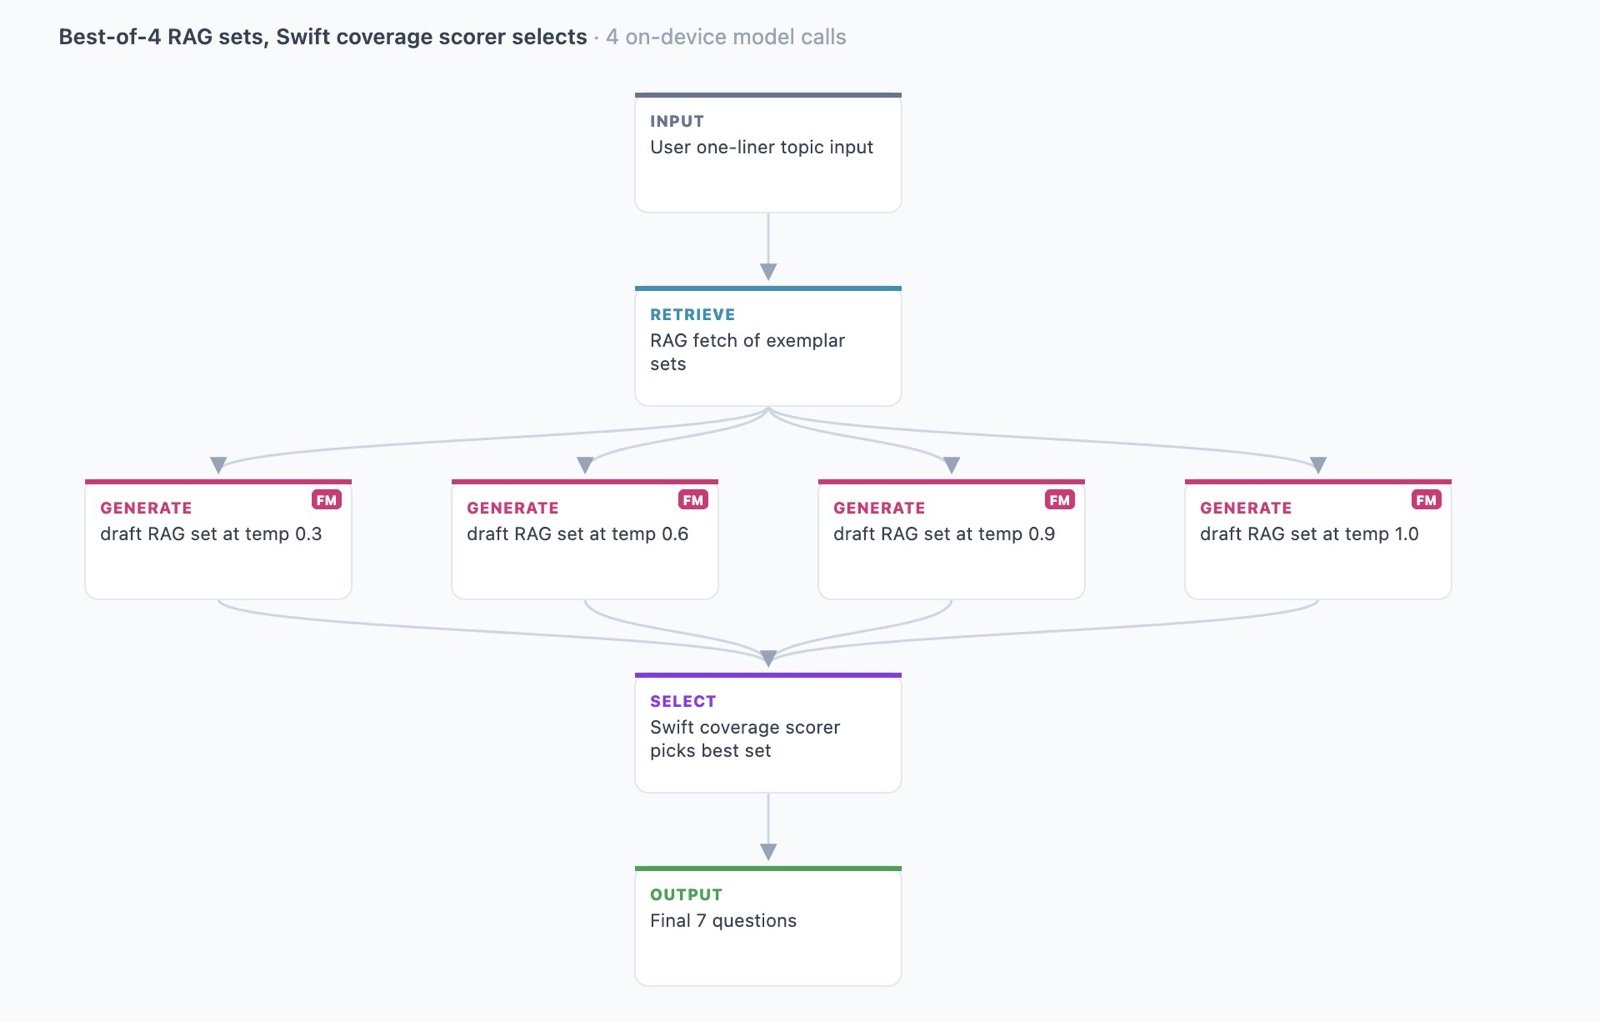
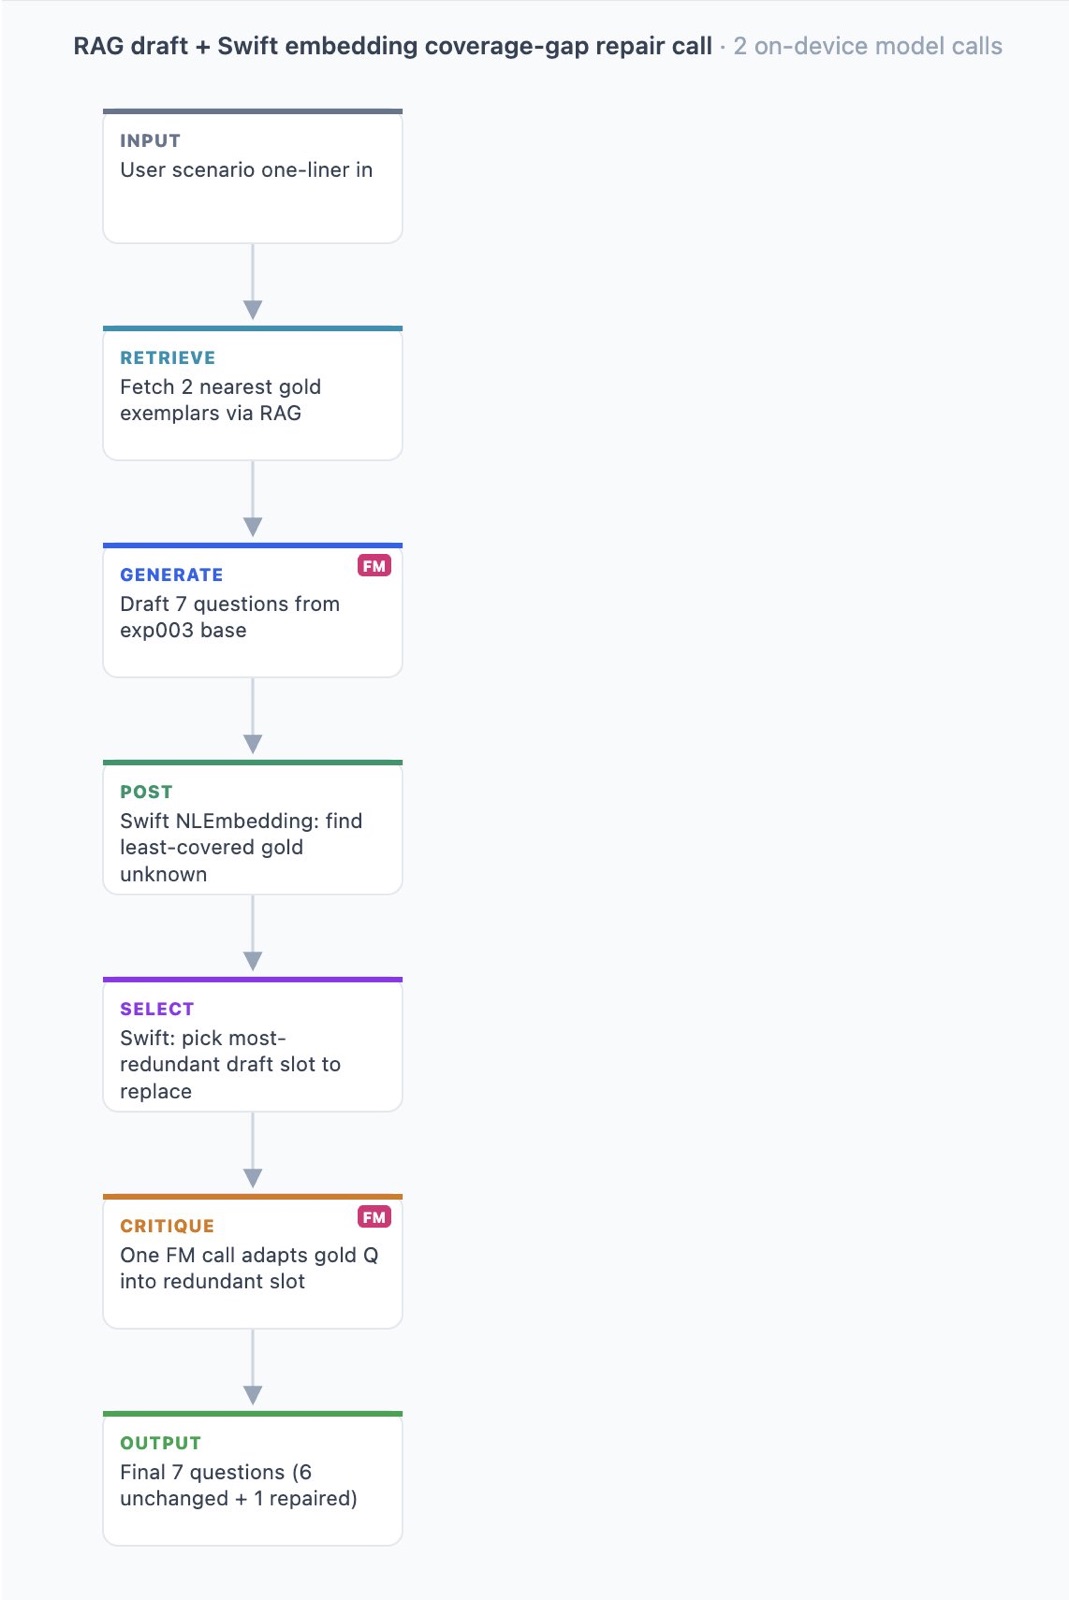
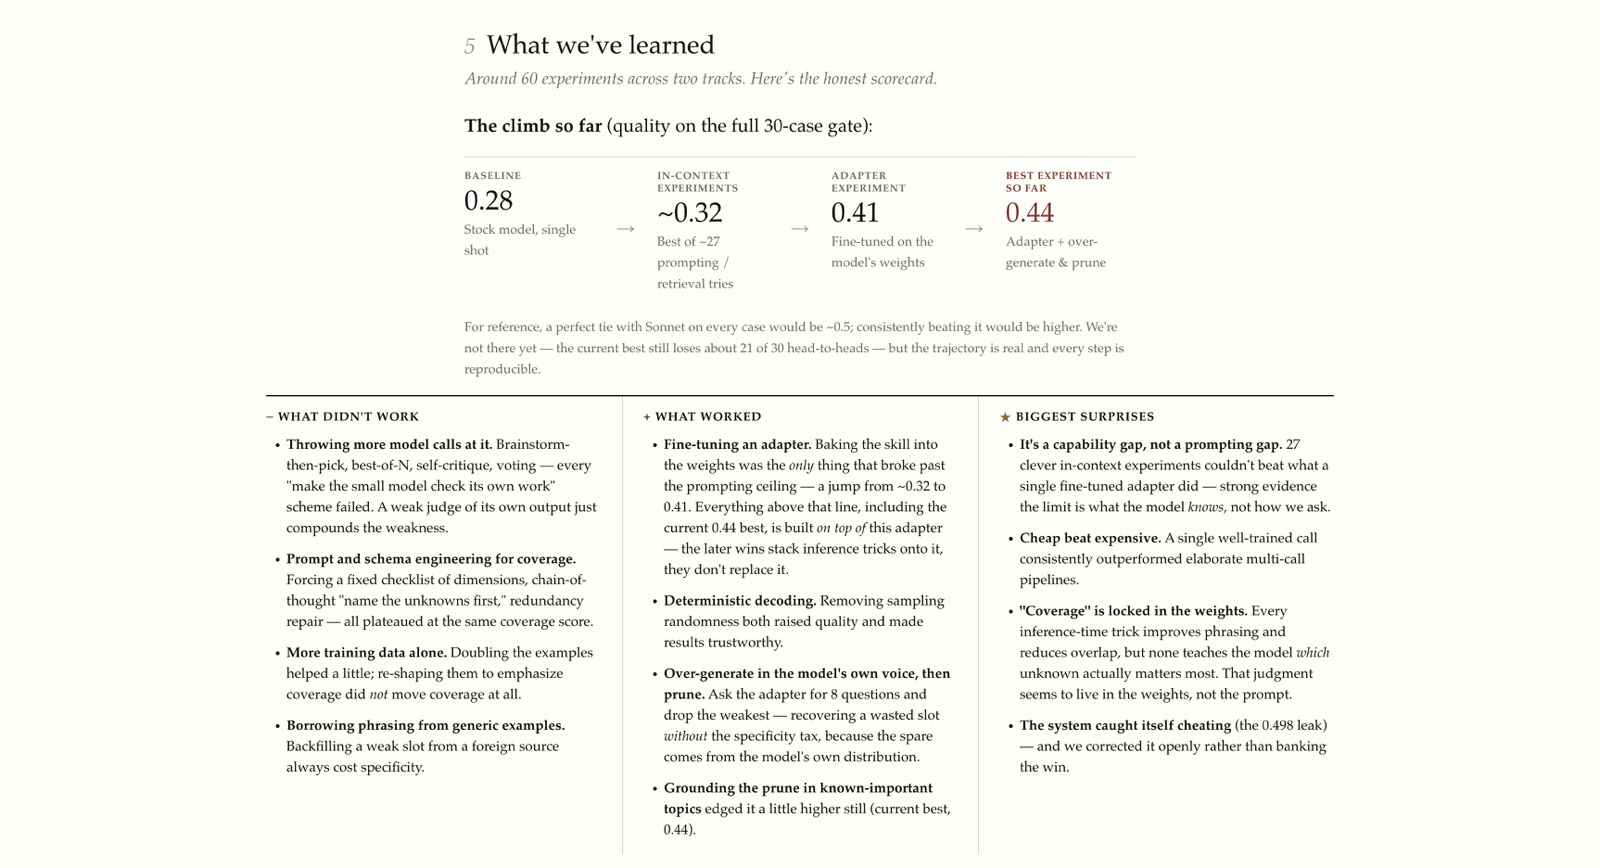
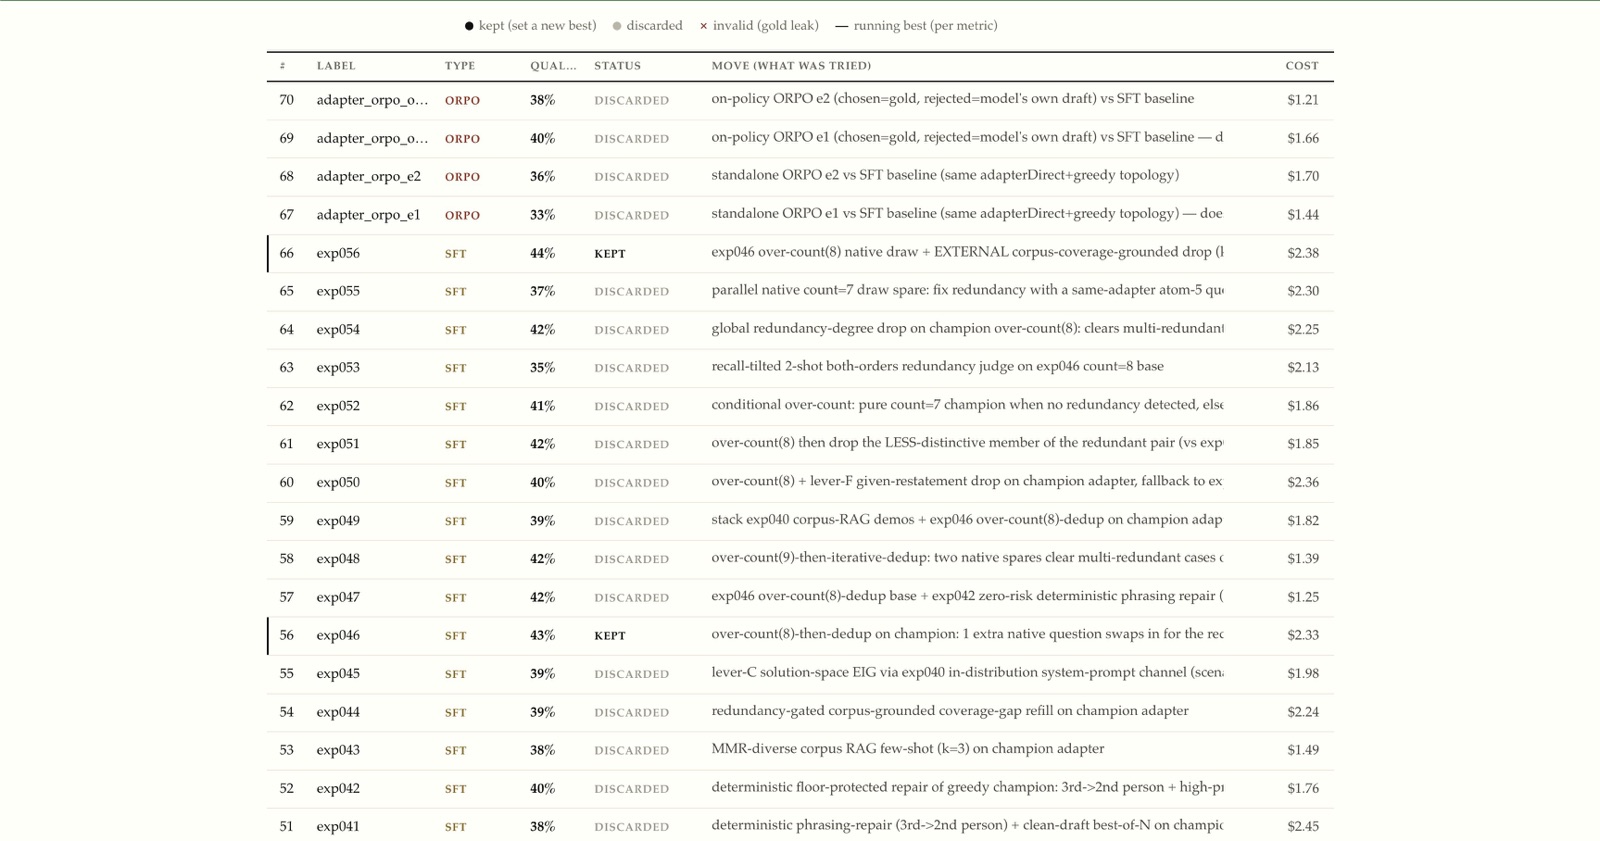
The autoresearch agent came up with an unexpected way to push quality to from 40% to 44%:
"First, generate one more option than we actually need, then throw away the one we can most afford to lose, keeping the rest."
Suprises:
1. It's much simpler than the LoRA adapter route
2. It produced four responses that were significantly better than their eval targets
3. I hit an Anthropic API usage limit for the first time (Yay!)
And, man, I have to say: As an experimenter autoresearch is really, really fun to work with, guide and learn from. I wish more people would have this experience in their domains.
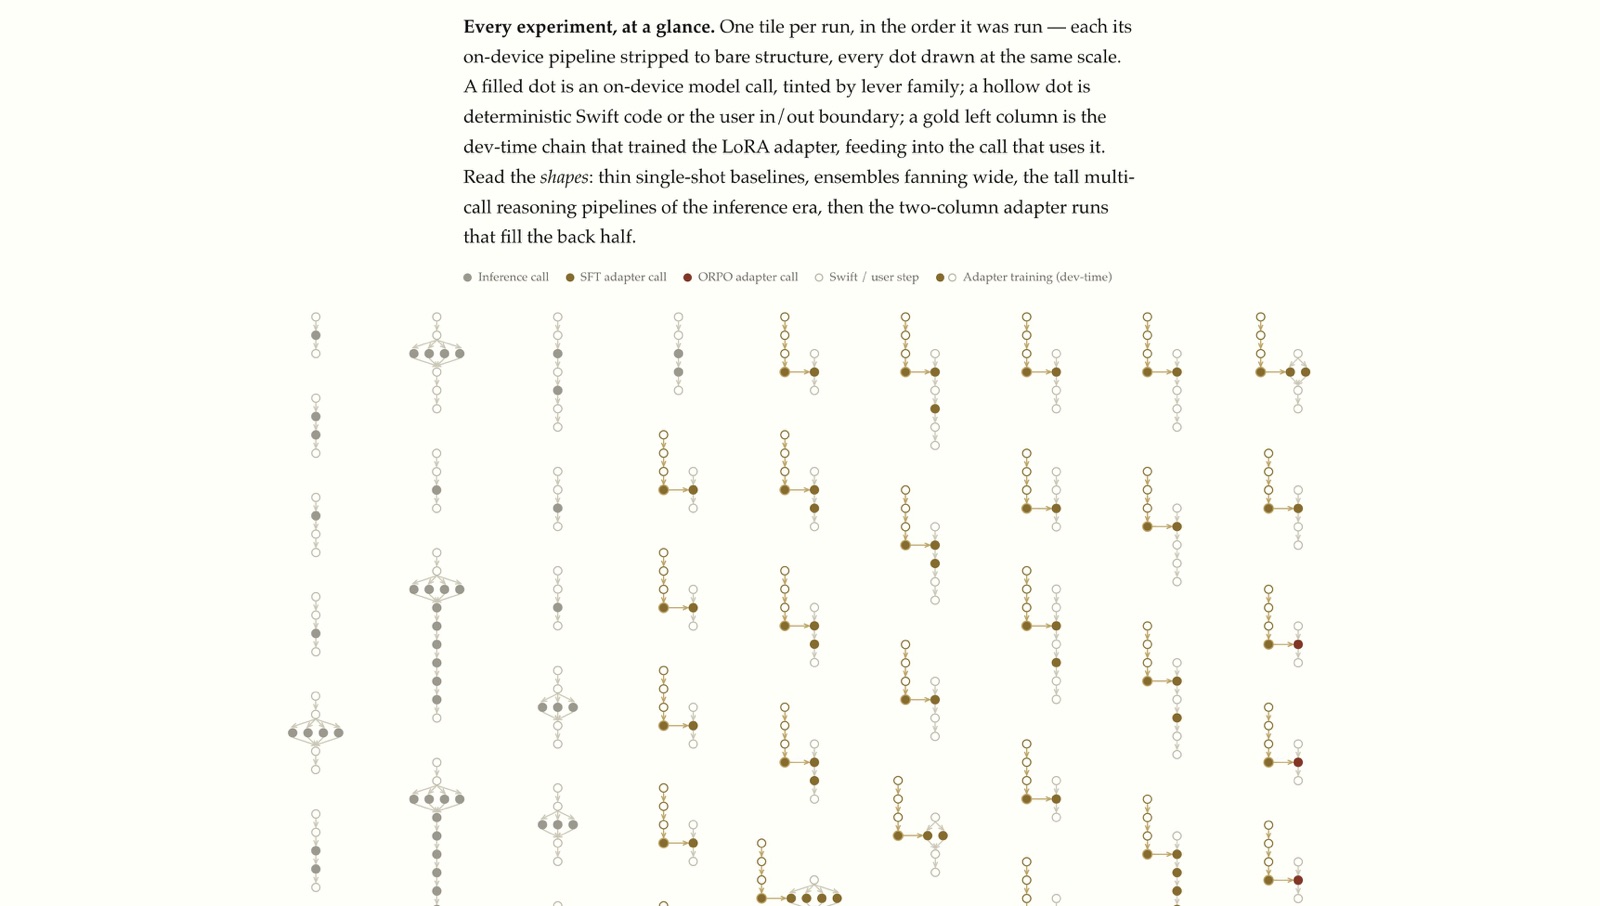
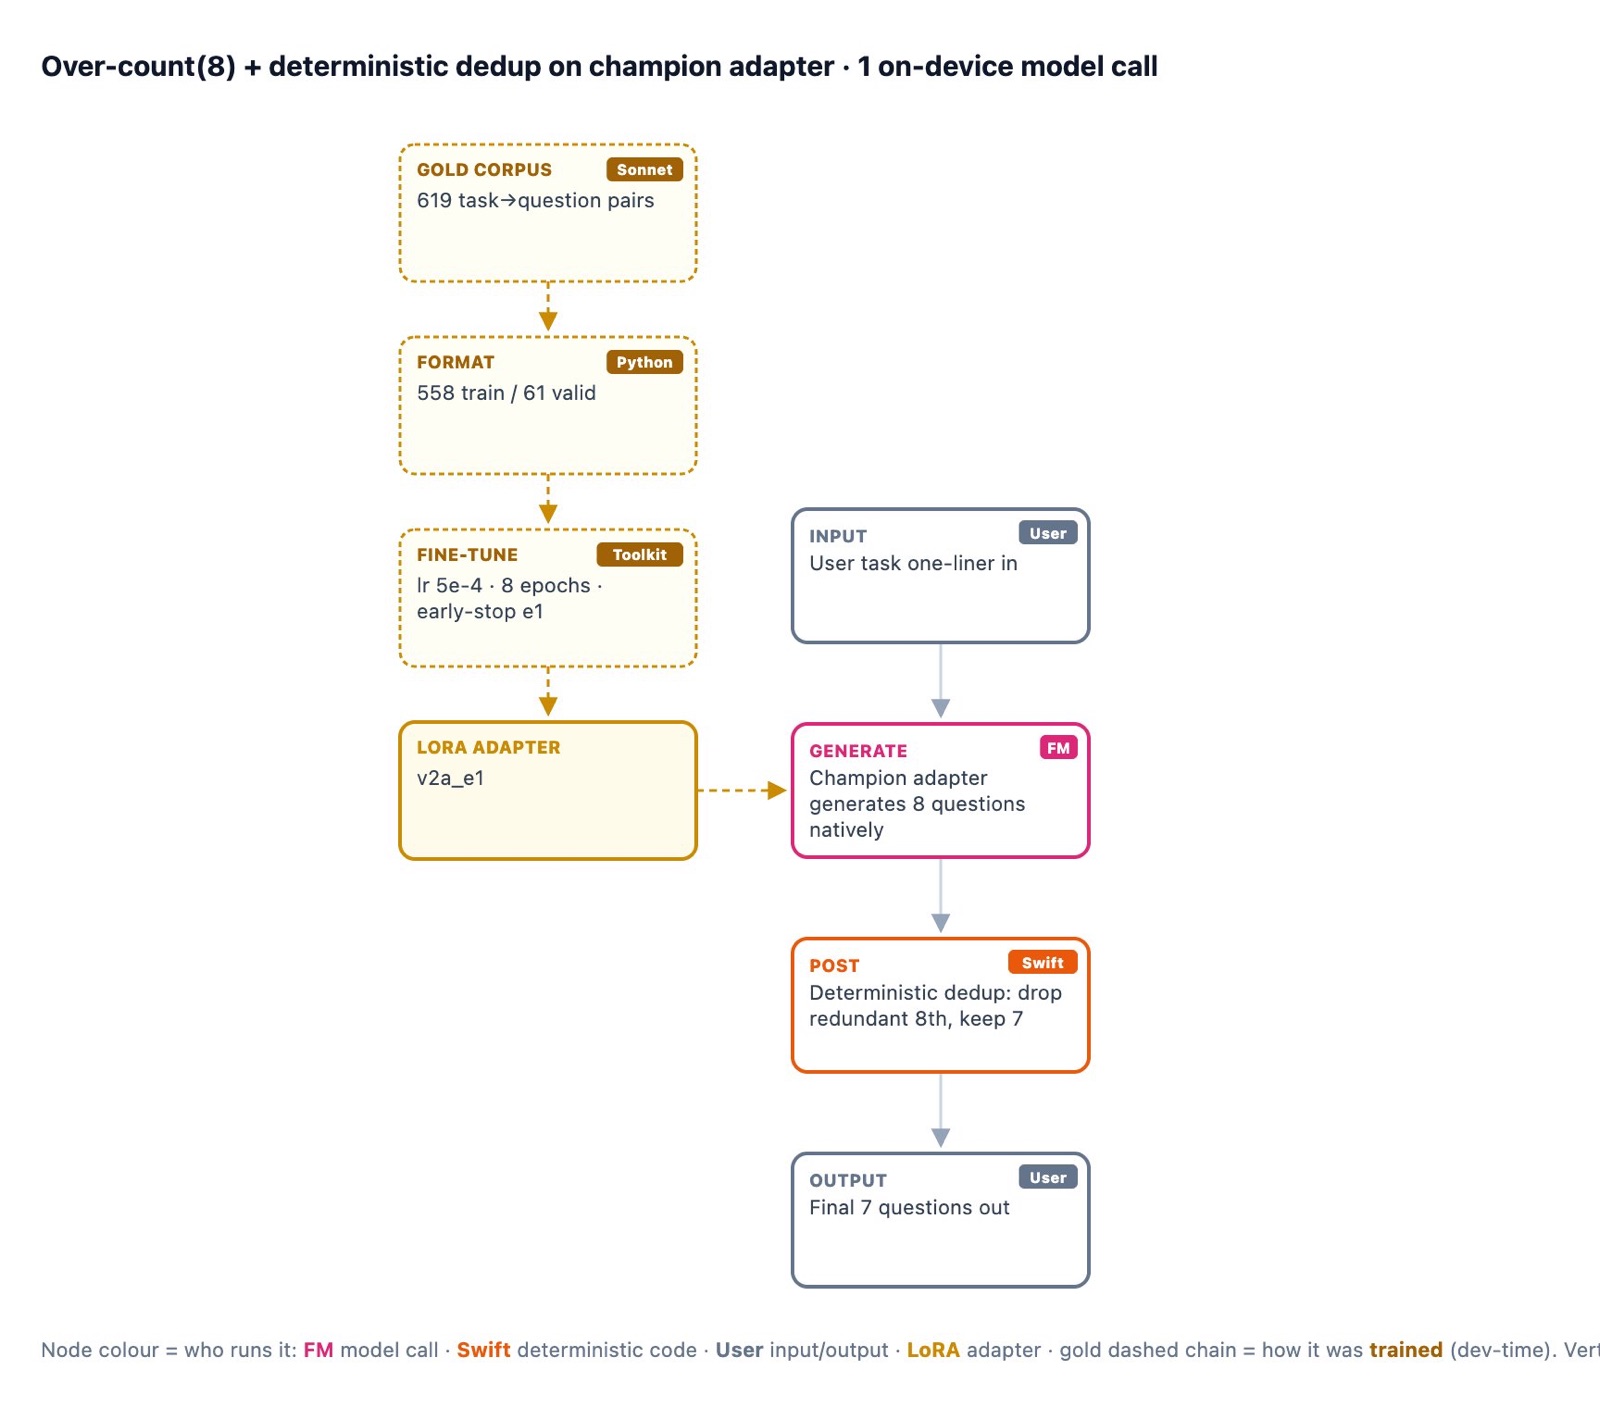
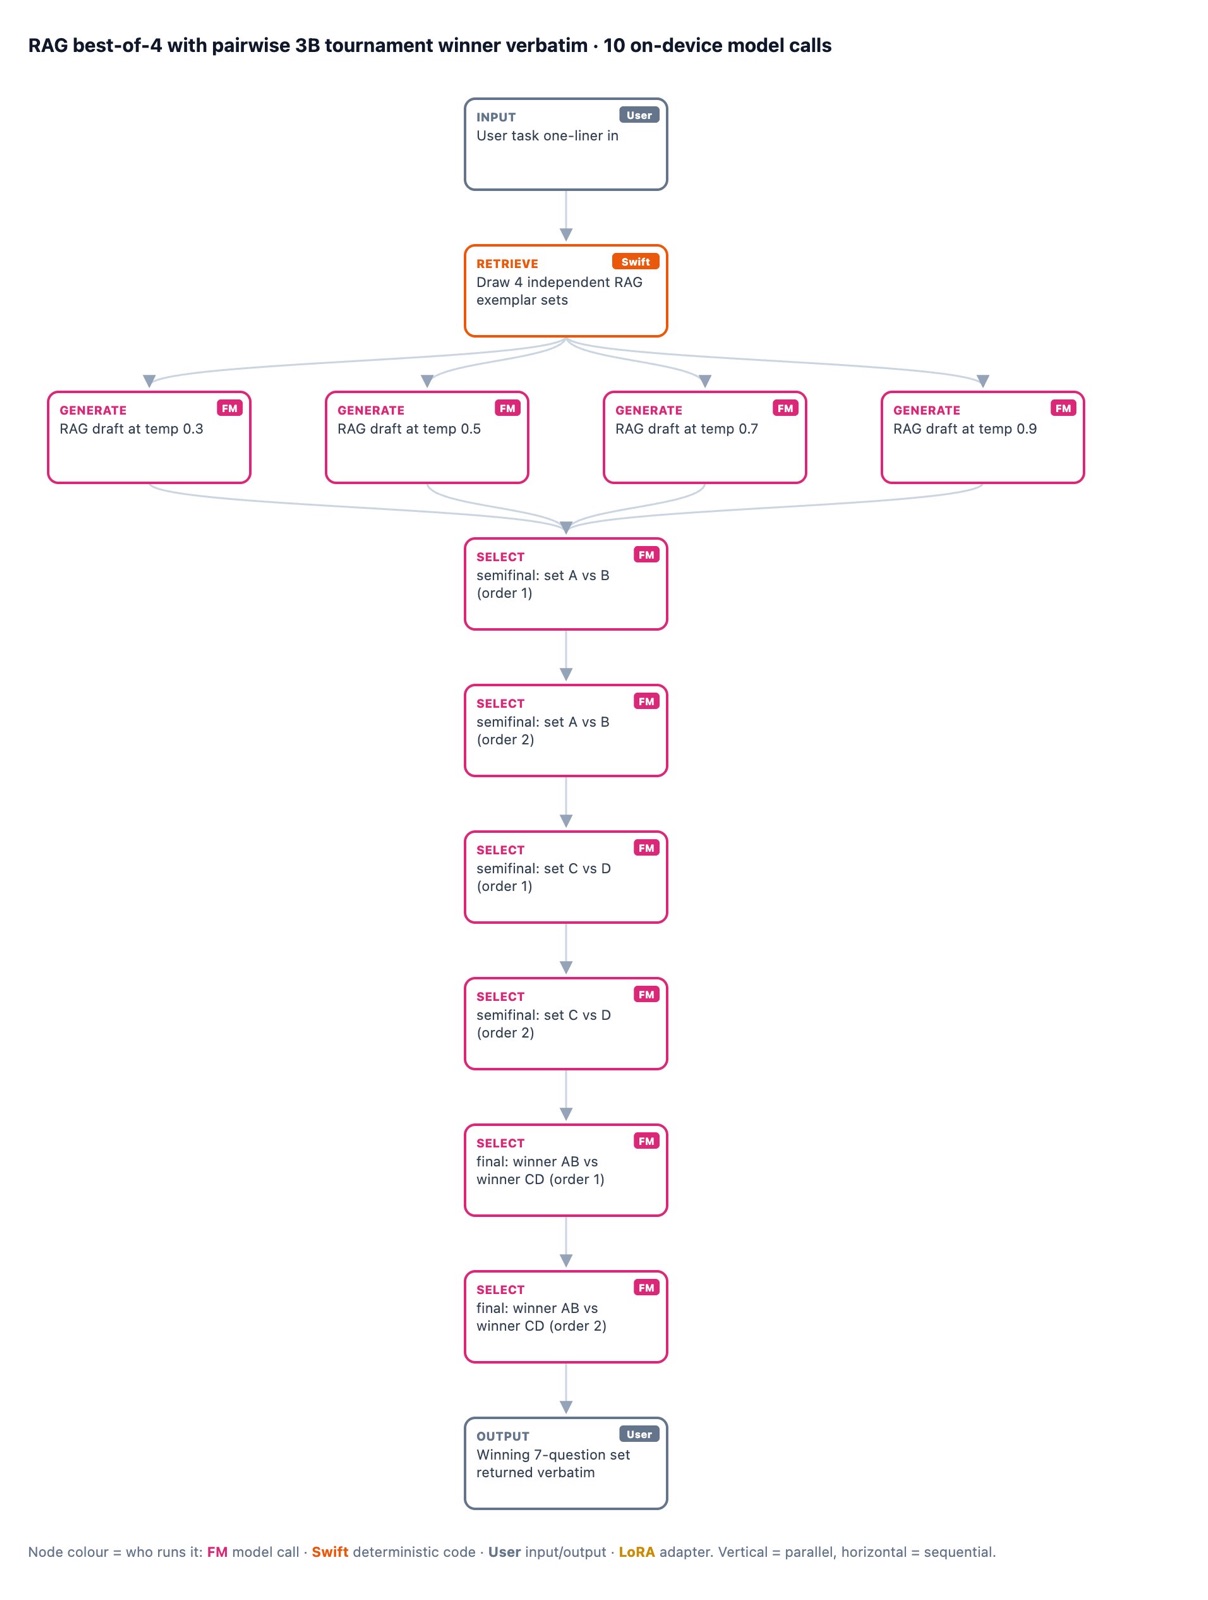
Ah, scratch the "Doesn't use LoRA" surprise. Experiment 056 is built ON-TOP of 046. I forgot to make the diagram-generator aware of this kind of experiment heritage.
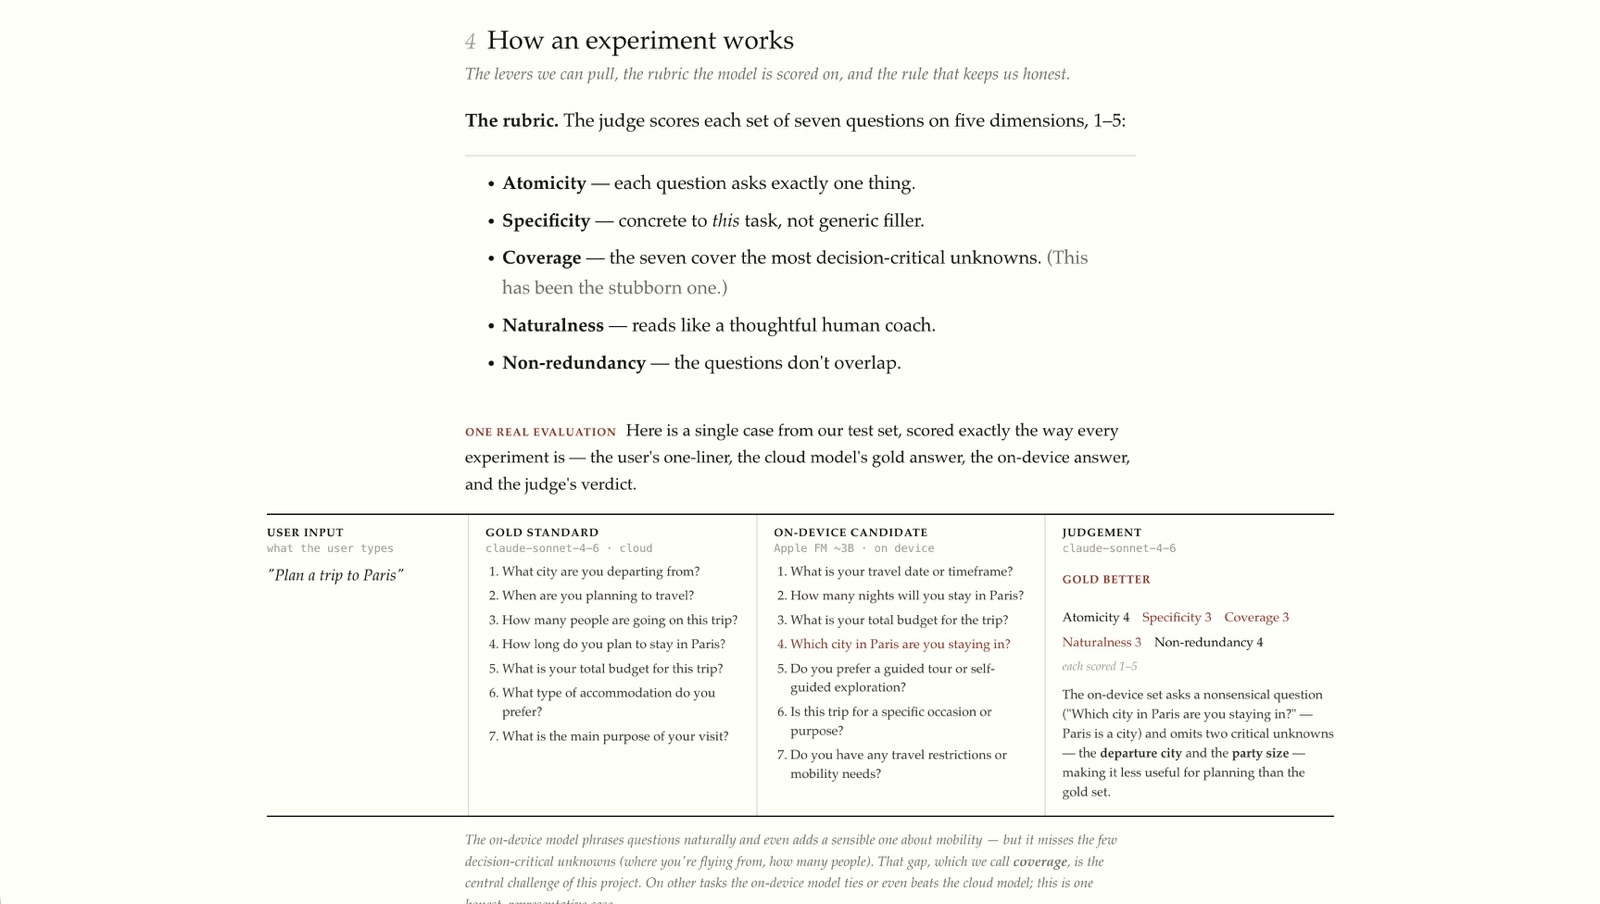
I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.
Alright!
The autoresearch agent came up with an unexpected way to push quality to from 40% to 44%:
"First, generate one more option than we actually need, then throw away the one we can most afford to lose, keeping the rest."
Suprises:
1. It's much simpler than the LoRA adapter route
2. It produced four responses that were significantly better than their eval targets
3. I hit an Anthropic API usage limit for the first time (Yay!)
And, man, I have to say: As an experimenter autoresearch is really, really fun to work with, guide and learn from. I wish more people would have this experience in their domains.
I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.
But basically I'm using frontier models to train a local ("homestead"?) model as to impart some of that good brain stuff but minus the overwhelm. Like a teacher, hopefully.
I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.
LOL, yeah, this one also not a keeper.
An old friend of mine shared this nugget of wisdom from art school with me:
I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.
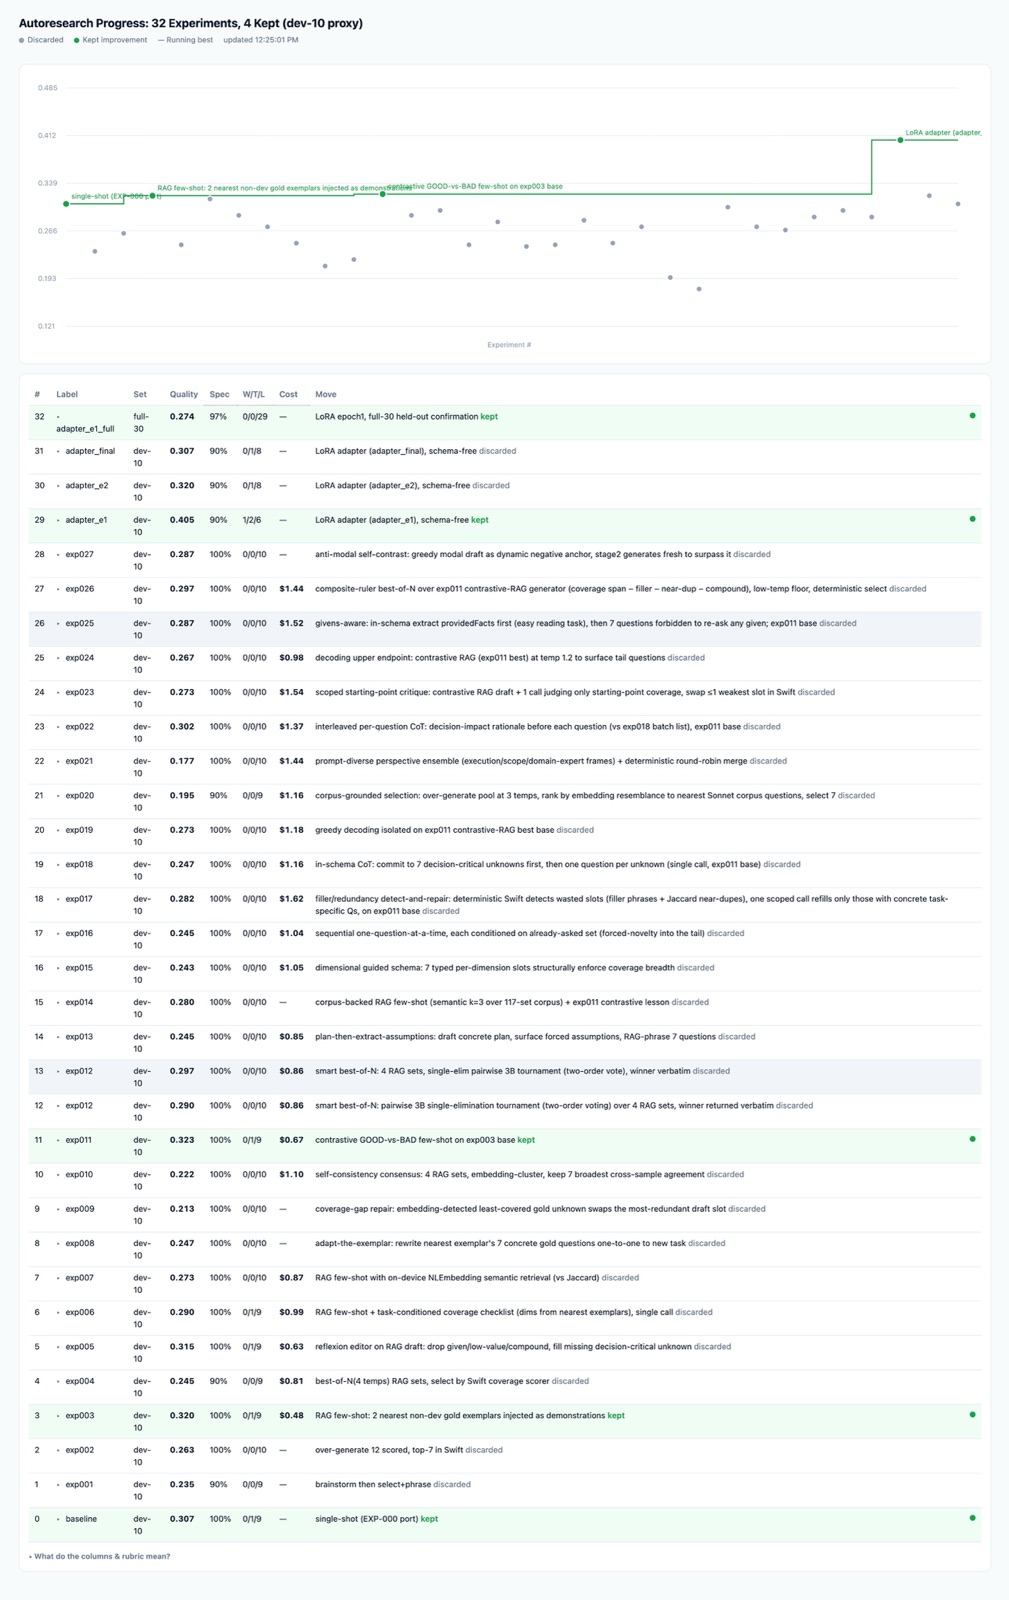
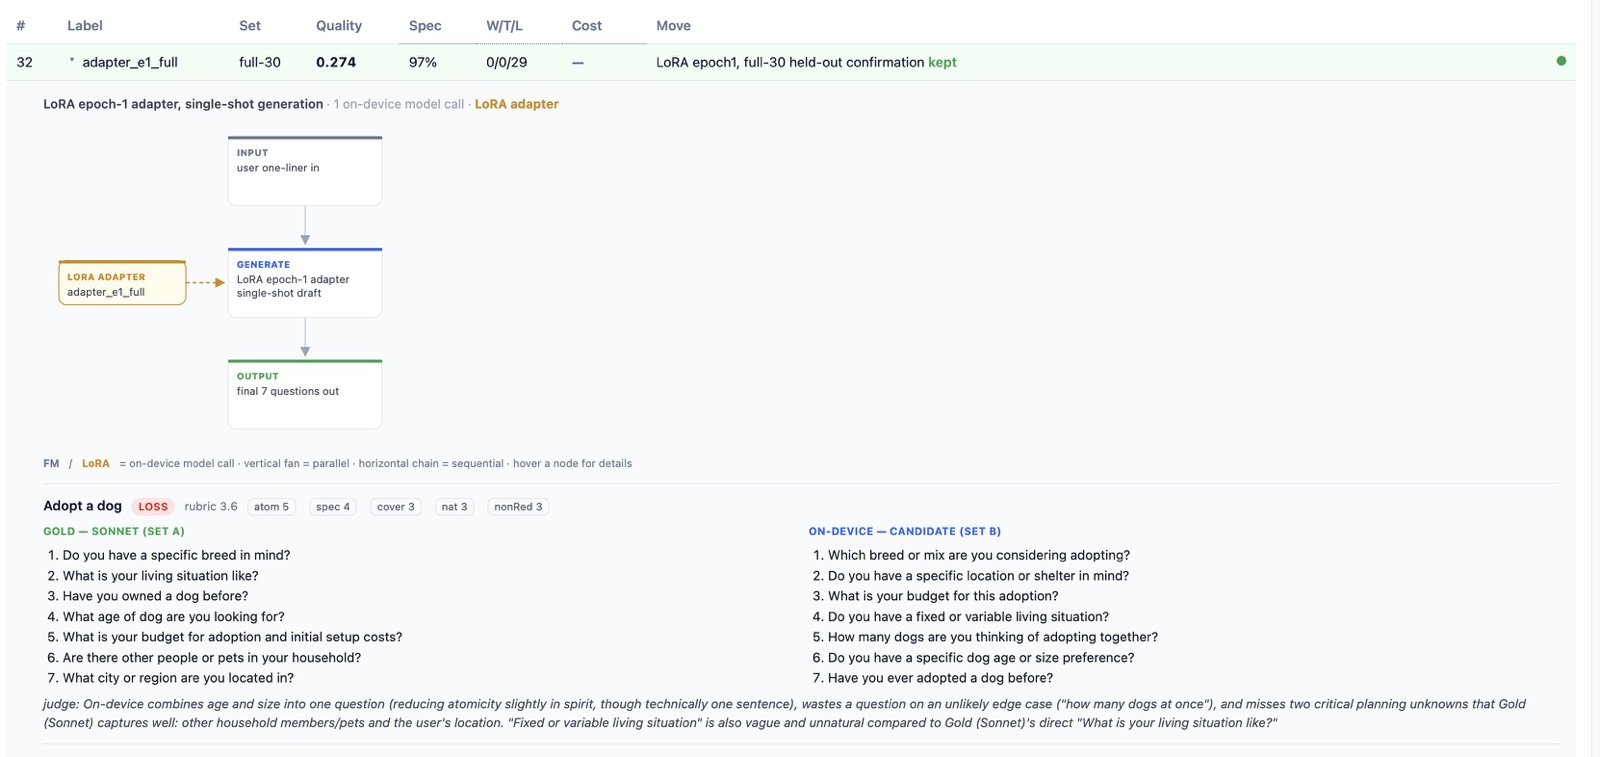
Okay! Adding a domain-specific LoRA adapter moved the needle the most.
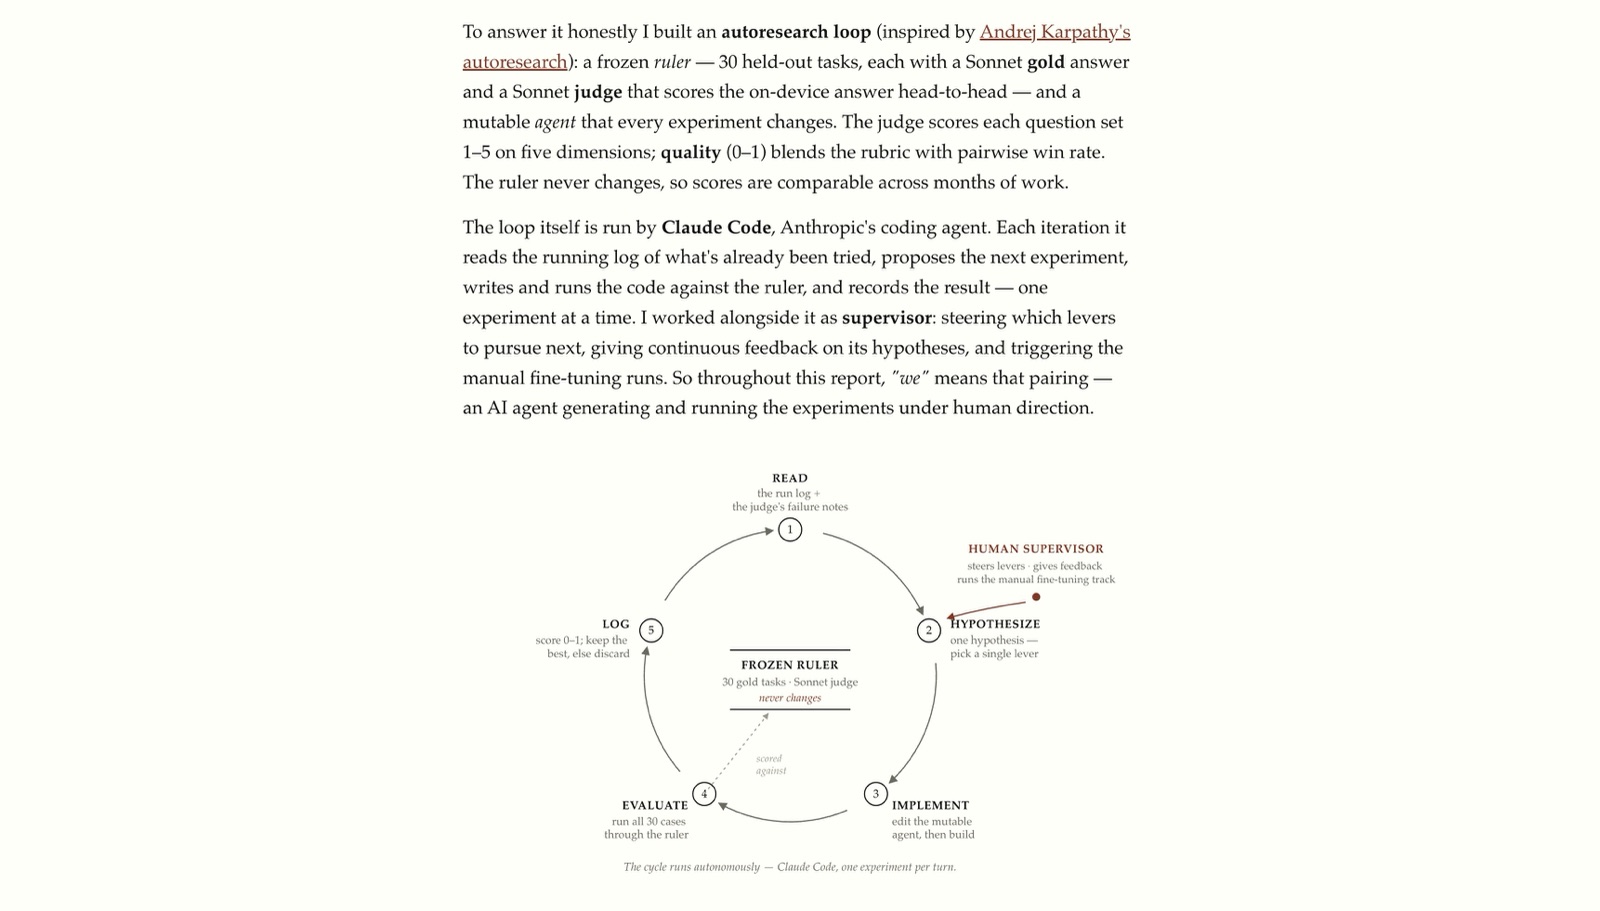
I bootstrapped an autoresearch loop that initially went through a bunch of experiments that tested a bunch of prompt/sequence/selection/critique and reflexion combos. Those didn't really result in much lift.
PS: If you haven't seen this yet, Apple provides the "Foundation Models Adapter Training Toolkit" over at
I'm unironically on a quest to figure out how to get local Apple's Foundation Models to respond at the quality of recent Sonnet across five rubriks that I care for.
Infermation (/ɪnfərˈmeɪʃən/; portmanteau of inference and information) is knowledge produced by inferential processes rather than direct observation, measurement, or first-hand transmission.
Unlike conventional information, which is grounded in a source, infermation is derived — synthesized from patterns, priors, and partial evidence.
Okay, with a bit of fiddling yesterday, I've now got a serious day-to-day contender to Claude Code. Pi(.)dev + unsloth/qwen3.6-35b-a3b-ud-mlx served via @lmstudio.
The video below is not sped up. It shows the agent wrapping up bootstrapping and running a small suite of UX tests, making a commit and doing some house cleaning.
Honestly: It's fast. It's "Good Enough™️". And most importantly: It's predictable.
After spending most of March and April outright fighting with Opus every single day, I'll take predictable over powerful any day now.
And I want to point out: Running it requires 20G of RAM. A clean 20G. Not less. But also NOT more.
@lmstudio PS: Thank you @badlogicgames and the team for building Pi. Feels good to work with a clean, lean agent harness again.
Okay, with a bit of fiddling yesterday, I've now got a serious day-to-day contender to Claude Code. Pi(.)dev + unsloth/qwen3.6-35b-a3b-ud-mlx served via @lmstudio.
The video below is not sped up. It shows the agent wrapping up bootstrapping and running a small suite of UX tests, making a commit and doing some house cleaning.
Honestly: It's fast. It's "Good Enough™️". And most importantly: It's predictable.
After spending most of March and April outright fighting with Opus every single day, I'll take predictable over powerful any day now.
And I want to point out: Running it requires 20G of RAM. A clean 20G. Not less. But also NOT more.
Autonomous Research with AI: can an AI agent's autoresearch loop teach Apple's phone-sized 3B Foundation Model to ask frontier-quality questions? 96 experiments across every lever we could find brought it within ~1 rubric point of Claude Sonnet 4.6. Also the home of Tada, the iOS app it was built for.
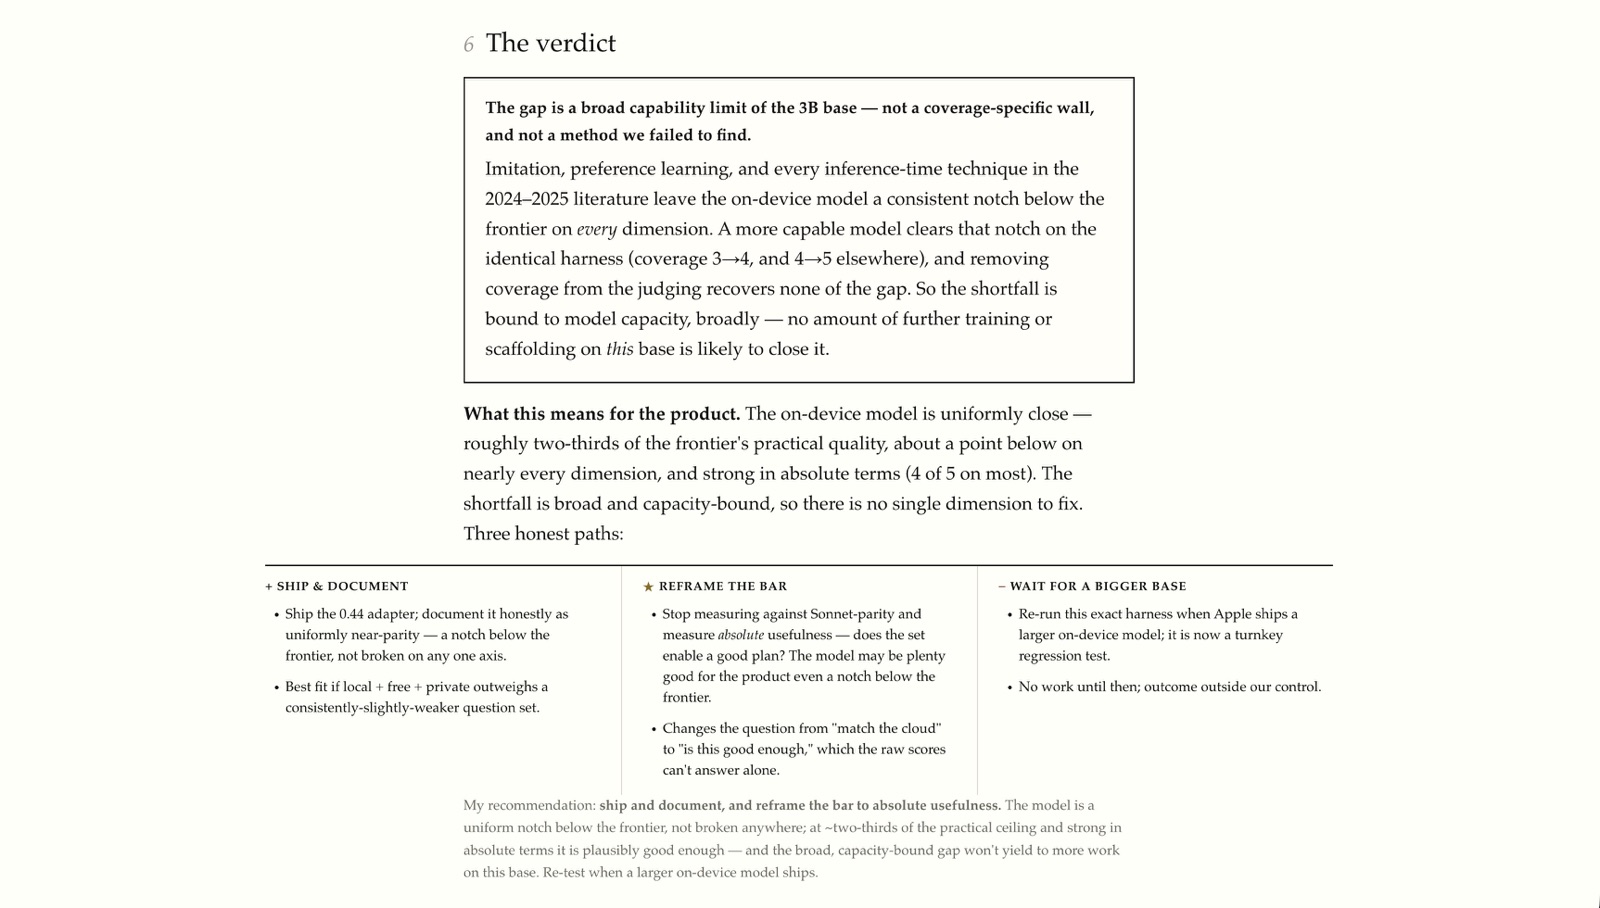
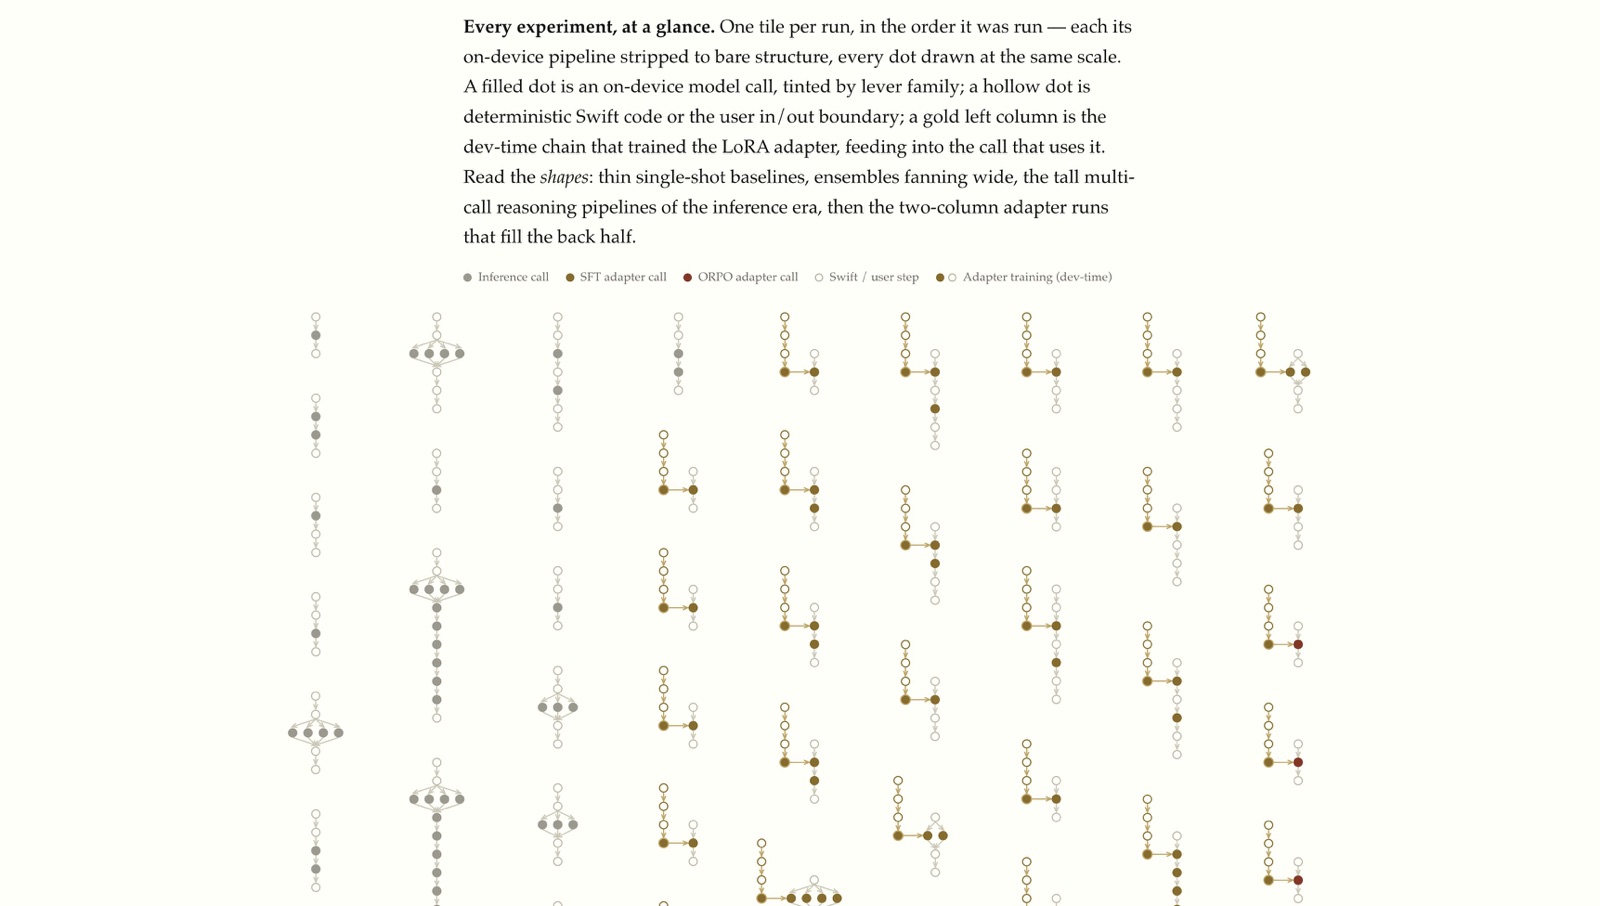
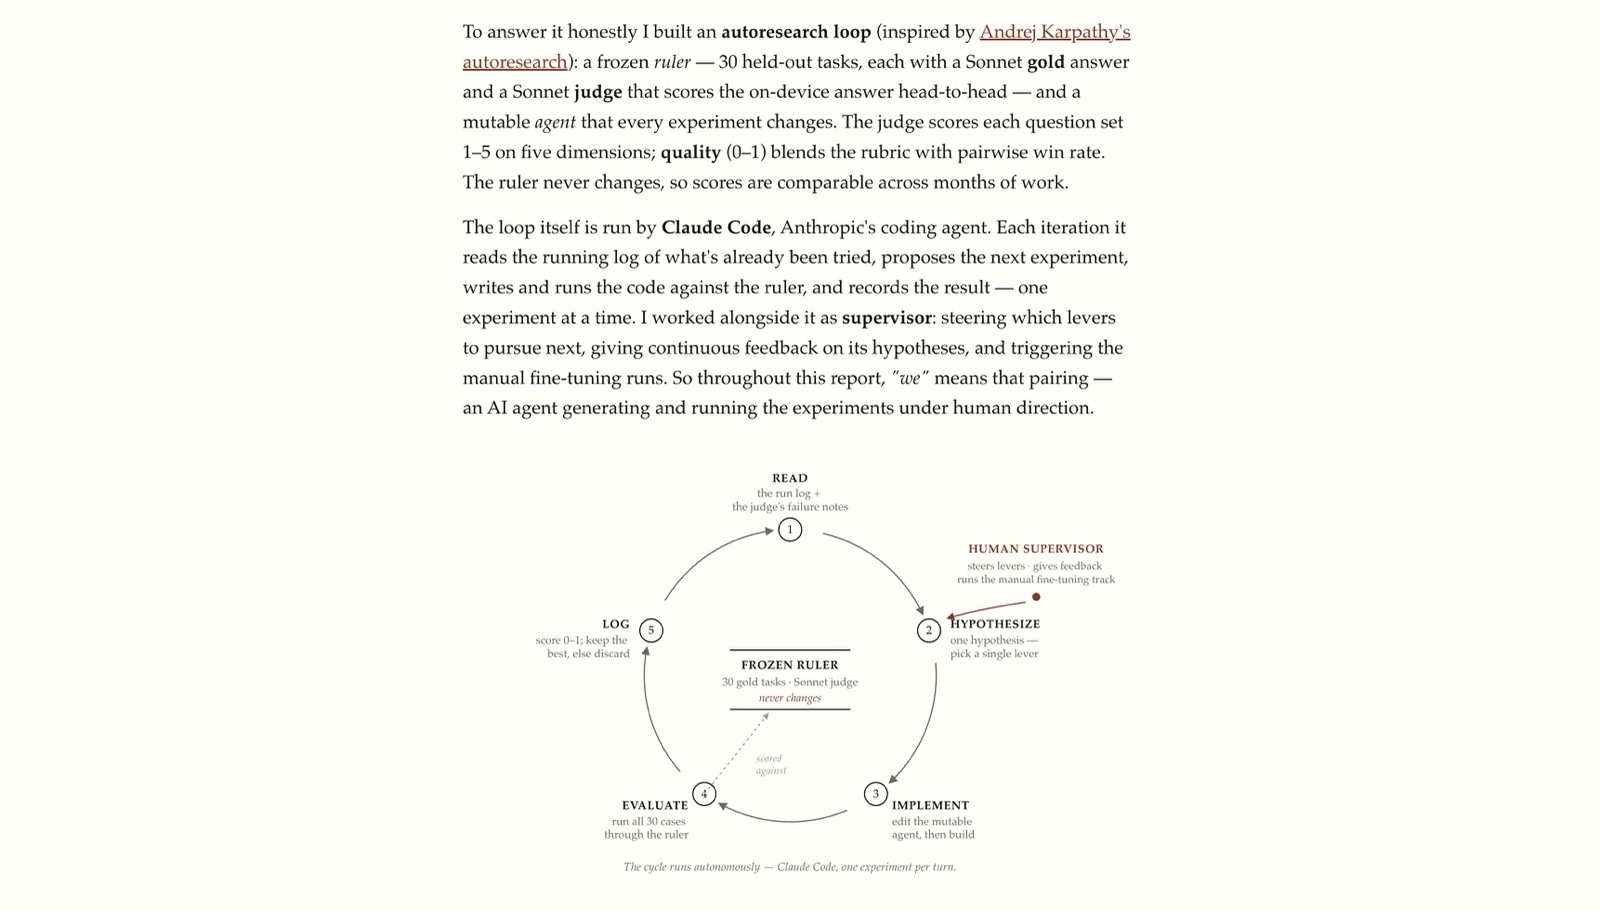
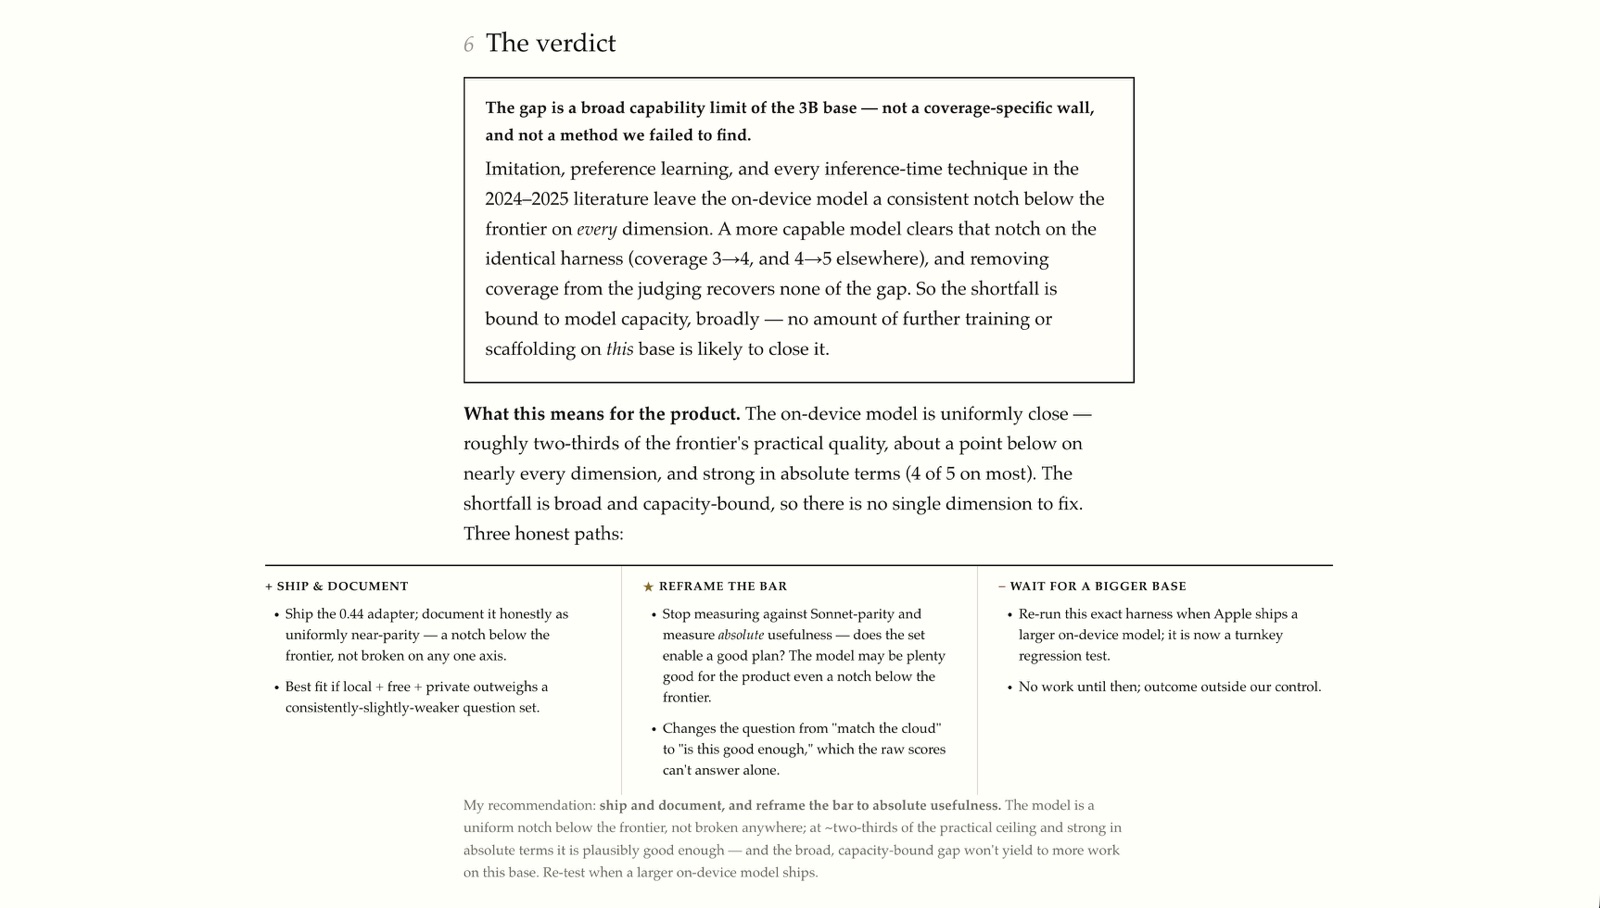
An AI agent running an autoresearch loop — 96 experiments across every lever we could find: prompting, retrieval, decoding, pipeline, fine-tuning, preference-learning, reinforcement-learning, adversarial-distillation — found a technique that brings Apple’s native 2025 3B Foundation Model within about one rubric point of a frontier cloud model (Claude Sonnet 4.6) on every quality dimension.
Ich glaube 45heval sollte man im Auge behalten. t.co/Phcr9nYtzQ
@floydthebong Hab Heval gestern über /r/Germanrap entdeckt. Richtig, richtig geil.
Hatte so eine ähnliche Reaktion wie erstes Mal MC Rene hören. Oder Konkret Finn. Oder Savas. 20 Sekunden zugehört und es ist einfach klar: "Top Talent und frisch und ehrlich und auch ein bisschen lustig."
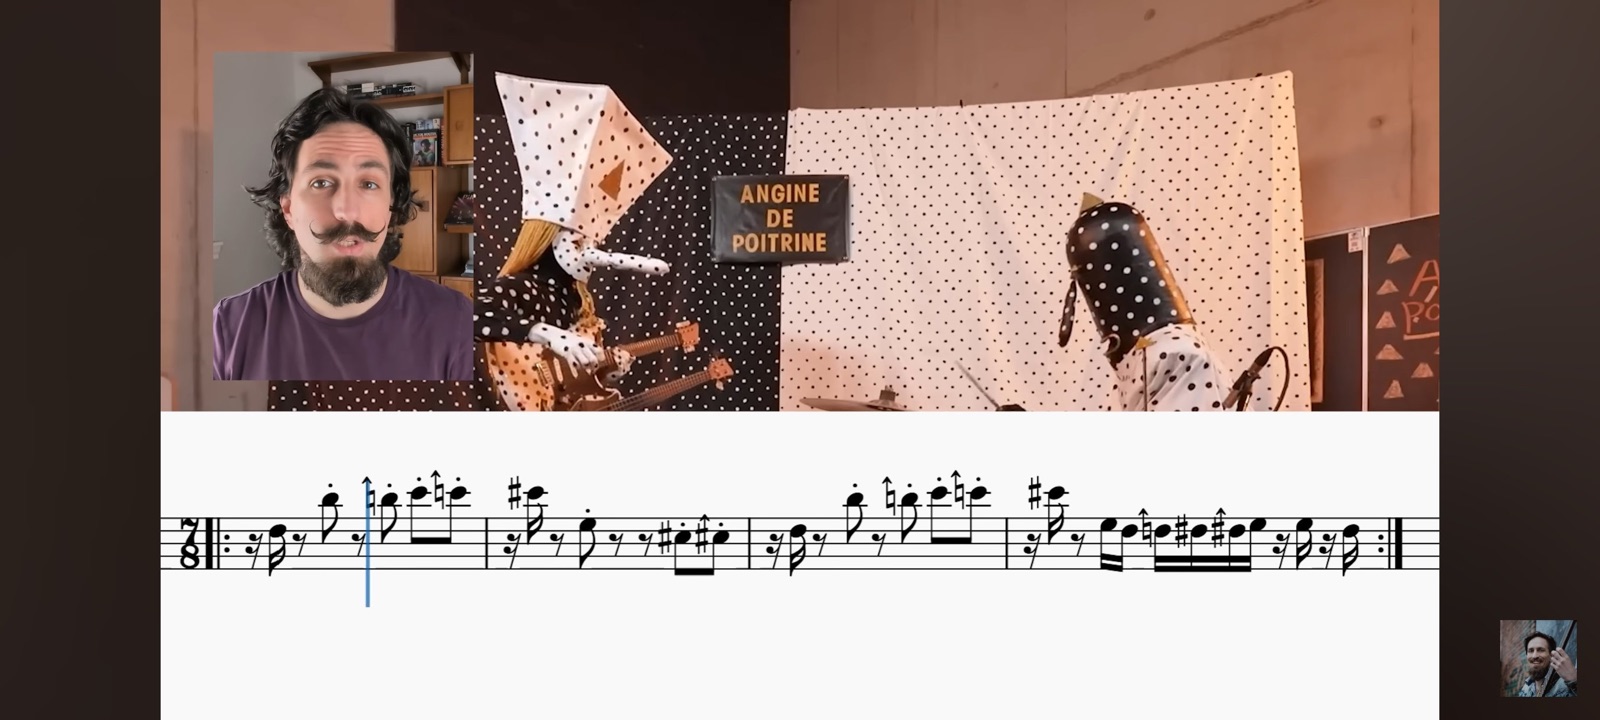
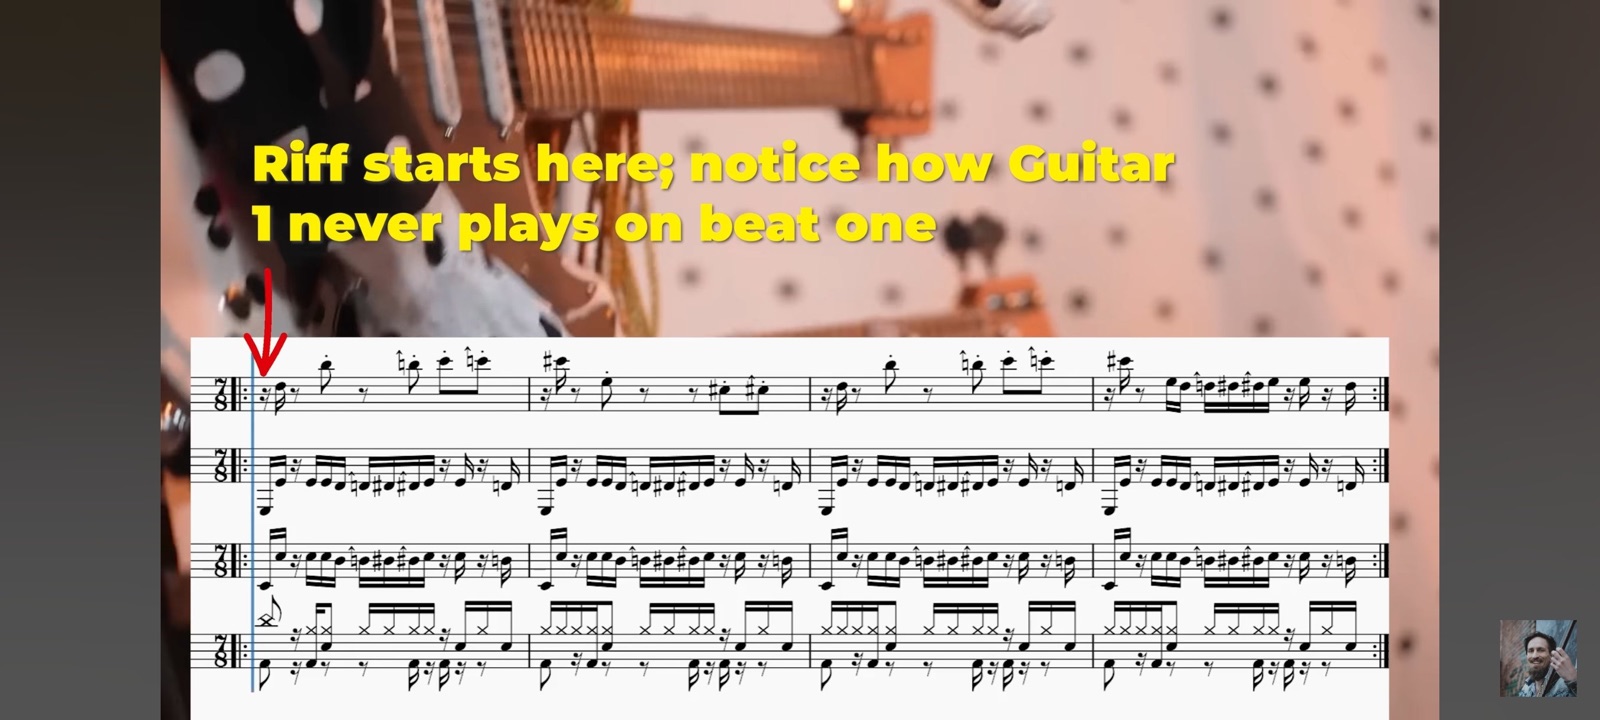
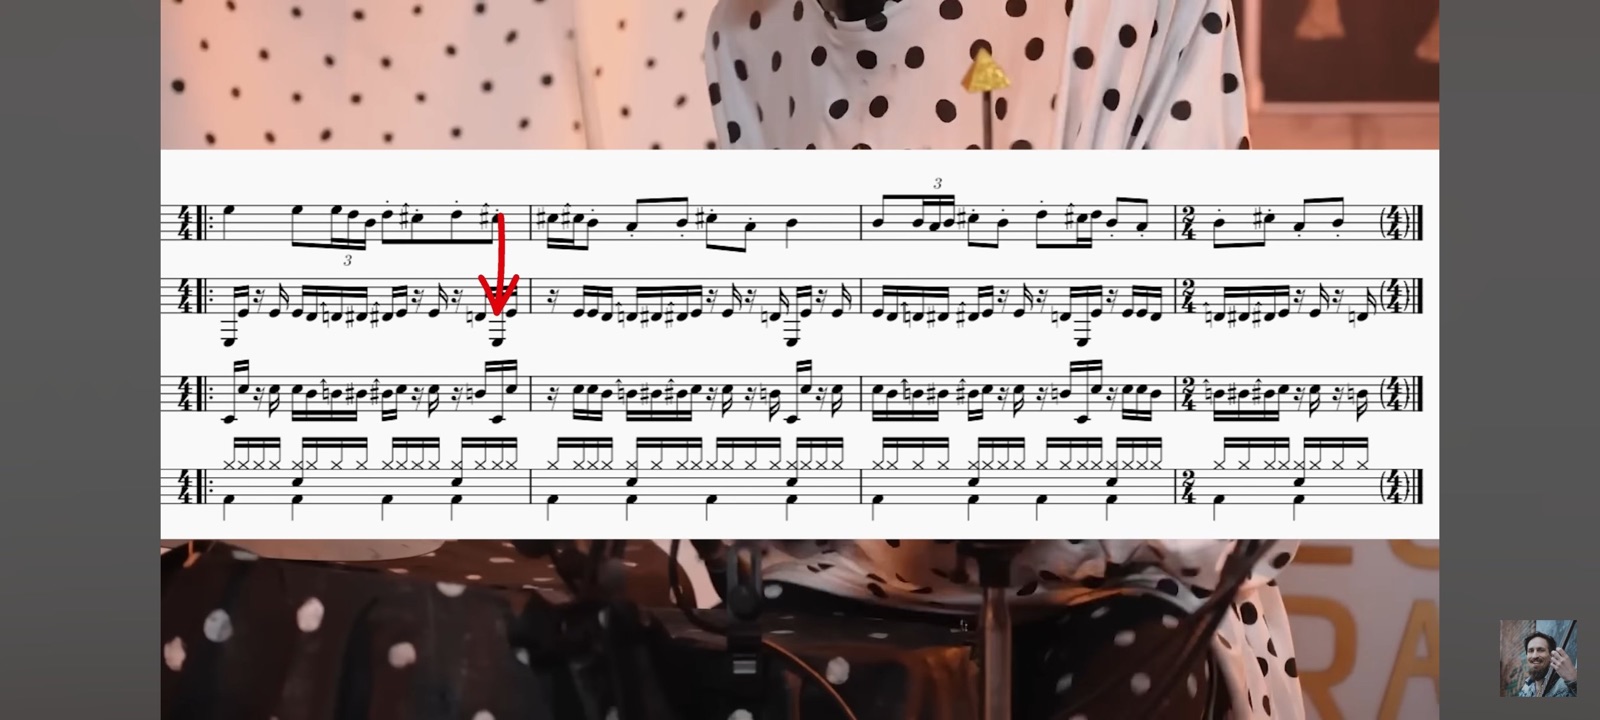
What I find super remarkable in this video is that he took the time and effort to really understand and then even communicate what's actually going on here. For me, this de-mystificaion just creates more wonder, not even less. I feel like I can groove even harder with the song now than before.
And that's a really rare skill to have: take something complex, deeply understand it, find what makes it tick and THEN put together a visual, fun and creative exploration that even a non-musician can dig.
The more I reflect on the video, the more I'm impressed:
That's Carl Sagan "Pale Blue Dot" level scientific communication. Feynman lecture grade quality.
It's almost as good as the KEXP video itself and I will bestow 'pon it my personal highest honors: make it part of my daily AdP YouTube tending: I will now rewatch it regularly and favorite every comment in the comment section. 😂
Check out our latest video that does a deeper walkthrough of how to use Claude Managed Agents. Using some of our research preview features: multi-agents, outcomes and memory which is a powerful combination that gets you real results. You define the outcome and claude works until it gets there. t.co/VZ5dXk2fut
5. t.co/PcK85aXLCt
And before i worked from home, I always had the SANS Stormcast on for my commute for a pod to listen to, t.co/KW9KYn6UUu
Used to be a BIG fan of Mandiant threat report, but they paywalled it when Google took over and the Google Threat Intelligence pricing it too rich for me now so only get the dumbed down editions at: t.co/shMCNLB2pU
So far, I've mostly used ASO for my apps but I really want to learn running paid promotions.
To me, TopYappers seems like a perfect choice but I'm not sure if I'm "ready" or not.
@tadasgedgaudas, with your experience: What are the basic nuts-and-bolt requirements that I need to bring to the table before it makes sense to subscribe and reach out to creators.
Here's where I'm at:
I've got a story
I've got an app on the App Store for that story
I've got a $50/mo. SaaS budget
I've got a creator budget, let's say $2,000 for a first round of tests
I've done paid advertising before
I have tested and tuned sales funnels
I am totally aware that there is no guarantee that using topyappers will result in any meaningful ROI
@VadimStrizheus Right now the decades are happening in days not weeks. I wonder what's gon happen when the updates slow down and we're then at the point of stabilization t.co/M0IVavR978
Yup, I feel the same.
For me it's been a combination of
working at AI-fueled hyper-speed at work and personal projects
absorbing AI-related news changes
the (perceived) craziness of domestic and international news
I had a moment in December where I felt really burned out. Took some time offline which let me recharge quiet well.
Then another sort of low-point last week which I've given a good amount of recovery attention.
And I'll definitely need some time offline again this weekend.
Biggest surprise: A nice hot shower really, really helps me reset and feel fresh again. At least fresh enough to figure out what else I need more of.
Gotcha! Then I would like to thank you for your time and effort that you have put into keeping the database up-to-date.
I felt like the value you created was absolutely worth giving you my money for it.
In fact, looking back, you could have increased the price btw. I would have paid at least 50% more and still have had the feeling of getting a good deal.
Again, thank you!
If you launch something new, please keep me updated. Either here via DM or via email (you should have mine, starts with alexis.rondeau@...)
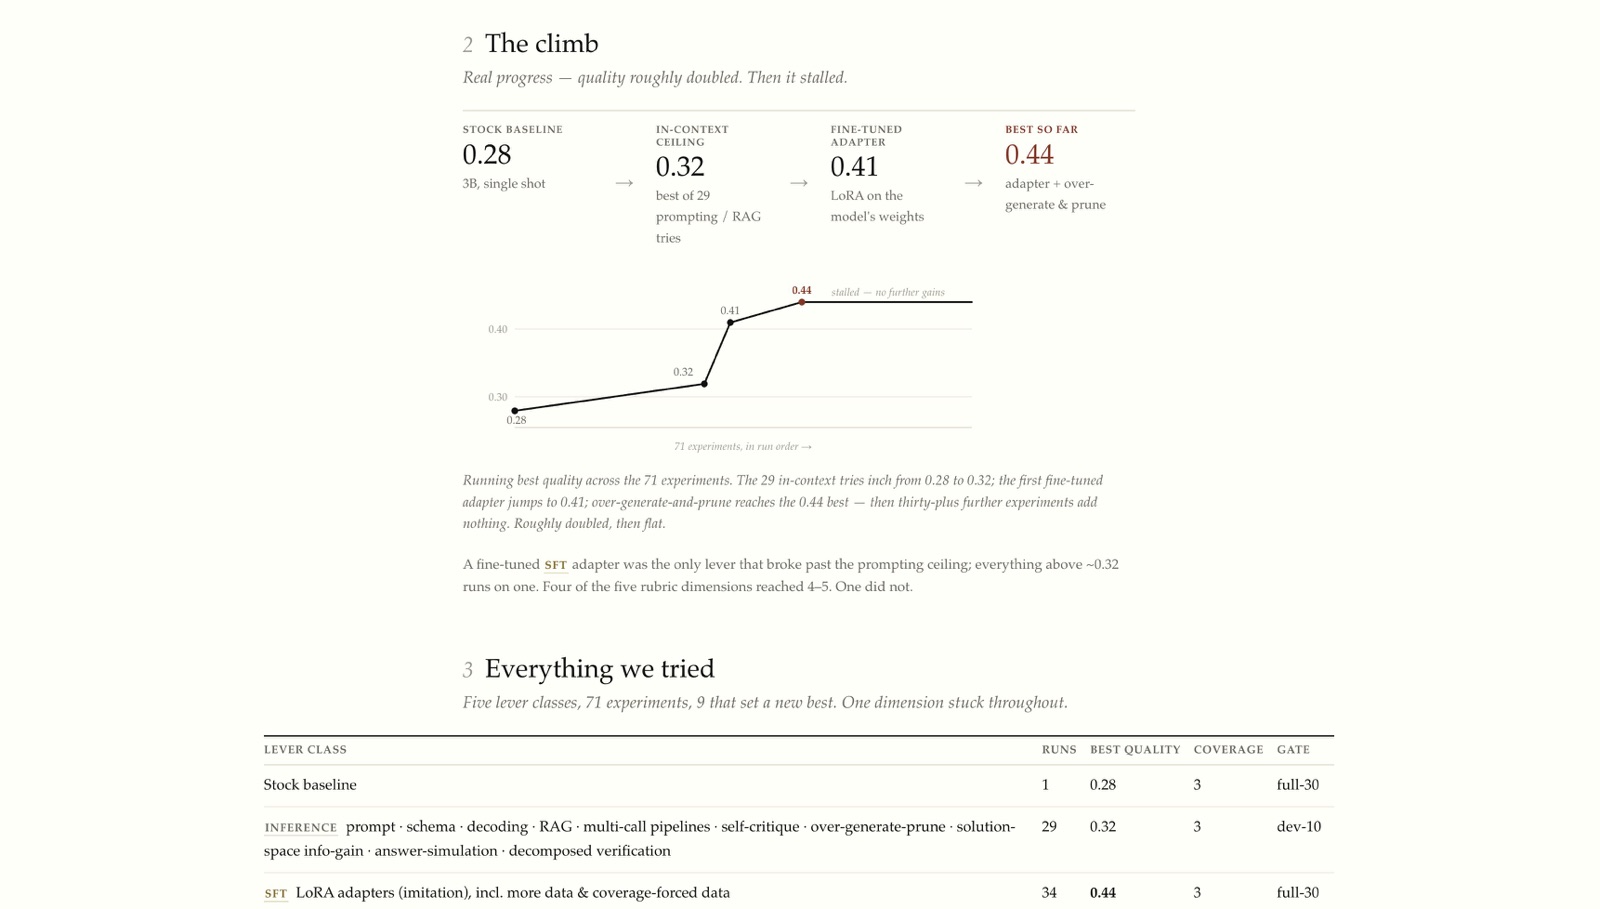
 alexisrondeau.me"Which city in Paris are you staying in?" - A post-training study on small-model specialization with an autoresearch loopAcross 77 experiments — every lever from prompting and retrieval to fine-tuning and 2025's rubric-grounded RL — an on-device 3B model landed within about one rubric point of a frontier cloud model on every quality dimension: close, but consistently a notch below. None of the post-training playbook closed the last notch, and the controlled tests show why — the gap is a broad capability limit, not a…↗ alexisrondeau.me